<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom" xmlns:media="http://search.yahoo.com/mrss/" xml:lang="en-US">
  <title>BigBinary Blog: Kubernetes</title>
  <subtitle>Deep technical writing on Ruby on Rails, performance, scaling, monitoring and engineering.</subtitle>
  <link rel="self" type="application/atom+xml" href="https://www.bigbinary.com/blog/categories/kubernetes/feed.xml"/>
  <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/categories/kubernetes"/>
  <id>https://www.bigbinary.com/blog/categories/kubernetes</id>
  <updated>2024-07-23T00:00:00.000Z</updated>
  <author>
    <name>BigBinary</name>
    <uri>https://www.bigbinary.com/</uri>
  </author>
  <icon>https://www.bigbinary.com/favicon.ico</icon>
  <logo>https://www.bigbinary.com/images/bigbinary_square_big_logo.png</logo>
  <rights>Copyright 2024 Big Binary LLC</rights>
  <generator uri="https://nextjs.org">Next.js</generator>
  <entry>
      <title type="text"><![CDATA[Scaling Kubernetes HPA on custom Prometheus metrics]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/prometheus-adapter"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/configuring_kubernetes_pod_autoscaler_based_on_custom_metrics.jpg"/>
      <id>https://www.bigbinary.com/blog/prometheus-adapter</id>
      <published>2024-07-23T00:00:00.000Z</published>
      <updated>2024-07-23T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="Kubernetes"/>
      <category term="DevOps"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/configuring_kubernetes_pod_autoscaler_based_on_custom_metrics.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[How we built autoscaling based on custom Prometheus metrics for NeetoDeploy]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/prometheus-adapter"><![CDATA[<p>Some of the major upsides of using Kubernetes to manage deployments are the
self-healing and autoscaling capabilities of Kubernetes. If a deployment has a
sudden spike of traffic, Kubernetes will automatically spin up new containers
and handle that load gracefully. It will also scale down deployments when the
traffic reduces.</p>
<p>Kubernetes has
<a href="https://www.bigbinary.com/blog/solving-scalability-in-neeto-deploy#understanding-kubernetes-autoscalers">a couple of different ways</a>
to scale deployments automatically based on the load the application receives.
The
<a href="https://kubernetes.io/docs/tasks/run-application/horizontal-pod-autoscale/">Horizontal Pod Autoscaler (HPA)</a>
can be used out of the box in a Kubernetes cluster to increase or decrease the
number of Pods of your deployment. By default, HPA supports scaling based on CPU
and memory usage, served by the
<a href="https://kubernetes.io/docs/tasks/debug/debug-cluster/resource-metrics-pipeline/#metrics-server">metrics server</a>.</p>
<p>While building <a href="https://neeto.com/neetodeploy">NeetoDeploy</a> initially, we'd set
up to scale deployments based on CPU and memory usage, since these were the
default metrics supported by the HPA. However, later we wanted to scale
deployments based on the average response time of our application.</p>
<p>This is an example of a case where the metric we want to scale is not directly
related to the CPU or the memory usage. Other examples of this could be network
metrics from the load balancer, like the number of requests received in the
application. In this blog, we will discuss how we achieved autoscaling of
deployments in Kubernetes based on the average response time using
<a href="https://github.com/kubernetes-sigs/prometheus-adapter">prometheus-adapter</a>.</p>
<p>When an application receives a lot of requests suddenly, this creates a spike in
the average response time. The CPU and memory metrics also spike, but they take
longer to catch up. In such cases, being able to scale deployments based on the
response time will ensure that the spike in traffic is handled gracefully.</p>
<p><a href="https://prometheus.io/">Prometheus</a> is one of the most popular cloud native
monitoring tools and the Kubernetes HPA can be extended to scale deployments
based on metrics exposed by Prometheus. We used the <code>prometheus-adapter</code> to
build autoscaling based on the average response time in
<a href="https://neeto.com/neetodeploy">NeetoDeploy</a>.</p>
<h2>Setting up the custom metrics</h2>
<p>We took the following steps to make our HPAs work with Prometheus metrics.</p>
<ol>
<li>Installed <code>prometheus-adapter</code> in our cluster.</li>
<li>Configured the metric we wanted for our HPAs as a custom metric in the
<code>prometheus-adapter</code>.</li>
<li>Confirmed that the metric is added to the <code>custom.metrics.k8s.io</code> API
endpoint.</li>
<li>Configured an HPA with the custom metric.</li>
</ol>
<h2>Install prometheus-adapter in the cluster</h2>
<p><a href="https://github.com/kubernetes-sigs/prometheus-adapter">prometheus-adapter</a> is
an implementation of the <code>custom.metrics.k8s.io</code> API using Prometheus. We used
the prometheus-adapter to set up Kubernetes metrics APIs for our Promtheus
metrics, which then can be used with our HPAs.</p>
<p>We installed <code>prometheus-adapter</code> in our cluster using <a href="https://helm.sh/">Helm</a>.
We got a template for the values file for the Helm installation
<a href="https://github.com/prometheus-community/helm-charts/blob/main/charts/prometheus-adapter/values.yaml">here</a>.</p>
<p>We made a few changes to the file before we applied it to our cluster and
deployed <code>prometheus-adapter</code>:</p>
<ol>
<li>We made sure that the Prometheus deployment is configured properly by giving
the correct service url and port.</li>
</ol>
<pre><code class="language-yaml"># values.yaml
prometheus:
  # Value is templated
  url: http://prometheus.monitoring.svc.cluster.local
  port: 9090
  path: &quot;&quot;
# ... rest of the file
</code></pre>
<ol start="2">
<li>We made sure that the custom metrics that we needed for our HPA are
configured under <code>rules.custom</code> in the <code>values.yaml</code> file. In the following
example, we are using the custom metric <code>traefik_service_avg_response_time</code>
since we'll be using that to calculate the average response time for each
deployment.</li>
</ol>
<pre><code class="language-yaml"># values.yaml
rules:
  default: false

  custom:
    - seriesQuery:'{__name__=~&quot;traefik_service_avg_response_time&quot;, service!=&quot;&quot;}'
      resources:
        overrides:
          app_name:
            resource: service
          namespace:
            resource: namespace
      metricsQuery: traefik_service_avg_response_time{&lt;&lt;.LabelMatchers&gt;&gt;}
</code></pre>
<p>Once we configured our <code>values.yaml</code> file properly, we installed
<code>prometheus-adapter</code> in our cluster with Helm.</p>
<pre><code class="language-bash">helm repo add prometheus https://prometheus-community.github.io/helm-charts
helm repo update
helm install prom-adapter prometheus-community/prometheus-adapter --values values.yaml
</code></pre>
<h2>Query for custom metric</h2>
<p>Once we got <code>prometheus-adapter</code> running, we queried our cluster to check if the
custom metric is coming up in the <code>custom.metrics.k8s.io</code> API endpoint.</p>
<pre><code class="language-bash">kubectl get --raw /apis/custom.metrics.k8s.io/v1beta1 | jq
</code></pre>
<p>The response looked like this:</p>
<pre><code class="language-json">{
  &quot;kind&quot;: &quot;APIResourceList&quot;,
  &quot;apiVersion&quot;: &quot;v1&quot;,
  &quot;groupVersion&quot;: &quot;custom.metrics.k8s.io/v1beta1&quot;,
  &quot;resources&quot;: [
    {
      &quot;name&quot;: &quot;services/traefik_service_avg_response_time&quot;,
      &quot;singularName&quot;: &quot;&quot;,
      &quot;namespaced&quot;: true,
      &quot;kind&quot;: &quot;MetricValueList&quot;,
      &quot;verbs&quot;: [&quot;get&quot;]
    },
    {
      &quot;name&quot;: &quot;namespaces/traefik_service_avg_response_time&quot;,
      &quot;singularName&quot;: &quot;&quot;,
      &quot;namespaced&quot;: false,
      &quot;kind&quot;: &quot;MetricValueList&quot;,
      &quot;verbs&quot;: [&quot;get&quot;]
    }
  ]
}
</code></pre>
<p>We also queried the metric API for a particular service we've configured the
metric for. Here, we're querying the <code>traefik_service_avg_response_time</code> metric
for the <code>neeto-chat-web-staging</code> app in the default namespace.</p>
<pre><code>kubectl get --raw /apis/custom.metrics.k8s.io/v1beta1/namespaces/default/services/neeto-chat-web-staging/traefik_service_avg_response_time | jq
</code></pre>
<p>The API response gave the following.</p>
<pre><code class="language-json">{
  &quot;kind&quot;: &quot;MetricValueList&quot;,
  &quot;apiVersion&quot;: &quot;custom.metrics.k8s.io/v1beta1&quot;,
  &quot;metadata&quot;: {},
  &quot;items&quot;: [
    {
      &quot;describedObject&quot;: {
        &quot;kind&quot;: &quot;Service&quot;,
        &quot;namespace&quot;: &quot;default&quot;,
        &quot;name&quot;: &quot;neeto-chat-web-staging&quot;,
        &quot;apiVersion&quot;: &quot;/v1&quot;
      },
      &quot;metricName&quot;: &quot;traefik_service_avg_response_time&quot;,
      &quot;timestamp&quot;: &quot;2024-02-26T19:31:33Z&quot;,
      &quot;value&quot;: &quot;19m&quot;,
      &quot;selector&quot;: null
    }
  ]
}
</code></pre>
<p>From the response, we can see that the average response time at the instant is
reported as <code>19ms</code>.</p>
<h2>Create the HPA</h2>
<p>Now that we're sure that <code>prometheus-adapter</code> is able to serve custom metrics
under the <code>custom.metrics.k8s.io</code> API, we wired this up with a Horizontal Pod
Autoscaler to scale our deployments based on our custom metric.</p>
<pre><code class="language-yaml">apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata:
  name: my-app-name-hpa
spec:
  scaleTargetRef:
    apiVersion: apps/v1
    kind: Deployment
    name: my-app-name-deployment
  minReplicas: 1
  maxReplicas: 10
  metrics:
    - type: Object
      object:
        metric:
          name: traefik_service_avg_response_time
          selector: { matchLabels: { app_name: my-app-name } }
        describedObject:
          apiVersion: v1
          kind: Service
          name: my-app-name
        target:
          type: Value
          value: 0.03
</code></pre>
<p>With everything set up, the HPA was able to fetch the custom metric scraped by
Prometheus and scale our Pods up and down based on the value of the metric. We
also created a recording rule in Prometheus for storing our custom metric
queries and dropped the unwanted labels as a best practice. We can use the
custom metric stored with the recording rule directly with <code>prometheus-adapter</code>
to expose the metrics as an API endpoint in Kubernetes. This is helpful when
your custom metric queries are complex.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
invite@neeto.com.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">X</a>. You can also join our
<a href="https://launchpass.com/neetohq">community Slack</a> to chat with us about any
Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[How we fixed app downtime issue in NeetoDeploy]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/how-we-fixed-app-down-time-in-neeto-deploy"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/how_we_fixed_app_downtime_in_neetoDeploy.jpg"/>
      <id>https://www.bigbinary.com/blog/how-we-fixed-app-down-time-in-neeto-deploy</id>
      <published>2024-07-09T00:00:00.000Z</published>
      <updated>2024-07-09T00:00:00.000Z</updated>
      <author>
        <name>Abhishek T</name>
        <uri>https://www.bigbinary.com/blog/authors/abhishekt98</uri>
      </author>
      <category term="NeetoDeploy"/>
      <category term="Kubernetes"/>
      <category term="DevOps"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/how_we_fixed_app_downtime_in_neetoDeploy.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[We are building NeetoDeploy, a compelling alternative to Heroku. Stay updated by following NeetoDeploy on Twitter and reading our blog. At neeto we are building 20+ applications, and most of our...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/how-we-fixed-app-down-time-in-neeto-deploy"><![CDATA[<p><em>We are building <a href="https://neeto.com/neetoDeploy">NeetoDeploy</a>, a compelling
alternative to Heroku. Stay updated by following NeetoDeploy on
<a href="https://twitter.com/neetodeploy">Twitter</a> and reading our
<a href="https://www.bigbinary.com/blog/categories/neetodeploy">blog</a>.</em></p>
<p>At <a href="https://www.neeto.com/">neeto</a> we are building 20+ applications, and most of
our applications are running in NeetoDeploy. Once we migrated from Heroku to
NeetoDeploy, we started getting 520 response code for our applications. This
issue was occurring randomly and rarely.</p>
<h3>What is 520 response code?</h3>
<p>A 520 response code happens when the connection is started on the origin web
server, but the request is not completed. This could be due to server crashes or
the inability to handle the incoming requests because of insufficient resources.</p>
<p>When we looked at our logs closely, we found that all the 520 response code
situations occurred when we restarted or deployed the app. From this, we
concluded that the new pods are failing to handle requests from the client
initially and working fine after some time.</p>
<h3>What is wrong with new pods?</h3>
<p>Once our investigation narrowed down to the new pods, we quickly realized that
requests are arriving at the server even when the server is not fully ready yet
to take new requests.</p>
<p>When we create a new pod in Kubernetes, it is marked as &quot;Ready&quot;, and requests
are sent to it as soon as its containers start. However, the servers initiated
within these containers may require additional time to boot up and to become
ready to accept the requests fully.</p>
<h4>Let's try restarting the application</h4>
<pre><code class="language-bash">$ kubectl rollout restart deployment bling-staging-web
</code></pre>
<p>As we can see, a new container is getting created for the new pod. The READY
status for the new pod is 0. It means it's not yet READY.</p>
<pre><code class="language-bash">NAME                               READY  STATUS             RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  1/1    Running            0         2m8s
bling-staging-web-79fc6f978-cdjf5  0/1    ContainerCreating  0         5s
</code></pre>
<p>Now we can see that the new pod is marked as READY (1 out of 1), and the old one
is terminating.</p>
<pre><code class="language-bash">NAME                               READY  STATUS             RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  0/1    Terminating        0         2m9s
bling-staging-web-79fc6f978-cdjf5  1/1    Running            0         6s
</code></pre>
<p>The new pod is shown as <code>READY</code> as soon as the container was created. But on
checking the logs, we could see that the server was still starting up and not
ready yet.</p>
<pre><code>[1] Puma starting in cluster mode...
[1] Installing dependencies...
</code></pre>
<p>From the above observation, we understood that the pod is marked as &quot;READY&quot;
right after the container is created. Consequently, requests are received even
before the server is fully prepared to serve them, and they get a 520 response
code.</p>
<h2>Solution</h2>
<p>To fix this issue, we must ensure that pods are marked as &quot;Ready&quot; only after the
server is up and ready to accept the requests. We can do this by using
Kubernetes
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/">health probes</a>.
More than six years ago we wrote
<a href="https://www.bigbinary.com/blog/deploying-rails-applications-using-kubernetes-with-zero-downtime">a blog</a>
on how we can leverage the readiness and liveness probes of Kubernetes.</p>
<h3>Adding Startup probe</h3>
<p>Initially, we only added
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#define-startup-probes">Startup probe</a>
since we had a problem with the boot-up phase. You can read more about the
configuration settings
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#configure-probes">here</a>.</p>
<p>The following configuration will add the Startup probe for the deployments:</p>
<pre><code class="language-yaml">startupProbe:
  failureThreshold: 10
  httpGet:
    path: /health_check
    port: 3000
    scheme: HTTP
  periodSeconds: 5
  successThreshold: 1
  timeoutSeconds: 60
  initialDelaySeconds: 10
</code></pre>
<p><code>/health_check</code> is a route in the application that is expected to return a 200
response code if all is going well. Now, let's restart the application again
after adding the Startup probe.</p>
<p>Container is created for the new pod, but the pod is still not &quot;Ready&quot;.</p>
<pre><code class="language-bash">NAME                               READY  STATUS            RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  1/1    Running           0         2m8s
bling-staging-web-79fc6f978-cdjf5  0/1    Running           0         5s
</code></pre>
<p>The new pod is marked as &quot;Ready&quot;, and the old one is &quot;Terminating&quot;.</p>
<pre><code class="language-bash">NAME                               READY  STATUS            RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  0/1    Terminating       0         2m38s
bling-staging-web-79fc6f978-cdjf5  1/1    Running           0         35s
</code></pre>
<p>If we check the logs, we can see the health check request:</p>
<pre><code>  [1] Puma starting in cluster mode...
  [1] Installing dependencies...
  [1] * Puma version: 6.3.1 (ruby 3.2.2-p53) (&quot;Mugi No Toki Itaru&quot;)
  [1] *  Min threads: 5
  [1] *  Max threads: 5
  [1] *  Environment: heroku
  [1] *   Master PID: 1
  [1] *      Workers: 1
  [1] *     Restarts: (✔) hot (✔) phased
 [1] * Listening on http://0.0.0.0:3000
 [1] Use Ctrl-C to stop
 [2024-02-10T02:40:48.944785 #23]  INFO -- : [bb9e756a-51cc-4d6b-9a4a-96b0464f6740] Started GET &quot;/health_check&quot; for 192.168.120.195 at 2024-02-10 02:40:48 +0000
 [2024-02-10T02:40:48.946148 #23]  INFO -- : [bb9e756a-51cc-4d6b-9a4a-96b0464f6740] Processing by HealthCheckController#healthy as */*
 [2024-02-10T02:40:48.949292 #23]  INFO -- : [bb9e756a-51cc-4d6b-9a4a-96b0464f6740] Completed 200 OK in 3ms (Allocations: 691)
</code></pre>
<p>Now, the pod is marked as &quot;Ready&quot; only after the health check succeeds, in other
words, only when the server is prepared to accept the requests.</p>
<h3>Fixing the Startup probe for production applications</h3>
<p>Once we released the health check for our deployments, we found that health
checks were failing for all production applications but working for staging and
review applications.</p>
<p>We were getting the following error in our production applications.</p>
<pre><code class="language-bash">Startup probe failed: Get &quot;https://192.168.43.231:3000/health_check&quot;: http: server gave HTTP response to HTTPS client

2024-02-12 06:40:04 +0000 HTTP parse error, malformed request: #&lt;Puma::HttpParserError: Invalid HTTP format, parsing fails. Are you trying to open an SSL connection to a non-SSL Puma?&gt;
</code></pre>
<p>From the above logs, it was clear that the issue was related to SSL
configuration. On comparing the production environment configuration with the
others, we figured out that we had enabled
<a href="https://guides.rubyonrails.org/configuring.html#config-force-ssl">force_ssl</a>
for production applications. The <code>force_ssl=true</code> setting ensures that all
incoming requests are SSL encrypted and will automatically redirect to their SSL
counterparts.</p>
<p>The following diagram broadly shows the path of an incoming request.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/how-we-fixed-app-down-time-in-neeto-deploy/image4.png" alt="HTTPS request path"></p>
<p>From the above diagram, we can infer the following things:</p>
<ul>
<li>SSL verification is happening in the ingress controller and not in the server.</li>
<li>Client requests are going through the ingress controller before reaching the
server.</li>
<li>Request from ingress controller to the pod is an HTTP request.</li>
<li>The HTTP health check requests are directly sent from Kubelet to the pod and
do not go through the ingress controller.</li>
</ul>
<p>Here is how our health check request works.</p>
<ol>
<li><a href="https://kubernetes.io/docs/reference/command-line-tools-reference/kubelet/">Kubelet</a>
sends an HTTP request to the server directly.</li>
<li>Since <code>force_ssl</code> is enabled,
<a href="https://api.rubyonrails.org/v7.1.2/classes/ActionDispatch/SSL.html">ActionDispatch::SSL</a>
middleware redirects the request to HTTPS.</li>
<li>When the HTTPS request reaches the server, <a href="https://puma.io/">Puma</a> throws
<code>Are you trying to open an SSL connection to a non-SSL Puma?</code> error since no
SSL certificates are configured with the server.</li>
</ol>
<p>The solution to our problem lies in understanding why only the health check
request is rejected, whereas the request from the ingress controller is not,
even though both are HTTP requests. This is because ingress controller sets some
headers before forwarding to the pod, and the header we are concerned about is
<a href="https://developer.mozilla.org/en-US/docs/Web/HTTP/Headers/X-Forwarded-Proto">X-FORWARDED-PROTO</a>.
The <code>X-Forwarded-Proto</code> header contains the HTTP/HTTPS scheme the client used to
access the application. When a client makes an HTTPS request, the ingress
controller terminates the SSL/TLS connection and forwards the request to the
backend service using plain HTTP after adding the<code>X-Forwarded-Proto</code> along with
the other headers.</p>
<p>Everything started working after adding the <code>X-Forwarded-Proto</code> header to our
startup probe request.</p>
<pre><code class="language-yaml">startupProbe:
  failureThreshold: 10
  httpGet:
    httpHeaders:
      - name: X-FORWARDED-PROTO
        value: https
    path: &lt;%= health_check_url %&gt;
    port: &lt;%= port %&gt;
    scheme: HTTP
  periodSeconds: 5
  successThreshold: 1
  timeoutSeconds: 60
  initialDelaySeconds: 10
</code></pre>
<p>We also added
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#define-readiness-probes">Readiness</a>
and
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#define-a-liveness-http-request">Liveness</a>
probes for our deployments.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">Twitter</a>. You can also join our
Slack community to chat with us about any Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Grafana Loki and Kubernetes Event exporter]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/k8s-event-exporter-and-grafana-loki-integration"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/grafana_loki_and_kubernetes_event_exporter.jpg"/>
      <id>https://www.bigbinary.com/blog/k8s-event-exporter-and-grafana-loki-integration</id>
      <published>2024-05-07T00:00:00.000Z</published>
      <updated>2024-05-07T00:00:00.000Z</updated>
      <author>
        <name>Vishal Yadav</name>
        <uri>https://www.bigbinary.com/blog/authors/vishal76342</uri>
      </author>
      <category term="NeetoCI"/>
      <category term="Prometheus"/>
      <category term="Grafana"/>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/grafana_loki_and_kubernetes_event_exporter.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[In this blog, we'll explore how to integrate the Kubernetes Event exporter & Grafana Loki into your Kubernetes Cluster using a helm chart.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/k8s-event-exporter-and-grafana-loki-integration"><![CDATA[<p>In the previous
<a href="https://www.bigbinary.com/blog/prometheus-and-grafana-integration">blog</a>, we
discussed integrating <a href="https://prometheus.io/">Prometheus</a> and
<a href="https://grafana.com/">Grafana</a> in the Kubernetes Cluster. In this blog, we'll
explore how to integrate the
<a href="https://github.com/resmoio/kubernetes-event-exporter">Kubernetes Event exporter</a>
&amp; <a href="https://grafana.com/oss/loki/">Grafana Loki</a> into your Kubernetes Cluster
using a helm chart.</p>
<p>Additionally, you’ll also learn how to add Grafana Loki as a data source to your
Grafana Dashboard. This will help you visualize the Kubernetes events.</p>
<p>Furthermore, we'll delve into the specifics of setting up the Event exporter and
Grafana Loki, ensuring you understand each step of the process. From downloading
and configuring the necessary helm charts to understanding the Grafana Loki
dashboard, we'll cover it all.</p>
<p>By the end of this blog, you'll be able to fully utilize Grafana Loki and
Kubernetes Event Exporter, gaining insights from your Kubernetes events.</p>
<h2>How Kubernetes event exporter can help us in monitoring health</h2>
<p>Objects in Kubernetes, such as Pod, Deployment, Ingress, Service publish events
to indicate status updates or problems. Most of the time, these events are
overlooked and their 1-hour lifespan might cause missing important updates. They
are also not searchable and cannot be aggregated.</p>
<p>For instance, they can alert you to changes in the state of pods, errors in
scheduling, and resource constraints. Therefore, exporting these events and
visualizing them can be crucial for maintaining the health of your cluster.</p>
<p>Kubernetes event exporter allows exporting the often missed Kubernetes events to
various outputs so that they can be used for observability or alerting purposes.
We can have multiple receivers to export the events from the Kubernetes cluster.</p>
<ul>
<li><a href="https://www.opsgenie.com/">Opsgenie</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#webhookshttp">Webhooks/HTTP</a></li>
<li><a href="https://www.elastic.co/">Elasticsearch</a></li>
<li><a href="https://opensearch.org/">OpenSearch</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#slack">Slack</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#kinesis">Kinesis</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#firehose">Firehose</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#sns">SNS</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#sqs">SQS</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#file">File</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#stdout">Stdout</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#kafka">Kafka</a></li>
<li><a href="https://docs.aws.amazon.com/systems-manager/latest/userguide/OpsCenter.html">OpsCenter</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#customizing-payload">Customize Payload</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#pubsub">Pubsub</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#teams">Teams</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#syslog">Syslog</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#bigquery">Bigquery</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#pipe">Pipe</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#aws-eventbridge">Event Bridge</a></li>
<li><a href="https://github.com/resmoio/kubernetes-event-exporter#loki">Grafana Loki</a></li>
</ul>
<h2>Setting up Grafana Loki &amp; Kubernetes event exporter using Helm chart</h2>
<p>We will once again use <a href="https://artifacthub.io/">ArtifactHub</a>, which provides a
helm chart for installing Grafana Loki onto a Kubernetes Cluster. If you need
instructions on how to install Helm on your system, you can refer to this blog.</p>
<p>In this blog post, we will install a Helm
<a href="https://artifacthub.io/packages/helm/grafana/loki">chart</a> that sets up Loki in
scalable mode, with separate read-and-write components that can be independently
scaled. Alternatively, we can install Loki in monolithic mode, where the Helm
Chart installation runs the Grafana Loki <em>single binary</em> within a Kubernetes
cluster. You can learn more about this
<a href="https://grafana.com/docs/loki/latest/setup/install/helm/install-monolithic/#install-the-monolithic-helm-chart">here</a>.</p>
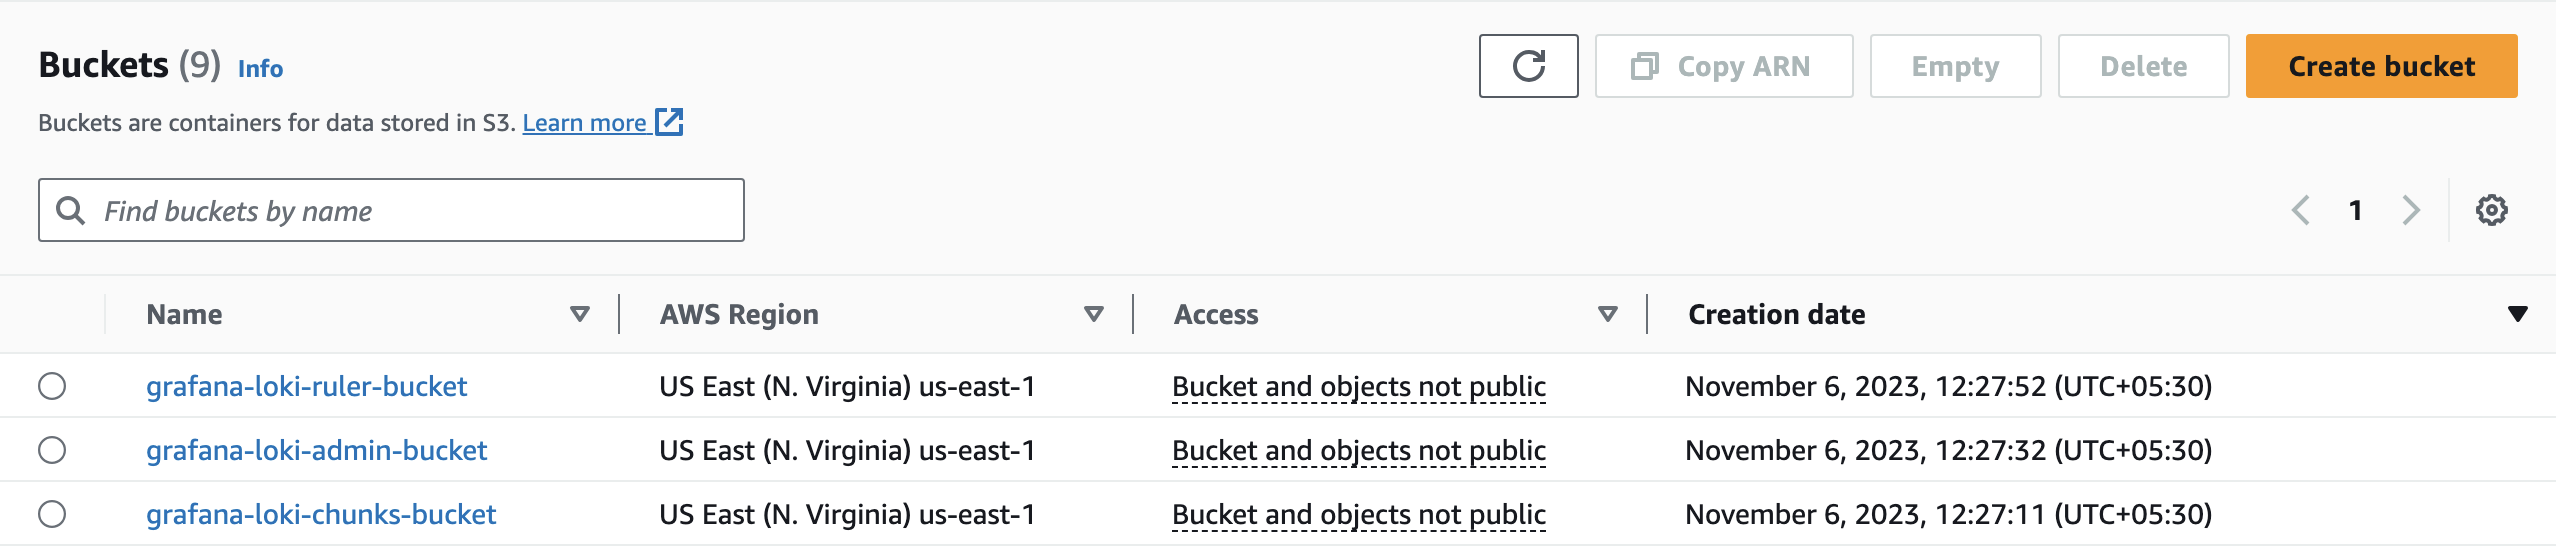
<h3>1. Create S3 buckets</h3>
<ul>
<li>
<p>grafana-loki-chunks-bucket</p>
</li>
<li>
<p>grafana-loki-admin-bucket</p>
</li>
<li>
<p>grafana-loki-ruler-bucket</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/loki-s3-buckets.png" alt="The four Grafana Loki buckets listed in the AWS S3 console"></p>
</li>
</ul>
<h3>2. Create a policy for Grafana Loki</h3>
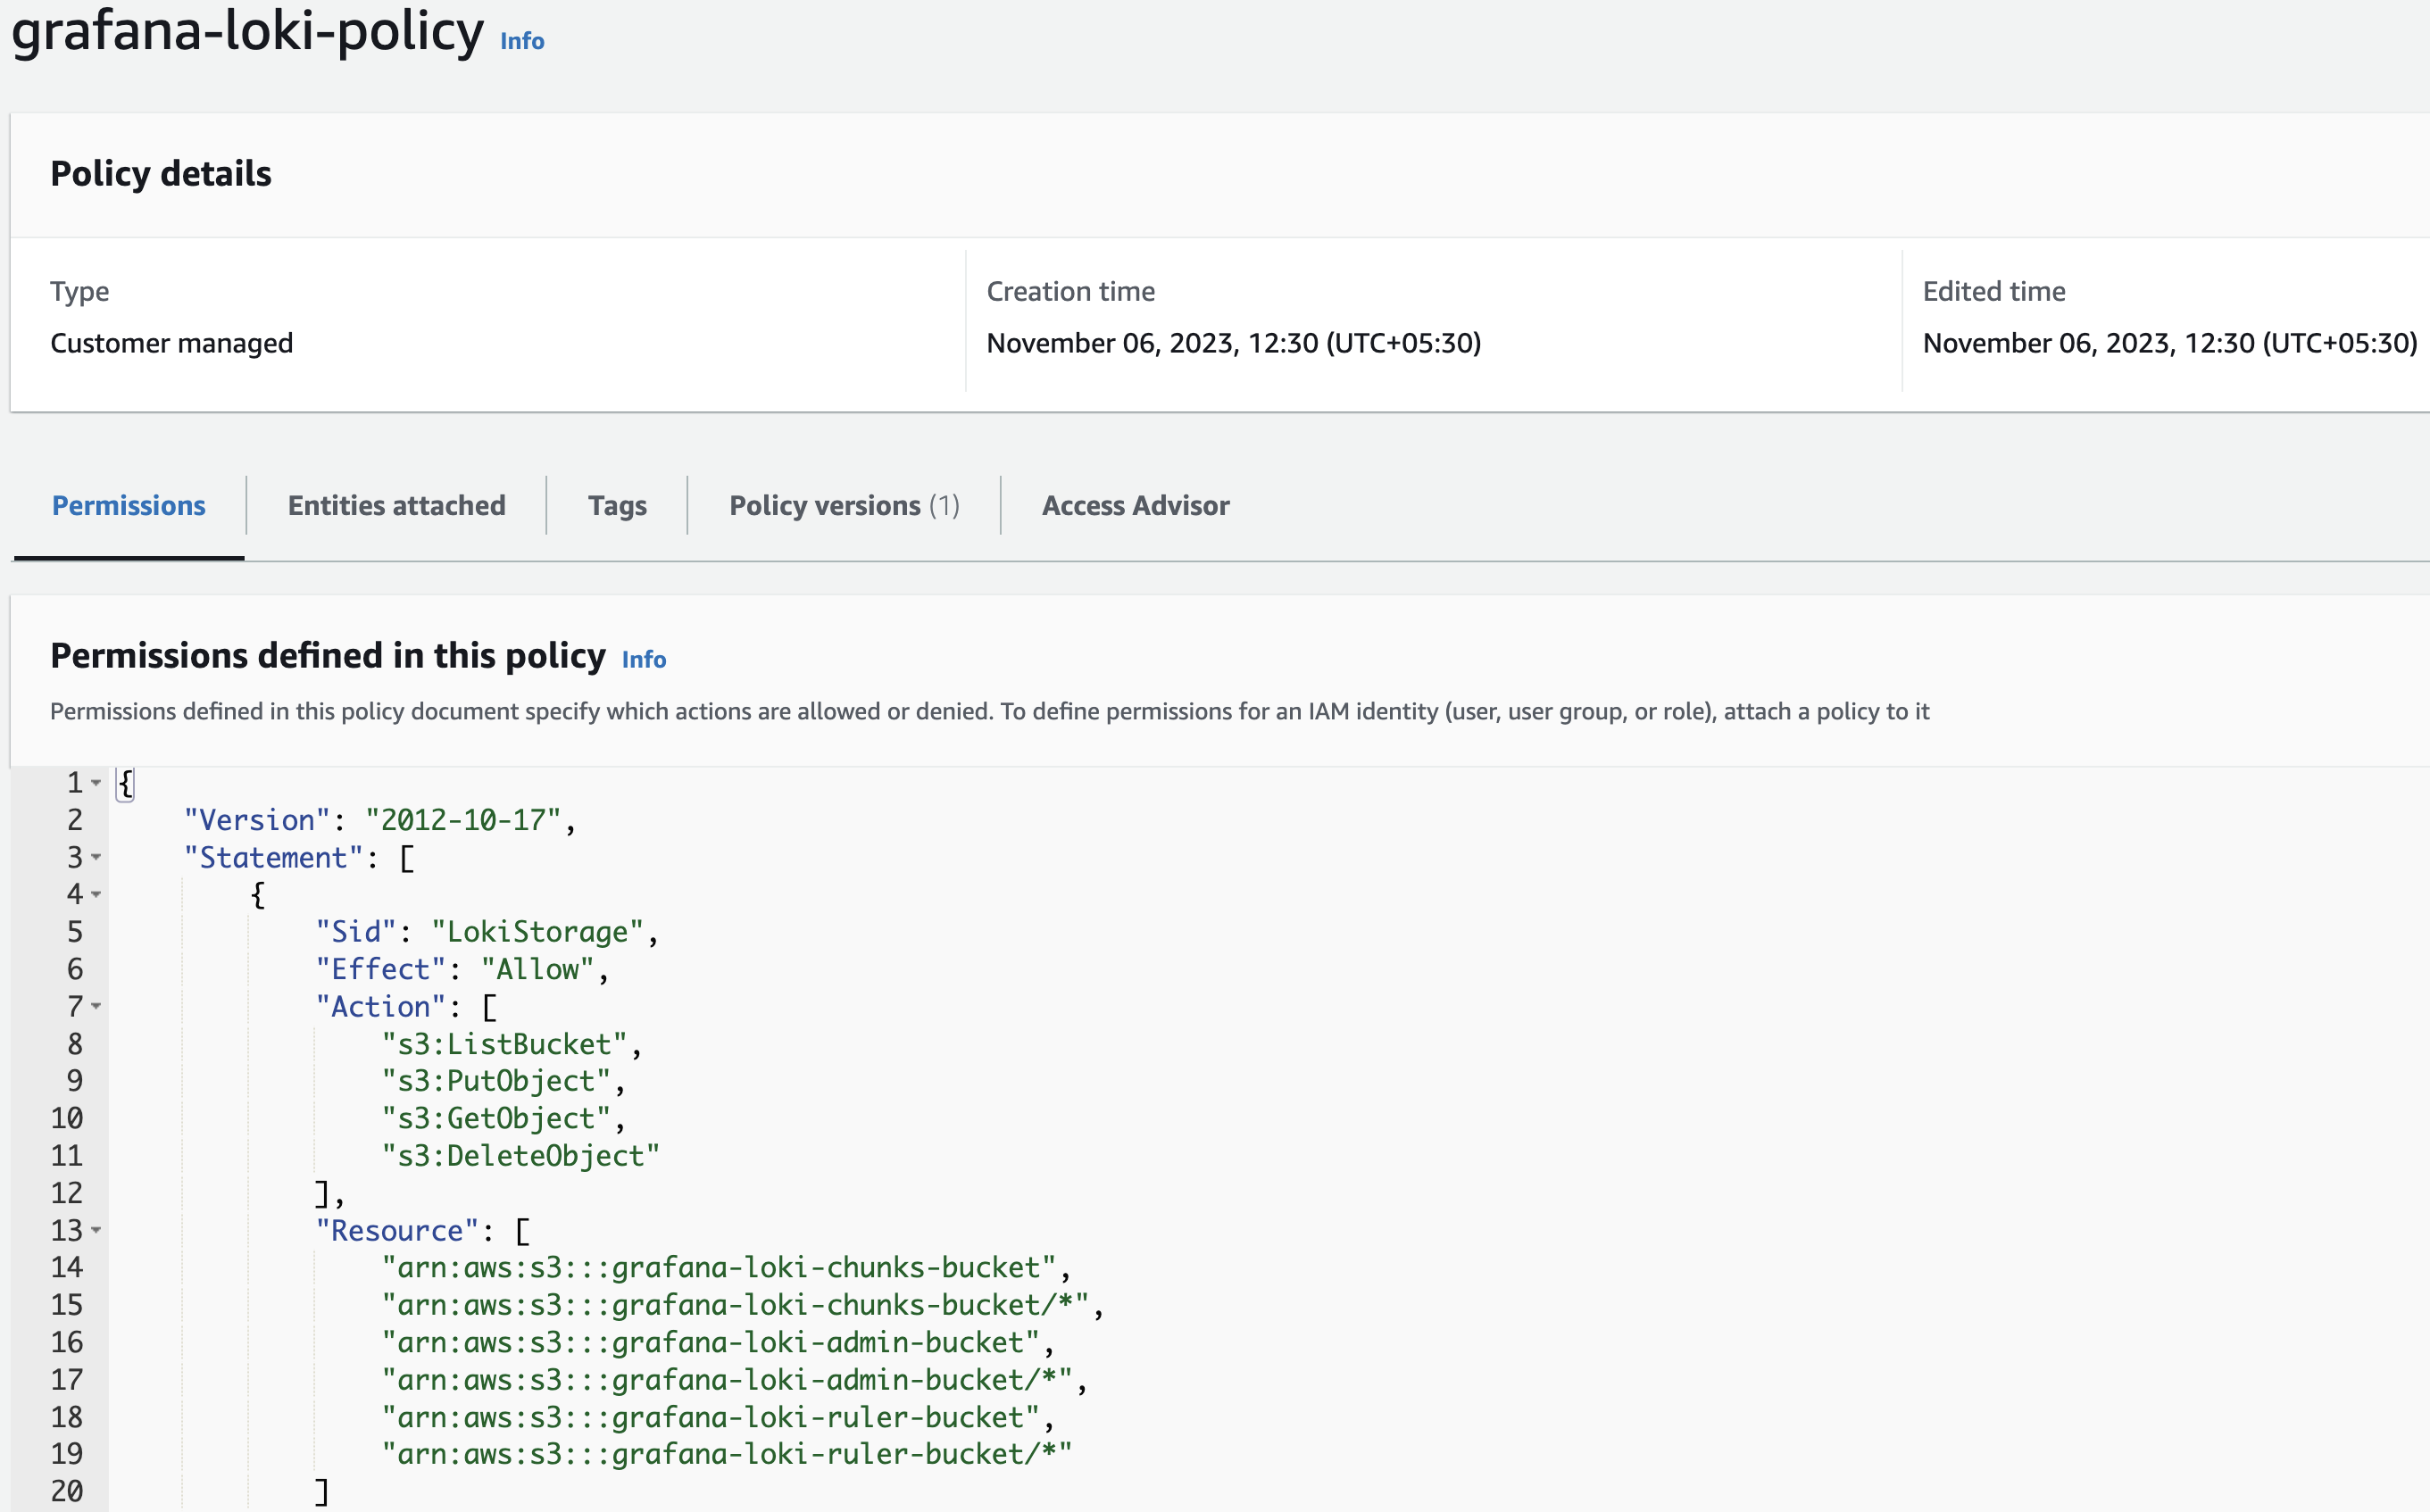
<p>Create a new policy under IAM on Amazon AWS using the below snippet.</p>
<pre><code>{
    &quot;Version&quot;: &quot;2012-10-17&quot;,
    &quot;Statement&quot;: [
        {
            &quot;Sid&quot;: &quot;LokiStorage&quot;,
            &quot;Effect&quot;: &quot;Allow&quot;,
            &quot;Action&quot;: [
                &quot;s3:ListBucket&quot;,
                &quot;s3:PutObject&quot;,
                &quot;s3:GetObject&quot;,
                &quot;s3:DeleteObject&quot;
            ],
            &quot;Resource&quot;: [
                &quot;arn:aws:s3:::grafana-loki-chunks-bucket&quot;,
                &quot;arn:aws:s3:::grafana-loki-chunks-bucket/*&quot;,
                &quot;arn:aws:s3:::grafana-loki-admin-bucket&quot;,
                &quot;arn:aws:s3:::grafana-loki-admin-bucket/*&quot;,
                &quot;arn:aws:s3:::grafana-loki-ruler-bucket&quot;,
                &quot;arn:aws:s3:::grafana-loki-ruler-bucket/*&quot;
            ]
        }
    ]
}
</code></pre>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/grafana-loki-policy.png" alt="Terminal output confirming the Grafana Loki IAM policy was created"></p>
<h3>3. Create a Role with the above permission</h3>
<p>Create a role with a custom trust policy &amp; use the below snippet</p>
<pre><code>{
    &quot;Version&quot;: &quot;2012-10-17&quot;,
    &quot;Statement&quot;: [
        {
            &quot;Effect&quot;: &quot;Allow&quot;,
            &quot;Principal&quot;: {
                &quot;Federated&quot;: &quot;arn:aws:iam::account_id:oidc-provider/oidc.eks.us-east-1.amazonaws.com/id/open_id&quot;
            },
            &quot;Action&quot;: &quot;sts:AssumeRoleWithWebIdentity&quot;,
            &quot;Condition&quot;: {
                &quot;StringEquals&quot;: {
                    &quot;oidc.eks.us-east-1.amazonaws.com/id/open_id:aud&quot;: &quot;sts.amazonaws.com&quot;,
                    &quot;oidc.eks.us-east-1.amazonaws.com/id/open_id:sub&quot;: &quot;system:serviceaccount:default:grafana-loki-access-s3-role-sa&quot;
                }
            }
        }
    ]
}
</code></pre>
<p>Note: Please update the account_id and open_id in the above given snippet.</p>
<p><strong>grafana-loki-access-s3-role-sa</strong> is the service account name that we will
mention in the Loki values.</p>
<h3>4. Add Grafana using the helm chart</h3>
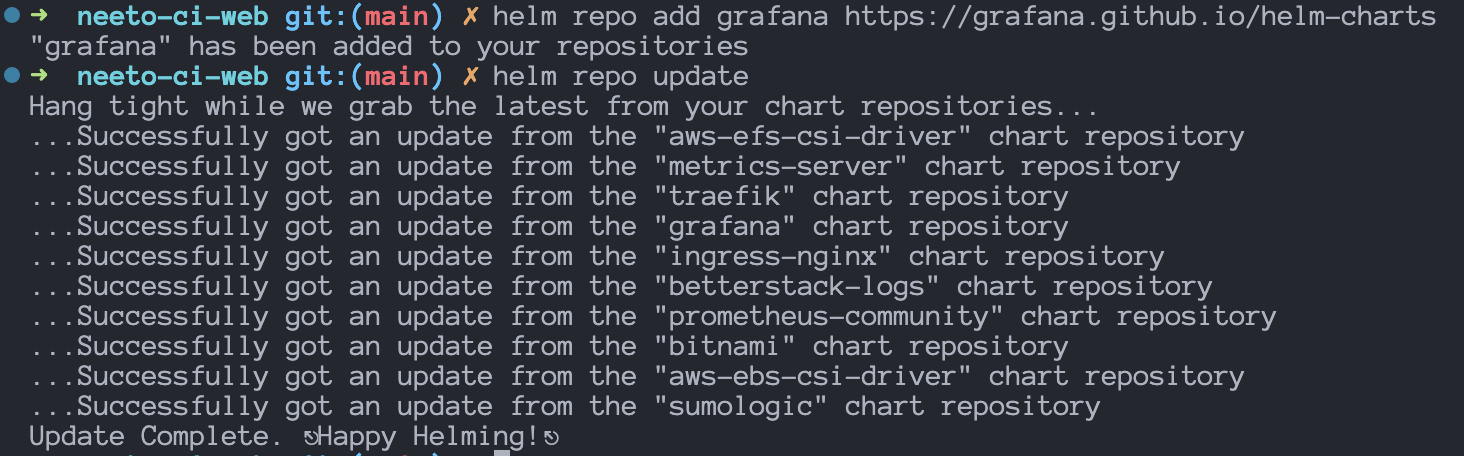
<p>To get this Helm chart, run this command:</p>
<pre><code class="language-jsx">helm repo add grafana https://grafana.github.io/helm-charts
helm repo update
</code></pre>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/chart-add-output.png" alt="Terminal output from adding and updating the Grafana Helm chart repository"></p>
<p>We have downloaded the latest version of the Grafana.</p>
<h3>5. Install grafana/loki stack using the helm chart</h3>
<p>Create a <strong>loki-values yaml</strong> file with the below snippet</p>
<pre><code>loki:
  readinessProbe: {}
  auth_enabled: false
  storage:
    bucketNames:
      chunks: grafana-loki-chunks-bucket
      ruler: grafana-loki-rules-bucket
      admin: grafana-loki-admin-bucket
    type: s3
    s3:
      endpoint: null
      region: us-east-1
      secretAccessKey: null
      accessKeyId: null
      s3ForcePathStyle: false
      insecure: false
monitoring:
  lokiCanary:
      enabled: false
  selfMonitoring:
    enabled: false
test:
  enabled: false
serviceAccount:
  create: true
  name: grafana-loki-access-s3-role-sa
  imagePullSecrets: []
  annotations:
    eks.amazonaws.com/role-arn: arn:aws:iam::account_id:role/loki-role
  automountServiceAccountToken: true
</code></pre>
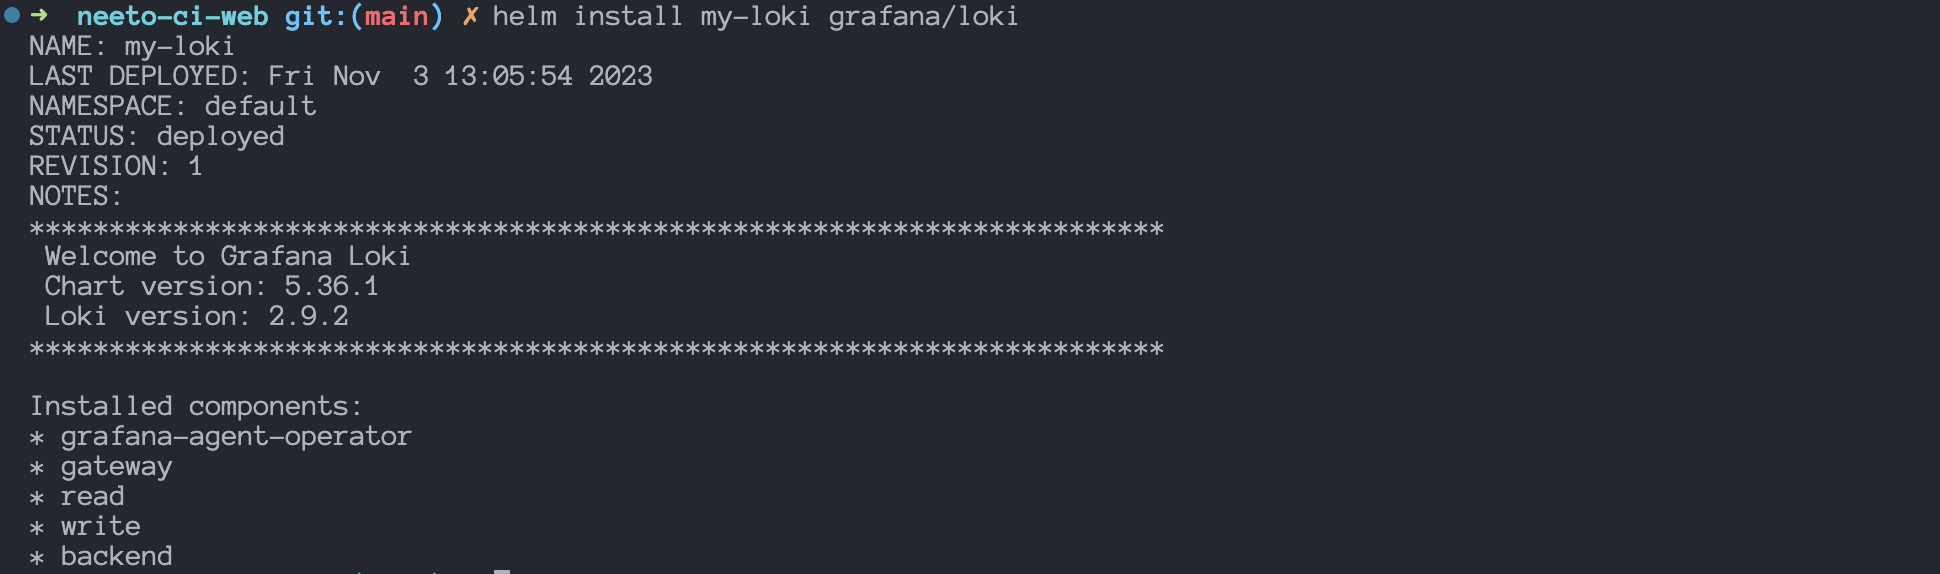
<p>To install Loki using the Helm Chart on Kubernetes Cluster, run
this <code>helm install</code> command:</p>
<pre><code class="language-jsx">helm install my-loki grafana/loki --values loki-values.yaml
</code></pre>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/chart-installation-output.png" alt="Terminal output from installing the Loki Helm chart"></p>
<p>We have successfully installed Loki on the Kubernetes Cluster.</p>
<p>Run the following command to view all the resources created by the Loki Helm
Chart in your Kubernetes cluster:</p>
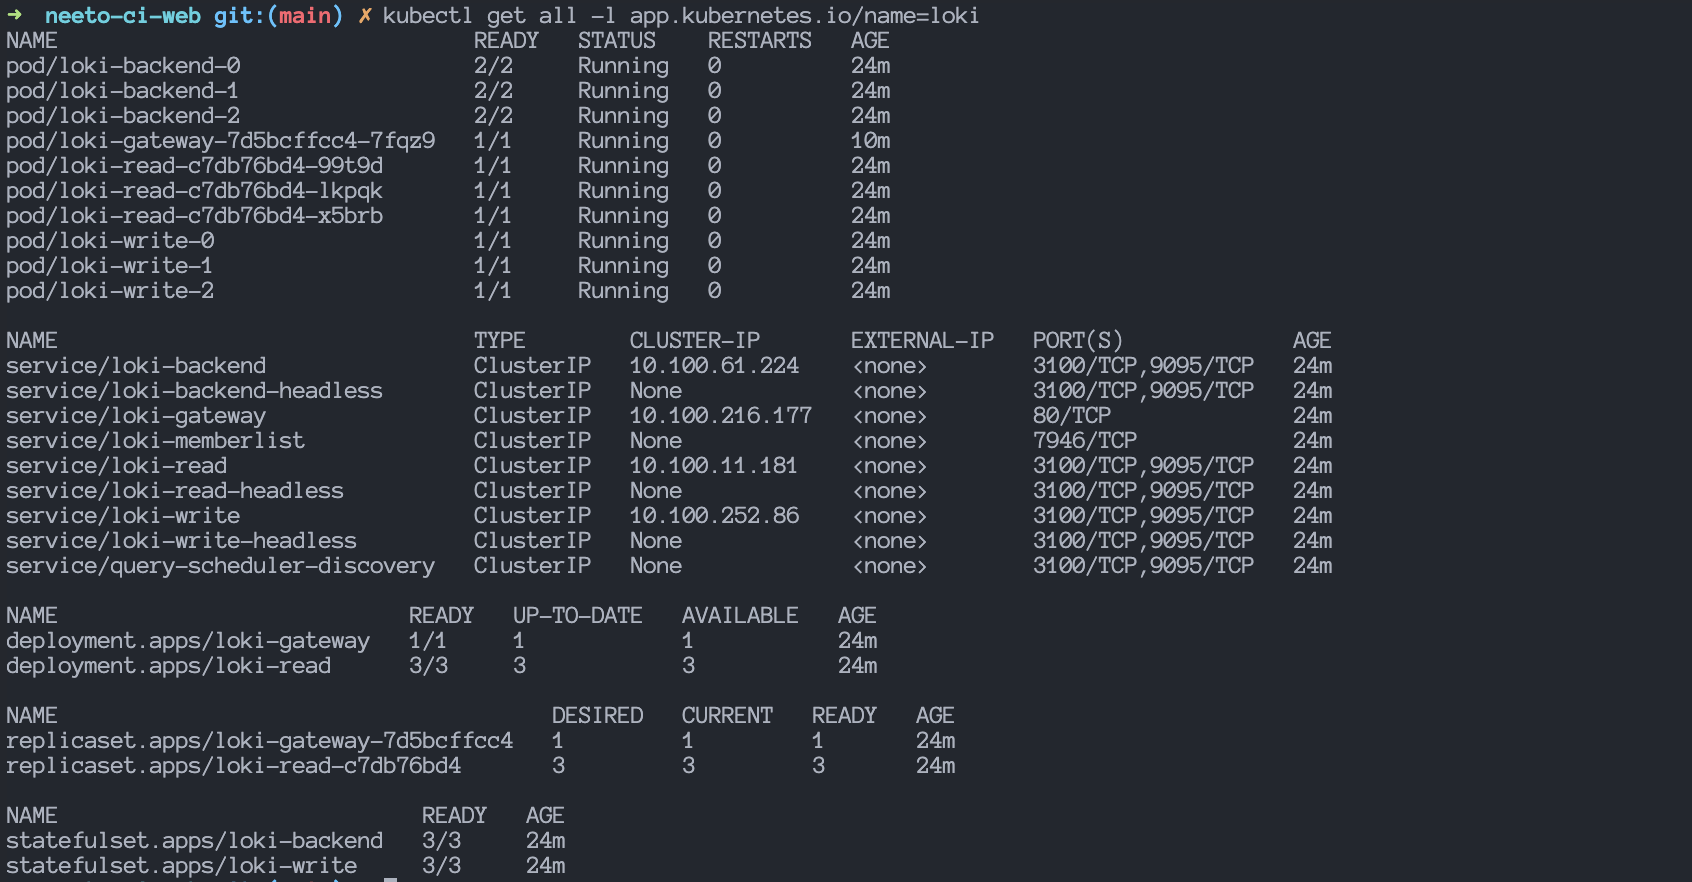
<pre><code class="language-jsx">kubectl get all -l app.kubernetes.io/name=loki
</code></pre>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/all-resources-output.png" alt="Output of kubectl get all for the Loki release, listing its pods, services and deployments"></p>
<p>Helm chart created the following components:</p>
<ul>
<li><strong>Loki read and write:</strong> Loki is installed in scalable mode by default, which
includes a read-and-write component. These components can be independently
scaled out.</li>
<li><strong>Gateway:</strong> Inspired by Grafana’s
<a href="https://github.com/grafana/loki/blob/main/production/ksonnet/loki">Tanka setup</a>,
the chart installs a gateway component by default. This NGINX component
exposes Loki’s API and automatically proxies requests to the appropriate Loki
components (read or write, or a single instance in the case of filesystem
storage). The gateway must be enabled to provide an Ingress since the Ingress
only exposes the gateway. If enabled, Grafana and log shipping agents, such as
Promtail, should be configured to use the gateway. If NetworkPolicies are
enabled, they become more restrictive when the gateway is active.</li>
<li><strong>Caching:</strong> In-memory caching is enabled by default. If this type of caching
is unsuitable for your deployment, consider setting up memcache.</li>
</ul>
<p>Run this command to view all the Kubernetes Services for Prometheus &amp; Grafana:</p>
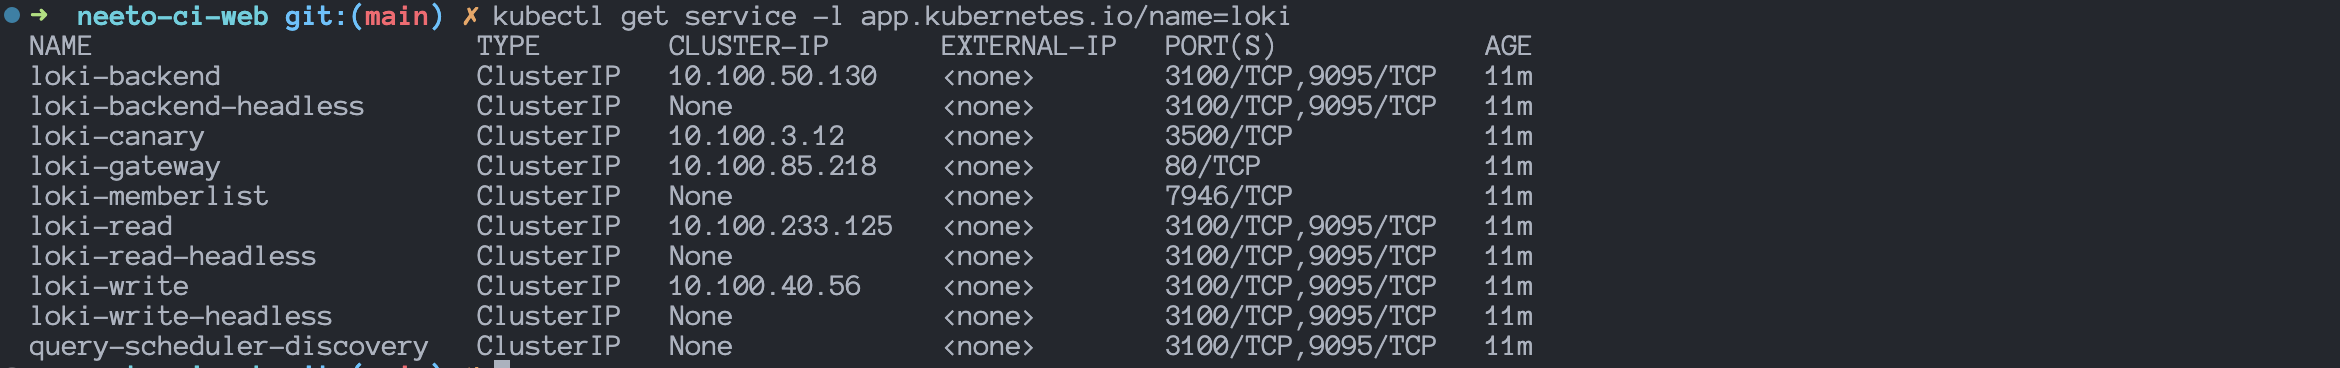
<pre><code class="language-jsx">kubectl get service -l app.kubernetes.io/name=loki
</code></pre>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/all-services-output.png" alt="Output of kubectl get service for the Loki release, listing its services"></p>
<p>Listed services for Loki are:</p>
<ul>
<li>loki-backend</li>
<li>loki-backend-headless</li>
<li>loki-gateway</li>
<li>loki-memberlist</li>
<li>loki-read</li>
<li>loki-read-headless</li>
<li>loki-write</li>
<li>loki-write-headless</li>
<li>query-scheduler-discovery</li>
</ul>
<p>The <code>loki-gateway</code> service will be used to add Loki as a Datasource into
Grafana.</p>
<h3>6. Adding Loki data source in Grafana</h3>
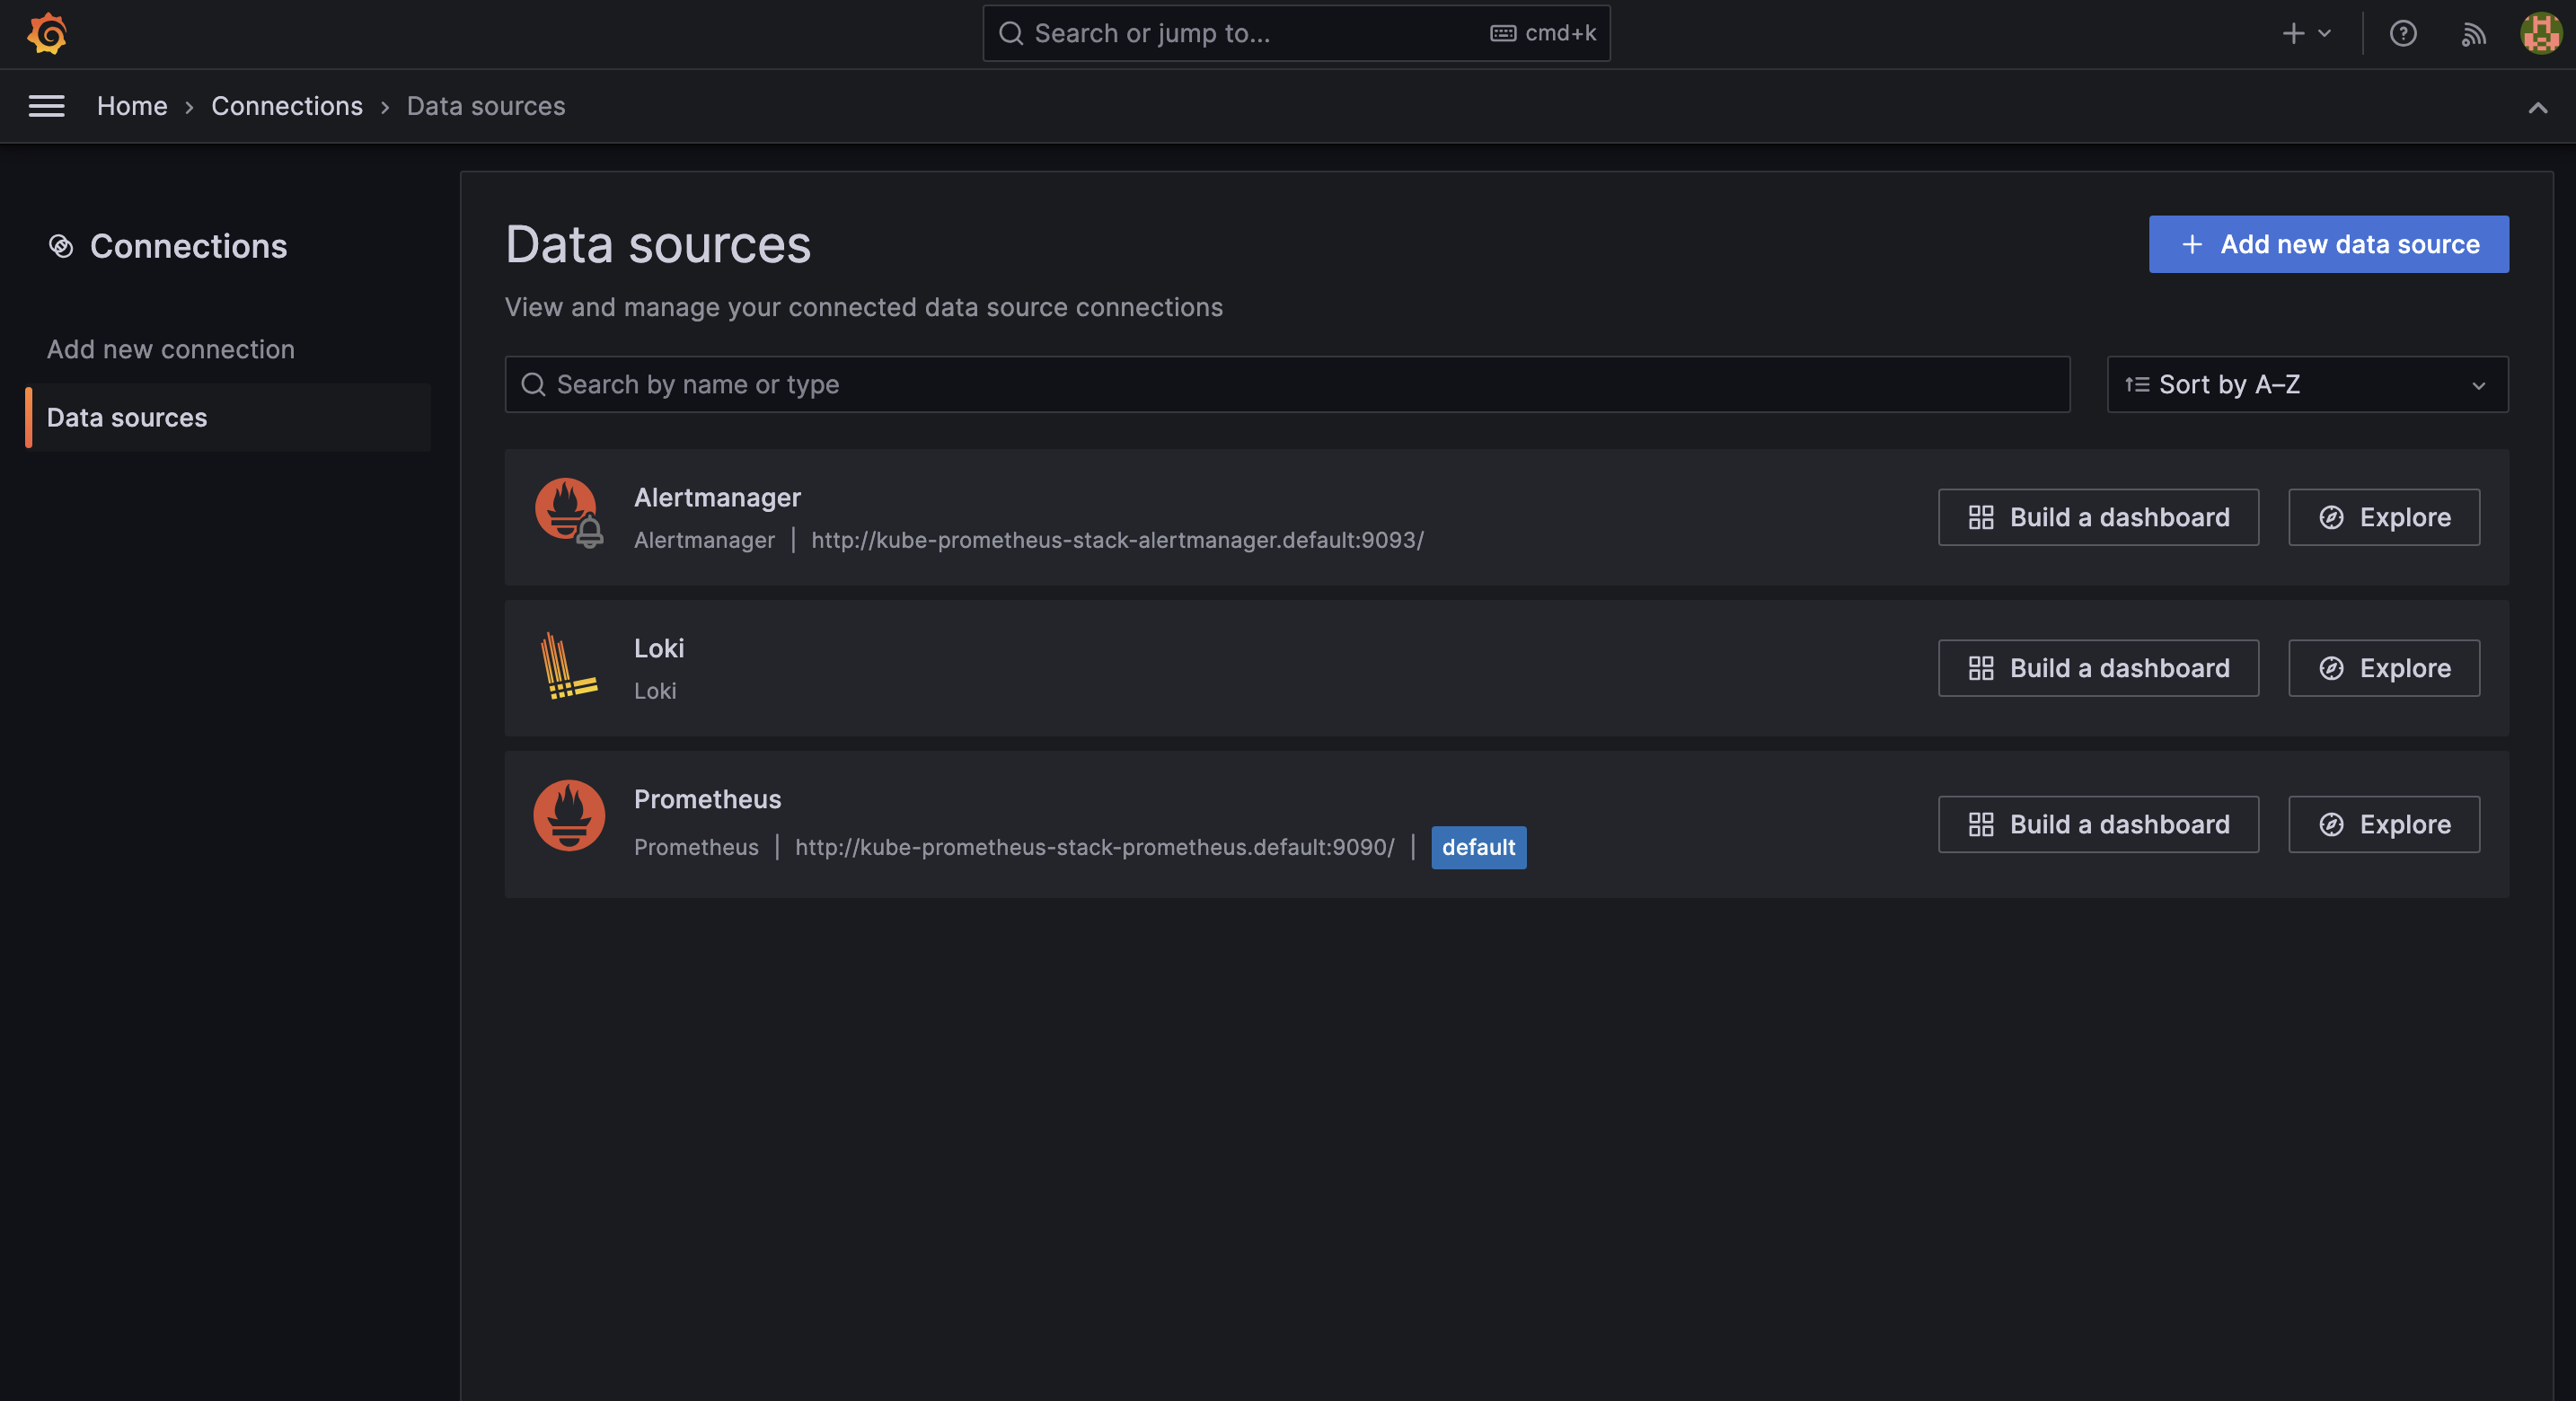
<p>On the main page of Grafana, click on &quot;<strong>Home</strong>&quot;. Under &quot;<strong>Connections</strong>&quot;, you
will find the &quot;<strong>Data sources</strong>&quot; option.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/grafana-dashboard.webp" alt="The Grafana home page, with the Data sources option listed under Connections"></p>
<p>On the Data Sources page, click on the &quot;Add new data source&quot; button.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/data-sources-page.png" alt="The Grafana Data sources page with the Add new data source button"></p>
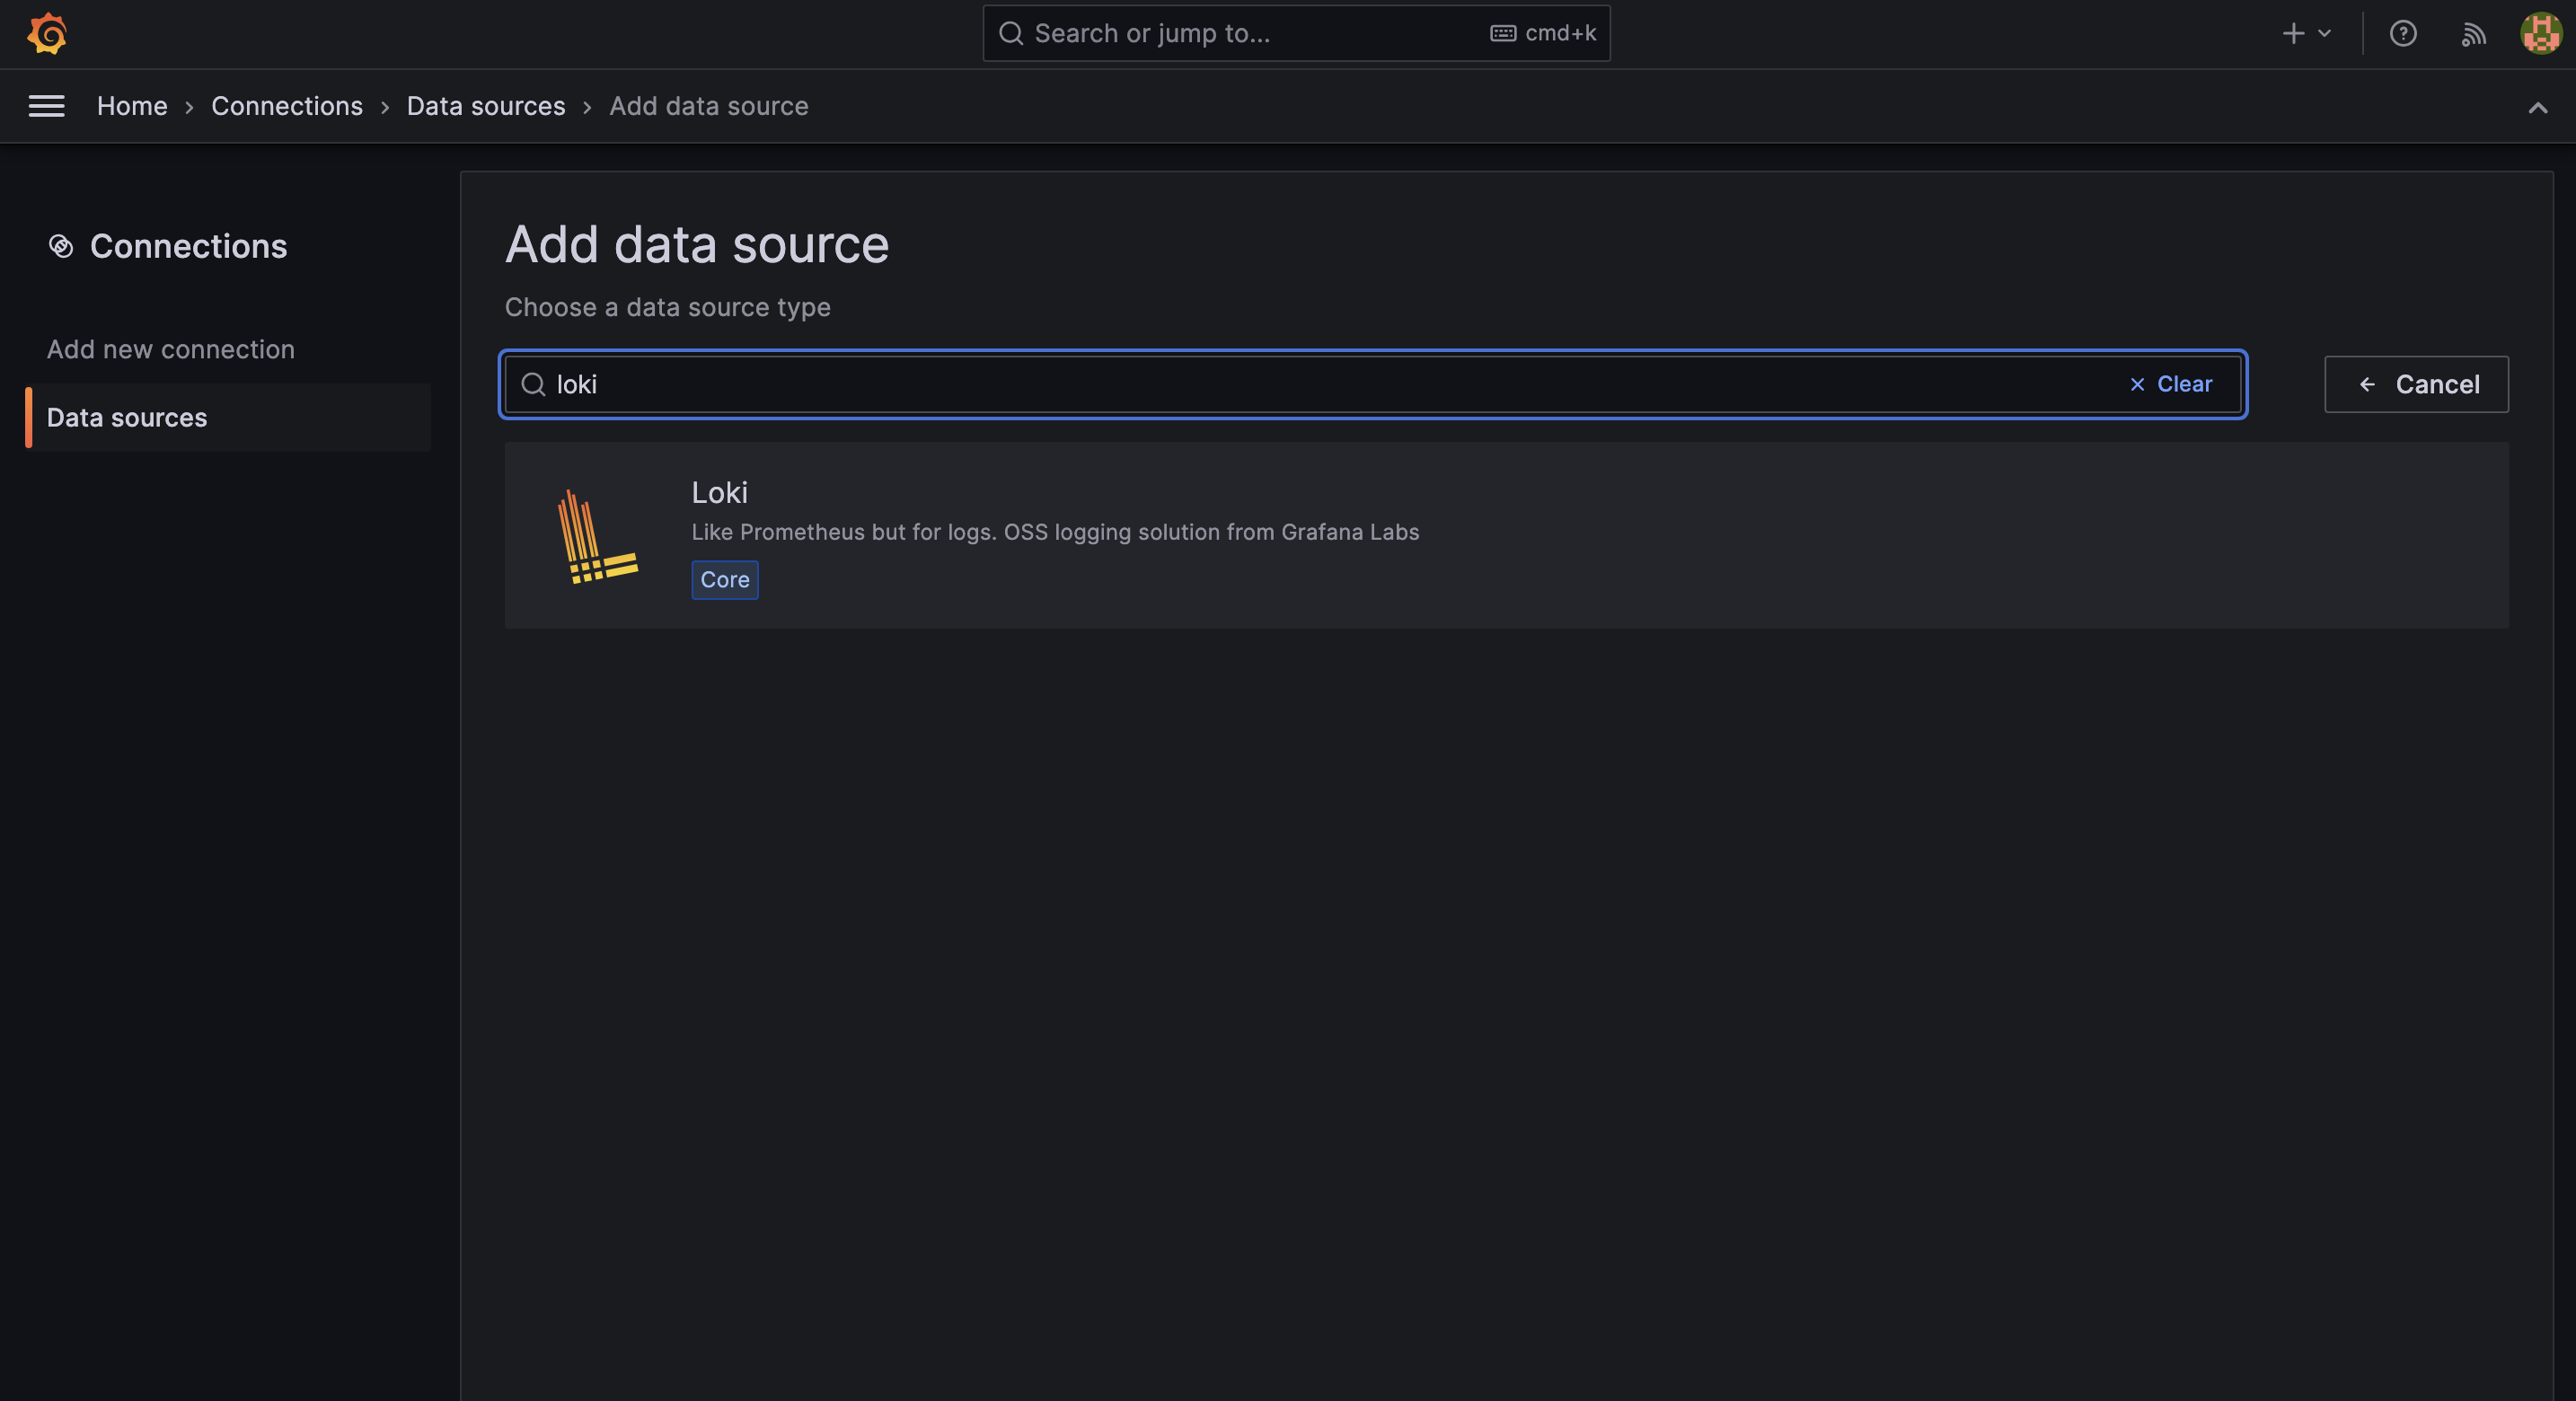
<p>In the search bar, type &quot;Loki&quot; and search for it.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/add-data-source.png" alt="Search results for Loki on the Add data source page"></p>
<p>Clicking on &quot;Loki&quot; will redirect you to the dedicated page for the Loki data
source.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/loki-data-source.png" alt="The dedicated settings page for the Loki data source in Grafana"></p>
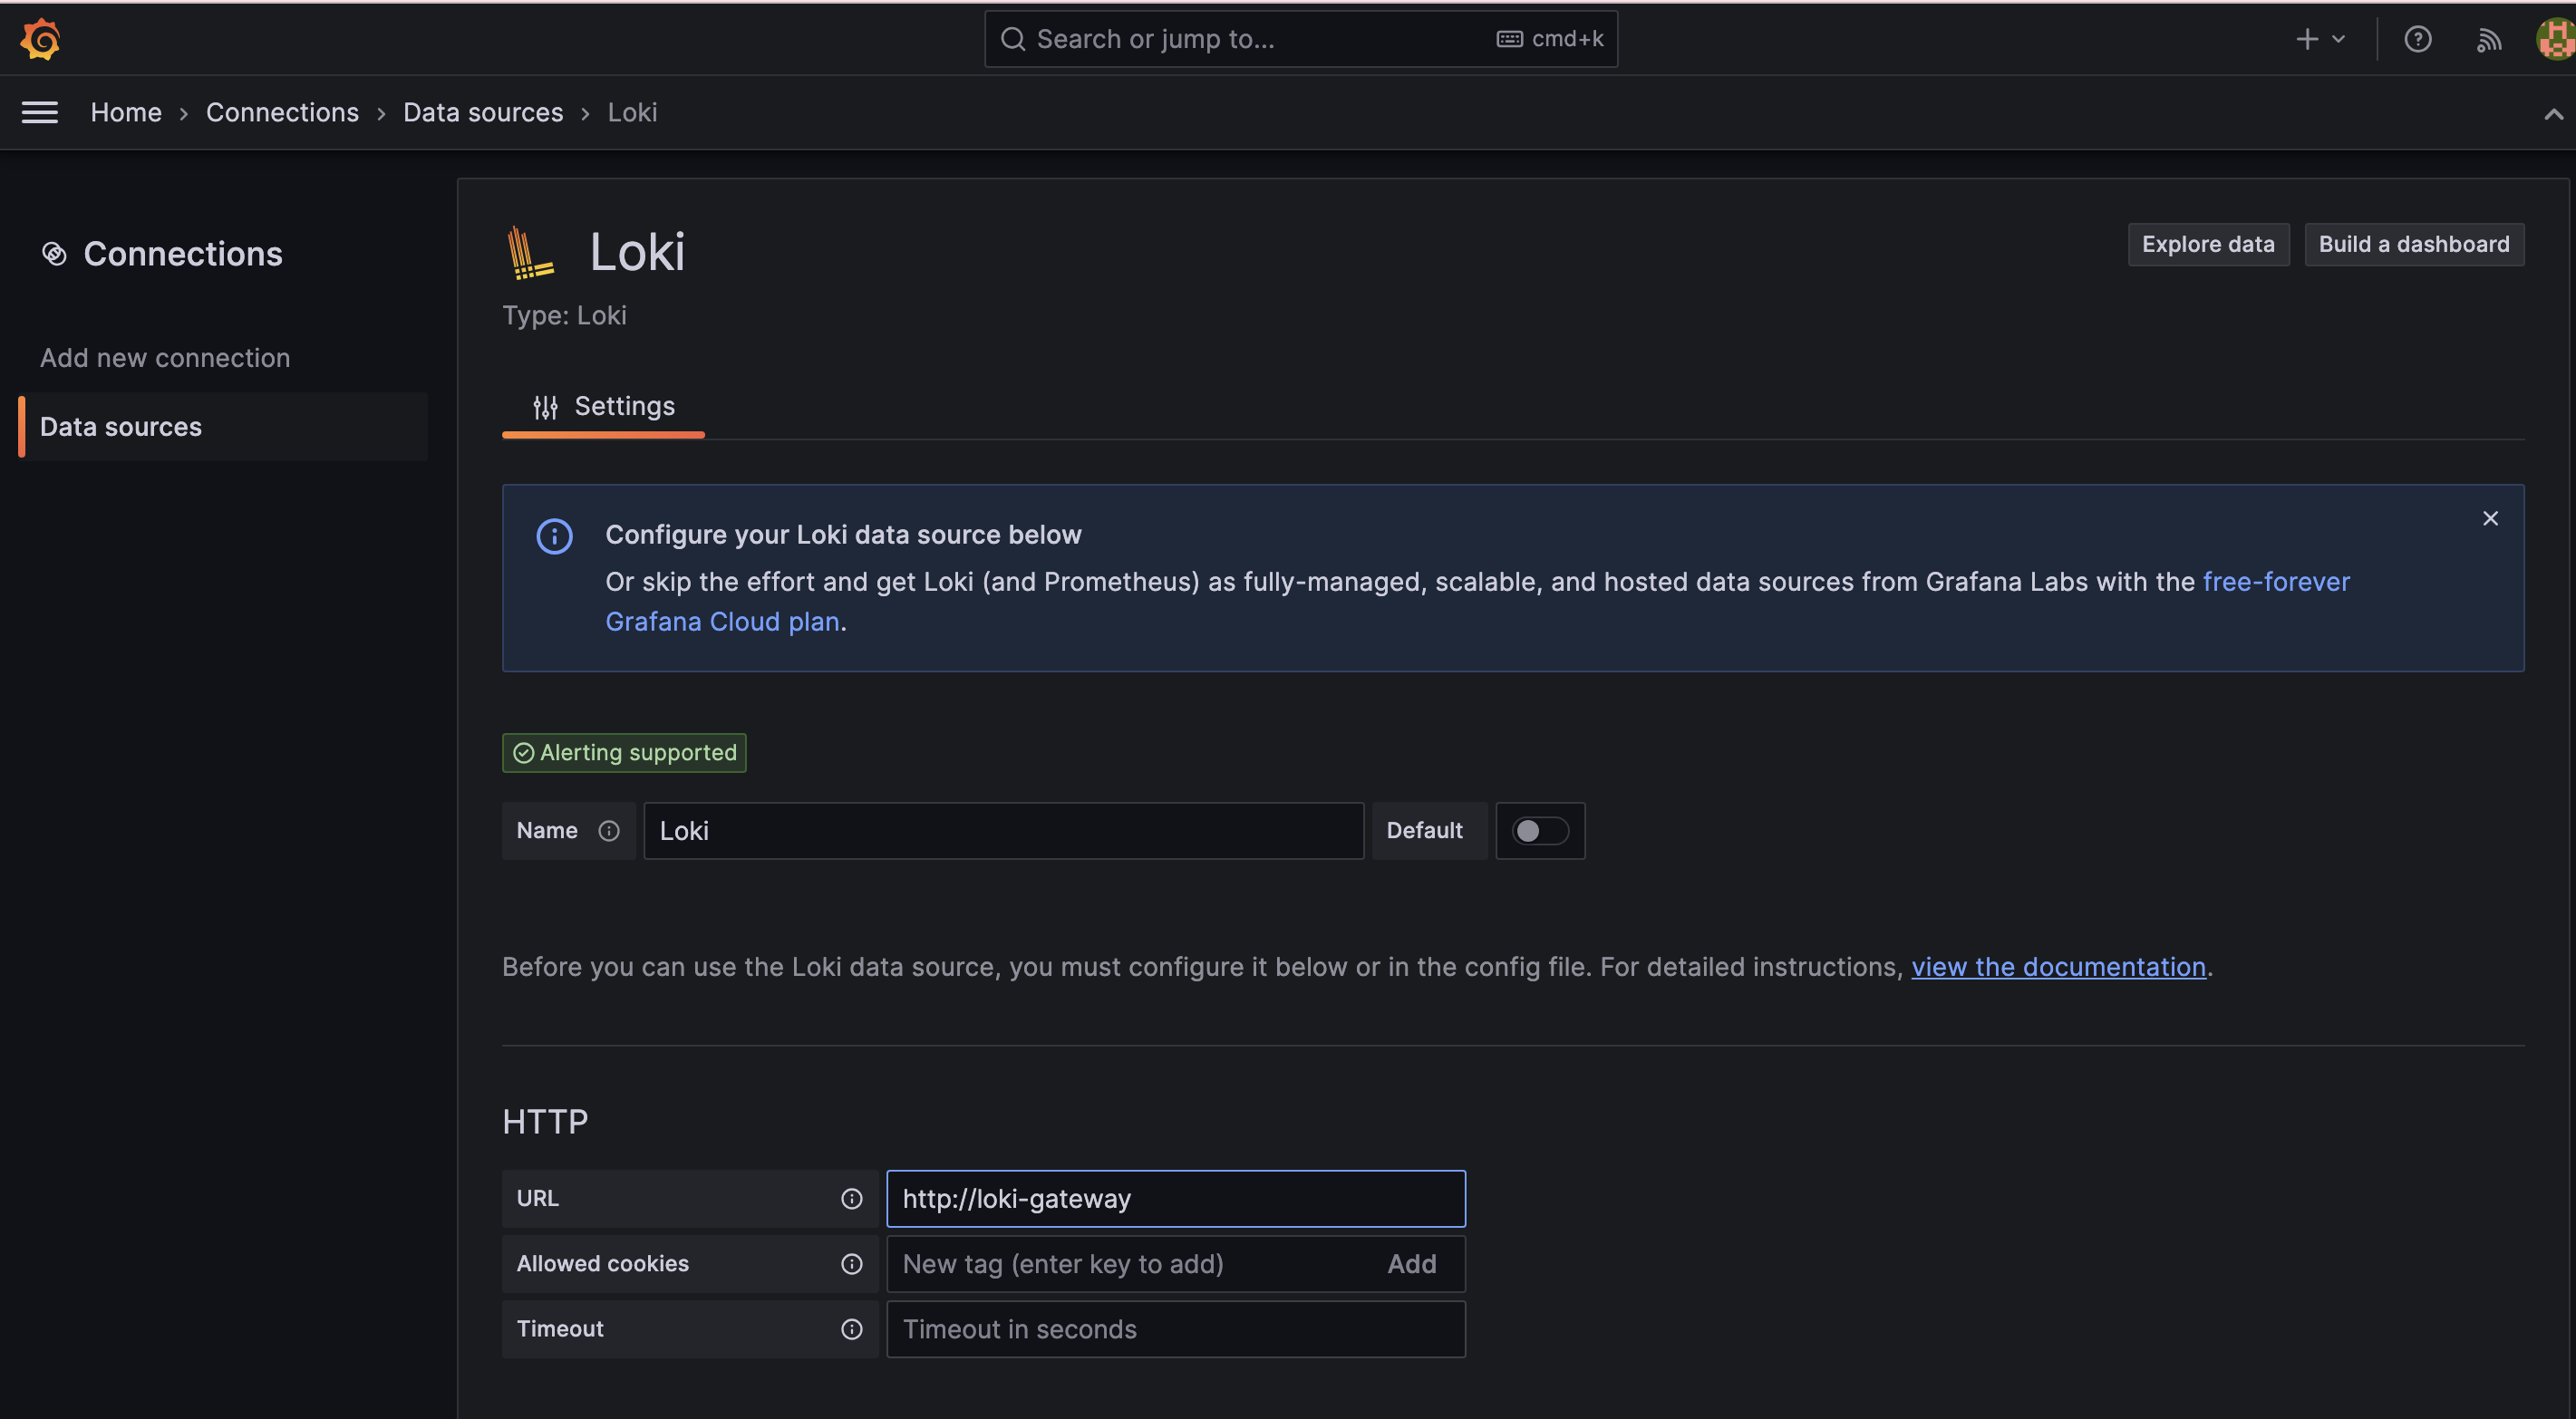
<p>To read the metrics from Loki, we will use the <code>loki-gateway</code> service. Add the
URL of the service as <code>http://loki-gateway</code>.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/loki-form.png" alt="The Loki data source form with the connection URL set to http://loki-gateway"></p>
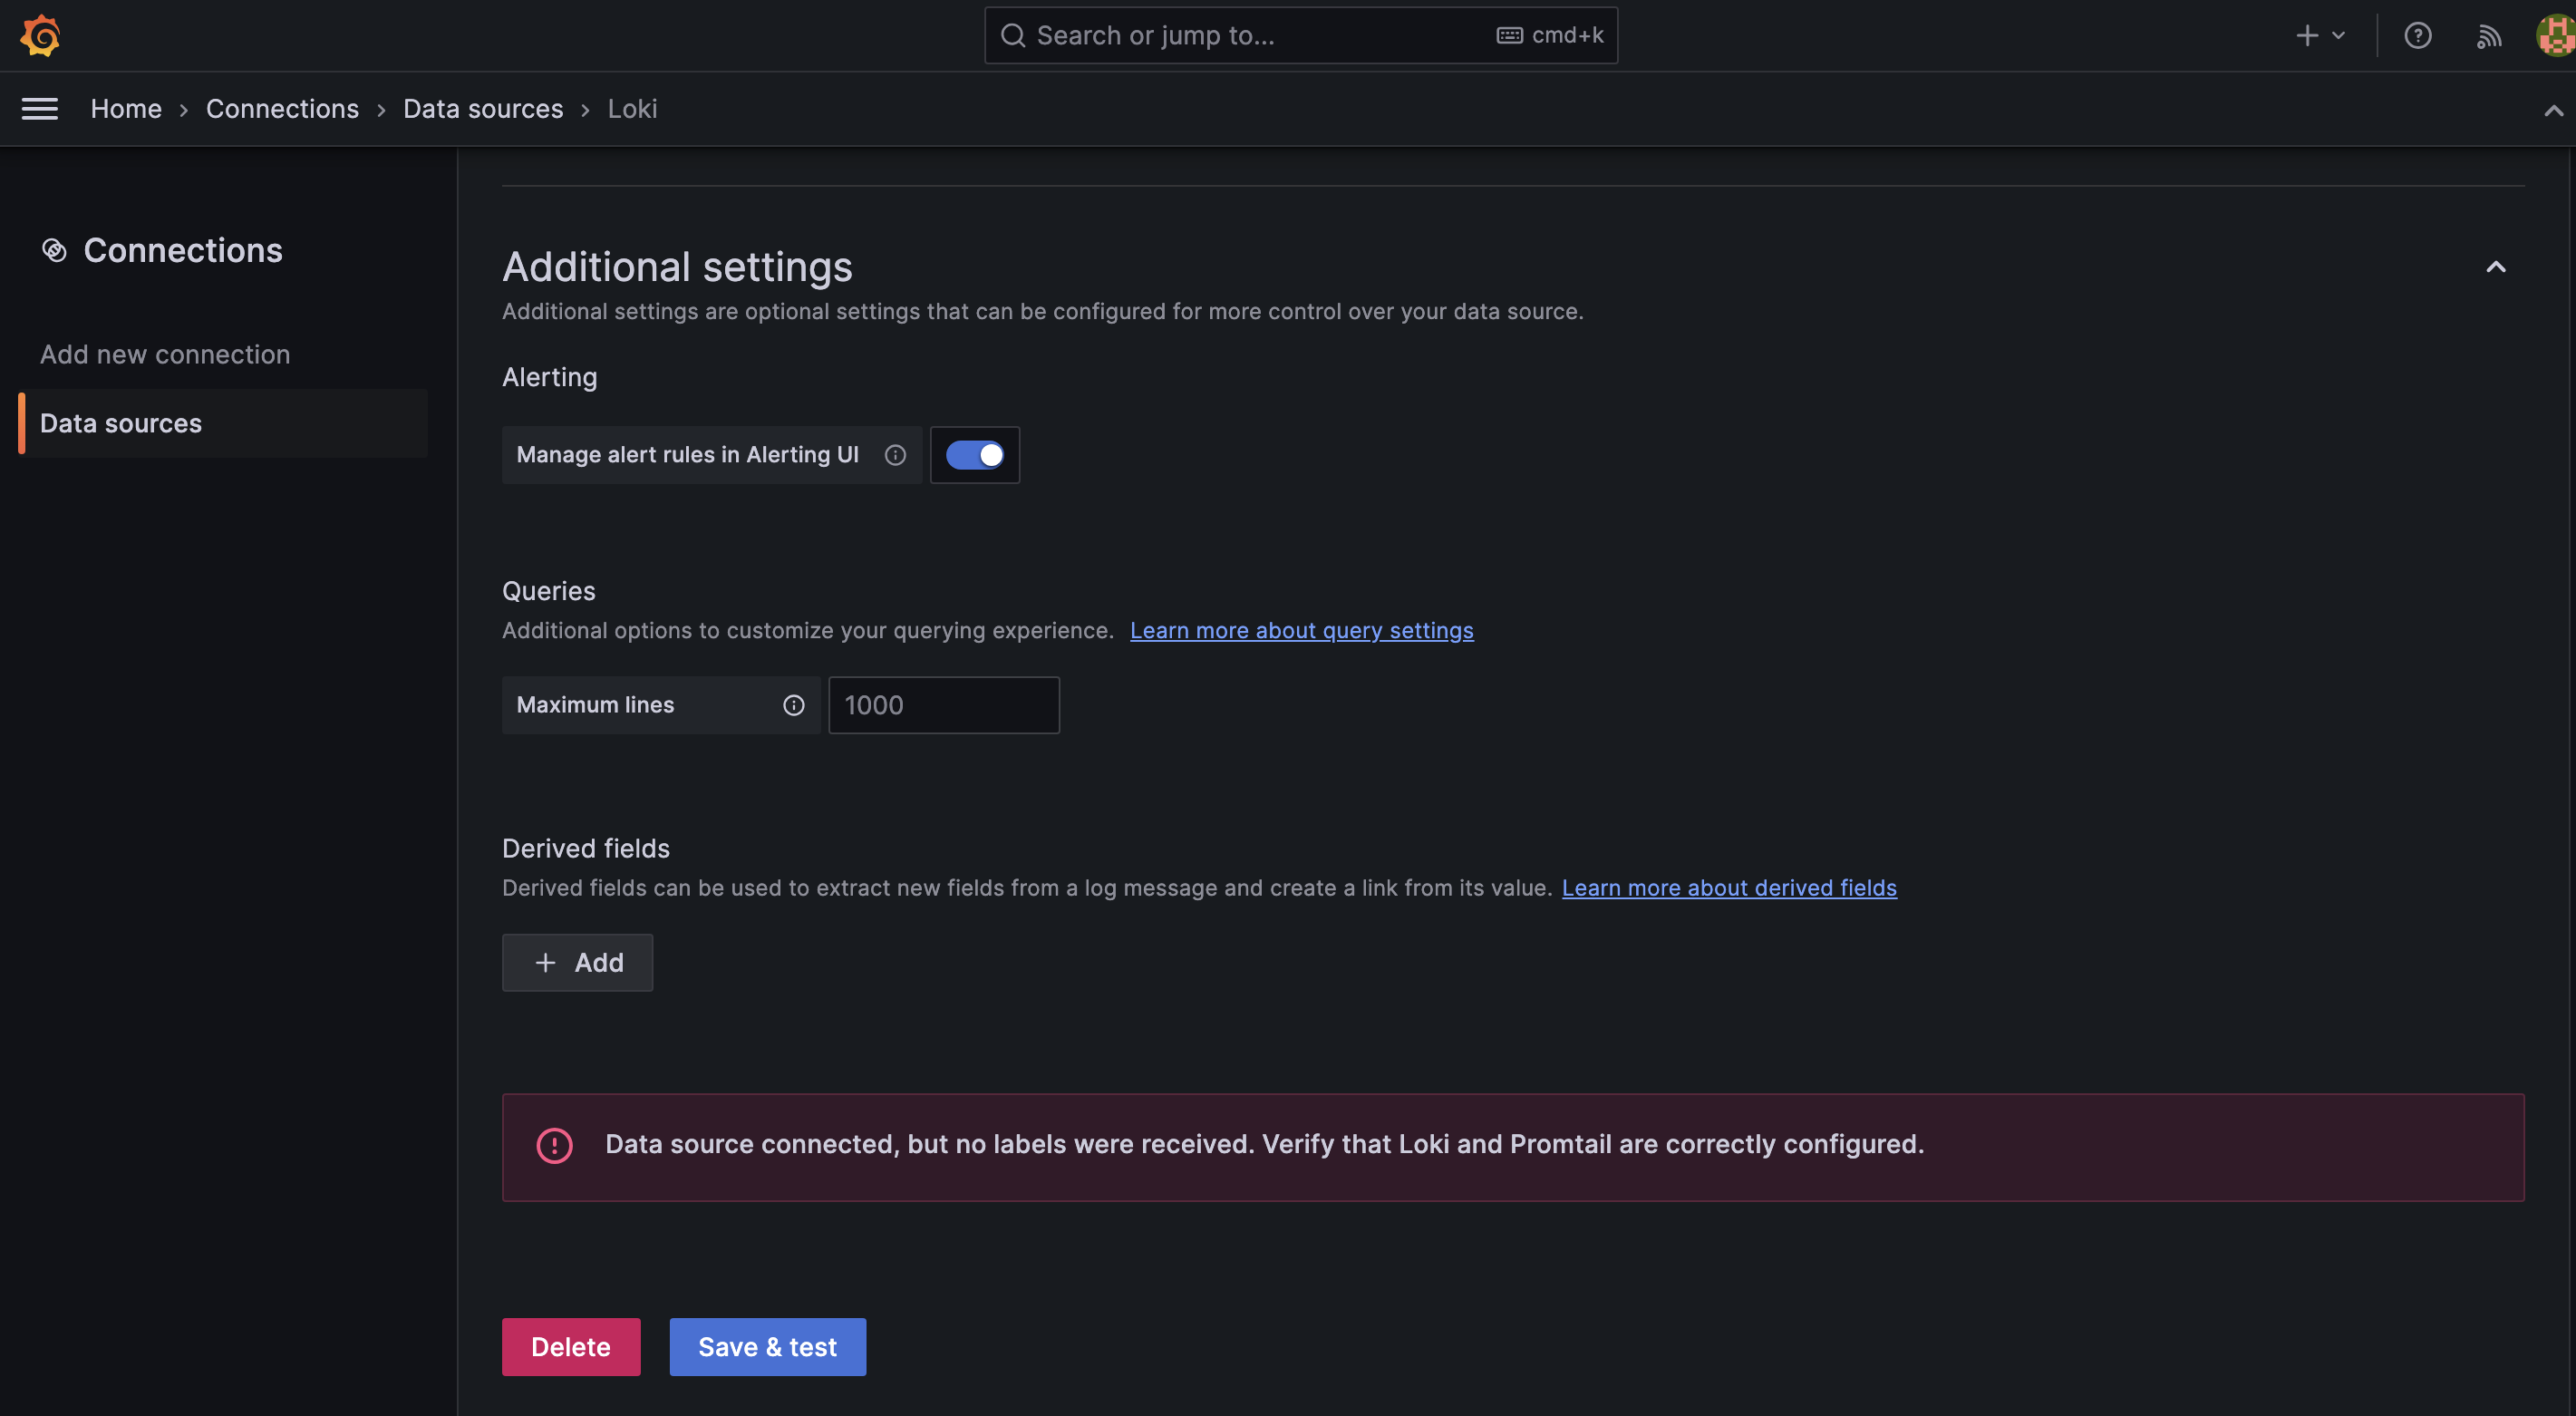
<p>After clicking on the &quot;Save &amp; test&quot; button, you will receive a toastr message
shown in the image below. This message is received because no clients have been
created for Loki yet.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/loki-addon-output.png" alt="A Grafana toast reporting that no clients exist yet for the Loki data source"></p>
<h3>7. Install Kubernetes event exporter using the helm chart</h3>
<p>Create an <strong>event-exporter-values yaml</strong> file with the below snippet</p>
<pre><code class="language-jsx">config:
  leaderElection: {}
  logLevel: debug
  logFormat: pretty
  metricsNamePrefix: event_exporter_
  receivers:
    - name: &quot;dump&quot;
      file:
        path: &quot;/dev/stdout&quot;
        layout: {}
    - name: &quot;loki&quot;
      loki:
        url: &quot;http://loki-gateway/loki/api/v1/push&quot;
        streamLabels:
          source: kubernetes-event-exporter
          container: kubernetes-event-exporter
  route:
    routes:
      - match:
          - receiver: &quot;dump&quot;
          - receiver: &quot;loki&quot;
</code></pre>
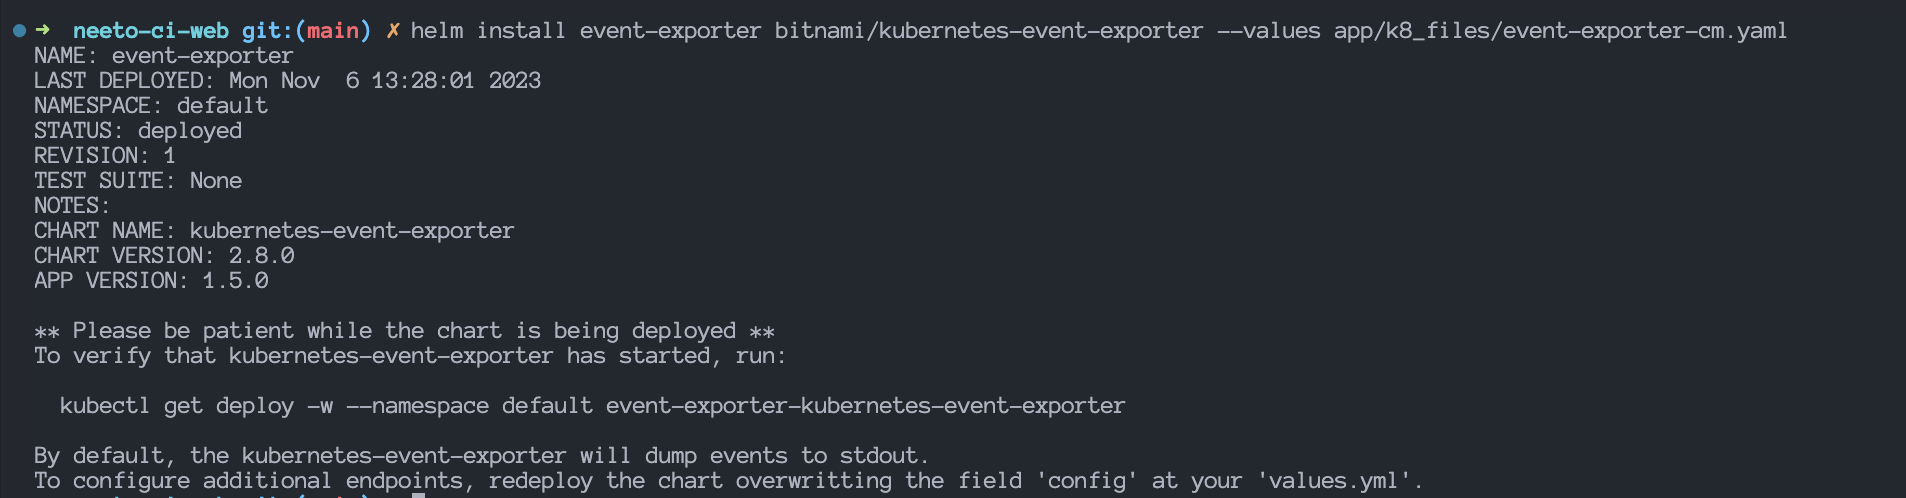
<p>With the use of the above snippet, run this command to install the Kubernetes
event exporter in your Kubernetes Cluster.</p>
<pre><code class="language-jsx">helm repo add bitnami [https://charts.bitnami.com/bitnami](https://charts.bitnami.com/bitnami)
helm install event-exporter bitnami/kubernetes-event-exporter --values event-exporter.yaml
</code></pre>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/event-exporter-installation-output.png" alt="Terminal output from installing the kubernetes-event-exporter Helm chart"></p>
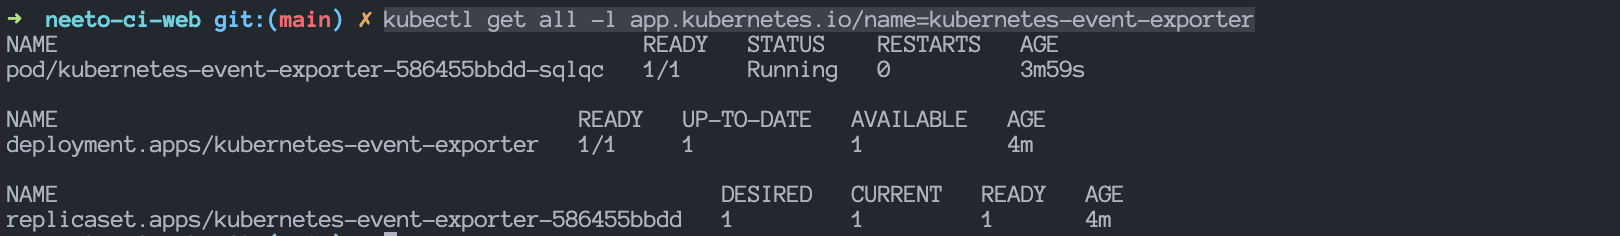
<p>To view all the resources created by the above helm chart, run this command:</p>
<pre><code class="language-jsx">kubectl get all -l app.kubernetes.io/name=kubernetes-event-exporter
</code></pre>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/event-exporter-all-resources.png" alt="Output of kubectl get all for the event exporter release, listing its pod and deployment"></p>
<p>To view the logs of the event exporter POD, run this command:</p>
<pre><code class="language-jsx">kubectl logs -f pod/kubernetes-event-exporter-586455bbdd-sqlqc
</code></pre>
<p>Note: Replace <strong>kubernetes-event-exporter-586455bbdd-sqlqc</strong> with your pod name.</p>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/event-exporter-logs.webp" alt="event-exporter-logs"></p>
<p>As you can see in the above image, the event exporter is working and running
fine. Event logs are being sent to both the receivers that we’d configure in the
values YAML file.</p>
<p>Once the POD is created &amp; running, we can go back to the Loki data source under
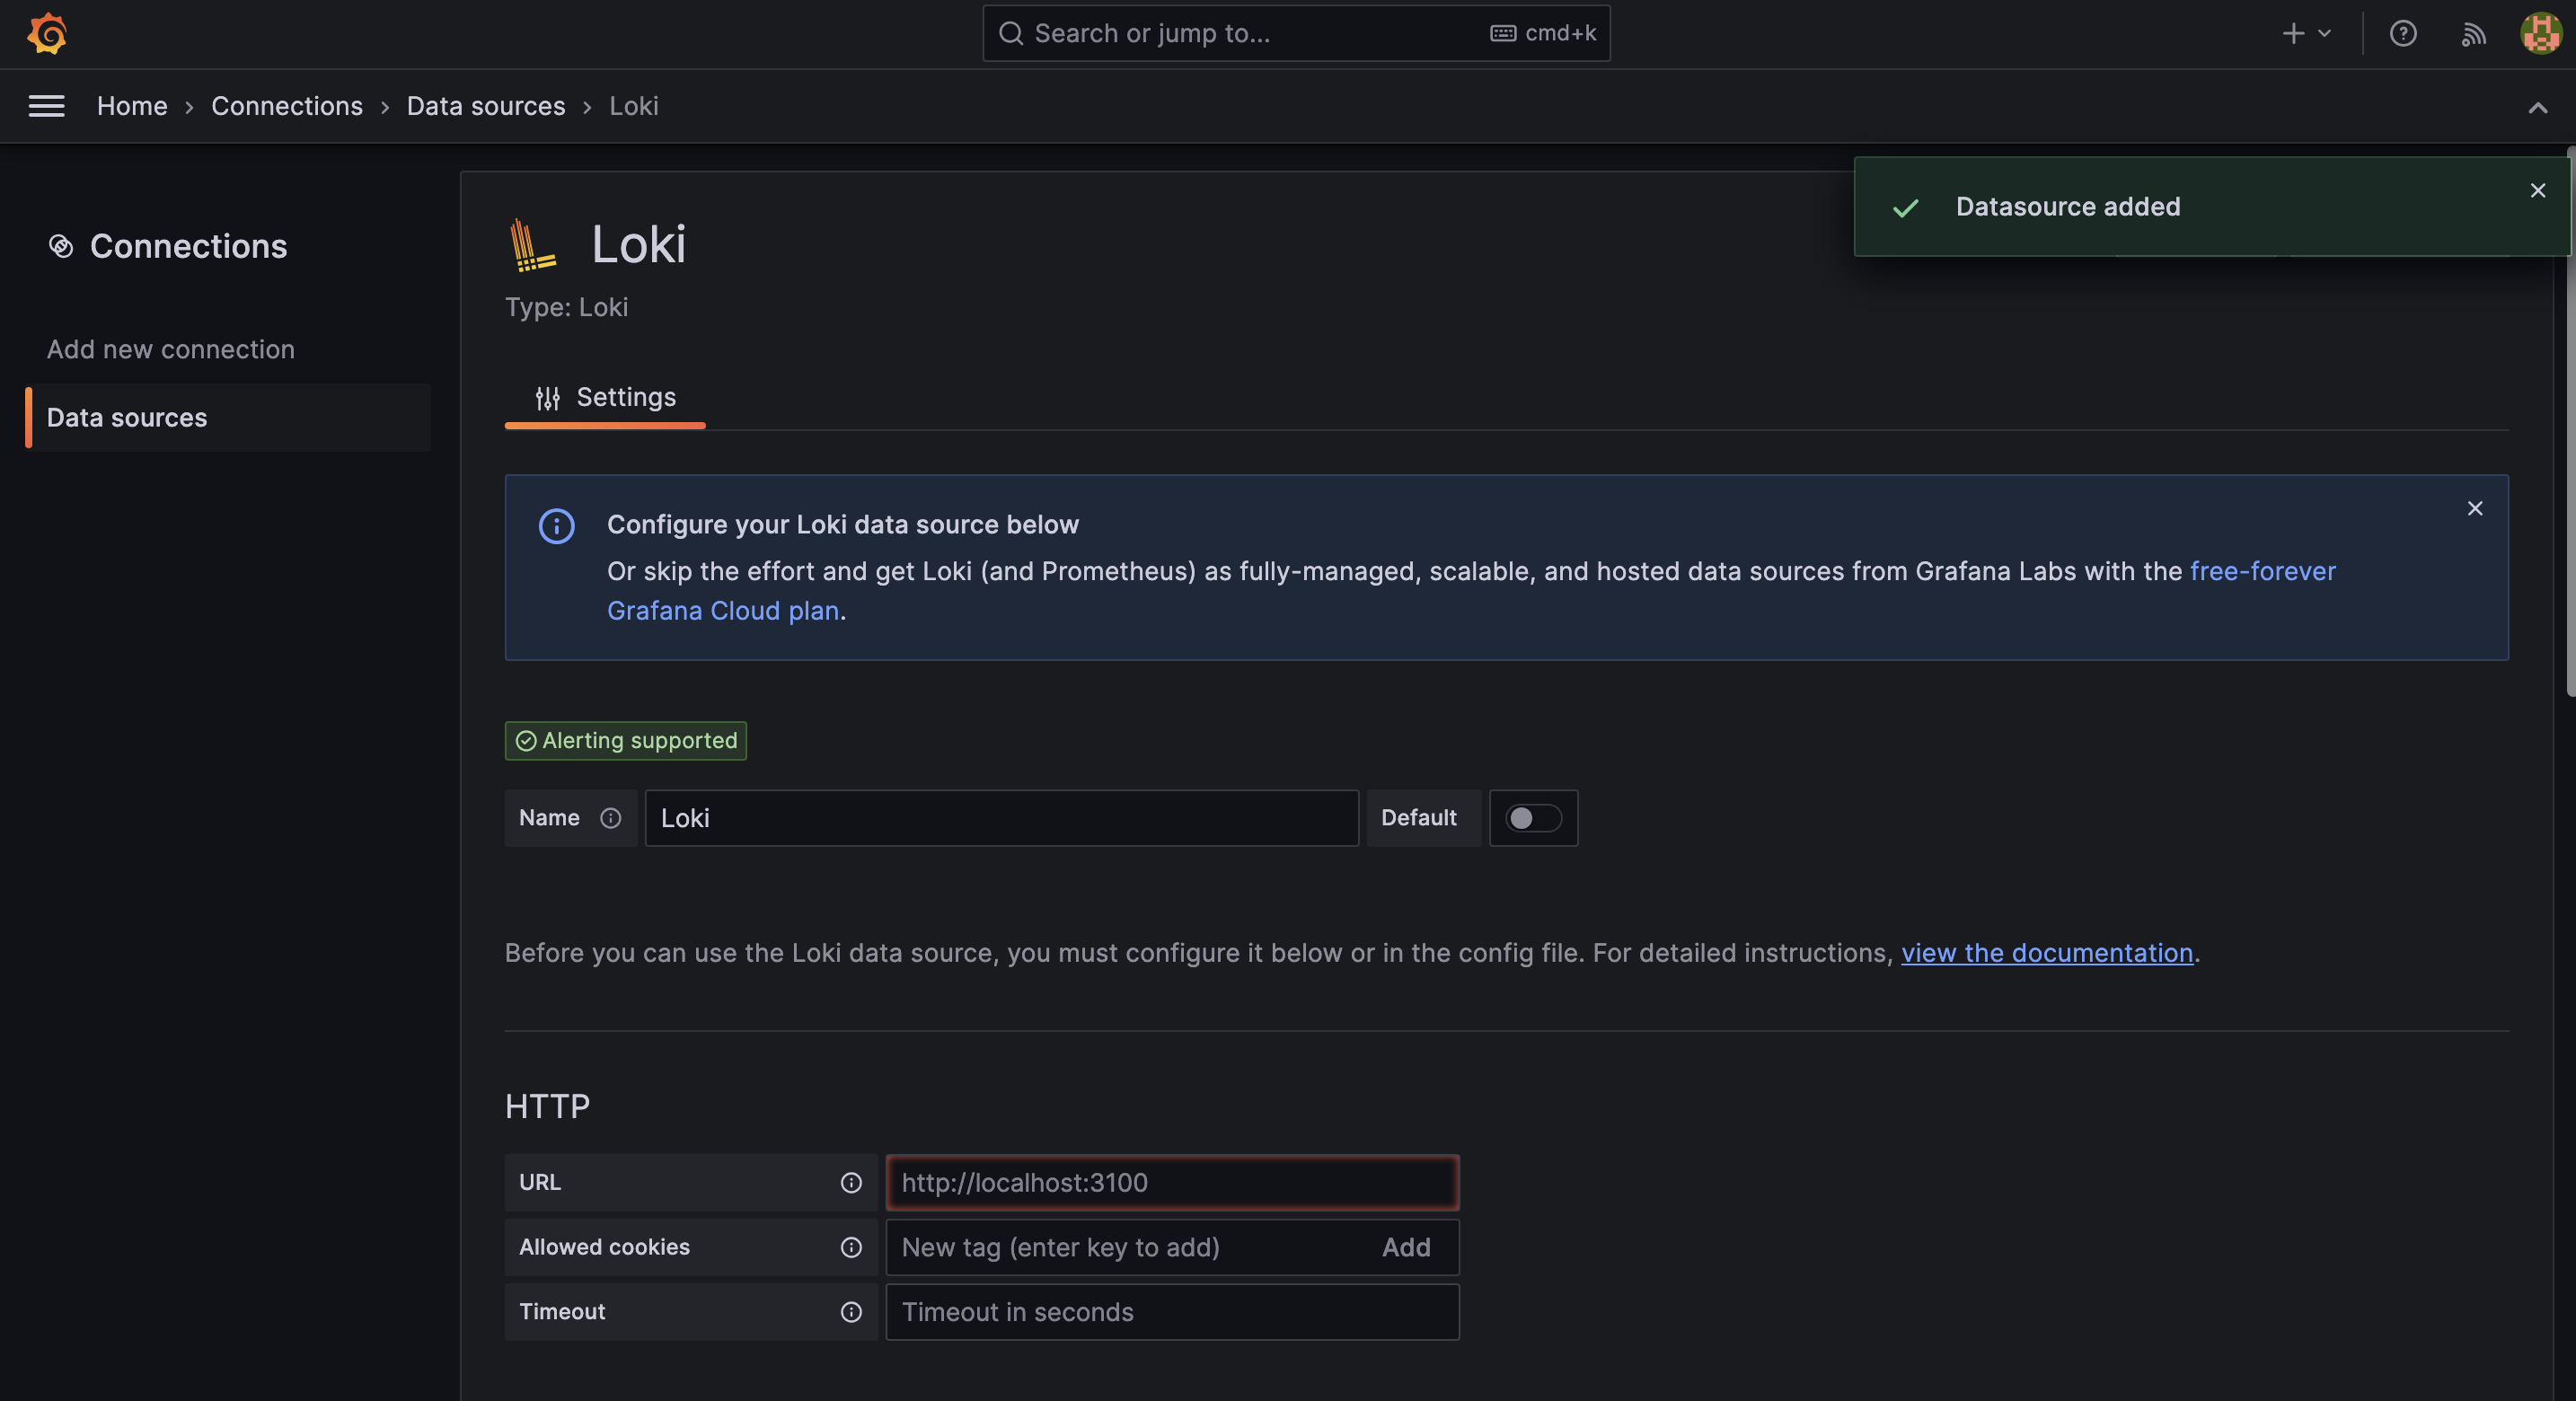
<strong>Connections</strong> &gt; <strong>Data Sources</strong> page.</p>
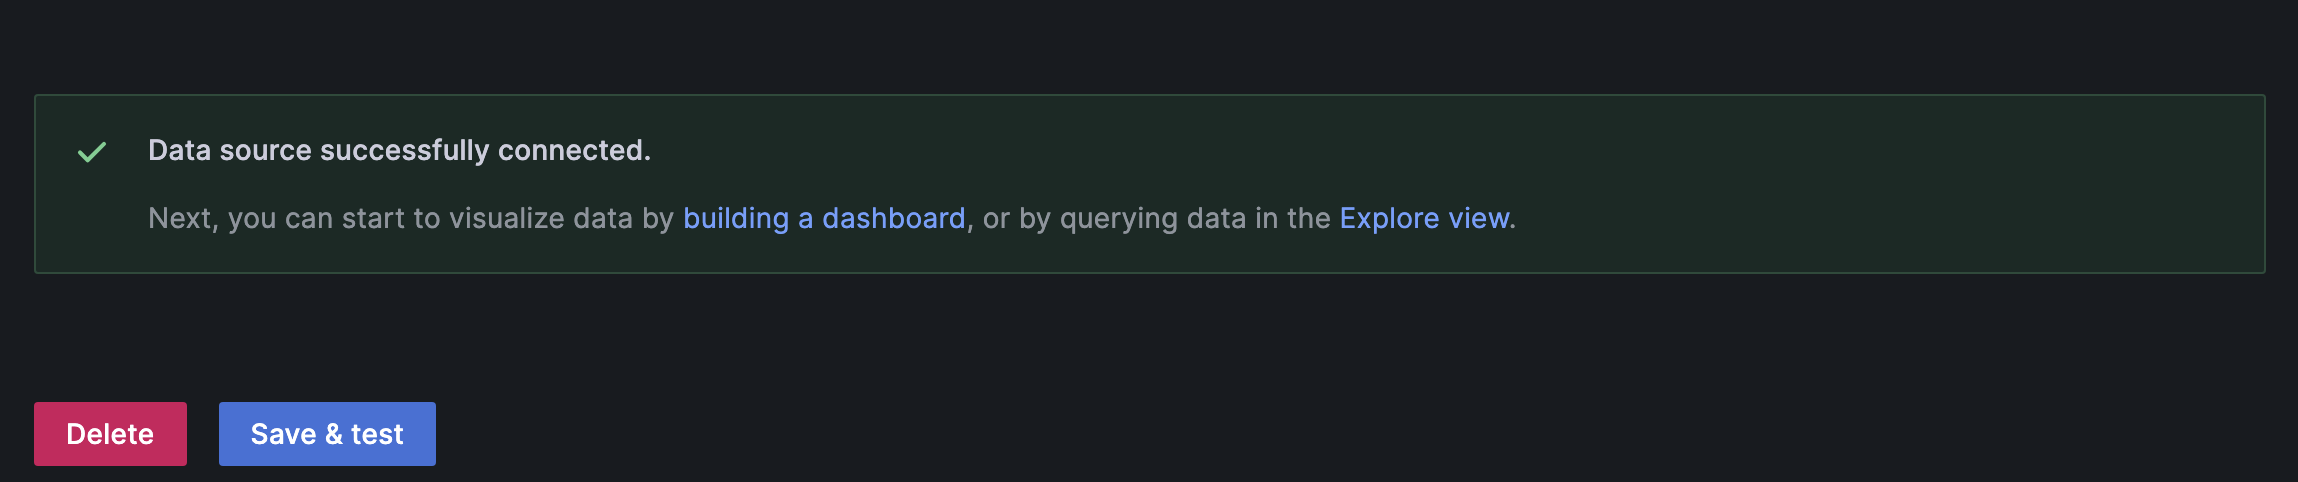
<p>Again click on the “Save &amp; test” button &amp; this time you’ll receive a success
toastr message.</p>
<p>Output:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/loki-data-source-added-output.png" alt="loki-data-source-added-output"></p>
<h3>8. Kubernetes event exporter dashboard</h3>
<p>We will import this
<a href="https://grafana.com/grafana/dashboards/17882-kubernetes-event-exporter/">dashboard</a>
into Grafana to monitor and track the events received from the Kubernetes
cluster. You can go through this blog if you want to learn how to import an
existing dashboard into Grafana.</p>
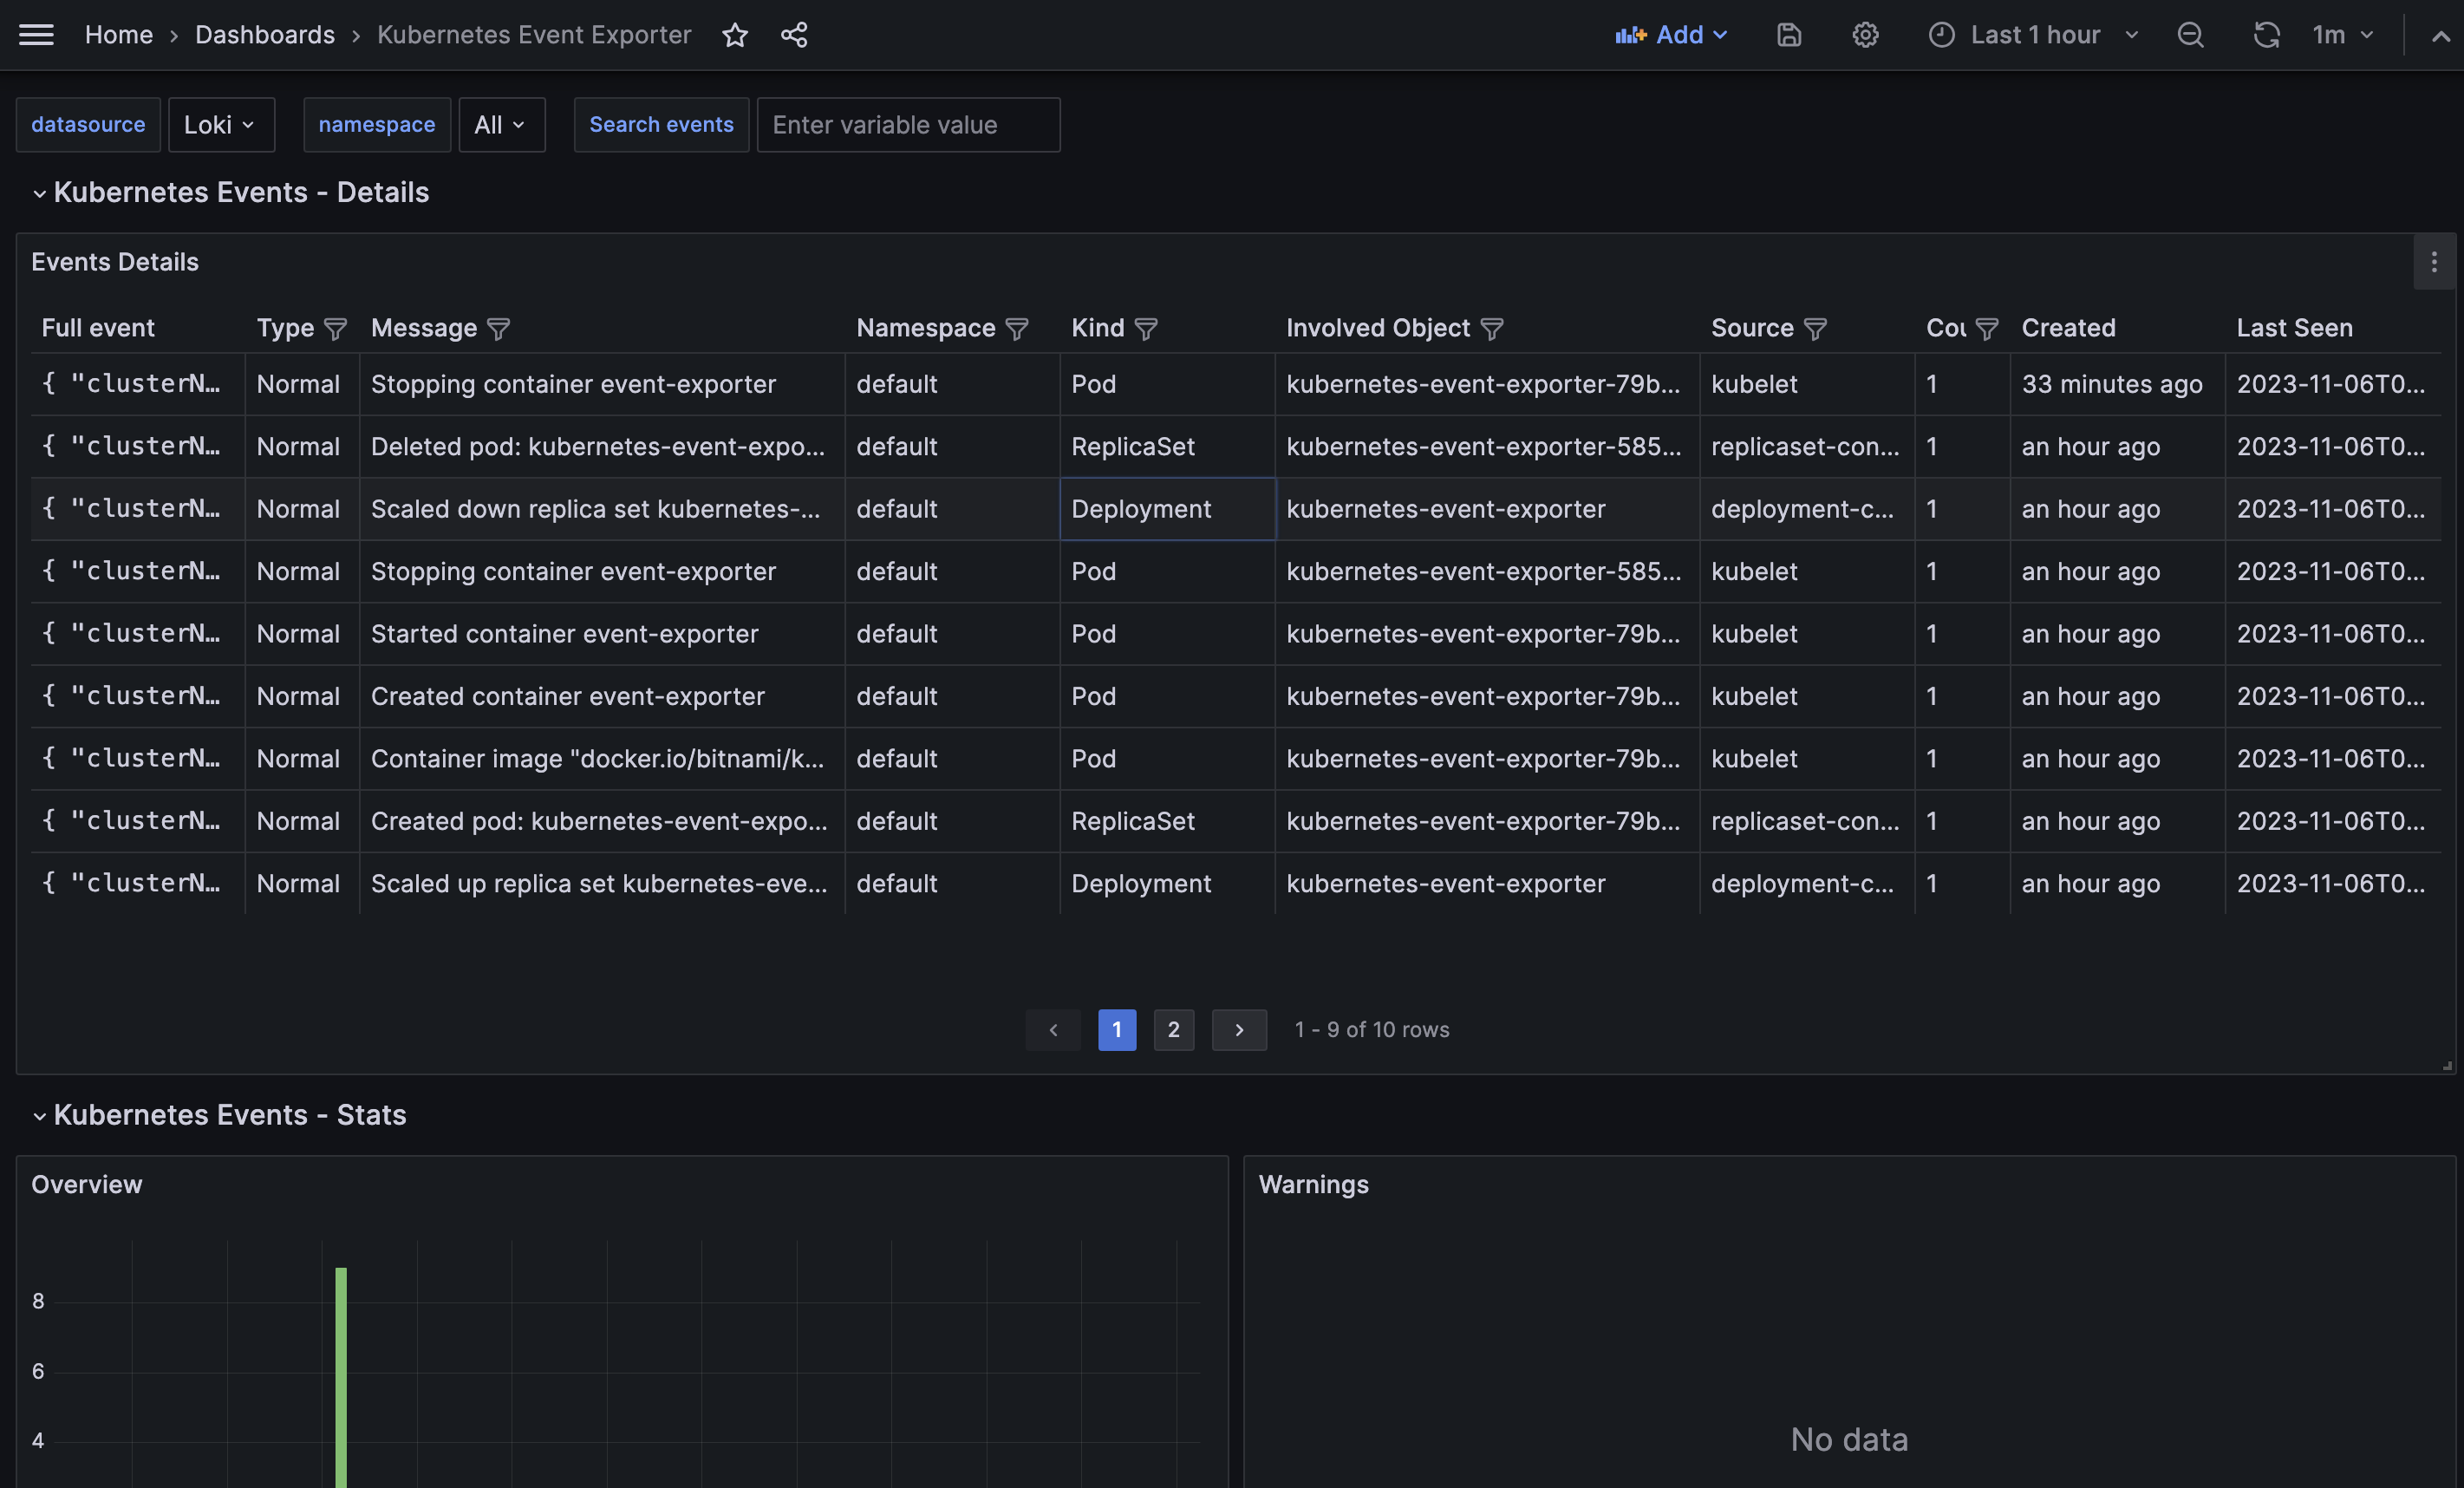
<p>After successfully importing the dashboard, you can view all the events from the
cluster, as shown in the image below. Additionally, you can filter the events
based on any value within any interval.</p>
<p>Kubernetes Event Exporter</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/k8s-event-exporter-and-grafana-loki-integration/event-exporter-dashboard.png" alt="Kubernetes Event Exporter"></p>
<h2>Conclusion</h2>
<p>In this blog post, we discussed the process of setting up Grafana Loki and
Kubernetes Event exporter. We covered various steps, such as creating a policy
for Grafana Loki, creating a role with the necessary permissions, and adding
Grafana using the Helm chart, installing the Loki stack, and adding Loki as a
data source in Grafana, installing Kubernetes event exporter using the Helm
chart, and finally, setting up the Kubernetes event exporter dashboard in
Grafana.</p>
<p>By following the steps outlined in this blog post, you can effectively monitor
and track events from your Kubernetes cluster using Grafana Loki and Kubernetes
Event exporter. This setup provides valuable insights and helps in
troubleshooting and analyzing events in your cluster.</p>
<p>If you have any questions or feedback, please feel free to reach out. Happy
monitoring!</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Setting up Prometheus and Grafana on Kubernetes using Helm]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/prometheus-and-grafana-integration"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/setting_prometheus_grafana_on_kubernetes_using_helm.jpg"/>
      <id>https://www.bigbinary.com/blog/prometheus-and-grafana-integration</id>
      <published>2024-01-25T00:00:00.000Z</published>
      <updated>2024-01-25T00:00:00.000Z</updated>
      <author>
        <name>Vishal Yadav</name>
        <uri>https://www.bigbinary.com/blog/authors/vishal76342</uri>
      </author>
      <category term="NeetoCI"/>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/setting_prometheus_grafana_on_kubernetes_using_helm.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[In this blog, we will learn how to set up Prometheus and Grafana on Kubernetes using Helm. Prometheus along with Grafana is a highly scalable open-source monitoring framework for container...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/prometheus-and-grafana-integration"><![CDATA[<p>In this blog, we will learn how to set up Prometheus and Grafana on Kubernetes
using Helm.</p>
<p><a href="https://prometheus.io/">Prometheus</a> along with
<a href="https://grafana.com/">Grafana</a> is a highly scalable open-source monitoring
framework for
<a href="https://devopscube.com/docker-container-clustering-tools/">container orchestration platform</a>.
Prometheus probes the application and collects various data. It stores all this
data in its time series database. Grafana is a visualization tool. It uses the
data from the database to show the data that is meaningful to the user.</p>
<p>Both Prometheus and Grafana are gaining popularity in
the <a href="https://devopscube.com/what-is-observability/">observability</a> space as it
helps with metrics and alerts. Learning to integrate them using Helm will allow
us to monitor our Kubernetes cluster and troubleshoot problems easily.
Furthermore, we can deep dive into our cluster's well-being and efficiency,
focusing on resource usage and performance metrics within our Kubernetes
environment.</p>
<p>We will also learn how to create a simple
<a href="https://grafana.com/grafana/dashboards/">dashboard</a> on Grafana.</p>
<h2><strong>Why using Prometheus and Grafana for monitoring is good</strong></h2>
<p>Using Prometheus and Grafana for monitoring has many benefits:</p>
<ul>
<li><strong>Scalability:</strong> Both tools are highly scalable and can handle the monitoring
needs of small to large Kubernetes clusters.</li>
<li><strong>Flexibility:</strong> They allow us to create custom dashboards tailored to our
specific monitoring requirements.</li>
<li><strong>Real-time Monitoring:</strong> Prometheus provides real-time monitoring, helping us
to quickly detect and respond to issues.</li>
<li><strong>Alerting:</strong> Prometheus enables us to set up alerts based on specific
metrics, so we can be notified when issues arise.</li>
<li><strong>Data Visualization:</strong> Grafana offers powerful data visualization
capabilities, making it easier to understand complex data.</li>
<li><strong>Open Source:</strong> Both Prometheus and Grafana are open-source, reducing
monitoring costs.</li>
<li><strong>Community Support:</strong> We can benefit from active communities, ensuring
continuous development and support.</li>
<li><strong>Integration:</strong> They seamlessly integrate with other Kubernetes components
and applications, simplifying setup.</li>
<li><strong>Historical Data:</strong> Grafana allows us to explore historical data, aiding in
long-term analysis and trend identification.</li>
<li><strong>Extensible:</strong> Both tools are extensible, allowing us to integrate additional
data sources and plugins.</li>
<li><strong>Efficient Resource Usage:</strong> Prometheus efficiently utilizes resources,
ensuring minimal impact on our cluster's performance.</li>
</ul>
<p>Two common ways to use Prometheus and Grafana on Kubernetes:</p>
<ol>
<li><strong>Manual Kubernetes deployment</strong>: In this method, we need to write 
<a href="https://kubernetes.io/docs/concepts/workloads/controllers/deployment/">Kubernetes Deployments</a> 
and 
<a href="https://kubernetes.io/docs/concepts/services-networking/service/">Services</a>
for both Prometheus and Grafana. In the YAML file, we need to put all the
settings for Prometheus and Grafana on Kubernetes. Then we send these files
to our Kubernetes cluster. But we can end up with many YAML files, which can
be hard. If we make a mistake in any YAML file, Prometheus and Grafana won't
work on Kubernetes.</li>
<li><strong>Using Helm</strong>: This is an easy way to send any application container to
Kubernetes. <a href="https://helm.sh/">Helm</a> is the official package manager for
Kubernetes. With Helm, we can make installing, sending, and managing
Kubernetes makes applications easier.</li>
</ol>
<p>A <a href="https://helm.sh/">Helm Chart</a> has all the YAML files:</p>
<ul>
<li>Deployments.</li>
<li>Services.</li>
<li>Secrets.</li>
<li>ConfigMaps manifests.</li>
</ul>
<p>We use these files to send the application container to Kubernetes. Instead of
making individual YAML files for each application container, Helm lets us
download Helm charts that already have YAML files.</p>
<h2>Setting up Prometheus and Grafana using Helm chart</h2>
<p>We will use <a href="https://artifacthub.io/">ArtifactHub</a>, which offers public and
private repositories for Helm Charts. We will use these Helm Charts to arrange
the pods and services in our Kubernetes cluster.</p>
<p>To get Prometheus and Grafana working on Kubernetes with Helm, we will start by
installing Helm.</p>
<h4>Installing Helm on Linux</h4>
<pre><code class="language-bash">sudo apt-get install helm
</code></pre>
<h4>Installing Helm on Windows</h4>
<pre><code class="language-bash">choco install Kubernetes-helm
</code></pre>
<h4>Installing Helm on macOS</h4>
<pre><code class="language-bash">brew install helm
</code></pre>
<p>We can check out the official 
<a href="https://helm.sh/docs/intro/install/">Helm documentation</a>  if we run into any
issues while installing Helm.</p>
<p>The image below represents the successful Helm installation on macOS.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-01_at_1.09.49_PM.png" alt="Terminal output confirming a successful Helm installation on macOS"></p>
<p>For this blog, we’re going to install Helm
<a href="https://artifacthub.io/packages/helm/prometheus-community/kube-prometheus-stack">chart</a>
and by default, this chart also installs additional, dependent charts (including
Grafana):</p>
<ul>
<li><a href="https://github.com/prometheus-community/helm-charts/tree/main/charts/kube-state-metrics">prometheus-community/kube-state-metrics</a></li>
<li><a href="https://github.com/prometheus-community/helm-charts/tree/main/charts/prometheus-node-exporter">prometheus-community/prometheus-node-exporter</a></li>
<li><a href="https://github.com/grafana/helm-charts/tree/main/charts/grafana">grafana/grafana</a></li>
</ul>
<p>To get this Helm chart, let's run this command:</p>
<pre><code class="language-bash">helm repo add prometheus-community https://prometheus-community.github.io/helm-charts
helm repo update
</code></pre>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-01_at_1.15.43_PM.png" alt="Terminal output from helm repo add and helm repo update"></p>
<p>We have downloaded the latest version of Prometheus &amp; Grafana.</p>
<p>To install the Prometheus Helm Chart on a Kubernetes Cluster, let's run the
following command:</p>
<pre><code class="language-bash">helm install my-kube-prometheus-stack prometheus-community/kube-prometheus-stack
</code></pre>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-01_at_1.21.46_PM.png" alt="Terminal output from installing the kube-prometheus-stack Helm chart"></p>
<p>We have successfully installed Prometheus &amp; Grafana on the Kubernetes Cluster.
We can access the Prometheus &amp; Grafana servers via ports 9090 &amp; 80,
respectively.</p>
<p>Now, let's run the following command to view all the resources created by the
Helm Chart in our Kubernetes cluster:</p>
<pre><code class="language-bash">kubectl get all
</code></pre>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_11.19.39_AM.png" alt="Output of kubectl get all, listing the pods, services and deployments the chart created">
The Helm chart created the following resources:</p>
<ul>
<li><strong>Pods</strong>: It hosts the deployed Prometheus Kubernetes application inside the
cluster.</li>
<li><strong>Replica Sets</strong>: A collection of instances of the same application inside the
Kubernetes cluster. It enhances application reliability.</li>
<li><strong>Deployments</strong>: It is the blueprint for creating the application pods.</li>
<li><strong>Services</strong>: It exposes the pods running inside the Kubernetes cluster. We
use it to access the deployed Kubernetes application.</li>
<li><strong>Stateful Sets</strong>: They manage the deployment of the stateful application
components and ensure stable and predictable network identities for these
components.</li>
<li><strong>Daemon Sets</strong>: They ensure that all (or a specific set of) nodes run a copy
of a pod, which is useful for tasks such as logging, monitoring, and other
node-specific operations.</li>
</ul>
<p>Run this command to view all the Kubernetes Services for Prometheus &amp; Grafana:</p>
<pre><code class="language-bash">kubectl get service
</code></pre>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_11.37.39_AM.png" alt="Output of kubectl get service, listing the ClusterIP services the chart created"></p>
<p>Listed services for Prometheus and Grafana are:</p>
<ul>
<li>alertmanager-operated</li>
<li>kube-prometheus-stack-alertmanager</li>
<li>kube-prometheus-stack-grafana</li>
<li>kube-prometheus-stack-kube-state-metrics</li>
<li>kube-prometheus-stack-operator</li>
<li>kube-prometheus-stack-prometheus</li>
<li>kube-prometheus-stack-prometheus-node-exporter</li>
<li>prometheus-operated</li>
</ul>
<p><code>kube-prometheus-stack-grafana</code> and <code>kube-prometheus-stack-prometheus</code> are the
<code>ClusterIP</code> type services, which means we can only access them within the
Kubernetes cluster.</p>
<p>To expose the Prometheus and Grafana to be accessed outside the Kubernetes
cluster , we can either use the NodeIP or LoadBalance service.</p>
<h2>Exposing Prometheus and Grafana using NodePort services</h2>
<p>Let's run the following command to expose the <code>Prometheus</code> Kubernetes service:</p>
<pre><code class="language-bash">kubectl expose service kube-prometheus-stack-prometheus --type=NodePort --target-port=9090 --name=prometheus-node-port-service

kubectl expose service kube-prometheus-stack-grafana --type=NodePort --target-port=3000 --name=grafana-node-port-service
</code></pre>
<p>That command will create new services of <code>NodePort</code> type &amp; make the Prometheus
and Grafana is accessible outside the Kubernetes Cluster on ports <code>9090</code> and
<code>80</code>.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_11.59.15_AM.png" alt="The Prometheus and Grafana services changed to NodePort type, exposing ports 9090 and 80"></p>
<p>As we can see, the <code>grafana-node-port-service</code> and
<code>prometheus-node-port-service</code> are successfully created and are being exposed on
node ports <code>32489</code> &amp; <code>30905</code></p>
<p>Now, we can run this command and get the external IP of any node to access the
Prometheus and Grafana:</p>
<pre><code class="language-jsx">kubectl get nodes -o wide
</code></pre>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_11.57.17_AM.png" alt="Output of kubectl get nodes -o wide, showing the internal IP of each node"></p>
<p>We can use the External-IP and the node ports to access the Prometheus and
Grafana dashboards outside the cluster environment.</p>
<p>Prometheus Dashboard</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.04.36_PM.png" alt="Prometheus Dashboard"></p>
<p>Grafana Dashboard</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.04.53_PM.png" alt="Grafana Dashboard"></p>
<p>Run this command, to get the password for the <strong>admin</strong> user of the Grafana
dashboard:</p>
<pre><code>kubectl get secret --namespace default kube-prometheus-stack-grafana -o jsonpath=&quot;{.data.admin-password}&quot; | base64 --decode ; echo
</code></pre>
<h2>Grafana Dashboard</h2>
<p>Upon login to the Grafana dashboard, use <code>admin</code> as the username and our
generated password. We will see &quot;Welcome to Grafana&quot; homepage as shown below.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.12.04_PM.png" alt="The Welcome to Grafana home page after logging in as admin"></p>
<p>Since we used the Kube Prometheus Stack helm chart, the data source for
Prometheus and Alert Manager is added by default.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.18.14_PM.png" alt="The Grafana data sources page, with Prometheus and Alertmanager already added by the Helm chart"></p>
<p>We can add more data sources by clicking on the <strong>Add new data source</strong> button
on the top right side.</p>
<p>By default, this Helm chart adds multiple dashboards to monitor the health of
the Kubernetes cluster and its resources.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.22.37_PM.png" alt="The Grafana dashboards list, showing the Kubernetes dashboards bundled with the Helm chart"></p>
<p>Additionally, we also have the option of creating our dashboards from scratch as
well as importing multiple Grafana dashboards provided by the
<a href="https://grafana.com/grafana/dashboards/">Grafana library</a>.</p>
<p>To import a Grafana Dashboard, let's follow these steps:</p>
<ul>
<li>
<p>From this <a href="https://grafana.com/grafana/dashboards/">Grafana library</a>, we can
add any dashboard</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.28.44_PM.webp" alt="The Grafana dashboard library at grafana.com, used to pick a dashboard to import"></p>
</li>
<li>
<p>Select Dashboard and copy the Dashboard ID</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.34.54_PM.webp" alt="A dashboard page in the Grafana library, showing the dashboard ID to copy"></p>
</li>
<li>
<p>Under <strong>Dashboards</strong> page we can get the <strong>Import</strong> option</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.32.55_PM.png" alt="The Import option on the Grafana Dashboards page"></p>
</li>
<li>
<p>Under &quot;Import Dashboard&quot; page, we need to paste the Dashboard IP that we
copied earlier &amp; click on the <strong>Load</strong> button.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.35.39_PM.png" alt="The Import Dashboard page with the copied dashboard ID pasted in, ready to load"></p>
</li>
<li>
<p>After clicking on the <strong>Load</strong> button, it will auto-load the dashboard from
the library after which we can import the dashboard by clicking on the
<strong>Import</strong> button.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.37.50_PM.png" alt="The loaded dashboard details with the Import button ready to confirm"></p>
</li>
<li>
<p>Once the import is complete, we’ll be redirected to the new imported dashboard
which’ll also be visible under the Dashboards page.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/prometheus-and-grafana-integration/Screenshot_2023-11-02_at_12.39.42_PM.png" alt="The newly imported dashboard rendering its panels in Grafana"></p>
<p>We can use this Node Exporter dashboard to monitor &amp; observe the health of our
nodes present in our Kubernetes Cluster.</p>
</li>
</ul>
<h2>Conclusion</h2>
<p>In this blog, we learned how to integrate Prometheus and Grafana using the helm
chart. We also learned how to import dashboards into Grafana from the
<a href="https://grafana.com/grafana/dashboards/">Grafana library</a>.</p>
<p>In the next blog, we will explore how to integrate
<a href="https://grafana.com/oss/loki/">Grafana Loki</a> with Grafana and collect and store
event-related metrics using the
<a href="https://github.com/resmoio/kubernetes-event-exporter">Kubernetes Event Exporter</a>.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Adding sleep when idle to NeetoDeploy to cut costs]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/how_we_added_sleep_when_idle_feature_to_neetoDeploy_and_reduced_cost.jpg"/>
      <id>https://www.bigbinary.com/blog/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps</id>
      <published>2024-01-19T00:00:00.000Z</published>
      <updated>2024-01-19T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="NeetoDeploy"/>
      <category term="Kubernetes"/>
      <category term="DevOps"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/how_we_added_sleep_when_idle_feature_to_neetoDeploy_and_reduced_cost.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[How we added sleep when idle feature to NeetoDeploy and reduced cost]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps"><![CDATA[<p><em>We are building <a href="https://neeto.com/neetoDeploy">NeetoDeploy</a>, a compelling
Heroku alternative. Stay updated by following NeetoDeploy on
<a href="https://twitter.com/neetodeploy">Twitter</a> and reading our
<a href="https://www.bigbinary.com/blog/categories/neetodeploy">blog</a>.</em></p>
<h2>What is sleep when idle feature</h2>
<p>&quot;Sleep when idle&quot; is a feature of NeetoDeploy, which puts the deployed
application to sleep when there is no hit to the server for 5 minutes. This
helps reduce the cost of the server.</p>
<p>&quot;Sleep when idle&quot; feature can be enabled not only for the pull request review
applications, but for staging and production applications too. Many folks build
applications to learn and for hobby. In such cases, there is no point in running
the server when the server is not likely to get any traffic. Since NeetoDeploy
billing is based on the usage &quot;Sleep when idle&quot; feature helps keep the bill low
for the users.</p>
<p>Let's say you build something and you deployed to production. You shared it with
your friends. For a day or two you got a bit of traffic, and after that you
moved on to other things. If &quot;sleep when idle&quot; is enabled then you don't need to
worry about anything. If the server is not getting any traffic then you will not
be billed.</p>
<h2>How is Neeto using sleep when idle feature</h2>
<p>At <a href="https://neeto.com">neeto</a>, we are building 20+ applications at the same
time. It means lots of pull requests for all these products and thus lots of PR
review apps are created.</p>
<p>For a long time, we were using Heroku to build the review apps. However when
NeetoDeploy started to become stable, we movedto generating PR review apps from
Heroku to NeetoDeploy. This helped reduce cost.</p>
<h2>How to make deployments sleep when idle?</h2>
<p>This video describes how &quot;sleep when idle&quot; feature is implemented.</p>
<p><a href="https://www.youtube.com/watch?v=trn2DJyTjnw"><img src="https://img.youtube.com/vi/trn2DJyTjnw/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=trn2DJyTjnw">Watch on YouTube</a></p>
<p>Keeping the apps running only when they're being used involves two steps:</p>
<ol>
<li>Scaling the deployments down and bringing them back up again</li>
<li>Figuring out when to do the scaling</li>
</ol>
<p>The deployments can be scaled easily using the <code>kubectl scale</code> command. For
example, if we want to turn our deployment off, we can run the following to
update our deployment to zero replicas, essentially destroying all the pods.</p>
<pre><code class="language-bash">kubectl scale deployment/nginx --replicas=0
</code></pre>
<p>We can also delete our service, ingress or any other resource we might have
created for our deployment. The configuration of the deployment itself would
still be present in the cluster even when we make it sleep, since the Kubernetes
Deployment is not deleted.</p>
<p>When we want to bring our app back up again, we can use the same command to spin
up new pods:</p>
<pre><code class="language-bash">kubectl scale deployment/nginx --replicas=1
</code></pre>
<p>The challenge was to figure out <em>when</em> to do this. We decided that we'd have a
threshold based on the time the app is last accessed by users. If the
application is not accessed for more than five minutes, we consider the
application to be idle and we will scale it down. It'll be brought back up when
a user tries to access it again.</p>
<h2>Exploring existing solutions</h2>
<p>There are existing CNCF projects like <a href="https://knative.dev/">Knative</a> and
<a href="https://keda.sh/">Keda</a>, which can potentially be used to achieve what we want
here. We spent some time exploring these but realized that these solutions
weren't exactly suitable for our requirements. Kubernetes also natively has a
<code>HPAScaleToZero</code>
<a href="https://kubernetes.io/docs/reference/command-line-tools-reference/feature-gates">feature gate</a>
which enables the
<a href="https://www.bigbinary.com/blog/solving-scalability-in-neeto-deploy#understanding-kubernetes-autoscalers">Horizontal Pod Autoscaler</a>
to scale down deployments to zero pods, but this is still in alpha and, hence is
not available in EKS yet.</p>
<p>Ultimately, we decided to write our own service for achieving this. The entire
backend of NeetoDeploy was designed as
<a href="https://www.bigbinary.com/blog/neeto-deploy-zero-to-one">a collection of microservices</a>
from day one. So it made sense to build our <em>pod idling service</em> as another
microservice that runs in our cluster.</p>
<h2>Figuring out when to make applications sleep</h2>
<p>To know when applications can be idled, we need to know when people are
accessing the applications from their browsers. Since all the requests to
applications deployed on NeetoDeploy would go through our load balancer, it
would contain the information of when every app was last accessed.</p>
<p>We use <a href="https://traefik.io/traefik/">Traefik</a> as our load balancer and we used
Traefik's <a href="https://doc.traefik.io/traefik/middlewares/overview/">middlewares</a> to
retrieve and process the information of when apps are being accessed. We wrote a
custom middleware to send all the request information to the pod idling service,
whenever an app is being accessed. The pod idling service would store all the
URLs, along with the timestamp at which they were accessed, in a Redis cache.
The following graphic shows how the request information would be collected and
stored by the pod idling service into its Redis cache, both of which are running
within the cluster.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/pod-idling-new-architecture.png" alt="The architecture of the pod idling service"></p>
<p>The pod idling service would then filter the apps that were last accessed more
than five minutes ago. It then sends a request to the cluster to scale all these
apps down. We'd also delete any related resources like the Services and the
IngressRoutes used to configure networking for the deployments.</p>
<p>We first tested this by running the service manually, and sure enough, all the
inactive deployments are filtered and scaled properly. We then added this as a
cron job in the pod idling service, which would run every five minutes. This
means that no app would run for more than five minutes if they're not being
used.</p>
<p>But wait! How would we bring the app back up after scaling it down?</p>
<h2>Building the downtime service</h2>
<p>As we discussed above, we use Traefik's IngressRoutes to route traffic to the
application being accessed. We made use of the
<a href="https://doc.traefik.io/traefik/v2.10/routing/routers/#priority_1">priority parameter</a>
of IngressRoutes to boot up apps that are sleeping. Essentially, we created a
wildcard Traefik IngressRoute that points to a &quot;downtime service&quot; deployment,
which is a React app that serves a message of <code>There's nothing here, yet</code> to let
users know that the app they're trying to access doesn't exist. You can see this
in action if you visit a random URL in NeetoDeploy, say something like
<a href="https://nonexistent-appname.neetodeployapp.com">nonexistent-appname.neetodeployapp.com</a></p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/downtime-service-page.png" alt="The downtime service page"></p>
<p>Wildcard IngressRoutes have the least priority by default. So if we create a
&quot;catch-all&quot; wildcard IngressRoute, any invalid url without an IngressRoute of
its own, can be redirected to a single Service in Kubernetes. This is how we're
redirecting non-existent apps to the page shown above. In the following graphic,
we can see how a request to a random URL is routed to the downtime service with
the wildcard IngressRoute.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/downtime-service-architecture.png" alt="Architecture of how the downtime service works in NeetoDeploy"></p>
<p>This also means that if an app is scaled down by the pod idling service and gets
its IngressRoute deleted, the next time a user tries to access the app, the
request would instead be routed to the downtime service. We need to handle the
scale up logic from the downtime service.</p>
<p>Whenever a user requests a URL that doesn't have an IngressRoute, there are two
possibilities.</p>
<ol>
<li>The app doesn't exist.</li>
<li>The app exists, but is currently scaled down.</li>
</ol>
<p>The downtime service would first check the cluster if the requested app is
present in the cluster in a sleeping state. If not then the user will be served
the &quot;There's nothing here, yet&quot; page. If there is a sleeping deployment,
however, we boot it back up. The downtime service sends the scale up request to
the cluster. We keep redirecting the user back to the url till the app is up and
running. This redirection would keep happening until the app is scaled up since
we create the Service and IngressRoute only after the pods of the app are
running. At this point, the request will be routed to the correct pod by the
app's IngressRoute, since it has a higher priority than the wildcard
IngressRoute of the downtime service. All of these steps are illustrated in the
GIF below:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/downtime-service.gif" alt="Illustration of how the downtime service works"></p>
<p>This design worked flawlessly and we were able to bring back scaled down
applications with as low as 20-30 seconds of wait time.</p>
<h2>Conclusion</h2>
<p>We've been running this setup for almost a year now, and it has been working
smoothly so far. Pod idling service and the downtime service started as simpler
microservices and continue to evolve, adapting to the increasing demand as we
grow.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
invite@neeto.com.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">X</a>. You can also join our
<a href="https://launchpass.com/neetohq">community Slack</a> to chat with us about any
Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Building the NeetoDeploy metrics dashboard with Prometheus]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/using-prometheus-in-neeto-deploy"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/building_metrics_dashboard_in_neetoDeploy.jpg"/>
      <id>https://www.bigbinary.com/blog/using-prometheus-in-neeto-deploy</id>
      <published>2024-01-09T00:00:00.000Z</published>
      <updated>2024-01-09T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="NeetoDeploy"/>
      <category term="Kubernetes"/>
      <category term="DevOps"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/building_metrics_dashboard_in_neetoDeploy.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Building the metrics dashboard in NeetoDeploy with Prometheus]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/using-prometheus-in-neeto-deploy"><![CDATA[<p><em>We are building <a href="https://neeto.com/neetoDeploy">NeetoDeploy</a>, a compelling
alternative to Heroku. Stay updated by following NeetoDeploy on
<a href="https://twitter.com/neetodeploy">Twitter</a> and reading our
<a href="https://www.bigbinary.com/blog/categories/neetodeploy">blog</a>.</em></p>
<p>One of the features that we wanted in our cloud deployment platform,
<strong>NeetoDeploy</strong> was an application metrics. We decided to use
<a href="https://prometheus.io/">Prometheus</a> for building this feature. Prometheus is an
open source monitoring and alerting toolkit and is a CNCF graduated project.
Venturing into the Cloud Native ecosystem of projects apart from Kubernetes was
something we had never done before. We ended up learning a lot about Prometheus
and how to use it during the course of building this feature.</p>
<h2>Initial setup</h2>
<p>We installed Prometheus in our Kubernetes cluster by writing a deployment
configuration YAML and applying it to our cluster. We also provisioned an AWS
Elastic Block Store volume using a PersistentVolumeClaim to store the metrics
data collected by Prometheus. Prometheus needed a
<a href="https://github.com/prometheus/prometheus/blob/main/documentation/examples/prometheus-kubernetes.yml">configuration file</a>
where we defined what all targets it will be scraping metrics from. This is a
YAML file which we stored in a ConfigMap in our cluster.</p>
<p>Targets in Prometheus can be anything that exposes metrics data in the
Prometheus format at a <code>/metrics</code> endpoint. This can be your application
servers, Kubernetes API servers or even Prometheus itself. Prometheus would
scrape the data at the defined <code>scrape_interval</code> and store it in the volume as
time series data. This can be queried and visualized in the Prometheus dashboard
that comes bundled in the Prometheus deployment.</p>
<p>We used <code>kubectl port-forward</code> command to test that Prometheus is working
locally. Once everything was tested and we confirmed, we exposed Prometheus with
an ingress so that we can hit its APIs with that url.</p>
<p>Initially we had configured the following targets:</p>
<ol>
<li><a href="https://github.com/prometheus/node_exporter">node_exporter</a> from Prometheus,
which would scrape the metrics of the machine the deployment is running on.</li>
<li><a href="https://github.com/kubernetes/kube-state-metrics">kube-state-metrics</a> which
would listen to the Kubernetes API and store metrics of all the objects.</li>
<li><a href="https://traefik.io/traefik/">Traefik</a> for all the network-related metrics
(like the number of requests etc.) since we are using Traefik as our ingress
controller.</li>
<li>kubernetes-nodes</li>
<li>kubernetes-pods</li>
<li>kubernetes-cadvisor</li>
<li>kubernetes-service-endpoints</li>
</ol>
<p>The last 4 scrape jobs would be collecting metrics from the Kubernetes REST API
related to nodes, pods, containers and services respectively.</p>
<p>For scraping metrics from all of these targets, we had set a resource request of
500 MB of RAM and 0.5 vCPU to our Prometheus deployment.</p>
<p>After setting up all of this, the Prometheus deployment was running fine, and we
were able to see the data from the Prometheus dashboard. Seeing this, we were
satisfied and happily started hacking with PromQL, Prometheus's query language.</p>
<h2>The CrashLoopBackOff crime scene</h2>
<p><code>CrashLoopBackOff</code> is when a Kubernetes pod is going into a loop of crashing,
restarting itself and then crashing again - and this was what was happening to
the Prometheus deployment we had created. From what we could see, the pod had
crashed, and when it gets recreated, Prometheus would initialize itself and do a
reload of the
<a href="https://prometheus.io/docs/prometheus/latest/storage/">Write Ahead Log (WAL)</a>.</p>
<p>The WAL is there for adding additional durability to the database. Prometheus
stores the metrics it scrapes in-memory before persisting them to the database
as chunks, and the WAL makes sure that the in-memory data will not be lost in
the case of a crash. In our case, the Prometheus deployment was crashing and it
would get recreated. It would try to load the data from WAL into memory, and
then crash again before this was completed, leading to the CrashLoopBackOff
state.</p>
<p>We tried deleting the WAL blocks manually from the volume, even though this
would incur some data loss. This was able to bring the deployment back up again
since WAL replay needn't be done. The deployment went into CrashLoopBackOff
again after a while.</p>
<h2>Investigating the error</h2>
<p>The first line of approach we took was to monitor the CPU, memory, and disk
usage of the deployment. The disk usage seemed to be normal. We had provisioned
a 100GB volume and it wasn't anywhere near getting used up. The CPU usage also
seemed normal. The memory usage, however, was suspicious.</p>
<p>After the pods had crashed initially, we recreated the deployment and monitored
it using kubectl's <code>--watch</code> flag for following all the pod updates. While doing
this we were able to see that the pods were going into CrashLoopBackOff because
they were getting OOMKilled first. The <code>OOMKilled</code> error in Kubernetes is when a
pod is terminated because it tries to use more memory than it is allotted in its
resource limits. We were consistently seeing the <code>OOMKilled</code> error so memory
must be the culprit here.</p>
<p>We added Prometheus itself as a target in Prometheus so that we could monitor
the memory usage of the Prometheus deployment. The following was the general
trend of how Prometheus's memory was increasing over time. This would go on
until the memory would cross the specified limit, and then the pod would go into
CrashLoopBackOff.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/memory_usage.png" alt="Memory usage of the Prometheus deployment"></p>
<p>Now that we knew that memory was the issue, we started looking into what was
causing the memory leak. After talking with some folks from the Kubernetes Slack
workspace, we were asked to look at the TSDB status of the Prometheus
deployment. We monitored the stats in real time and saw that the number of time
series data stored in the database was growing in tens of thousands by each
second! This lined up with the increase in the memory usage graph from earlier.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/tsdb.png" alt="Prometheus TSDB stats"></p>
<h2>How we fixed it</h2>
<p>We can calculate the memory requirement for Prometheus based on the number of
targets we are scraping metrics from and the frequency at which we are scraping
the data. The memory requirement of the deployment is a function of both of
these parameters. In our case ,this was definitely higher than what we could
afford to allocate (based on the nodegroup's machine type) since we were
scraping a lot of data at a scrape interval of 15 seconds, which was set in the
default configuration for Prometheus.</p>
<p>We increased the scrape interval to 60 seconds and removed all the targets from
the Prometheus configuration whose metrics we didn't need for building the
dashboard. Within the targets that we were scraping from, we used the
<code>metric_relabel_configs</code> option to persist in the database only those metrics
which we needed and to drop everything else. We only needed the
<code>container_cpu_usage_seconds_total</code>, <code>container_memory_usage_bytes</code> and the
<code>traefik_service_requests_total</code> metrics - so we configured Prometheus so that
only these three would be stored in our database, and by extension the WAL.</p>
<p>We redeployed Prometheus after making these changes and the memory showed great
stability afterwards. The following is the memory usage of Prometheus over the
last few days. It has not exceeded 1GB.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/memory_usage_after_fix.png" alt="Memory usage of the Prometheus deployment after the fix"></p>
<h2>The aftermath</h2>
<p>Once Prometheus was stable we were able to build the metrics dashboard with the
Prometheus API in a straightforward manner. The metrics dashboard came to use
within a couple of days, when the staging deployment of
<a href="https://neetocode.com/">NeetoCode</a> had faced a downtime. You can see the
changes in the metrics from the time when the outage had occurred</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/neetocode_metrics.png" alt="NeetoCode metrics showing the downtime"></p>
<p>The quintessential learning that we got from this experience is to always be
wary of the resources that are being used up when it comes to tasks like
scraping metrics over an extended period of time. We were scraping all the
metrics initially in order to explore everything, even though all the metrics
were not being used. But because of this, we were able to read a lot about how
Prometheus works internally, and also learn some Prometheus best practices the
hard way.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">Twitter</a>. You can also join our
<a href="https://neetohq.slack.com/">community Slack</a> to chat with us about any Neeto
product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Use parametrized containers to deploy Rails microservices]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/deploying-rails-applications-with-parmaetrized-containers"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/deploying-rails-applications-with-parmaetrized-containers.png"/>
      <id>https://www.bigbinary.com/blog/deploying-rails-applications-with-parmaetrized-containers</id>
      <published>2018-09-26T00:00:00.000Z</published>
      <updated>2018-09-26T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <category term="Rails"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/deploying-rails-applications-with-parmaetrized-containers.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Using parametrized containers to deploy micro services in Rails applications]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/deploying-rails-applications-with-parmaetrized-containers"><![CDATA[<p>When using micro services with containers, one has to consider <strong>modularity</strong>
and <strong>reusability</strong> while designing a system.</p>
<p>While using Kubernetes as a distributed system for container deployments,
modularity and reusability can be achieved using parameterizing containers to
deploy micro services.</p>
<h2>Parameterized containers</h2>
<p>Assuming container as a function in a program, how many parameters does it have?
Each parameter represents an input that can customize a generic container to a
specific situation.</p>
<p>Let's assume we have a Rails application isolated in services like puma,
sidekiq/delayed-job and websocket. Each service runs as a separate deployment on
a separate container for the same application. When deploying the change we
should be building the same image for all the three containers but they should
be different function/processes. In our case, we will be running 3 pods with the
same image. This can be achieved by building a generic image for containers. The
Generic container must be accepting parameters to run different services.</p>
<p>We need to expose parameters and consume them inside the container. There are
two ways to pass parameters to our container.</p>
<ol>
<li>Using environment variables.</li>
<li>Using command line arguments.</li>
</ol>
<p>In this article, we will use environment variables to run parameterized
containers like puma, sidekiq/delayed-job and websocket for Rails applications
on kubernetes.</p>
<p>We will deploy <a href="https://github.com/bigbinary/wheel">wheel</a> on kubernetes using
parametrized container approach.</p>
<h4>Pre-requisite</h4>
<ul>
<li>
<p>Understanding of
<a href="https://docs.docker.com/engine/reference/builder/">Dockerfile</a> and image
building.</p>
</li>
<li>
<p>Access to working kubernetes cluster.</p>
</li>
<li>
<p>Understanding of <a href="http://kubernetes.io/">Kubernetes</a> terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>,
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>,
<a href="https://kubernetes.io/docs/concepts/services-networking/service/">services</a>,
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-pod-configmap/">configmap</a>,
and
<a href="https://kubernetes.io/docs/concepts/overview/working-with-objects/annotations/">annotations</a>.</p>
</li>
</ul>
<h3>Building a generic container image.</h3>
<p>Dockerfile (Link is not available) in wheel uses bash script
<code>setup_while_container_init.sh</code> as a command to start a container. The script is
self-explanatory and, as we can see, it consists of two functions <code>web</code> and
<code>background</code>. Function <code>web</code> starts the puma service and <code>background</code> starts the
delayed_job service.</p>
<p>We create two different deployments on kubernetes for web and background
services. Deployment templates are identical for both web and background. The
value of environment variable <code>POD_TYPE</code> to init-script runs the particular
service in a pod.</p>
<p>Once we have docker image built, let's deploy the application.</p>
<h3>Creating kubernetes deployment manifests for wheel application</h3>
<p>Wheel uses PostgreSQL database and we need postgres service to run the
application. We will use the postgres image from docker hub and will deploy it
as deployment.</p>
<p><strong>Note:</strong> For production deployments, database should be deployed as a
statefulset or use managed database services.</p>
<p>K8s manifest for deploying PostgreSQL.</p>
<pre><code class="language-yaml">---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  labels:
    app: db
  name: db
spec:
  replicas: 1
  template:
    metadata:
      labels:
        app: db
    spec:
      containers:
        - image: postgres:9.4
          name: db
          env:
            - name: POSTGRES_USER
              value: postgres
            - name: POSTGRES_PASSWORD
              value: welcome

---
apiVersion: v1
kind: Service
metadata:
  labels:
    app: db
  name: db
spec:
  ports:
    - name: headless
      port: 5432
      targetPort: 5432
  selector:
    app: db
</code></pre>
<p>Create Postgres DB and the service.</p>
<pre><code class="language-bash">$ kubectl create -f db-deployment.yml -f db-service.yml
deployment db created
service db created
</code></pre>
<p>Now that DB is available, we need to access it from the application using
<code>database.yml</code>.</p>
<p>We will create configmap to store database credentials and mount it on the
<code>config/database.yml</code> in our application deployments.</p>
<pre><code class="language-yaml">---
apiVersion: v1
kind: ConfigMap
metadata:
  name: database-config
data:
  database.yml: |
    development:
      adapter: postgresql
      database: wheel_development
      host: db
      username: postgres
      password: welcome
      pool: 5

    test:
      adapter: postgresql
      database: wheel_test
      host: db
      username: postgres
      password: welcome
      pool: 5

    staging:
      adapter: postgresql
      database: postgres
      host: db
      username: postgres
      password: welcome
      pool: 5
</code></pre>
<p>Create configmap for database.yml.</p>
<pre><code class="language-bash">$ kubectl create -f database-configmap.yml
configmap database-config created
</code></pre>
<p>We have the database ready for our application, now let's proceed to deploy our
Rails services.</p>
<h3>Deploying Rails micro-services using the same docker image</h3>
<p>In this blog, we will limit our services to web and background with kubernetes
deployment.</p>
<p>Let's create a deployment and service for our web application.</p>
<pre><code class="language-yaml">---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  name: wheel-web
  labels:
    app: wheel-web
spec:
  replicas: 1
  template:
    metadata:
      labels:
        app: wheel-web
    spec:
      containers:
      - image: bigbinary/wheel:generic
        name: web
        imagePullPolicy: Always
        env:
        - name: DEPLOY_TIME
          value: $date
          value: staging
        - name: POD_TYPE
          value: WEB
        ports:
        - containerPort: 80
        volumeMounts:
          - name: database-config
            mountPath: /wheel/config/database.yml
            subPath: database.yml
      volumes:
        - name: database-config
          configMap:
            name: database-config

---

apiVersion: v1
kind: Service
metadata:
  labels:
    app: wheel-web
  name: web
spec:
  ports:
  - name: puma
    port: 80
    targetPort: 80
  selector:
    app: wheel-web
  type: LoadBalancer
</code></pre>
<p>Note that we used <code>POD_TYPE</code> as <code>WEB</code>, which will start the puma process from
the container startup script.</p>
<p>Let's create a web/puma deployment and service.</p>
<pre><code class="language-bash">kubectl create -f web-deployment.yml -f web-service.yml
deployment wheel-web created
service web created
</code></pre>
<pre><code class="language-yaml">---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  name: wheel-background
  labels:
    app: wheel-background
spec:
  replicas: 1
  template:
    metadata:
      labels:
        app: wheel-background
    spec:
      containers:
        - image: bigbinary/wheel:generic
          name: background
          imagePullPolicy: Always
          env:
            - name: DEPLOY_TIME
              value: $date
            - name: POD_TYPE
              value: background
          ports:
            - containerPort: 80
          volumeMounts:
            - name: database-config
              mountPath: /wheel/config/database.yml
              subPath: database.yml
      volumes:
        - name: database-config
          configMap:
            name: database-config

---
apiVersion: v1
kind: Service
metadata:
  labels:
    app: wheel-background
  name: background
spec:
  ports:
    - name: background
      port: 80
      targetPort: 80
  selector:
    app: wheel-background
</code></pre>
<p>For background/delayed-job we set <code>POD_TYPE</code> as <code>background</code>. It will start
delayed-job process.</p>
<p>Let's create background deployment and the service.</p>
<pre><code class="language-bash">kubectl create -f background-deployment.yml -f background-service.yml
deployment wheel-background created
service background created
</code></pre>
<p>Get application endpoint.</p>
<pre><code class="language-bash">$ kubectl get svc web -o wide | awk '{print $4}'
a55714dd1a22d11e88d4b0a87a399dcf-2144329260.us-east-1.elb.amazonaws.com
</code></pre>
<p>We can access the application using the endpoint.</p>
<p>Now let's see pods.</p>
<pre><code class="language-bash">$ kubectl get pods
NAME                                READY     STATUS    RESTARTS   AGE
db-5f7d5c96f7-x9fll                 1/1       Running   0          1h
wheel-background-6c7cbb4c75-sd9sd   1/1       Running   0          30m
wheel-web-f5cbf47bd-7hzp8           1/1       Running   0          10m
</code></pre>
<p>We see that <code>db</code> pod is running postgres, <code>wheel-web</code> pod is running puma and
<code>wheel-background</code> pod is running delayed job.</p>
<p>If we check logs, everything coming to puma is handled by web pod. All the
background jobs are handled by background pod.</p>
<p>Similarly, if we are using websocket, separate API pods, traffic will be routed
to respective services.</p>
<p>This is how we can deploy Rails micro services using parametrized containers and
a generic image.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Kubernetes ingress controller for authenticating apps]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/using-kubernetes-ingress-authentication"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-kubernetes-ingress-authentication.png"/>
      <id>https://www.bigbinary.com/blog/using-kubernetes-ingress-authentication</id>
      <published>2018-08-14T00:00:00.000Z</published>
      <updated>2018-08-14T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-kubernetes-ingress-authentication.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Authenticate your application using kubernetes ingress]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/using-kubernetes-ingress-authentication"><![CDATA[<p><a href="https://kubernetes.io/docs/concepts/services-networking/ingress/">Kubernetes Ingress</a>
has redefined the routing in this era of containerization and with all these
freehand routing techniques the thought of &quot;My router my rules&quot; seems real.</p>
<p>We use nginx-ingress as a routing service for our applications. There is a lot
more than routing we can do with ingress. One of the important features is
setting up authentication using ingress for our application. As all the traffic
goes from ingress to our service, it makes sense to setup authentication on
ingress.</p>
<p>As mentioned in
<a href="https://github.com/kubernetes/ingress-nginx/tree/master/docs/examples/">ingress repository</a>
there are different types of techniques available for authentication including:</p>
<ul>
<li>Basic authentication</li>
<li>Client-certs authentication</li>
<li>External authentication</li>
<li>Oauth external authentication</li>
</ul>
<p>In this blog, we will set up authentication for the sample application using
basic ingress authentication technique.</p>
<h4>Pre-requisites</h4>
<ul>
<li>
<p>Access to working kubernetes cluster.</p>
</li>
<li>
<p>Understanding of <a href="http://kubernetes.io/">Kubernetes</a> terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>,
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>,
<a href="https://kubernetes.io/docs/concepts/services-networking/service/">services</a>,
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-pod-configmap/">configmap</a>,
<a href="https://kubernetes.io/docs/concepts/services-networking/ingress/">ingress</a>
and
<a href="https://kubernetes.io/docs/concepts/overview/working-with-objects/annotations/">annotations</a></p>
</li>
</ul>
<p>First, let's create ingress resources from upstream example by running the
following command.</p>
<pre><code class="language-bash">
$ kubectl create -f https://raw.githubusercontent.com/kubernetes/ingress-nginx/master/deploy/mandatory.yaml
namespace &quot;ingress-nginx&quot; created
deployment &quot;default-http-backend&quot; created
service &quot;default-http-backend&quot; created
configmap &quot;nginx-configuration&quot; created
configmap &quot;tcp-services&quot; created
configmap &quot;udp-services&quot; created
serviceaccount &quot;nginx-ingress-serviceaccount&quot; created
clusterrole &quot;nginx-ingress-clusterrole&quot; created
role &quot;nginx-ingress-role&quot; created
rolebinding &quot;nginx-ingress-role-nisa-binding&quot; created
clusterrolebinding &quot;nginx-ingress-clusterrole-nisa-binding&quot; created
deployment &quot;nginx-ingress-controller&quot; created

</code></pre>
<p>Now that ingress controller resources are created we need a service to access
the ingress.</p>
<p>Use following manifest to create service for ingress.</p>
<pre><code class="language-yaml">apiVersion: v1
kind: Service
metadata:
  annotations:
    service.beta.kubernetes.io/aws-load-balancer-backend-protocol: tcp
  labels:
    k8s-addon: ingress-nginx.addons.k8s.io
  name: ingress-nginx
  namespace: ingress-nginx
spec:
  externalTrafficPolicy: Cluster
  ports:
    - name: https
      port: 443
      protocol: TCP
      targetPort: http
    - name: http
      port: 80
      protocol: TCP
      targetPort: http
  selector:
    app: ingress-nginx
  type: LoadBalancer
</code></pre>
<p>Now, get the ELB endpoint and bind it with some domain name.</p>
<pre><code class="language-bash">
$kubectl create -f ingress-service.yml
service ingress-nginx created

$ kubectl -n ingress-nginx get svc  ingress-nginx -o wide
NAME            CLUSTER-IP      EXTERNAL-IP                                                               PORT(S)                      AGE       SELECTOR
ingress-nginx   100.71.250.56   abcghccf8540698e8bff782799ca8h04-1234567890.us-east-2.elb.amazonaws.com   80:30032/TCP,443:30108/TCP   10s       app=ingress-nginx

</code></pre>
<p>Let's create a deployment and service for our sample application kibana. We need
elasticsearch to run kibana.</p>
<p>Here is manifest for the sample application.</p>
<pre><code class="language-yaml">---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  labels:
    app: kibana
  name: kibana
  namespace: ingress-nginx
spec:
  replicas: 1
  template:
    metadata:
      labels:
        app: kibana
    spec:
      containers:
        - image: kibana:latest
          name: kibana
          ports:
            - containerPort: 5601
---
apiVersion: v1
kind: Service
metadata:
  annotations:
  labels:
    app: kibana
  name: kibana
  namespace: ingress-nginx

spec:
  ports:
    - name: kibana
      port: 5601
      targetPort: 5601
  selector:
    app: kibana
---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  labels:
    app: elasticsearch
  name: elasticsearch
  namespace: ingress-nginx
spec:
  replicas: 1
  strategy:
    type: RollingUpdate
  template:
    metadata:
      labels:
        app: elasticsearch
    spec:
      containers:
        - image: elasticsearch:latest
          name: elasticsearch
          ports:
            - containerPort: 5601
---
apiVersion: v1
kind: Service
metadata:
  annotations:
  labels:
    app: elasticsearch
  name: elasticsearch
  namespace: ingress-nginx
spec:
  ports:
    - name: elasticsearch
      port: 9200
      targetPort: 9200
  selector:
    app: elasticsearch
</code></pre>
<p>Create the sample application.</p>
<pre><code class="language-bash">
kubectl apply -f kibana.yml
deployment &quot;kibana&quot; created
service &quot;kibana&quot; created
deployment &quot;elasticsearch&quot; created
service &quot;elasticsearch&quot; created

</code></pre>
<p>Now that we have created application and ingress resources, it's time to create
an ingress and access the application.</p>
<p>Use the following manifest to create ingress.</p>
<pre><code class="language-yaml">apiVersion: extensions/v1beta1
kind: Ingress
metadata:
  annotations:
  name: kibana-ingress
  namespace: ingress-nginx
spec:
  rules:
    - host: logstest.myapp-staging.com
      http:
        paths:
          - path: /
            backend:
              serviceName: kibana
              servicePort: 5601
</code></pre>
<pre><code class="language-bash">
$kubectl -n ingress-nginx create -f ingress.yml
ingress &quot;kibana-ingress&quot; created.

</code></pre>
<p>Now that our application is up, when we access the kibana dashboard using URL
http://logstest.myapp-staging.com We directly have access to our Kibana
dashboard and anyone with this URL can access logs as shown in the following
image.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/using-kubernetes-ingress-authentication/kibana.png" alt="Kibana dashboard without authentication"></p>
<p>Now, let's set up a basic authentication using htpasswd.</p>
<p>Follow below commands to generate the secret for credentials.</p>
<p>Let's create an auth file with username and password.</p>
<pre><code class="language-bash">
$ htpasswd -c auth kibanaadmin
New password: &lt;kibanaadmin&gt;
New password:
Re-type new password:
Adding password for user kibanaadmin

</code></pre>
<p>Create k8s secret.</p>
<pre><code class="language-bash">
$ kubectl -n ingress-nginx create secret generic basic-auth --from-file=auth
secret &quot;basic-auth&quot; created

</code></pre>
<p>Verify the secret.</p>
<pre><code class="language-yaml">
kubectl get secret basic-auth -o yaml
apiVersion: v1
data:
  auth: Zm9vOiRhcHIxJE9GRzNYeWJwJGNrTDBGSERBa29YWUlsSDkuY3lzVDAK
kind: Secret
metadata:
  name: basic-auth
  namespace: ingress-nginx
type: Opaque

</code></pre>
<p>Use following annotations in our ingress manifest by updating the ingress
manifest.</p>
<pre><code class="language-bash">kubectl -n ingress-nginx edit ingress kibana ingress
</code></pre>
<p>Paste the following annotations</p>
<pre><code class="language-bash">nginx.ingress.kubernetes.io/auth-type: basic
nginx.ingress.kubernetes.io/auth-secret: basic-auth
nginx.ingress.kubernetes.io/auth-realm: &quot;Kibana Authentication Required - kibanaadmin&quot;

</code></pre>
<p>Now that ingress is updated, hit the URL again and as shown in the image below
we are asked for authentication.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/using-kubernetes-ingress-authentication/kibana_auth.png" alt="Kibana dashboard without authentication"></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Speed up Docker image build process of a Rails app]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/speeding-up-docker-image-build-process-of-a-rails-application"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/speeding-up-docker-image-build-process-of-a-rails-application.png"/>
      <id>https://www.bigbinary.com/blog/speeding-up-docker-image-build-process-of-a-rails-application</id>
      <published>2018-07-25T00:00:00.000Z</published>
      <updated>2018-07-25T00:00:00.000Z</updated>
      <author>
        <name>Vishal Telangre</name>
        <uri>https://www.bigbinary.com/blog/authors/vishaltelangre</uri>
      </author>
      <category term="Rails"/>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/speeding-up-docker-image-build-process-of-a-rails-application.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[By reusing bundler cache and cache of precompiled assets, we can speed up Docker image building process of a Rails application.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/speeding-up-docker-image-build-process-of-a-rails-application"><![CDATA[<p><strong>tl;dr : We reduced the Docker image building time from 10 minutes to 5 minutes
by reusing bundler cache and by precompiling assets.</strong></p>
<p>We deploy one of our Rails applications on a dedicated Kubernetes cluster.
Kubernetes is a good fit for us since as per the load and resource consumption,
Kubernetes horizontally scales the containerized application automatically. The
prerequisite to deploy any kind of application on Kubernetes is that the
application needs to be containerized. We use Docker to containerize our
application.</p>
<p>We have been successfully containerizing and deploying our Rails application on
Kubernetes for about a year now. Although containerization was working fine, we
were not happy with the overall time spent to containerize the application
whenever we changed the source code and deployed the app.</p>
<p>We use <a href="https://jenkins.io/">Jenkins</a> for building on-demand Docker images of
our application with the help of
<a href="https://wiki.jenkins-ci.org/display/JENKINS/CloudBees+Docker+Build+and+Publish+plugin">CloudBees Docker Build and Publish plugin</a>.</p>
<p>We observed that the average build time of a Jenkins job to build a Docker image
was about 9 to 10 minutes.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/speeding-up-docker-image-build-process-of-a-rails-application/build-time-trend-before-speedup-tweaks.png" alt="Screenshot of build time trend graph before speedup tweaks"></p>
<h2>Investigating what takes most time</h2>
<p>We wipe the workspace folder of the Jenkins job after finishing each Jenkins
build to avoid any unintentional behavior caused by the residue left from a
previous build. The application's folder is about 500 MiB in size. Each Jenkins
build spends about 20 seconds to perform a shallow Git clone of the latest
commit of the specified git branch from our remote GitHub repository.</p>
<p>After cloning the latest source code, Jenkins executes <code>docker build</code> command to
build a Docker image with a unique tag to containerize the cloned source code of
the application.</p>
<p>Jenkins build spends another 10 seconds invoking <code>docker build</code> command and
sending build context to Docker daemon.</p>
<pre><code class="language-bash">01:05:43 [docker-builder] $ docker build --build-arg RAILS_ENV=production -t bigbinary/xyz:production-role-management-feature-1529436929 --pull=true --file=./Dockerfile /var/lib/jenkins/workspace/docker-builder
01:05:53 Sending build context to Docker daemon 489.4 MB
</code></pre>
<p>We use the same Docker image on a number of Kubernetes pods. Therefore, we do
not want to execute <code>bundle install</code> and <code>rake assets:precompile</code> tasks while
starting a container in each pod which would prevent that pod from accepting any
requests until these tasks are finished.</p>
<p>The recommended approach is to run <code>bundle install</code> and <code>rake assets:precompile</code>
tasks while or before containerizing the Rails application.</p>
<p>Following is a trimmed down version of our actual Dockerfile which is used by
<code>docker build</code> command to containerize our application.</p>
<pre><code class="language-dockerfile">FROM bigbinary/xyz-base:latest

ENV APP_PATH /data/app/

WORKDIR $APP_PATH

ADD . $APP_PATH

ARG RAILS_ENV

RUN bin/bundle install --without development test

RUN bin/rake assets:precompile

CMD [&quot;bin/bundle&quot;, &quot;exec&quot;, &quot;puma&quot;]
</code></pre>
<p>The <code>RUN</code> instructions in the above Dockerfile executes <code>bundle install</code> and
<code>rake assets:precompile</code> tasks while building a Docker image. Therefore, when a
Kubernetes pod is created using such a Docker image, Kubernetes pulls the image,
starts a Docker container using that image inside the pod and runs <code>puma</code> server
immediately.</p>
<p>The base Docker image which we use in the <code>FROM</code> instruction contains necessary
system packages. We rarely need to update any system package. Therefore, an
intermediate layer which may have been built previously for that instruction is
reused while executing the <code>docker build</code> command. If the layer for <code>FROM</code>
instruction is reused, Docker reuses cached layers for the next two instructions
such as <code>ENV</code> and <code>WORKDIR</code> respectively since both of them are never changed.</p>
<pre><code class="language-bash">01:05:53 Step 1/8 : FROM bigbinary/xyz-base:latest
01:05:53 latest: Pulling from bigbinary/xyz-base
01:05:53 Digest: sha256:193951cad605d23e38a6016e07c5d4461b742eb2a89a69b614310ebc898796f0
01:05:53 Status: Image is up to date for bigbinary/xyz-base:latest
01:05:53  ---&gt; c2ab738db405
01:05:53 Step 2/8 : ENV APP_PATH /data/app/
01:05:53  ---&gt; Using cache
01:05:53  ---&gt; 5733bc978f19
01:05:53 Step 3/8 : WORKDIR $APP_PATH
01:05:53  ---&gt; Using cache
01:05:53  ---&gt; 0e5fbc868af8
</code></pre>
<p>Docker checks contents of the files in the image and calculates checksum for
each file for an <code>ADD</code> instruction. Since source code changes often, the
previously cached layer for the <code>ADD</code> instruction is invalidated due to the
mismatching checksums. Therefore, the 4th instruction <code>ADD</code> in our Dockerfile
has to add the local files in the provided build context to the filesystem of
the image being built in a separate intermediate container instead of reusing
the previously cached instruction layer. On an average, this instruction spends
about 25 seconds.</p>
<pre><code class="language-bash">01:05:53 Step 4/8 : ADD . $APP_PATH
01:06:12  ---&gt; cbb9a6ac297e
01:06:17 Removing intermediate container 99ca98218d99
</code></pre>
<p>We need to build Docker images for our application using different Rails
environments. To achieve that, we trigger a
<a href="https://wiki.jenkins.io/display/JENKINS/Parameterized+Build">parameterized Jenkins build</a>
by specifying the needed Rails environment parameter. This parameter is then
passed to the <code>docker build</code> command using <code>--build-arg RAILS_ENV=production</code>
option. The <code>ARG</code> instruction in the Dockerfile defines <code>RAILS_ENV</code> variable and
is implicitly used as an environment variable by the rest of the instructions
defined just after that <code>ARG</code> instruction. Even if the previous <code>ADD</code>
instruction didn't invalidate build cache; if the <code>ARG</code> variable is different
from a previous build, then a &quot;cache miss&quot; occurs and the build cache is
invalidated for the subsequent instructions.</p>
<pre><code class="language-bash">01:06:17 Step 5/8 : ARG RAILS_ENV
01:06:17  ---&gt; Running in b793b8cc2fe7
01:06:22  ---&gt; b8a70589e384
01:06:24 Removing intermediate container b793b8cc2fe7
</code></pre>
<p>The next two <code>RUN</code> instructions are used to install gems and precompile static
assets using sprockets. As earlier instruction(s) already invalidates the build
cache, these <code>RUN</code> instructions are mostly executed instead of reusing cached
layer. The <code>bundle install</code> command takes about 2.5 minutes and the
<code>rake assets:precompile</code> task takes about 4.35 minutes.</p>
<pre><code class="language-bash">01:06:24 Step 6/8 : RUN bin/bundle install --without development test
01:06:24  ---&gt; Running in a556c7ca842a
01:06:25 bin/bundle install --without development test
01:08:22  ---&gt; 82ab04f1ff42
01:08:40 Removing intermediate container a556c7ca842a
01:08:58 Step 7/8 : RUN bin/rake assets:precompile
01:08:58  ---&gt; Running in b345c73a22c
01:08:58 bin/bundle exec rake assets:precompile
01:09:07 ** Invoke assets:precompile (first_time)
01:09:07 ** Invoke assets:environment (first_time)
01:09:07 ** Execute assets:environment
01:09:07 ** Invoke environment (first_time)
01:09:07 ** Execute environment
01:09:12 ** Execute assets:precompile
01:13:20  ---&gt; 57bf04f3c111
01:13:23 Removing intermediate container b345c73a22c
</code></pre>
<p>Above both <code>RUN</code> instructions clearly looks like the main culprit which were
slowing down the whole <code>docker build</code> command and thus the Jenkins build.</p>
<p>The final instruction <code>CMD</code> which starts the <code>puma</code> server takes another 10
seconds. After building the Docker image, the <code>docker push</code> command spends
another minute.</p>
<pre><code class="language-bash">01:13:23 Step 8/8 : CMD [&quot;bin/bundle&quot;, &quot;exec&quot;, &quot;puma&quot;]
01:13:23  ---&gt; Running in 104967ad1553
01:13:31  ---&gt; 35d2259cdb1d
01:13:34 Removing intermediate container 104967ad1553
01:13:34 [0mSuccessfully built 35d2259cdb1d
01:13:35 [docker-builder] $ docker inspect 35d2259cdb1d
01:13:35 [docker-builder] $ docker push bigbinary/xyz:production-role-management-feature-1529436929
01:13:35 The push refers to a repository [docker.io/bigbinary/xyz]
01:14:21 d67854546d53: Pushed
01:14:22 production-role-management-feature-1529436929: digest: sha256:07f86cfd58fac412a38908d7a7b7d0773c6a2980092df416502d7a5c051910b3 size: 4106
01:14:22 Finished: SUCCESS
</code></pre>
<p>So, we found the exact commands which were causing the <code>docker build</code> command to
take so much time to build a Docker image.</p>
<p>Let's summarize the steps involved in building our Docker image and the average
time each needed to finish.</p>
<table>
<thead>
<tr>
<th>Command or Instruction</th>
<th>Average Time Spent</th>
</tr>
</thead>
<tbody>
<tr>
<td>Shallow clone of Git Repository by Jenkins</td>
<td>20 Seconds</td>
</tr>
<tr>
<td>Invocation of <code>docker build</code> by Jenkins and sending build context to Docker daemon</td>
<td>10 Seconds</td>
</tr>
<tr>
<td><code>FROM bigbinary/xyz-base:latest</code></td>
<td>0 Seconds</td>
</tr>
<tr>
<td><code>ENV APP_PATH /data/app/</code></td>
<td>0 Seconds</td>
</tr>
<tr>
<td><code>WORKDIR $APP_PATH</code></td>
<td>0 Seconds</td>
</tr>
<tr>
<td><code>ADD . $APP_PATH</code></td>
<td>25 Seconds</td>
</tr>
<tr>
<td><code>ARG RAILS_ENV</code></td>
<td>7 Seconds</td>
</tr>
<tr>
<td><code>RUN bin/bundle install --without development test</code></td>
<td>2.5 Minutes</td>
</tr>
<tr>
<td><code>RUN bin/rake assets:precompile</code></td>
<td>4.35 Minutes</td>
</tr>
<tr>
<td><code>CMD [&quot;bin/bundle&quot;, &quot;exec&quot;, &quot;puma&quot;]</code></td>
<td>1.15 Minutes</td>
</tr>
<tr>
<td><strong>Total</strong></td>
<td><strong>9 Minutes</strong></td>
</tr>
</tbody>
</table>
<p>Often, people build Docker images from a single Git branch, like <code>master</code>. Since
changes in a single branch are incremental and hardly has differences in the
<code>Gemfile.lock</code> file across commits, bundler cache need not be managed
explicitly. Instead, Docker automatically reuses the previously built layer for
the <code>RUN bundle install</code> instruction if the <code>Gemfile.lock</code> file remains
unchanged.</p>
<p>In our case, this does not happen. For every new feature or a bug fix, we create
a separate Git branch. To verify the changes on a particular branch, we deploy a
separate review app which serves the code from that branch. To achieve this
workflow, everyday we need to build a lot of Docker images containing source
code from varying Git branches as well as with varying environments. Most of the
times, the <code>Gemfile.lock</code> and assets have different versions across these Git
branches. Therefore, it is hard for Docker to cache layers for <code>bundle install</code>
and <code>rake assets:precompile</code> tasks and reuse those layers during every
<code>docker build</code> command run with different application source code and a
different environment. This is why the previously built Docker layer for the
<code>RUN bin/bundle install</code> instruction and the <code>RUN bin/rake assets:precompile</code>
instruction was often not being used in our case. This reason was causing the
<code>RUN</code> instructions to be executed without reusing the previously built Docker
layer cache while performing every other Docker build.</p>
<p>Before discussing the approaches to speed up our Docker build flow, let's
familiarize with the <code>bundle install</code> and <code>rake assets:precompile</code> tasks and how
to speed up them by reusing cache.</p>
<h2>Speeding up &quot;bundle install&quot; by using cache</h2>
<p>By default, Bundler installs gems at the location which is set by Rubygems.
Also, Bundler looks up for the installed gems at the same location.</p>
<p>This location can be explicitly changed by using <code>--path</code> option.</p>
<p>If <code>Gemfile.lock</code> does not exist or no gem is found at the explicitly provided
location or at the default gem path then <code>bundle install</code> command fetches all
remote sources, resolves dependencies if needed and installs required gems as
per <code>Gemfile</code>.</p>
<p>The <code>bundle install --path=vendor/cache</code> command would install the gems at the
<code>vendor/cache</code> location in the current directory. If the same command is run
without making any change in <code>Gemfile</code>, since the gems were already installed
and cached in <code>vendor/cache</code>, the command will finish instantly because Bundler
need not to fetch any new gems.</p>
<p>The tree structure of <code>vendor/cache</code> directory looks like this.</p>
<pre><code class="language-tree">vendor/cache
├── aasm-4.12.3.gem
├── actioncable-5.1.4.gem
├── activerecord-5.1.4.gem
├── [...]
├── ruby
│   └── 2.4.0
│       ├── bin
│       │   ├── aws.rb
│       │   ├── dotenv
│       │   ├── erubis
│       │   ├── [...]
│       ├── build_info
│       │   └── nokogiri-1.8.1.info
│       ├── bundler
│       │   └── gems
│       │       ├── activeadmin-043ba0c93408
│       │       [...]
│       ├── cache
│       │   ├── aasm-4.12.3.gem
│       │   ├── actioncable-5.1.4.gem
│       │   ├── [...]
│       │   ├── bundler
│       │   │   └── git
│       └── specifications
│           ├── aasm-4.12.3.gemspec
│           ├── actioncable-5.1.4.gemspec
│           ├── activerecord-5.1.4.gemspec
│           ├── [...]
│           [...]
[...]
</code></pre>
<p>It appears that Bundler keeps two separate copies of the <code>.gem</code> files at two
different locations, <code>vendor/cache</code> and <code>vendor/cache/ruby/VERSION_HERE/cache</code>.</p>
<p>Therefore, even if we remove a gem in the <code>Gemfile</code>, then that gem will be
removed only from the <code>vendor/cache</code> directory. The
<code>vendor/cache/ruby/VERSION_HERE/cache</code> will still have the cached <code>.gem</code> file
for that removed gem.</p>
<p>Let's see an example.</p>
<p>We have <code>'aws-sdk', '2.11.88'</code> gem in our Gemfile and that gem is installed.</p>
<pre><code class="language-bash">$ ls vendor/cache/aws-sdk-*
vendor/cache/aws-sdk-2.11.88.gem
vendor/cache/aws-sdk-core-2.11.88.gem
vendor/cache/aws-sdk-resources-2.11.88.gem

$ ls vendor/cache/ruby/2.4.0/cache/aws-sdk-*
vendor/cache/ruby/2.4.0/cache/aws-sdk-2.11.88.gem
vendor/cache/ruby/2.4.0/cache/aws-sdk-core-2.11.88.gem
vendor/cache/ruby/2.4.0/cache/aws-sdk-resources-2.11.88.gem
</code></pre>
<p>Now, we will remove the <code>aws-sdk</code> gem from Gemfile and run <code>bundle install</code>.</p>
<pre><code class="language-bash">$ bundle install --path=vendor/cache
Using rake 12.3.0
Using aasm 4.12.3
[...]
Updating files in vendor/cache
Removing outdated .gem files from vendor/cache
  * aws-sdk-2.11.88.gem
  * jmespath-1.3.1.gem
  * aws-sdk-resources-2.11.88.gem
  * aws-sdk-core-2.11.88.gem
  * aws-sigv4-1.0.2.gem
Bundled gems are installed into `./vendor/cache`

$ ls vendor/cache/aws-sdk-*
no matches found: vendor/cache/aws-sdk-*

$ ls vendor/cache/ruby/2.4.0/cache/aws-sdk-*
vendor/cache/ruby/2.4.0/cache/aws-sdk-2.11.88.gem
vendor/cache/ruby/2.4.0/cache/aws-sdk-core-2.11.88.gem
vendor/cache/ruby/2.4.0/cache/aws-sdk-resources-2.11.88.gem
</code></pre>
<p>We can see that the cached version of gem(s) remained unaffected.</p>
<p>If we add the same gem <code>'aws-sdk', '2.11.88'</code> back to the Gemfile and perform
<code>bundle install</code>, instead of fetching that gem from remote Gem repository,
Bundler will install that gem from the cache.</p>
<pre><code class="language-bash">$ bundle install --path=vendor/cache
Resolving dependencies........
[...]
Using aws-sdk 2.11.88
[...]
Updating files in vendor/cache
  * aws-sigv4-1.0.3.gem
  * jmespath-1.4.0.gem
  * aws-sdk-core-2.11.88.gem
  * aws-sdk-resources-2.11.88.gem
  * aws-sdk-2.11.88.gem

$ ls vendor/cache/aws-sdk-*
vendor/cache/aws-sdk-2.11.88.gem
vendor/cache/aws-sdk-core-2.11.88.gem
vendor/cache/aws-sdk-resources-2.11.88.gem
</code></pre>
<p>What we understand from this is that if we can reuse the explicitly provided
<code>vendor/cache</code> directory every time we need to execute <code>bundle install</code> command,
then the command will be much faster because Bundler will use gems from local
cache instead of fetching from the Internet.</p>
<h2>Speeding up &quot;rake assets:precompile&quot; task by using cache</h2>
<p>JavaScript code written in TypeScript, Elm, JSX etc cannot be directly served to
the browser. Almost all web browsers understands JavaScript (ES4), CSS and image
files. Therefore, we need to transpile, compile or convert the source asset into
the formats which browsers can understand. In Rails,
<a href="https://github.com/rails/sprockets">Sprockets</a> is the most widely used library
for managing and compiling assets.</p>
<p>In development environment, Sprockets compiles assets on-the-fly as and when
needed using <code>Sprockets::Server</code>. In production environment, recommended
approach is to pre-compile assets in a directory on disk and serve it using a
web server like Nginx.</p>
<p>Precompilation is a multi-step process for converting a source asset file into a
static and optimized form using components such as processors, transformers,
compressors, directives, environments, a manifest and pipelines with the help of
various gems such as <code>sass-rails</code>, <code>execjs</code>, etc. The assets need to be
precompiled in production so that Sprockets need not resolve inter-dependencies
between required source dependencies every time a static asset is requested. To
understand how Sprockets work in great detail, please read
<a href="https://github.com/rails/sprockets/blob/0cb3314368f9f9e84343ebedcc09c7137e920bc4/guides/how_sprockets_works.md#sprockets">this guide</a>.</p>
<p>When we compile source assets using <code>rake assets:precompile</code> task, we can find
the compiled assets in <code>public/assets</code> directory inside our Rails application.</p>
<pre><code class="language-bash">$ ls public/assets
manifest-15adda275d6505e4010b95819cf61eb3.json
icons-6250335393ad03df1c67eafe138ab488.eot
icons-6250335393ad03df1c67eafe138ab488.eot.gz
cons-b341bf083c32f9e244d0dea28a763a63.svg
cons-b341bf083c32f9e244d0dea28a763a63.svg.gz
application-8988c56131fcecaf914b22f54359bf20.js
application-8988c56131fcecaf914b22f54359bf20.js.gz
xlsx.full.min-feaaf61b9d67aea9f122309f4e78d5a5.js
xlsx.full.min-feaaf61b9d67aea9f122309f4e78d5a5.js.gz
application-adc697aed7731c864bafaa3319a075b1.css
application-adc697aed7731c864bafaa3319a075b1.css.gz
FontAwesome-42b44fdc9088cae450b47f15fc34c801.otf
FontAwesome-42b44fdc9088cae450b47f15fc34c801.otf.gz
[...]
</code></pre>
<p>We can see that the each source asset has been compiled and minified along with
its gunzipped version.</p>
<p>Note that the assets have a unique and random digest or fingerprint in their
file names. A digest is a hash calculated by Sprockets from the contents of an
asset file. If the contents of an asset is changed, then that asset's digest
also changes. The digest is mainly used for busting cache so a new version of
the same asset can be generated if the source file is modified or the configured
cache period is expired.</p>
<p>The <code>rake assets:precompile</code> task also generates a manifest file along with the
precompiled assets. This manifest is used by Sprockets to perform fast lookups
without having to actually compile our assets code.</p>
<p>An example manifest file, in our case
<code>public/assets/manifest-15adda275d6505e4010b95819cf61eb3.json</code> looks like this.</p>
<pre><code class="language-json">{
  &quot;files&quot;: {
    &quot;application-8988c56131fcecaf914b22f54359bf20.js&quot;: {
      &quot;logical_path&quot;: &quot;application.js&quot;,
      &quot;mtime&quot;: &quot;2018-07-06T07:32:27+00:00&quot;,
      &quot;size&quot;: 3797752,
      &quot;digest&quot;: &quot;8988c56131fcecaf914b22f54359bf20&quot;
    },
    &quot;xlsx.full.min-feaaf61b9d67aea9f122309f4e78d5a5.js&quot;: {
      &quot;logical_path&quot;: &quot;xlsx.full.min.js&quot;,
      &quot;mtime&quot;: &quot;2018-07-05T22:06:17+00:00&quot;,
      &quot;size&quot;: 883635,
      &quot;digest&quot;: &quot;feaaf61b9d67aea9f122309f4e78d5a5&quot;
    },
    &quot;application-adc697aed7731c864bafaa3319a075b1.css&quot;: {
      &quot;logical_path&quot;: &quot;application.css&quot;,
      &quot;mtime&quot;: &quot;2018-07-06T07:33:12+00:00&quot;,
      &quot;size&quot;: 242611,
      &quot;digest&quot;: &quot;adc697aed7731c864bafaa3319a075b1&quot;
    },
    &quot;FontAwesome-42b44fdc9088cae450b47f15fc34c801.otf&quot;: {
      &quot;logical_path&quot;: &quot;FontAwesome.otf&quot;,
      &quot;mtime&quot;: &quot;2018-06-20T06:51:49+00:00&quot;,
      &quot;size&quot;: 134808,
      &quot;digest&quot;: &quot;42b44fdc9088cae450b47f15fc34c801&quot;
    },
    [...]
  },
  &quot;assets&quot;: {
    &quot;icons.eot&quot;: &quot;icons-6250335393ad03df1c67eafe138ab488.eot&quot;,
    &quot;icons.svg&quot;: &quot;icons-b341bf083c32f9e244d0dea28a763a63.svg&quot;,
    &quot;application.js&quot;: &quot;application-8988c56131fcecaf914b22f54359bf20.js&quot;,
    &quot;xlsx.full.min.js&quot;: &quot;xlsx.full.min-feaaf61b9d67aea9f122309f4e78d5a5.js&quot;,
    &quot;application.css&quot;: &quot;application-adc697aed7731c864bafaa3319a075b1.css&quot;,
    &quot;FontAwesome.otf&quot;: &quot;FontAwesome-42b44fdc9088cae450b47f15fc34c801.otf&quot;,
    [...]
  }
}
</code></pre>
<p>Using this manifest file, Sprockets can quickly find a fingerprinted file name
using that file's logical file name and vice versa.</p>
<p>Also, Sprockets generates cache in binary format at <code>tmp/cache/assets</code> in the
Rails application's folder for the specified Rails environment. Following is an
example tree structure of the <code>tmp/cache/assets</code> directory automatically
generated after executing <code>RAILS_ENV=environment_here rake assets:precompile</code>
command for each Rails environment.</p>
<pre><code class="language-tree">$ cd tmp/cache/assets &amp;&amp; tree
.
├── demo
│   ├── sass
│   │   ├── 7de35a15a8ab2f7e131a9a9b42f922a69327805d
│   │   │   ├── application.css.sassc
│   │   │   └── bootstrap.css.sassc
│   │   ├── [...]
│   └── sprockets
│       ├── 002a592d665d92efe998c44adc041bd3
│       ├── 7dd8829031d3067dcf26ffc05abd2bd5
│       └── [...]
├── production
│   ├── sass
│   │   ├── 80d56752e13dda1267c19f4685546798718ad433
│   │   │   ├── application.css.sassc
│   │   │   └── bootstrap.css.sassc
│   │   ├── [...]
│   └── sprockets
│       ├── 143f5a036c623fa60d73a44d8e5b31e7
│       ├── 31ae46e77932002ed3879baa6e195507
│       └── [...]
└── staging
    ├── sass
    │   ├── 2101b41985597d41f1e52b280a62cd0786f2ee51
    │   │   ├── application.css.sassc
    │   │   └── bootstrap.css.sassc
    │   ├── [...]
    └── sprockets
        ├── 2c154d4604d873c6b7a95db6a7d5787a
        ├── 3ae685d6f922c0e3acea4bbfde7e7466
        └── [...]
</code></pre>
<p>Let's inspect the contents of an example cached file. Since the cached file is
in binary form, we can forcefully see the non-visible control characters as well
as the binary content in text form using <code>cat -v</code> command.</p>
<pre><code class="language-bash">$ cat -v tmp/cache/assets/staging/sprockets/2c154d4604d873c6b7a95db6a7d5787a

^D^H{^QI&quot;
class^F:^FETI&quot;^SProcessedAsset^F;^@FI&quot;^Qlogical_path^F;^@TI&quot;^]components/Comparator.js^F;^@TI&quot;^Mpathname^F;^@TI&quot;T$root/app/assets/javascripts/components/Comparator.jsx^F;^@FI&quot;^Qcontent_type^F;^@TI&quot;^[application/javascript^F;^@TI&quot;
mtime^F;^@Tl+^GM-gM-z;[I&quot;^Klength^F;^@Ti^BM-L^BI&quot;^Kdigest^F;^@TI&quot;%18138d01fe4c61bbbfeac6d856648ec9^F;^@FI&quot;^Ksource^F;^@TI&quot;^BM-L^Bvar Comparator = function (props) {
  var comparatorOptions = [React.createElement(&quot;option&quot;, { key: &quot;?&quot;, value: &quot;?&quot; })];
  var allComparators = props.metaData.comparators;
  var fieldDataType = props.fieldDataType;
  var allowedComparators = allComparators[fieldDataType] || allComparators.integer;
  return React.createElement(
    &quot;select&quot;,
    {
      id: &quot;comparator-&quot; + props.id,
      disabled: props.disabled,
      onChange: props.handleComparatorChange,
      value: props.comparatorValue },
    comparatorOptions.concat(allowedComparators.map(function (comparator, id) {
      return React.createElement(
        &quot;option&quot;,
        { key: id, value: comparator },
        comparator
      );
    }))
  );
};^F;^@TI&quot;^Vdependency_digest^F;^@TI&quot;%d6c86298311aa7996dd6b5389f45949f^F;^@FI&quot;^Srequired_paths^F;^@T[^FI&quot;T$root/app/assets/javascripts/components/Comparator.jsx^F;^@FI&quot;^Udependency_paths^F;^@T[^F{^HI&quot;   path^F;^@TI&quot;T$root/app/assets/javascripts/components/Comparator.jsx^F;^@F@^NI&quot;^^2018-07-03T22:38:31+00:00^F;^@T@^QI&quot;%51ab9ceec309501fc13051c173b0324f^F;^@FI&quot;^M_version^F;^@TI&quot;%30fd133466109a42c8cede9d119c3992^F;^@F
</code></pre>
<p>We can see that there are some weird looking characters in the above file
because it is not a regular file to be read by humans. Also, it seems to be
holding some important information such as mime-type, original source code's
path, compiled source, digest, paths and digests of required dependencies, etc.
Above compiled cache appears to be of the original source file located at
<code>app/assets/javascripts/components/Comparator.jsx</code> having actual contents in JSX
and ES6 syntax as shown below.</p>
<pre><code class="language-jsx">const Comparator = props =&gt; {
  const comparatorOptions = [&lt;option key=&quot;?&quot; value=&quot;?&quot; /&gt;];
  const allComparators = props.metaData.comparators;
  const fieldDataType = props.fieldDataType;
  const allowedComparators =
    allComparators[fieldDataType] || allComparators.integer;
  return (
    &lt;select
      id={`comparator-${props.id}`}
      disabled={props.disabled}
      onChange={props.handleComparatorChange}
      value={props.comparatorValue}
    &gt;
      {comparatorOptions.concat(
        allowedComparators.map((comparator, id) =&gt; (
          &lt;option key={id} value={comparator}&gt;
            {comparator}
          &lt;/option&gt;
        ))
      )}
    &lt;/select&gt;
  );
};
</code></pre>
<p>If similar cache exists for a Rails environment under <code>tmp/cache/assets</code> and if
no source asset file is modified then re-running the <code>rake assets:precompile</code>
task for the same environment will finish quickly. This is because Sprockets
will reuse the cache and therefore will need not to resolve the inter-assets
dependencies, perform conversion, etc.</p>
<p>Even if certain source assets are modified, Sprockets will rebuild the cache and
re-generate compiled and fingerprinted assets just for the modified source
assets.</p>
<p>Therefore, now we can understand that that if we can reuse the directories
<code>tmp/cache/assets</code> and <code>public/assets</code> every time we need to execute
<code>rake assets:precompile</code> task, then the Sprockets will perform precompilation
much faster.</p>
<h2>Speeding up &quot;docker build&quot; -- first attempt</h2>
<p>As discussed above, we were now familiar about how to speed up the
<code>bundle install</code> and <code>rake assets:precompile</code> commands individually.</p>
<p>We decided to use this knowledge to speed up our slow <code>docker build</code> command.
Our initial thought was to mount a directory on the host Jenkins machine into
the filesystem of the image being built by the <code>docker build</code> command. This
mounted directory then can be used as a cache directory to persist the cache
files of both <code>bundle install</code> and <code>rake assets:precompile</code> commands run as part
of <code>docker build</code> command in each Jenkins build. Then every new build could
reuse the previous build's cache and therefore could finish faster.</p>
<p>Unfortunately, this wasn't possible due to no support from Docker yet. Unlike
the <code>docker run</code> command, we cannot mount a host directory into <code>docker build</code>
command. A feature request for providing a shared host machine directory path
option to the <code>docker build</code> command is still
<a href="https://github.com/moby/moby/issues/14080#issuecomment-119371247">open here</a>.</p>
<p>To reuse cache and perform faster, we need to carry the cache files of both
<code>bundle install</code> and <code>rake assets:precompile</code> commands between each
<code>docker build</code> (therefore, Jenkins build). We were looking for some place which
can be treated as a shared cache location and can be accessed during each build.</p>
<p>We decided to use Amazon's <a href="https://aws.amazon.com/s3/">S3 service</a> to solve
this problem.</p>
<p>To upload and download files from S3, we needed to inject credentials for S3
into the build context provided to the <code>docker build</code> command.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/speeding-up-docker-image-build-process-of-a-rails-application/jenkins-configuration-to-inject-s3-credentials-in-docker-build.png" alt="Screenshot of Jenkins configuration to inject S3 credentials in docker build command"></p>
<p>Alternatively, these S3 credentials can be provided to the <code>docker build</code>
command using <code>--build-arg</code> option as discussed earlier.</p>
<p>We used <code>s3cmd</code> command-line utility to interact with the S3 service.</p>
<p>Following shell script named as <code>install_gems_and_precompile_assets.sh</code> was
configured to be executed using a <code>RUN</code> instruction while running the
<code>docker build</code> command.</p>
<pre><code class="language-bash">set -ex

# Step 1.
if [ -e s3cfg ]; then mv s3cfg ~/.s3cfg; fi

bundler_cache_path=&quot;vendor/cache&quot;
assets_cache_path=&quot;tmp/assets/cache&quot;
precompiled_assets_path=&quot;public/assets&quot;
cache_archive_name=&quot;cache.tar.gz&quot;
s3_bucket_path=&quot;s3://docker-builder-bundler-and-assets-cache&quot;
s3_cache_archive_path=&quot;$s3_bucket_path/$cache_archive_name&quot;

# Step 2.
# Fetch tarball archive containing cache and extract it.
# The &quot;tar&quot; command extracts the archive into &quot;vendor/cache&quot;,
# &quot;tmp/assets/cache&quot; and &quot;public/assets&quot;.
if s3cmd get $s3_cache_archive_path; then
  tar -xzf $cache_archive_name &amp;&amp; rm -f $cache_archive_name
fi

# Step 3.
# Install gems from &quot;vendor/cache&quot; and pack up them.
bin/bundle install --without development test --path $bundler_cache_path
bin/bundle pack --quiet

# Step 4.
# Precompile assets.
# Note that the &quot;RAILS_ENV&quot; is already defined in Dockerfile
# and will be used implicitly.
bin/rake assets:precompile

# Step 5.
# Compress &quot;vendor/cache&quot;, &quot;tmp/assets/cache&quot;
# and &quot;public/assets&quot; directories into a tarball archive.
tar -zcf $cache_archive_name $bundler_cache_path \
                             $assets_cache_path  \
                             $precompiled_assets_path

# Step 6.
# Push the compressed archive containing updated cache to S3.
s3cmd put $cache_archive_name $s3_cache_archive_path || true

# Step 7.
rm -f $cache_archive_name ~/.s3cfg
</code></pre>
<p>Let's discuss the various steps annotated in the above script.</p>
<ol>
<li>The S3 credentials file injected by Jenkins into the build context needs to
be placed at <code>~/.s3cfg</code> location, so we move that credentials file
accordingly.</li>
<li>Try to fetch the compressed tarball archive comprising directories such as
<code>vendor/cache</code>, <code>tmp/assets/cache</code> and <code>public/assets</code>. If exists, extract
the tarball archive at respective paths and remove that tarball.</li>
<li>Execute the <code>bundle install</code> command which would reuse the extracted cache
from <code>vendor/cache</code>.</li>
<li>Execute the <code>rake assets:precompile</code> command which would reuse the extracted
cache from <code>tmp/assets/cache</code> and <code>public/assets</code>.</li>
<li>Compress the cache directories <code>vendor/cache</code>, <code>tmp/assets/cache</code> and
<code>public/assets</code> in a tarball archive.</li>
<li>Upload the compressed tarball archive containing updated cache directories to
S3.</li>
<li>Remove the compressed tarball archive and the S3 credentials file.</li>
</ol>
<p>Please note that, in our actual case we had generated different tarball archives
depending upon the provided <code>RAILS_ENV</code> environment. For demonstration, here we
use just a single archive instead.</p>
<p>The <code>Dockerfile</code> needed to update to execute the
<code>install_gems_and_precompile_assets.sh</code> script.</p>
<pre><code class="language-dockerfile">FROM bigbinary/xyz-base:latest

ENV APP_PATH /data/app/

WORKDIR $APP_PATH

ADD . $APP_PATH

ARG RAILS_ENV

RUN install_gems_and_precompile_assets.sh

CMD [&quot;bin/bundle&quot;, &quot;exec&quot;, &quot;puma&quot;]
</code></pre>
<p>With this setup, average time of the Jenkins builds was now reduced to about 5
minutes. This was a great achievement for us.</p>
<p>We reviewed this approach in a great detail. We found that although the approach
was working fine, there was a major security flaw. It is not at all recommended
to inject confidential information such as login credentials, private keys, etc.
as part of the build context or using build arguments while building a Docker
image using <code>docker build</code> command. And we were actually injecting S3
credentials into the Docker image. Such confidential credentials provided while
building a Docker image can be inspected using <code>docker history</code> command by
anyone who has access to that Docker image.</p>
<p>Due to above reason, we needed to abandon this approach and look for another.</p>
<h2>Speeding up &quot;docker build&quot; -- second attempt</h2>
<p>In our second attempt, we decided to execute <code>bundle install</code> and
<code>rake assets:precompile</code> commands outside the <code>docker build</code> command. Outside
meaning the place to execute these commands was Jenkins build itself. So with
the new approach, we had to first execute <code>bundle install</code> and
<code>rake assets:precompile</code> commands as part of the Jenkins build and then execute
<code>docker build</code> as usual. With this approach, we could now avail the inter-build
caching benefits provided by Jenkins.</p>
<p>The prerequisite was to have all the necessary system packages installed on the
Jenkins machine required by the gems enlisted in the application's Gemfile. We
installed all the necessary system packages on our Jenkins server.</p>
<p>Following screenshot highlights the things that we needed to configure in our
Jenkins job to make this approach work.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/speeding-up-docker-image-build-process-of-a-rails-application/jenkins-configuration-to-install-arbitrary-ruby-version-and-perform-caching.png" alt="Screenshot of Jenkins configuration highlighting installation of arbitrary Ruby version and maintaining cache and bundling gems and precompiling assets outside Docker build"></p>
<h4>1. Running the Jenkins build in RVM managed environment with the specified Ruby version</h4>
<p>Sometimes, we need to use different Ruby version as specified in the
<code>.ruby-version</code> in the cloned source code of the application. By default, the
<code>bundle install</code> command would install the gems for the system Ruby version
available on the Jenkins machine. This was not acceptable for us. Therefore, we
needed a way to execute the <code>bundle install</code> command in Jenkins build in an
isolated environment which could use the Ruby version specified in the
<code>.ruby-version</code> file instead of the default system Ruby version. To address
this, we used <a href="https://wiki.jenkins.io/display/JENKINS/RVM+Plugin">RVM plugin</a>
for Jenkins. The RVM plugin enabled us to run the Jenkins build in an isolated
environment by using or installing the Ruby version specified in the
<code>.ruby-version</code> file. The section highlighted with green color in the above
screenshot shows the configuration required to enable this plugin.</p>
<h4>2. Carrying cache files between Jenkins builds required to speed up &quot;bundle install&quot; and &quot;rake assets:precompile&quot; commands</h4>
<p>We used <a href="https://wiki.jenkins.io/display/JENKINS/Job+Cacher+Plugin">Job Cacher</a>
Jenkins plugin to persist and carry the cache directories such as
<code>vendor/cache</code>, <code>tmp/cache/assets</code> and <code>public/assets</code> between builds. At the
beginning of a Jenkins build just after cloning the source code of the
application, the Job Cacher plugin restores the previously cached version of
these directories into the current build. Similarly, before finishing a Jenkins
build, the Job Cacher plugin copies the current version of these directories at
<code>/var/lib/jenkins/jobs/docker-builder/cache</code> on the Jenkins machine which is
outside the workspace directory of the Jenkins job. The section highlighted with
red color in the above screenshot shows the necessary configuration required to
enable this plugin.</p>
<h4>3. Executing the &quot;bundle install&quot; and &quot;rake assets:precompile&quot; commands before &quot;docker build&quot; command</h4>
<p>Using the &quot;Execute shell&quot; build step provided by Jenkins, we execute
<code>bundle install</code> and <code>rake assets:precompile</code> commands just before the
<code>docker build</code> command invoked by the CloudBees Docker Build and Publish plugin.
Since the Job Cacher plugin already restores the version of <code>vendor/cache</code>,
<code>tmp/cache/assets</code> and <code>public/assets</code> directories from the previous build into
the current build, the <code>bundle install</code> and <code>rake assets:precompile</code> commands
reuses the cache and performs faster.</p>
<p>The updated Dockerfile has lesser number of instructions now.</p>
<pre><code class="language-dockerfile">FROM bigbinary/xyz-base:latest

ENV APP_PATH /data/app/

WORKDIR $APP_PATH

ADD . $APP_PATH

CMD [&quot;bin/bundle&quot;, &quot;exec&quot;, &quot;puma&quot;]
</code></pre>
<p>With this approach, average Jenkins build time is now between 3.5 to 4.5
minutes.</p>
<p>Following graph shows the build time trend of some of the recent builds on our
Jenkins server.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/speeding-up-docker-image-build-process-of-a-rails-application/build-time-trend-after-speedup-tweaks.png" alt="Screenshot of build time trend graph after speedup tweaks"></p>
<p>Please note that the spikes in the above graphs shows that certain Jenkins
builds took more than 5 minutes sometimes due to concurrently running builds at
that time. Because our Jenkins server has a limited set of resources,
concurrently running builds often run longer than estimated.</p>
<p>We are still looking to improve the containerization speed even more and still
maintaining the image size small. Please let us know if there's anything else we
can do to improve the containerization process.</p>
<p>Note that that our Jenkins server runs on the Ubuntu OS which is based on
Debian. Our base Docker image is also based on Debian. Some of the gems in our
Gemfile are native extensions written in C. The pre-installed gems on Jenkins
machine have been working without any issues while running inside the Docker
containers on Kubernetes. It may not work if both of the platforms are different
since native extension gems installed on Jenkins host may fail to work inside
the Docker container.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Tailing logs with Logtrail, Kibana and Kubernetes]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/tail-log-using-logtrail-with-elk-on-kubernetes"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/tail-log-using-logtrail-with-elk-on-kubernetes.png"/>
      <id>https://www.bigbinary.com/blog/tail-log-using-logtrail-with-elk-on-kubernetes</id>
      <published>2018-06-01T00:00:00.000Z</published>
      <updated>2018-06-01T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/tail-log-using-logtrail-with-elk-on-kubernetes.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Using Logtrail(Papertrail like UI) to tail log with Elasticsearch and Kibana on Kubernetes]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/tail-log-using-logtrail-with-elk-on-kubernetes"><![CDATA[<p>Monitoring and Logging are important aspects of deployments. Centralized logging
is always useful in helping us identify the problems.</p>
<p>EFK (Elasticsearch, Fluentd, Kibana) is a beautiful combination of tools to
store logs centrally and visualize them on a single click. There are many other
open-source logging tools available in the market but EFK (ELK if Logstash is
used) is one of the most widely used centralized logging tools.</p>
<p>This blog post shows how to integrate
<a href="https://github.com/sivasamyk/logtrail">Logtrail</a> which has a
<a href="https://papertrailapp.com/">papertrail</a> like UI to tail the logs. Using
Logtrail we can also apply filters to tail the logs centrally.</p>
<p>As EFK ships as an add-on with Kubernetes, all we have to do is deploy the EFK
add-on on our k8s cluster.</p>
<h4>Pre-requisite:</h4>
<ul>
<li>
<p>Access to working kubernetes cluster with
<a href="https://kubernetes.io/docs/reference/kubectl/kubectl/">kubectl</a>
configuration.</p>
</li>
<li>
<p>All our application logs should be redirected to STDOUT, so that Fluentd
forwards them to Elasticsearch.</p>
</li>
<li>
<p>Understanding of <a href="http://kubernetes.io/">Kubernetes</a> terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>,
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>,
<a href="https://kubernetes.io/docs/concepts/services-networking/service/">services</a>,
<a href="https://kubernetes.io/docs/concepts/workloads/controllers/daemonset/">daemonsets</a>,
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-pod-configmap/">configmap</a>
and
<a href="https://kubernetes.io/docs/concepts/cluster-administration/addons/">addons</a>.</p>
</li>
</ul>
<p>Installing EFK add-on from
<a href="https://github.com/kubernetes/kops/tree/master/addons/logging-elasticsearch">kubernetes upstream</a>
is simple. Deploy EFK using following command.</p>
<pre><code class="language-bash">$ kubectl create -f https://raw.githubusercontent.com/kubernetes/kops/master/addons/logging-elasticsearch/v1.6.0.yaml
serviceaccount &quot;elasticsearch-logging&quot; created
clusterrole &quot;elasticsearch-logging&quot; created
clusterrolebinding &quot;elasticsearch-logging&quot; created
serviceaccount &quot;fluentd-es&quot; created
clusterrole &quot;fluentd-es&quot; created
clusterrolebinding &quot;fluentd-es&quot; created
daemonset &quot;fluentd-es&quot; created
service &quot;elasticsearch-logging&quot; created
statefulset &quot;elasticsearch-logging&quot; created
deployment &quot;kibana-logging&quot; created
service &quot;kibana-logging&quot; created
</code></pre>
<p>Once k8s resources are created access the Kibana dashboard. To access the
dashboard get the URL using <code>kubectl cluster-info</code></p>
<pre><code class="language-bash">$ kubectl cluster-info | grep Kibana
Kibana is running at https://api.k8s-test.com/api/v1/proxy/namespaces/kube-system/services/kibana-logging
</code></pre>
<p>Now goto Kibana dashboard and we should be able to see the logs on our
dashboard.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/tail-log-using-logtrail-with-elk-on-kubernetes/kibana_dashboard.png" alt="Kibana dashboard"></p>
<p>Above dashboard shows the Kibana UI. We can create metrics and graphs as per our
requirement.</p>
<p>We also want to view logs in <code>tail</code> style. We will use
<a href="https://github.com/sivasamyk/logtrail">logtrail</a> to view logs in tail format.
For that, we need docker image having logtrail plugin pre-installed.</p>
<p><strong>Note:</strong> If upstream Kibana version of k8s EFK add-on is 4.x, use kibana 4.x
image for installing logtrail plugin in your custom image. If add-on ships with
kibana version 5.x, make sure you pre-install logtrail on kibana 5 image.</p>
<p>Check the kibana version for add-on
<a href="https://github.com/kubernetes/kops/blob/master/addons/logging-elasticsearch/v1.6.0.yaml#L245">here</a>.</p>
<p>We will replace default kibana image with
<a href="https://hub.docker.com/r/rahulmahale/kubernetes-logtrail/">kubernetes-logtrail image</a>.</p>
<p>To replace docker image update the kibana deployment using below command.</p>
<pre><code class="language-bash">$ kubectl -n kube-system set image deployment/kibana-logging kibana-logging=rahulmahale/kubernetes-logtrail:latest
deployment &quot;kibana-logging&quot; image updated
</code></pre>
<p>Once the image is deployed go to the kibana dashboard and click on logtrail as
shown below.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/tail-log-using-logtrail-with-elk-on-kubernetes/kibana-logtrail-menu.png" alt="Switch to logtrail"></p>
<p>After switching to logtrail we will start seeing all the logs in real time as
shown below.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/tail-log-using-logtrail-with-elk-on-kubernetes/logtrail.png" alt="Logs in Logtrail"></p>
<p>This centralized logging dashboard with logtrail allows us to filter on several
parameters.</p>
<p>For example let's say we want to check all the logs for namespace <code>myapp</code>. We
can use filter <code>kubernetes.namespace_name:&quot;myapp&quot;</code>. We can user filter
<code>kubernetes.container_name:&quot;mycontainer&quot;</code> to monitor log for a specific
container.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Increase reliability using super_fetch of Sidekiq Pro]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/increase-reliability-of-background-job-processing-using-super_fetch-of-sidekiq-pro"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/increase-reliability-of-background-job-processing-using-super_fetch-of-sidekiq-pro.png"/>
      <id>https://www.bigbinary.com/blog/increase-reliability-of-background-job-processing-using-super_fetch-of-sidekiq-pro</id>
      <published>2018-05-08T00:00:00.000Z</published>
      <updated>2018-05-08T00:00:00.000Z</updated>
      <author>
        <name>Vishal Telangre</name>
        <uri>https://www.bigbinary.com/blog/authors/vishaltelangre</uri>
      </author>
      <category term="Ruby"/>
      <category term="Rails"/>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/increase-reliability-of-background-job-processing-using-super_fetch-of-sidekiq-pro.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Increase reliability of background job processing using super_fetch of Sidekiq Pro]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/increase-reliability-of-background-job-processing-using-super_fetch-of-sidekiq-pro"><![CDATA[<p><a href="https://github.com/mperham/sidekiq">Sidekiq</a>
is a background job processing library for Ruby.
Sidekiq offers three versions: OSS, Pro and Enterprise.</p>
<p>OSS is free and open source and has basic features.
Pro and Enterprise versions are closed source and paid,
thus comes with more advanced features.
To compare the list of features offered by each of these versions,
please visit <a href="https://sidekiq.org">Sidekiq website</a>.</p>
<p>Sidekiq Pro 3.4.0
<a href="https://github.com/mperham/sidekiq/blob/6e79f2a860ae558f2ed52b8917d2fede846c0a50/Pro-Changes.md#340">introduced</a>
<code>super_fetch</code> strategy
to reliably fetch jobs from the queue in Redis.</p>
<p>In this post, we will discuss the benefits of using <code>super_fetch</code> strategy.</p>
<h2>Problem</h2>
<p>Open source version of Sidekiq comes with <code>basic_fetch</code> strategy.
Let's see an example to understand how it works.</p>
<p>Let's add Sidekiq to our <code>Gemfile</code> and run <code>bundle install</code> to install it.</p>
<pre><code class="language-ruby">gem 'sidekiq'
</code></pre>
<p>Add following Sidekiq worker in <code>app/workers/sleep_worker.rb</code>.</p>
<pre><code class="language-ruby">class SleepWorker
  include Sidekiq::Worker

  def perform(name)
    puts &quot;Started #{name}&quot;
    sleep 30
    puts &quot;Finished #{name}&quot;
  end
end
</code></pre>
<p>This worker does nothing great but sleeps for 30 seconds.</p>
<p>Let's open Rails console
and schedule this worker to run as a background job asynchronously.</p>
<pre><code class="language-ruby">&gt;&gt; require &quot;sidekiq/api&quot;
=&gt; true
&gt;&gt; Sidekiq::Queue.new.size
=&gt; 0
&gt;&gt; SleepWorker.perform_async(&quot;A&quot;)
=&gt; &quot;5d8bf898c36a60a1096cf4d3&quot;
&gt;&gt; Sidekiq::Queue.new.size
=&gt; 1
</code></pre>
<p>As we can see, queue now has 1 job scheduled to be processed.</p>
<p>Let's start Sidekiq in another terminal tab.</p>
<pre><code class="language-ruby">$ bundle exec sidekiq

40510 TID-owu1swr1i INFO: Booting Sidekiq 5.1.3 with redis options {:id=&gt;&quot;Sidekiq-server-PID-40510&quot;, :url=&gt;nil}
40510 TID-owu1swr1i INFO: Starting processing, hit Ctrl-C to stop
40510 TID-owu1tr5my SleepWorker JID-5d8bf898c36a60a1096cf4d3 INFO: start
Started A
</code></pre>
<p>As we can see, the job with ID <code>5d8bf898c36a60a1096cf4d3</code>
was picked up by Sidekiq
and it started processing the job.</p>
<p>If we check the Sidekiq queue size in the Rails console, it will be zero now.</p>
<pre><code class="language-ruby">&gt;&gt; Sidekiq::Queue.new.size
=&gt; 0
</code></pre>
<p>Let's shutdown the Sidekiq process gracefully
while Sidekiq is still in the middle of processing our scheduled job.
Press either <code>Ctrl-C</code> or run <code>kill -SIGINT &lt;PID&gt;</code> command.</p>
<pre><code class="language-ruby">$ kill -SIGINT 40510
</code></pre>
<pre><code class="language-ruby">40510 TID-owu1swr1i INFO: Shutting down
40510 TID-owu1swr1i INFO: Terminating quiet workers
40510 TID-owu1x00rm INFO: Scheduler exiting...
40510 TID-owu1swr1i INFO: Pausing to allow workers to finish...
40510 TID-owu1swr1i WARN: Terminating 1 busy worker threads
40510 TID-owu1swr1i WARN: Work still in progress [#&lt;struct Sidekiq::BasicFetch::UnitOfWork queue=&quot;queue:default&quot;, job=&quot;{\&quot;class\&quot;:\&quot;SleepWorker\&quot;,\&quot;args\&quot;:[\&quot;A\&quot;],\&quot;retry\&quot;:true,\&quot;queue\&quot;:\&quot;default\&quot;,\&quot;jid\&quot;:\&quot;5d8bf898c36a60a1096cf4d3\&quot;,\&quot;created_at\&quot;:1525427293.956314,\&quot;enqueued_at\&quot;:1525427293.957355}&quot;&gt;]
40510 TID-owu1swr1i INFO: Pushed 1 jobs back to Redis
40510 TID-owu1tr5my SleepWorker JID-5d8bf898c36a60a1096cf4d3 INFO: fail: 19.576 sec
40510 TID-owu1swr1i INFO: Bye!
</code></pre>
<p>As we can see, Sidekiq pushed back the unfinished job back to Redis queue
when Sidekiq received a <code>SIGINT</code> signal.</p>
<p>Let's verify it.</p>
<pre><code class="language-ruby">&gt;&gt; Sidekiq::Queue.new.size
=&gt; 1
</code></pre>
<p>Before we move on, let's learn some basics about signals such as <code>SIGINT</code>.</p>
<h2>A crash course on POSIX signals</h2>
<p><code>SIGINT</code> is an interrupt signal.
It is an alternative to hitting
<code>Ctrl-C</code> from the keyboard.
When a process is running in foreground,
we can hit <code>Ctrl-C</code> to signal the process to shut down.
When the process is running in background,
we can use <code>kill</code> command to send a <code>SIGINT</code> signal to the process' PID.
A process can optionally catch this signal and shutdown itself gracefully.
If the process does not respect this signal and ignores it,
then nothing really happens and the process keeps running.
Both <code>INT</code> and <code>SIGINT</code> are identical signals.</p>
<p>Another useful signal is <code>SIGTERM</code>.
It is called a termination signal.
A process can either catch it
and perform necessary cleanup or just ignore it.
Similar to a <code>SIGINT</code> signal,
if a process ignores this signal, then the process keeps running.
Note that, if no signal is supplied to the <code>kill</code> command,
<code>SIGTERM</code> is used by default.
Both <code>TERM</code> and <code>SIGTERM</code> are identical signals.</p>
<p><code>SIGTSTP</code> or <code>TSTP</code> is called terminal stop signal.
It is an alternative to hitting <code>Ctrl-Z</code> on the keyboard.
This signal causes a process to suspend further execution.</p>
<p><code>SIGKILL</code> is known as kill signal.
This signal is intended to kill the process immediately and forcefully.
A process cannot catch this signal,
therefore the process cannot perform cleanup or graceful shutdown.
This signal is used
when a process does not respect and respond
to both <code>SIGINT</code> and <code>SIGTERM</code> signals.
<code>KILL</code>, <code>SIGKILL</code> and <code>9</code> are identical signals.</p>
<p>There are a lot of other signals besides these,
but they are not relevant for this post.
Please check them out <a href="https://en.wikipedia.org/wiki/Signal_(IPC)#POSIX_signals">here</a>.</p>
<p>A Sidekiq process pays respect
to all of these signals and behaves as we expect.
When Sidekiq receives a <code>TERM</code> or <code>SIGTERM</code> signal,
Sidekiq terminates itself gracefully.</p>
<h2>Back to our example</h2>
<p>Coming back to our example from above,
we had sent a <code>SIGINT</code> signal to the Sidekiq process.</p>
<pre><code class="language-ruby">$ kill -SIGINT 40510
</code></pre>
<p>On receiving this <code>SIGINT</code> signal,
Sidekiq process having PID 40510 terminated quiet workers,
paused the queue and waited for a while
to let busy workers finish their jobs.
Since our busy SleepWorker did not finish quickly,
Sidekiq terminated that busy worker
and pushed it back to the queue in Redis.
After that, Sidekiq gracefully terminated itself with an exit code 0.
Note that, the default timeout is 8 seconds
until which Sidekiq can wait to let the busy workers finish
otherwise it pushes the unfinished jobs back to the queue in Redis.
This timeout can be changed with <code>-t</code> option
given at the startup of Sidekiq process.</p>
<p>Sidekiq <a href="https://github.com/mperham/sidekiq/wiki/Deployment#overview">recommends</a>
to send a <code>TSTP</code> and a <code>TERM</code> together
to ensure that the Sidekiq process shuts down safely and gracefully.
On receiving a <code>TSTP</code> signal,
Sidekiq stops pulling new work
and
finishes the work which is in-progress.
The idea is to first send a <code>TSTP</code> signal,
wait as much as possible (by default for 8 seconds as discussed above)
to ensure that busy workers finish their jobs
and then send a <code>TERM</code> signal
to shutdown the process.</p>
<p>Sidekiq pushes back the unprocessed job in Redis when terminated gracefully.
It means that Sidekiq pulls the unfinished job and starts processing again when
we restart the Sidekiq process.</p>
<pre><code class="language-ruby">$ bundle exec sidekiq

45916 TID-ovfq8ll0k INFO: Booting Sidekiq 5.1.3 with redis options {:id=&gt;&quot;Sidekiq-server-PID-45916&quot;, :url=&gt;nil}
45916 TID-ovfq8ll0k INFO: Starting processing, hit Ctrl-C to stop
45916 TID-ovfqajol4 SleepWorker JID-5d8bf898c36a60a1096cf4d3 INFO: start
Started A
Finished A
45916 TID-ovfqajol4 SleepWorker JID-5d8bf898c36a60a1096cf4d3 INFO: done: 30.015 sec
</code></pre>
<p>We can see that Sidekiq pulled the previously terminated job
with ID <code>5d8bf898c36a60a1096cf4d3</code> and processed that job again.</p>
<p>So far so good.</p>
<p>This behavior is implemented using
<a href="https://github.com/mperham/sidekiq/blob/6e79f2a860ae558f2ed52b8917d2fede846c0a50/lib/sidekiq/fetch.rb"><code>basic_fetch</code></a>
strategy which is present in the open sourced version of Sidekiq.</p>
<p>Sidekiq uses <a href="https://redis.io/commands/brpop">BRPOP</a> Redis command
to fetch a scheduled job from the queue.
When a job is fetched,
that job gets removed from the queue and
that job no longer exists in Redis.
If this fetched job is processed, then all is good.
Also, if the Sidekiq process is terminated gracefully on
receiving either a <code>SIGINT</code> or a <code>SIGTERM</code> signal,
Sidekiq will push back the unfinished jobs back to the queue in Redis.</p>
<p>But what if the Sidekiq process crashes in the middle
while processing that fetched job?</p>
<p>A process is considered as crashed
if the process does not shutdown gracefully.
As we discussed before,
when we send a <code>SIGKILL</code> signal to a process,
the process cannot receive or catch this signal.
Because the process cannot shutdown gracefully and nicely,
it gets crashed.</p>
<p>When a Sidekiq process is crashed,
the fetched jobs by that Sidekiq process
which are not yet finished get lost
forever.</p>
<p>Let's try to reproduce this scenario.</p>
<p>We will schedule another job.</p>
<pre><code class="language-ruby">&gt;&gt; SleepWorker.perform_async(&quot;B&quot;)
=&gt; &quot;37a5ab4139796c4b9dc1ea6d&quot;

&gt;&gt; Sidekiq::Queue.new.size
=&gt; 1
</code></pre>
<p>Now, let's start Sidekiq process and kill it using <code>SIGKILL</code> or <code>9</code> signal.</p>
<pre><code class="language-ruby">$ bundle exec sidekiq

47395 TID-ow8q4nxzf INFO: Starting processing, hit Ctrl-C to stop
47395 TID-ow8qba0x7 SleepWorker JID-37a5ab4139796c4b9dc1ea6d INFO: start
Started B
[1]    47395 killed     bundle exec sidekiq
</code></pre>
<pre><code class="language-ruby">$ kill -SIGKILL 47395
</code></pre>
<p>Let's check if Sidekiq had pushed the busy (unprocessed) job
back to the queue in Redis before terminating.</p>
<pre><code class="language-ruby">&gt;&gt; Sidekiq::Queue.new.size
=&gt; 0
</code></pre>
<p>No. It does not.</p>
<p>Actually, the Sidekiq process did not get a chance to shutdown gracefully
when it received the <code>SIGKILL</code> signal.</p>
<p>If we restart the Sidekiq process,
it cannot fetch that unprocessed job
since the job was not pushed back to the queue in Redis at all.</p>
<pre><code class="language-ruby">$ bundle exec sidekiq

47733 TID-ox1lau26l INFO: Booting Sidekiq 5.1.3 with redis options {:id=&gt;&quot;Sidekiq-server-PID-47733&quot;, :url=&gt;nil}
47733 TID-ox1lau26l INFO: Starting processing, hit Ctrl-C to stop
</code></pre>
<p>Therefore,
the job having name argument as <code>B</code> or ID as <code>37a5ab4139796c4b9dc1ea6d</code>
is completely lost.
There is no way to get that job back.</p>
<p>Losing job like this may not be a problem for some applications
but for some critical applications this could be a huge issue.</p>
<p>We faced a similar problem like this.
One of our clients' application is deployed on a Kubernetes cluster.
Our Sidekiq process runs in a Docker container
in the Kubernetes
<a href="https://kubernetes.io/docs/concepts/workloads/pods/pod">pods</a>
which we call <code>background</code> pods.</p>
<p>Here's our stripped down version of
<a href="https://kubernetes.io/docs/concepts/workloads/controllers/deployment/">Kubernetes deployment</a>
manifest which creates a Kubernetes deployment resource.
Our Sidekiq process runs in the pods spawned by that deployment resource.</p>
<pre><code class="language-ruby">---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  name: background
spec:
  replicas: 2
  template:
    spec:
      terminationGracePeriodSeconds: 60
      containers:
      - name: background
        image: &lt;%= ENV['IMAGE'] %&gt;
        env:
        - name: POD_TYPE
          value: background
        lifecycle:
          preStop:
            exec:
              command:
              - /bin/bash
              - -l
              - -c
              - for pid in tmp/pids/sidekiq*.pid; do bin/bundle exec sidekiqctl stop $pid 60; done
</code></pre>
<p>When we apply an updated version of this manifest
,for say, changing the Docker image, the running pods are terminated
and new pods are created.</p>
<p>Before terminating the only container in the pod,
Kubernetes executes <code>sidekiqctl stop $pid 60</code> command
which we have defined using the
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/attach-handler-lifecycle-event/">preStop</a>
event handler.
Note that, Kubernetes already sends <code>SIGTERM</code> signal
to the container being terminated inside the pod
before invoking the <code>preStop</code> event handler.
The default termination grace period is 30 seconds and it is configurable.
If the container doesn't terminate within the termination grace period,
a <code>SIGKILL</code> signal will be sent to forcefully terminate the container.</p>
<p>The <code>sidekiqctl stop $pid 60</code> command executed in the <code>preStop</code> handler does
three things.</p>
<ol>
<li>Sends a <code>SIGTERM</code> signal to the Sidekiq process running in the container.</li>
<li>Waits for 60 seconds.</li>
<li>Sends a <code>SIGKILL</code> signal to kill the Sidekiq process forcefully
if the process has not terminated gracefully yet.</li>
</ol>
<p>This worked for us when the count of busy jobs was relatively small.</p>
<p>When the number of processing jobs is higher,
Sidekiq does not get enough time
to quiet the busy workers
and fails to push some of them back on the Redis queue.</p>
<p>We found that some of the jobs were getting lost
when our <code>background</code> pod restarted.
We had to restart our background pod for
reasons such as
updating the Kubernetes deployment manifest,
pod being automatically evicted by Kubernetes
due to host node encountering OOM (out of memory) issue, etc.</p>
<p>We tried increasing both
<code>terminationGracePeriodSeconds</code> in the deployment manifest
as well as the <code>sidekiqctl stop</code> command's timeout.
Despite that,
we still kept facing the same issue
of losing jobs whenever pod restarts.</p>
<p>We even tried sending <code>TSTP</code> and then <code>TERM</code> after a timeout
relatively longer than 60 seconds.
But the pod was getting harshly terminated
without gracefully terminating Sidekiq process running inside it.
Therefore we kept losing the busy jobs
which were running during the pod termination.</p>
<h2>Sidekiq Pro's super_fetch</h2>
<p>We were looking for a way to stop losing our Sidekiq jobs
or a way to recover them reliably when our <code>background</code> Kubernetes pod restarts.</p>
<p>We realized that the commercial version of Sidekiq,
Sidekiq Pro offers an additional fetch strategy,
<a href="https://github.com/mperham/sidekiq/wiki/Reliability#using-super_fetch"><code>super_fetch</code></a>,
which seemed more efficient and reliable
compared to <code>basic_fetch</code> strategy.</p>
<p>Let's see what difference <code>super_fetch</code> strategy
makes over <code>basic_fetch</code>.</p>
<p>We will need to use <code>sidekiq-pro</code> gem which needs to be purchased.
Since Sidekiq Pro gem is close sourced, we cannot fetch it
from the default public gem registry,
<a href="https://rubygems.org">https://rubygems.org</a>.
Instead, we will have to fetch it from a private gem registry
which we get after purchasing it.
We add following code to our <code>Gemfile</code> and run <code>bundle install</code>.</p>
<pre><code class="language-ruby">source ENV['SIDEKIQ_PRO_GEM_URL'] do
  gem 'sidekiq-pro'
end
</code></pre>
<p>To enable <code>super_fetch</code>,
we need to add following code
in an initializer <code>config/initializers/sidekiq.rb</code>.</p>
<pre><code class="language-ruby">Sidekiq.configure_server do |config|
  config.super_fetch!
end
</code></pre>
<p>Well, that's it.
Sidekiq will use <code>super_fetch</code> instead of <code>basic_fetch</code> now.</p>
<pre><code class="language-ruby">$ bundle exec sidekiq

75595 TID-owsytgvqj INFO: Sidekiq Pro 4.0.2, commercially licensed.  Thanks for your support!
75595 TID-owsytgvqj INFO: Booting Sidekiq 5.1.3 with redis options {:id=&gt;&quot;Sidekiq-server-PID-75595&quot;, :url=&gt;nil}
75595 TID-owsytgvqj INFO: Starting processing, hit Ctrl-C to stop
75595 TID-owsys5imz INFO: SuperFetch activated
</code></pre>
<p>When <code>super_fetch</code> is activated, Sidekiq process' graceful shutdown behavior
is similar to that of <code>basic_fetch</code>.</p>
<pre><code class="language-ruby">&gt;&gt; SleepWorker.perform_async(&quot;C&quot;)
=&gt; &quot;f002a41393f9a79a4366d2b5&quot;
&gt;&gt; Sidekiq::Queue.new.size
=&gt; 1
</code></pre>
<pre><code class="language-ruby">$ bundle exec sidekiq

76021 TID-ow6kdcca5 INFO: Sidekiq Pro 4.0.2, commercially licensed.  Thanks for your support!
76021 TID-ow6kdcca5 INFO: Booting Sidekiq 5.1.3 with redis options {:id=&gt;&quot;Sidekiq-server-PID-76021&quot;, :url=&gt;nil}
76021 TID-ow6kdcca5 INFO: Starting processing, hit Ctrl-C to stop
76021 TID-ow6klq2cx INFO: SuperFetch activated
76021 TID-ow6kiesnp SleepWorker JID-f002a41393f9a79a4366d2b5 INFO: start
Started C
</code></pre>
<pre><code class="language-ruby">&gt;&gt; Sidekiq::Queue.new.size
=&gt; 0
</code></pre>
<pre><code class="language-ruby">$ kill -SIGTERM 76021
</code></pre>
<pre><code class="language-ruby">76021 TID-ow6kdcca5 INFO: Shutting down
76021 TID-ow6kdcca5 INFO: Terminating quiet workers
76021 TID-ow6kieuwh INFO: Scheduler exiting...
76021 TID-ow6kdcca5 INFO: Pausing to allow workers to finish...
76021 TID-ow6kdcca5 WARN: Terminating 1 busy worker threads
76021 TID-ow6kdcca5 WARN: Work still in progress [#&lt;struct Sidekiq::Pro::SuperFetch::Retriever::UnitOfWork queue=&quot;queue:default&quot;, job=&quot;{\&quot;class\&quot;:\&quot;SleepWorker\&quot;,\&quot;args\&quot;:[\&quot;C\&quot;],\&quot;retry\&quot;:true,\&quot;queue\&quot;:\&quot;default\&quot;,\&quot;jid\&quot;:\&quot;f002a41393f9a79a4366d2b5\&quot;,\&quot;created_at\&quot;:1525500653.404454,\&quot;enqueued_at\&quot;:1525500653.404501}&quot;, local_queue=&quot;queue:sq|vishal.local:76021:3e64c4b08393|default&quot;&gt;]
76021 TID-ow6kdcca5 INFO: SuperFetch: Moving job from queue:sq|vishal.local:76021:3e64c4b08393|default back to queue:default
76021 TID-ow6kiesnp SleepWorker JID-f002a41393f9a79a4366d2b5 INFO: fail: 13.758 sec
76021 TID-ow6kdcca5 INFO: Bye!
</code></pre>
<pre><code class="language-ruby">&gt;&gt; Sidekiq::Queue.new.size
=&gt; 1
</code></pre>
<p>That looks good.
As we can see, Sidekiq moved busy job back from a private queue
to the queue in Redis
when Sidekiq received a <code>SIGTERM</code> signal.</p>
<p>Now, let's try to kill Sidekiq process forcefully
without allowing a graceful shutdown
by sending a <code>SIGKILL</code> signal.</p>
<p>Since Sidekiq was gracefully shutdown before,
if we restart Sidekiq again,
it will re-process the pushed back job having ID <code>f002a41393f9a79a4366d2b5</code>.</p>
<pre><code class="language-ruby">$ bundle exec sidekiq

76890 TID-oxecurbtu INFO: Sidekiq Pro 4.0.2, commercially licensed.  Thanks for your support!
76890 TID-oxecurbtu INFO: Booting Sidekiq 5.1.3 with redis options {:id=&gt;&quot;Sidekiq-server-PID-76890&quot;, :url=&gt;nil}
76890 TID-oxecurbtu INFO: Starting processing, hit Ctrl-C to stop
76890 TID-oxecyhftq INFO: SuperFetch activated
76890 TID-oxecyotvm SleepWorker JID-f002a41393f9a79a4366d2b5 INFO: start
Started C
[1]    76890 killed     bundle exec sidekiq
</code></pre>
<pre><code class="language-ruby">$ kill -SIGKILL 76890
</code></pre>
<pre><code class="language-ruby">&gt;&gt; Sidekiq::Queue.new.size
=&gt; 0
</code></pre>
<p>It appears that Sidekiq didn't get any chance
to push the busy job back to the queue in Redis
on receiving a <code>SIGKILL</code> signal.</p>
<p>So, where is the magic of <code>super_fetch</code>?</p>
<p>Did we lose our job again?</p>
<p>Let's restart Sidekiq and see it ourself.</p>
<pre><code class="language-ruby">$ bundle exec sidekiq

77496 TID-oum04ghgw INFO: Sidekiq Pro 4.0.2, commercially licensed.  Thanks for your support!
77496 TID-oum04ghgw INFO: Booting Sidekiq 5.1.3 with redis options {:id=&gt;&quot;Sidekiq-server-PID-77496&quot;, :url=&gt;nil}
77496 TID-oum04ghgw INFO: Starting processing, hit Ctrl-C to stop
77496 TID-oum086w9s INFO: SuperFetch activated
77496 TID-oum086w9s WARN: SuperFetch: recovered 1 jobs
77496 TID-oum08eu3o SleepWorker JID-f002a41393f9a79a4366d2b5 INFO: start
Started C
Finished C
77496 TID-oum08eu3o SleepWorker JID-f002a41393f9a79a4366d2b5 INFO: done: 30.011 sec
</code></pre>
<p>Whoa, isn't that cool?</p>
<p>See that line where it says <code>SuperFetch: recovered 1 jobs</code>.</p>
<p>Although the job wasn't pushed back to the queue in Redis,
Sidekiq somehow recovered our lost job having ID <code>f002a41393f9a79a4366d2b5</code>
and reprocessed that job again!</p>
<p>Interested to learn about how Sidekiq did that? Keep on reading.</p>
<p>Note that, since Sidekiq Pro is a close sourced and commercial software,
we cannot explain <code>super_fetch</code>'s exact implementation details.</p>
<p>As we discussed in-depth before,
Sidekiq's <code>basic_fetch</code> strategy uses <code>BRPOP</code> Redis command
to fetch a job from the queue in Redis.
It works great to some extent,
but it is prone to losing job
if Sidekiq crashes or does not shutdown gracefully.</p>
<p>On the other hand, Sidekiq Pro offers <code>super_fetch</code> strategy which uses
<a href="http://redis.io/commands/rpoplpush">RPOPLPUSH</a> Redis command to fetch a job.</p>
<p><code>RPOPLPUSH</code> Redis command provides
a unique approach towards implementing a reliable queue.
<code>RPOPLPUSH</code> command accepts two lists
namely a source list and a destination list.
This command atomically
returns and removes the last element from the source list,
and pushes that element as the first element in the destination list.
Atomically means that both pop and push operations
are performed as a single operation at the same time;
i.e. both should succeed, otherwise both are treated as failed.</p>
<p><code>super_fetch</code> registers a private queue in Redis
for each Sidekiq process on start-up.
<code>super_fetch</code> atomically fetches a scheduled job
from the public queue in Redis
and pushes that job into the private queue (or working queue)
using <code>RPOPLPUSH</code> Redis command.
Once the job is finished processing,
Sidekiq removes that job from the private queue.
During a graceful shutdown,
Sidekiq moves back the unfinished jobs
from the private queue to the public queue.
If shutdown of Sidekiq process is not graceful,
the unfinished jobs of that Sidekiq process
remain there in the private queue which are called as orphaned jobs.
On restarting or starting another Sidekiq process,
<code>super_fetch</code> looks for such orphaned jobs in the private queues.
If Sidekiq finds orphaned jobs, Sidekiq re-enqueue them and processes again.</p>
<p>It may happen that
we have multiple Sidekiq processes running at the same time.
If a process dies among them, its unfinished jobs become orphans.
<a href="https://github.com/mperham/sidekiq/wiki/Reliability#recovering-jobs">This Sidekiq wiki</a>
describes in detail the criteria which <code>super_fetch</code> relies upon
for identifying which jobs are orphaned and which jobs are not orphaned.
If we don't restart or start another process,
<code>super_fetch</code> may take 5 minutes or 3 hours to recover such orphaned jobs.
The recommended approach is to restart or start another Sidekiq process
to signal <code>super_fetch</code> to look for orphans.</p>
<p>Interestingly, in the older versions of Sidekiq Pro,
<code>super_fetch</code> performed checks for orphaned jobs and queues
<a href="https://github.com/mperham/sidekiq/issues/3273">every 24 hours</a>
at the Sidekiq process startup.
Due to this, when the Sidekiq process crashes,
the orphaned jobs of that process remain unpicked for up to 24 hours
until the next restart.
This orphan delay check window
had been later lowered to 1 hour in Sidekiq Pro 3.4.1.</p>
<p>Another fun thing to know is that,
there existed two fetch strategies namely
<a href="https://github.com/mperham/sidekiq/wiki/Reliability/_compare/71312b1f3880bcee9ff47f59c7516c15657553d8...15776fd781848a36a0ddb24c3f2315202696e30c"><code>reliable_fetch</code></a>
and <code>timed_fetch</code>
in the older versions of Sidekiq Pro.
Apparently, <code>reliable_fetch</code>
<a href="https://github.com/mperham/sidekiq/wiki/Pro-Reliability-Server#reliable_fetch">did not work with Docker</a>
and <code>timed_fetch</code> had asymptotic computational complexity <code>O(log N)</code>,
comparatively
<a href="https://github.com/mperham/sidekiq/wiki/Pro-Reliability-Server#timed_fetch">less efficient</a>
than <code>super_fetch</code>,
which has asymptotic computational complexity <code>O(1)</code>.
Both of these strategies had been deprecated
in Sidekiq Pro 3.4.0 in favor of <code>super_fetch</code>.
Later, both of these strategies had been
<a href="https://github.com/mperham/sidekiq/blob/6e79f2a860ae558f2ed52b8917d2fede846c0a50/Pro-4.0-Upgrade.md#whats-new">removed</a>
in Sidekiq Pro 4.0
and <a href="https://github.com/mperham/sidekiq/wiki/Reliability#notes">are not documented anywhere</a>.</p>
<h2>Final result</h2>
<p>We have enabled <code>super_fetch</code> in our application and
it seemed to be working without any major issues so far.
Our Kubernetes <code>background</code> pods does not seem to
be loosing any jobs when these pods are restarted.</p>
<p>Update : Mike Pheram, author of Sidekiq, posted following
<a href="https://www.reddit.com/r/ruby/comments/8htnpe/increase_reliability_of_background_job_processing">comment</a>.</p>
<blockquote>
<p>Faktory provides all of the beanstalkd functionality, including the same reliability, with a nicer Web UI. It's free and OSS.
https://github.com/contribsys/faktory http://contribsys.com/faktory/</p>
</blockquote>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Deploying Docker Registry on Kubernetes using S3 Storage]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/deploying-docker-registry-on-kubernetes-using-s3-storage"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/deploying-docker-registry-on-kubernetes-using-s3-storage.png"/>
      <id>https://www.bigbinary.com/blog/deploying-docker-registry-on-kubernetes-using-s3-storage</id>
      <published>2018-05-03T00:00:00.000Z</published>
      <updated>2018-05-03T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/deploying-docker-registry-on-kubernetes-using-s3-storage.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Deploying self-hosted Docker Registry on kubernetes using S3 storage.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/deploying-docker-registry-on-kubernetes-using-s3-storage"><![CDATA[<p>In today's era of containerization, no matter what container we are using we
need an image to run the container. Docker images are stored on container
registries like Docker hub(cloud), Google Container Registry(GCR), AWS ECR,
quay.io etc.</p>
<p>We can also self-host docker registry on any docker platform. In this blog post,
we will see how to deploy docker registry on kubernetes using storage driver S3.</p>
<h4>Pre-requisite:</h4>
<ul>
<li>
<p>Access to working kubernetes cluster.</p>
</li>
<li>
<p>Understanding of <a href="http://kubernetes.io/">Kubernetes</a> terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>,
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>,
<a href="https://kubernetes.io/docs/concepts/services-networking/service/">services</a>,
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-pod-configmap/">configmap</a>
and
<a href="https://kubernetes.io/docs/concepts/services-networking/ingress/">ingress</a>.</p>
</li>
</ul>
<p>As per docker registry
<a href="https://docs.docker.com/registry/deploying/">documentation</a>, We can simply
start the registry using docker image <code>registry</code>.</p>
<p>Basic parameters when deploying production registry are:</p>
<ul>
<li>Authentication</li>
<li>SSL</li>
<li>Storage</li>
</ul>
<p>We will use <strong>htpasswd</strong> authentication for this post though registry image
supports <strong>silly</strong> and <strong>token</strong> based authentication as well.</p>
<p>Docker registry requires applications to use SSL certificate and key in the
registry. We will use kubernetes service, which terminates SSL on ELB level
using annotations.</p>
<p>For registry storage, we can use filesystem, s3, azure, swift etc. For the
complete list of options please visit
<a href="https://docs.docker.com/registry/configuration/#storagedocker">docker site</a>
site.</p>
<p>We need to store the docker images pushed to the registry. We will use S3 to
store these docker images.</p>
<h4>Steps for deploying registry on kubernetes.</h4>
<p>Get the <code>ARN</code> of the SSL certificate to be used for SSL.</p>
<p>If you don't have SSL on AWS IAM, upload it using the following command.</p>
<pre><code class="language-bash">$aws iam upload-server-certificate --server-certificate-name registry --certificate-body file://registry.crt --private-key file://key.pem

</code></pre>
<p>Get the <code>arn</code> for the certificate using the command.</p>
<pre><code class="language-bash">$aws iam get-server-certificate --server-certificate-name registry  | grep Arn

</code></pre>
<p>Create S3 bucket which will be used to store docker images using s3cmd or aws
s3.</p>
<pre><code class="language-bash">
$s3cmd mb s3://myregistry
Bucket 's3://myregistry/' created

</code></pre>
<p>Create a separate namespace, configmap, deployment and service for registry
using following templates.</p>
<pre><code class="language-yaml">---
apiVersion: v1
kind: Namespace
metadata:
name: container-registry

---
apiVersion: v1
kind: ConfigMap
metadata:
  name: auth
  namespace: container-registry
data:
  htpasswd: |
    admin:$2y$05$TpZPzI7U7cr3cipe6jrOPe0bqohiwgEerEB6E4bFLsUf7Bk.SEBRi

---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  labels:
    app: registry
  name: registry
  namespace: container-registry
spec:
  replicas: 1
  strategy:
    type: RollingUpdate
  template:
    metadata:
      labels:
        app: registry
    spec:
      containers:
        - env:
            - name: REGISTRY_AUTH
              value: htpasswd
            - name: REGISTRY_AUTH_HTPASSWD_PATH
              value: /auth/htpasswd
            - name: REGISTRY_AUTH_HTPASSWD_REALM
              value: Registry Realm
            - name: REGISTRY_STORAGE
              value: s3
            - name: REGISTRY_STORAGE_S3_ACCESSKEY
              value: &lt;your-s3-access-key&gt;
            - name: REGISTRY_STORAGE_S3_BUCKET
              value: &lt;your-registry-bucket&gt;
            - name: REGISTRY_STORAGE_S3_REGION
              value: us-east-1
            - name: REGISTRY_STORAGE_S3_SECRETKEY
              value: &lt;your-secret-s3-key&gt;
          image: registry:2
          name: registry
          ports:
            - containerPort: 5000
          volumeMounts:
            - name: auth
              mountPath: /auth
      volumes:
        - name: auth
          configMap:
            name: auth
---
apiVersion: v1
kind: Service
metadata:
  annotations:
    service.beta.kubernetes.io/aws-load-balancer-ssl-cert: &lt;your-iam-certificate-arn&gt;
    service.beta.kubernetes.io/aws-load-balancer-instance-protocol: http
    service.beta.kubernetes.io/aws-load-balancer-ssl-ports: &quot;443&quot;
  labels:
    app: registry
  name: registry
  namespace: container-registry
spec:
  ports:
    - name: &quot;443&quot;
      port: 443
      targetPort: 5000
  selector:
    app: registry
type: LoadBalancer
</code></pre>
<p>Let's launch this manifest using <code>kubectl apply</code>.</p>
<pre><code class="language-bash">
kubectl apply -f registry-namespace.yml registry-configmap.yml registry-deployment.yaml registry-namespace.yml
namespace &quot;registry&quot; created
configmap &quot;auth&quot; created
deployment &quot;registry&quot; created
service &quot;registry&quot; created

</code></pre>
<p>Now that we have created registry, we should map DNS to web service ELB
endpoint. We can get the webservice ELB endpoint using the following command.</p>
<pre><code class="language-bash">
$kubectl -n registry get svc registry -o wide

NAME       CLUSTER-IP      EXTERNAL-IP                                                               PORT(S)         AGE       SELECTOR
registry   100.71.250.56   abcghccf8540698e8bff782799ca8h04-1234567890.us-east-2.elb.amazonaws.com   443:30494/TCP   1h       app=registry

</code></pre>
<p>We will point DNS to this ELB endpoint with domain registry.myapp.com</p>
<p>Once we have registry running, now it's time to push the image to a registry.</p>
<p>First, pull the image or build the image locally to push.</p>
<p>On local machine run following commands:</p>
<pre><code class="language-bash">
$docker pull busybox
latest: Pulling from busybox
f9ea5e501ad7: Pull complete
ac3f08b78d4e: Pull complete
Digest: sha256:da268b65d710e5ca91271f161d0ff078dc63930bbd6baac88d21b20d23b427ec
Status: Downloaded newer image for busybox:latest

</code></pre>
<p>Now login to our registry using the following commands.</p>
<pre><code class="language-bash">
$ sudo docker login registry.myapp.com

Username: admin

Password:

Login Succeeded

</code></pre>
<p>Now tag the image to point it to our registry using <code>docker tag</code> command</p>
<pre><code class="language-bash">$ sudo docker tag busybox registry.myapp.com/my-app:latest

</code></pre>
<p>Once the image is tagged we are good to push.</p>
<p>Using the <code>docker push</code> command let's push the image.</p>
<pre><code class="language-bash">
$ sudo docker push docker.gocloudlogistics.com/my-app:latest

The push refers to a repository [registry.myapp.com/my-app]

05732a3f47b5: Pushed
30de36c4bd15: Pushed
5237590c0d08: Pushed
latest: digest: sha256:f112e608b2639b21498bd4dbca9076d378cc216a80d52287f7f0f6ea6ad739ab size: 205

</code></pre>
<p>We are successfully able to push image to registry running on kunbernetes and
stored on S3. Let's verify if it exists on S3.</p>
<p>Navigate to our s3 bucket and we can see the docker registry repository
<code>busybox</code> has been created.</p>
<pre><code class="language-bash">$ s3cmd ls s3://myregistry/docker/registry/repositories/
DIR   s3://myregistry/docker/registry/repositories/busybox/

</code></pre>
<p>All our image related files are stored on S3.</p>
<p>In this way, we self-host container registry on kubernetes backed by s3 storage.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Path based routing for Rails with HAProxy Ingress]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/using-haproxy-ingress-with-rails-uniconrn-and-websockets"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-haproxy-ingress-with-rails-uniconrn-and-websockets.png"/>
      <id>https://www.bigbinary.com/blog/using-haproxy-ingress-with-rails-uniconrn-and-websockets</id>
      <published>2018-02-28T00:00:00.000Z</published>
      <updated>2018-02-28T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <category term="Rails"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-haproxy-ingress-with-rails-uniconrn-and-websockets.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Deploying Ruby on Rails application using HAProxy Ingress with unicorn/puma and websockets on Kubernetes.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/using-haproxy-ingress-with-rails-uniconrn-and-websockets"><![CDATA[<p>After months of testing we recently moved a Ruby on Rails application to
production that is using Kubernetes cluster.</p>
<p>In this article we will discuss how to setup path based routing for a Ruby on
Rails application in kubernetes using HAProxy ingress.</p>
<p>This post assumes that you have basic understanding of
<a href="http://kubernetes.io/">Kubernetes</a> terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>,
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>,
<a href="https://kubernetes.io/docs/concepts/services-networking/service/">services</a>,
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-pod-configmap/">configmap</a>
and <a href="https://kubernetes.io/docs/concepts/services-networking/ingress/">ingress</a>.</p>
<p>Typically our Rails app has services like unicorn/puma,
sidekiq/delayed-job/resque, Websockets and some dedicated API services. We had
one web service exposed to the world using load balancer and it was working
well. But as the traffic increased it became necessary to route traffic based on
URLs/path.</p>
<p>However Kubernetes does not supports this type of load balancing out of the box.
There is work in progress for
<a href="https://github.com/coreos/alb-ingress-controller">alb-ingress-controller</a> to
support this but we could not rely on it for production usage as it is still in
alpha.</p>
<p>The best way to achieve path based routing was to use
<a href="https://kubernetes.io/docs/concepts/services-networking/ingress/#ingress-controllers">ingress controller</a>.</p>
<p>We researched and found that there are different types of ingress available in
k8s world.</p>
<ol>
<li><a href="https://github.com/kubernetes/ingress-nginx">nginx-ingress</a></li>
<li><a href="https://github.com/kubernetes/ingress-gce">ingress-gce</a></li>
<li><a href="https://github.com/jcmoraisjr/haproxy-ingress">HAProxy-ingress</a></li>
<li><a href="https://docs.traefik.io/providers/kubernetes-ingress/">traefik</a></li>
<li><a href="https://github.com/appscode/voyager">voyager</a></li>
</ol>
<p>We experimented with nginx-ingress and HAProxy and decided to go with HAProxy.
HAProxy has better support for Rails websockets which we needed in the project.</p>
<p>We will walk you through step by step on how to use haproxy ingress in a Rails
app.</p>
<h3>Configuring Rails app with HAProxy ingress controller</h3>
<p>Here is what we are going to do.</p>
<ul>
<li>Create a Rails app with different services and deployments.</li>
<li>Create tls secret for SSL.</li>
<li>Create HAProxy ingress configmap.</li>
<li>Create HAProxy ingress controller.</li>
<li>Expose ingress with service type LoadBalancer</li>
<li>Setup app DNS with ingress service.</li>
<li>Create different ingress rules specifying path based routing.</li>
<li>Test the path based routing.</li>
</ul>
<p>Now let's build Rails application deployment manifest for services like
web(unicorn),background(sidekiq), Websocket(ruby thin),API(dedicated unicorn).</p>
<p>Here is our web app deployment and service template.</p>
<pre><code class="language-yaml">
---
apiVersion: v1
kind: Deployment
metadata:
  name: test-production-web
  labels:
    app: test-production-web
  namespace: test
spec:
  template:
    metadata:
      labels:
        app: test-production-web
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-production
        imagePullPolicy: Always
       env:
        - name: POSTGRES_HOST
          value: test-production-postgres
        - name: REDIS_HOST
          value: test-production-redis
        - name: APP_ENV
          value: production
        - name: APP_TYPE
          value: web
        - name: CLIENT
          value: test
        ports:
        - containerPort: 80
      imagePullSecrets:
        - name: registrykey
---
apiVersion: v1
kind: Service
metadata:
  name: test-production-web
  labels:
    app: test-production-web
  namespace: test
spec:
  ports:
  - port: 80
    protocol: TCP
    targetPort: 80
  selector:
    app: test-production-web

</code></pre>
<p>Here is background app deployment and service template.</p>
<pre><code class="language-yaml">
---
apiVersion: v1
kind: Deployment
metadata:
  name: test-production-background
  labels:
    app: test-production-background
  namespace: test
spec:
  template:
    metadata:
      labels:
        app: test-production-background
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-production
        imagePullPolicy: Always
       env:
        - name: POSTGRES_HOST
          value: test-production-postgres
        - name: REDIS_HOST
          value: test-production-redis
        - name: APP_ENV
          value: production
        - name: APP_TYPE
          value: background
        - name: CLIENT
          value: test
        ports:
        - containerPort: 80
      imagePullSecrets:
        - name: registrykey
---
apiVersion: v1
kind: Service
metadata:
  name: test-production-background
  labels:
    app: test-production-background
  namespace: test
spec:
  ports:
  - port: 80
    protocol: TCP
    targetPort: 80
  selector:
    app: test-production-background

</code></pre>
<p>Here is websocket app deployment and service template.</p>
<pre><code class="language-yaml">
---
apiVersion: v1
kind: Deployment
metadata:
  name: test-production-websocket
  labels:
    app: test-production-websocket
  namespace: test
spec:
  template:
    metadata:
      labels:
        app: test-production-websocket
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-production
        imagePullPolicy: Always
       env:
        - name: POSTGRES_HOST
          value: test-production-postgres
        - name: REDIS_HOST
          value: test-production-redis
        - name: APP_ENV
          value: production
        - name: APP_TYPE
          value: websocket
        - name: CLIENT
          value: test
        ports:
        - containerPort: 80
      imagePullSecrets:
        - name: registrykey
---
apiVersion: v1
kind: Service
metadata:
  name: test-production-websocket
  labels:
    app: test-production-websocket
  namespace: test
spec:
  ports:
  - port: 80
    protocol: TCP
    targetPort: 80
  selector:
    app: test-production-websocket

</code></pre>
<p>Here is API app deployment and service info.</p>
<pre><code class="language-yaml">
---
apiVersion: v1
kind: Deployment
metadata:
  name: test-production-api
  labels:
    app: test-production-api
  namespace: test
spec:
  template:
    metadata:
      labels:
        app: test-production-api
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-production
        imagePullPolicy: Always
       env:
        - name: POSTGRES_HOST
          value: test-production-postgres
        - name: REDIS_HOST
          value: test-production-redis
        - name: APP_ENV
          value: production
        - name: APP_TYPE
          value: api
        - name: CLIENT
          value: test
        ports:
        - containerPort: 80
      imagePullSecrets:
        - name: registrykey
---
apiVersion: v1
kind: Service
metadata:
  name: test-production-api
  labels:
    app: test-production-api
  namespace: test
spec:
  ports:
  - port: 80
    protocol: TCP
    targetPort: 80
  selector:
    app: test-production-api

</code></pre>
<p>Let's launch this manifest using <code>kubectl apply</code>.</p>
<pre><code class="language-bash">
$ kubectl apply -f test-web.yml -f test-background.yml -f test-websocket.yml -f test-api.yml
deployment &quot;test-production-web&quot; created
service &quot;test-production-web&quot; created
deployment &quot;test-production-background&quot; created
service &quot;test-production-background&quot; created
deployment &quot;test-production-websocket&quot; created
service &quot;test-production-websocket&quot; created
deployment &quot;test-production-api&quot; created
service &quot;test-production-api&quot; created

</code></pre>
<p>Once our app is deployed and running we should create HAProxy ingress. Before
that let's create a tls secret with our SSL key and certificate.</p>
<p>This is also used to enable HTTPS for app URL and to terminate it on L7.</p>
<pre><code class="language-bash">
$ kubectl create secret tls tls-certificate --key server.key --cert server.pem

</code></pre>
<p>Here <code>server.key</code> is our SSL key and <code>server.pem</code> is our SSL certificate in pem
format.</p>
<p>Now let's Create HAProxy controller resources.</p>
<h3>HAProxy configmap</h3>
<p>For all the available configuration parameters from HAProxy refer
<a href="https://github.com/jcmoraisjr/HAProxy-ingress#configmap">here</a>.</p>
<pre><code class="language-yaml">apiVersion: v1
data:
  dynamic-scaling: &quot;true&quot;
  backend-server-slots-increment: &quot;4&quot;
kind: ConfigMap
metadata:
  name: haproxy-configmap
  namespace: test
</code></pre>
<h3>HAProxy Ingress controller deployment</h3>
<p>Deployment template for the Ingress controller with at-least 2 replicas to
manage rolling deploys.</p>
<pre><code class="language-yaml">apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  labels:
    run: haproxy-ingress
  name: haproxy-ingress
  namespace: test
spec:
  replicas: 2
  selector:
    matchLabels:
      run: haproxy-ingress
  template:
    metadata:
      labels:
        run: haproxy-ingress
    spec:
      containers:
        - name: haproxy-ingress
          image: quay.io/jcmoraisjr/haproxy-ingress:v0.5-beta.1
          args:
            - --default-backend-service=$(POD_NAMESPACE)/test-production-web
            - --default-ssl-certificate=$(POD_NAMESPACE)/tls-certificate
            - --configmap=$(POD_NAMESPACE)/haproxy-configmap
            - --ingress-class=haproxy
          ports:
            - name: http
              containerPort: 80
            - name: https
              containerPort: 443
            - name: stat
              containerPort: 1936
          env:
            - name: POD_NAME
              valueFrom:
                fieldRef:
                  fieldPath: metadata.name
            - name: POD_NAMESPACE
              valueFrom:
                fieldRef:
                  fieldPath: metadata.namespace
</code></pre>
<p>Notable fields in above manifest are arguments passed to controller.</p>
<p><code>--default-backend-service</code> is the service when No rule is matched your request
will be served by this app.</p>
<p>In our case it is <code>test-production-web</code> service, But it can be custom 404 page
or whatever better you think.</p>
<p><code>--default-ssl-certificate</code> is the SSL secret we just created above this will
terminate SSL on L7 and our app is served on HTTPS to outside world.</p>
<h3>HAProxy Ingress service</h3>
<p>This is the <code>LoadBalancer</code> type service to allow client traffic to reach our
Ingress Controller.</p>
<p>LoadBalancer has access to both public network and internal Kubernetes network
while retaining the L7 routing of the Ingress Controller.</p>
<pre><code class="language-yaml">apiVersion: v1
kind: Service
metadata:
  labels:
    run: haproxy-ingress
  name: haproxy-ingress
  namespace: test
spec:
  type: LoadBalancer
  ports:
    - name: http
      port: 80
      protocol: TCP
      targetPort: 80
    - name: https
      port: 443
      protocol: TCP
      targetPort: 443
    - name: stat
      port: 1936
      protocol: TCP
      targetPort: 1936
  selector:
    run: haproxy-ingress
</code></pre>
<p>Now let's apply all the manifests of HAProxy.</p>
<pre><code class="language-bash">
$ kubectl apply -f haproxy-configmap.yml -f haproxy-deployment.yml -f haproxy-service.yml
configmap &quot;haproxy-configmap&quot; created
deployment &quot;haproxy-ingress&quot; created
service &quot;haproxy-ingress&quot; created

</code></pre>
<p>Once all the resources are running get the LoadBalancer endpoint using.</p>
<pre><code class="language-bash">
$ kubectl -n test get svc haproxy-ingress -o wide

NAME               TYPE           CLUSTER-IP       EXTERNAL-IP                                                            PORT(S)                                     AGE       SELECTOR
haproxy-ingress   LoadBalancer   100.67.194.186   a694abcdefghi11e8bc3b0af2eb5c5d8-806901662.us-east-1.elb.amazonaws.com   80:31788/TCP,443:32274/TCP,1936:32157/TCP   2m        run=ingress

</code></pre>
<h3>DNS mapping with application URL</h3>
<p>Once we have ELB endpoint of ingress service, map the DNS with URL like
<code>test-rails-app.com</code>.</p>
<h3>Ingress Implementation</h3>
<p>Now after doing all the hard work it is time to configure ingress and path based
rules.</p>
<p>In our case we want to have following rules.</p>
<p><em>https://test-rails-app.com</em> requests to be served by <code>test-production-web</code>.</p>
<p><em>https://test-rails-app.com/websocket</em> requests to be served by
<code>test-production-websocket</code>.</p>
<p><em>https://test-rails-app.com/api</em> requests to be served by <code>test-production-api</code>.</p>
<p>Let's create a ingress manifest defining all the rules.</p>
<pre><code class="language-yaml">---
apiVersion: extensions/v1beta1
kind: Ingress
metadata:
  name: ingress
  namespace: test
spec:
  tls:
    - hosts:
        - test-rails-app.com
      secretName: tls-certificate
  rules:
    - host: test-rails-app.com
      http:
        paths:
          - path: /
            backend:
              serviceName: test-production-web
              servicePort: 80
          - path: /api
            backend:
              serviceName: test-production-api
              servicePort: 80
          - path: /websocket
            backend:
              serviceName: test-production-websocket
              servicePort: 80
</code></pre>
<p>Moreover there are
<a href="https://github.com/jcmoraisjr/haproxy-ingress#annotations">Ingress Annotations</a>
for adjusting configuration changes.</p>
<p>As expected, now our default traffic on <code>/</code> is routed to <code>test-production-web</code>
service.</p>
<p><code>/api</code> is routed to <code>test-production-api</code> service.</p>
<p><code>/websocket</code> is routed to <code>test-production-websocket</code> service.</p>
<p>Thus ingress implementation solves our purpose of path based routing and
terminating SSL on L7 on Kubernetes.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Scheduling pods on nodes in Kubernetes using labels]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/scheduling-pods-on-nodes-in-kubernetes-using-labels"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/scheduling-pods-on-nodes-in-kubernetes-using-labels.png"/>
      <id>https://www.bigbinary.com/blog/scheduling-pods-on-nodes-in-kubernetes-using-labels</id>
      <published>2017-10-16T00:00:00.000Z</published>
      <updated>2017-10-16T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/scheduling-pods-on-nodes-in-kubernetes-using-labels.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Blog post on how to assign pods to specific nodes on Kubernetes]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/scheduling-pods-on-nodes-in-kubernetes-using-labels"><![CDATA[<p>This post assumes that you have basic understanding of
<a href="http://kubernetes.io/">Kubernetes</a> terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>,
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a> and
<a href="https://kubernetes.io/docs/concepts/architecture/nodes/">nodes</a>.</p>
<p>A Kubernetes cluster can have many nodes. Each node in turn can run multiple
pods. By default Kubernetes manages which pod will run on which node and this is
something we do not need to worry about it.</p>
<p>However sometimes we want to ensure that certain pods do not run on the same
node. For example we have an application called <em>wheel</em>. We have both staging
and production version of this app and we want to ensure that production pod and
staging pod are not on the same host.</p>
<p>To ensure that certain pods do not run on the same host we can use
<strong>nodeSelector</strong> constraint in <strong>PodSpec</strong> to schedule pods on nodes.</p>
<h3>Kubernetes cluster</h3>
<p>We will use <a href="https://github.com/kubernetes/kops/">kops</a> to provision cluster. We
can check the health of cluster using <code>kops validate-cluster</code>.</p>
<pre><code class="language-bash">$ kops validate cluster
Using cluster from kubectl context: test-k8s.nodes-staging.com

Validating cluster test-k8s.nodes-staging.com

INSTANCE GROUPS
NAME              ROLE   MACHINETYPE MIN MAX SUBNETS
master-us-east-1a Master m4.large    1   1 us-east-1a
master-us-east-1b Master m4.large    1   1 us-east-1b
master-us-east-1c Master m4.large    1   1 us-east-1c
nodes-wheel-stg   Node   m4.large    2   5 us-east-1a,us-east-1b
nodes-wheel-prd   Node   m4.large    2   5 us-east-1a,us-east-1b

NODE STATUS
           NAME                ROLE   READY
ip-192-10-110-59.ec2.internal  master True
ip-192-10-120-103.ec2.internal node   True
ip-192-10-42-9.ec2.internal    master True
ip-192-10-73-191.ec2.internal  master True
ip-192-10-82-66.ec2.internal   node   True
ip-192-10-72-68.ec2.internal   node   True
ip-192-10-182-70.ec2.internal  node   True

Your cluster test-k8s.nodes-staging.com is ready
</code></pre>
<p>Here we can see that there are two instance groups for nodes: <em>nodes-wheel-stg</em>
and <em>nodes-wheel-prd</em>.</p>
<p><em>nodes-wheel-stg</em> might have application pods like <em>pod-wheel-stg-sidekiq</em>,
<em>pod-wheel-stg-unicorn</em> and <em>pod-wheel-stg-redis</em>. Similarly <em>nodes-wheel-prd</em>
might have application pods like <em>pod-wheel-prd-sidekiq</em>,
<em>pod-wheel-prd-unicorn</em> and <em>pod-wheel-prd-redis</em>.</p>
<p>As we can see the <strong>Max number of nodes</strong> for instance group <em>nodes-wheel-stg</em>
and <em>nodes-wheel-prd</em> is 5. It means if new nodes are created in future then
based on the instance group the newly created nodes will automatically be
labelled and no manual work is required.</p>
<h3>Labelling a Node</h3>
<p>We will use
<a href="https://kubernetes.io/docs/concepts/overview/working-with-objects/labels/">kubernetes labels</a>
to label a node. To add a label we need to edit instance group using kops.</p>
<pre><code class="language-bash">$ kops edit ig nodes-wheel-stg
</code></pre>
<p>This will open up instance group configuration file, we will add following label
in instance group spec.</p>
<pre><code class="language-yaml">nodeLabels:
  type: wheel-stg
</code></pre>
<p>Complete <code>ig</code> configuration looks like this.</p>
<pre><code class="language-yaml">apiVersion: kops/v1alpha2
kind: InstanceGroup
metadata:
  creationTimestamp: 2017-10-12T06:24:53Z
  labels:
    kops.k8s.io/cluster: k8s.nodes-staging.com
  name: nodes-wheel-stg
spec:
  image: kope.io/k8s-1.7-debian-jessie-amd64-hvm-ebs-2017-07-28
  machineType: m4.large
  maxSize: 5
  minSize: 2
  nodeLabels:
    type: wheel-stg
  role: Node
  subnets:
    - us-east-1a
    - us-east-1b
    - us-east-1c
</code></pre>
<p>Similarly, we can label for instance group <em>nodes-wheel-prod</em> with label <em>type
wheel-prod</em>.</p>
<p>After making the changes update cluster using
<code>kops rolling update cluster --yes --force</code>. This will update the cluster with
specified labels.</p>
<p>New nodes added in future will have labels based on respective
<code>instance groups</code>.</p>
<p>Once nodes are labeled we can verify using <code>kubectl describe node</code>.</p>
<pre><code class="language-bash">$ kubectl describe node ip-192-10-82-66.ec2.internal
Name:               ip-192-10-82-66.ec2.internal
Roles:              node
Labels:             beta.kubernetes.io/arch=amd64
                    beta.kubernetes.io/instance-type=m4.large
                    beta.kubernetes.io/os=linux
                    failure-domain.beta.kubernetes.io/region=us-east-1
                    failure-domain.beta.kubernetes.io/zone=us-east-1a
                    kubernetes.io/hostname=ip-192-10-82-66.ec2.internal
                    kubernetes.io/role=node
                    type=wheel-stg
</code></pre>
<p>In this way we have our node labeled using kops.</p>
<h3>Labelling nodes using kubectl</h3>
<p>We can also label node using <code>kubectl</code>.</p>
<pre><code class="language-bash">$ kubectl label node ip-192-20-44-136.ec2.internal type=wheel-stg
</code></pre>
<p>After labeling a node, we will add <code>nodeSelector</code> field to our <code>PodSpec</code> in
deployment template.</p>
<p>We will add the following block in deployment manifest.</p>
<pre><code class="language-yaml">nodeSelector:
  type: wheel-stg
</code></pre>
<p>We can add this configuration in original deployment manifest.</p>
<pre><code class="language-yaml">apiVersion: v1
kind: Deployment
metadata:
  name: test-staging-node
  labels:
    app: test-staging
  namespace: test
spec:
  replicas: 1
  template:
    metadata:
      labels:
        app: test-staging
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-staging
        imagePullPolicy: Always
        - name: REDIS_HOST
          value: test-staging-redis
        - name: APP_ENV
          value: staging
        - name: CLIENT
          value: test
        ports:
        - containerPort: 80
      nodeSelector:
        type: wheel-stg
      imagePullSecrets:
        - name: registrykey
</code></pre>
<p>Let's launch this deployment and check where the pod is scheduled.</p>
<pre><code class="language-bash">$ kubectl apply -f test-deployment.yml
deployment &quot;test-staging-node&quot; created
</code></pre>
<p>We can verify that our pod is running on node <code>type=wheel-stg</code>.</p>
<pre><code class="language-bash">kubectl describe pod test-staging-2751555626-9sd4m
Name:           test-staging-2751555626-9sd4m
Namespace:      default
Node:           ip-192-10-82-66.ec2.internal/192.10.82.66
...
...
Conditions:
  Type           Status
  Initialized    True
  Ready          True
  PodScheduled   True
QoS Class:       Burstable
Node-Selectors:  type=wheel-stg
Tolerations:     node.alpha.kubernetes.io/notReady:NoExecute for 300s
                 node.alpha.kubernetes.io/unreachable:NoExecute for 300s
Events:          &lt;none&gt;
</code></pre>
<p>Similarly we run <em>nodes-wheel-prod</em> pods on nodes labeled with
<code>type: wheel-prod</code>.</p>
<p>Please note that when we specify <code>nodeSelector</code> and no node matches label then
pods are in <code>pending</code> state as they don't find node with matching label.</p>
<p>In this way we schedule our pods to run on specific nodes for certain use-cases.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Graceful shutdown of Sidekiq processes on Kubernetes]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/graceful-shutdown-of-sidekiq-processes-on-k8s"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/graceful-shutdown-of-sidekiq-processes-on-k8s.png"/>
      <id>https://www.bigbinary.com/blog/graceful-shutdown-of-sidekiq-processes-on-k8s</id>
      <published>2017-08-24T00:00:00.000Z</published>
      <updated>2017-08-24T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/graceful-shutdown-of-sidekiq-processes-on-k8s.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Blog post on how to handle graceful shutdown of processes like Sidekiq on Kubernetes]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/graceful-shutdown-of-sidekiq-processes-on-k8s"><![CDATA[<p>In our last <a href="https://www.bigbinary.com/blog/deploying-rails-applications-using-kubernetes-with-zero-downtime">blog</a>, we explained how to handle
rolling deployments of Rails applications with no downtime.</p>
<p>In this article we will walk you through
how to handle graceful shutdown of processes in Kubernetes.</p>
<p>This post assumes that you have basic understanding of
<a href="http://kubernetes.io/">Kubernetes</a>
terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>
and
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>.</p>
<h3>Problem</h3>
<p>When we deploy Rails applications on kubernetes
it stops existing pods and spins up new ones.
When old pod is terminated by Replicaset,
then active Sidekiq processes are also terminated.
We run our batch jobs using sidekiq and it is possible that
sidekiq jobs might be running when deployment is being performed.
Terminating old pod during deployment can kill the already running jobs.</p>
<h3>Solution #1</h3>
<p>As per default
<a href="https://kubernetes.io/docs/concepts/workloads/pods/pod/#termination-of-pods">pod termination</a>
policy of kubernetes, kubernetes sends command to delete pod with a default grace period of 30 seconds.
At this time kubernetes sends TERM signal.
When the grace period expires, any processes still running in the Pod are killed with SIGKILL.</p>
<p>We can adjust the <code>terminationGracePeriodSeconds</code> timeout as per our need and can change it from
30 seconds to 2 minutes.</p>
<p>However there might be cases where we are not
sure how much time a process takes to gracefully shutdown.
In such cases we should consider using
<code>PreStop</code> hook which is our next solution.</p>
<h3>Solution #2</h3>
<p>Kubernetes provides many
<a href="https://kubernetes.io/docs/concepts/containers/container-lifecycle-hooks/">Container lifecycle hooks</a>.</p>
<p><code>PreStop</code> hook is called immediately before a container is terminated.
It is a blocking call. It means it is synchronous.
It also means that this hook must be completed before
the container is terminated.</p>
<p>Note that unlike solution1 this solution is not time bound.
Kubernetes will wait as long as it takes for <code>PreStop</code> process
to finish. It is never a good idea to have a process which takes more
than a minute to shutdown but in real world there are cases
where more time is needed. Use <code>PreStop</code> for such cases.</p>
<p>We decided to use <code>preStop</code> hook to stop Sidekiq because we had some really long running processes.</p>
<h3>Using PreStop hooks in Sidekiq deployment</h3>
<p>This is a simple deployment template which terminates
<a href="https://github.com/mperham/sidekiq/wiki/Signals">Sidekiq process</a>
when pod is terminated during deployment.</p>
<pre><code class="language-yaml">apiVersion: v1
kind: Deployment
metadata:
  name: test-staging-sidekiq
  labels:
    app: test-staging
  namespace: test
spec:
  template:
    metadata:
      labels:
        app: test-staging
    spec:
      containers:
        - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
          name: test-staging
          imagePullPolicy: Always
          env:
            - name: REDIS_HOST
              value: test-staging-redis
            - name: APP_ENV
              value: staging
            - name: CLIENT
              value: test
          volumeMounts:
            - mountPath: /etc/sidekiq/config
              name: test-staging-sidekiq
          ports:
            - containerPort: 80
      volumes:
        - name: test-staging-sidekiq
          configMap:
            name: test-staging-sidekiq
            items:
              - key: config
                path: sidekiq.yml
      imagePullSecrets:
        - name: registrykey
</code></pre>
<p>Next we will use <code>PreStop</code> lifecycle hook to stop
Sidekiq safely before pod termination.</p>
<p>We will add the following block in deployment manifest.</p>
<pre><code class="language-yaml">lifecycle:
  preStop:
    exec:
      command:
        [
          &quot;/bin/bash&quot;,
          &quot;-l&quot;,
          &quot;-c&quot;,
          &quot;cd /opt/myapp/current; for f in tmp/pids/sidekiq*.pid; do bundle exec sidekiqctl stop $f; done&quot;,
        ]
</code></pre>
<p><code>PreStop</code> hook stops all the
Sidekiq processes and does graceful shutdown of Sidekiq
before terminating the pod.</p>
<p>We can add this configuration in original deployment manifest.</p>
<pre><code class="language-yaml">apiVersion: v1
kind: Deployment
metadata:
  name: test-staging-sidekiq
  labels:
    app: test-staging
  namespace: test
spec:
  replicas: 1
  template:
    metadata:
      labels:
        app: test-staging
    spec:
      containers:
        - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
          name: test-staging
          imagePullPolicy: Always
          lifecycle:
            preStop:
              exec:
                command:
                  [
                    &quot;/bin/bash&quot;,
                    &quot;-l&quot;,
                    &quot;-c&quot;,
                    &quot;cd /opt/myapp/current; for f in tmp/pids/sidekiq*.pid; do bundle exec sidekiqctl stop $f; done&quot;,
                  ]
          env:
            - name: REDIS_HOST
              value: test-staging-redis
            - name: APP_ENV
              value: staging
            - name: CLIENT
              value: test
          volumeMounts:
            - mountPath: /etc/sidekiq/config
              name: test-staging-sidekiq
          ports:
            - containerPort: 80
      volumes:
        - name: test-staging-sidekiq
          configMap:
            name: test-staging-sidekiq
            items:
              - key: config
                path: sidekiq.yml

      imagePullSecrets:
        - name: registrykey
</code></pre>
<p>Let's launch this deployment and monitor the rolling deployment.</p>
<pre><code class="language-bash">
$ kubectl apply -f test-deployment.yml
deployment &quot;test-staging-sidekiq&quot; configured

</code></pre>
<p>We can confirm that existing Sidekiq jobs are completed
before termination of old pod during the deployment process.
In this way we handle a graceful shutdown of
Sidekiq process. We can apply this technique to other processes
as well.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Deploy Rails apps on Kubernetes cluster & no downtime]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/deploying-rails-applications-using-kubernetes-with-zero-downtime"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/deploying-rails-applications-using-kubernetes-with-zero-downtime.png"/>
      <id>https://www.bigbinary.com/blog/deploying-rails-applications-using-kubernetes-with-zero-downtime</id>
      <published>2017-07-25T00:00:00.000Z</published>
      <updated>2017-07-25T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/deploying-rails-applications-using-kubernetes-with-zero-downtime.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Deploying Rails applications on Kubernetes cluster with Zero downtime]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/deploying-rails-applications-using-kubernetes-with-zero-downtime"><![CDATA[<p>This post assumes that you have basic understanding of
<a href="http://kubernetes.io/">Kubernetes</a>
terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>
and
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>.</p>
<h3>Problem</h3>
<p>We deploy Rails applications on Kubernetes frequently
and
we need to ensure that
deployments do not cause any downtime.
When we used Capistrano to manage deployments
it was much easier since
it has provision to restart services in the rolling fashion.</p>
<p>Kubernetes restarts pods directly
and
any process already running on the pod is terminated.
So on rolling deployments we face downtime
until the new pod is up and running.</p>
<h3>Solution</h3>
<p>In Kubernetes we have
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-probes/">readiness probes and liveness probes</a>.
Liveness probes take care of keeping pod live
while readiness probe is responsible for keeping pods ready.</p>
<p>This is what Kubernetes documentation has to say about
when to use readiness probes.</p>
<blockquote>
<p>Sometimes, applications are temporarily unable to serve traffic. For example, an application might need to load large data or configuration files during startup. In such cases, you don’t want to kill the application, but you don’t want to send it requests either. Kubernetes provides readiness probes to detect and mitigate these situations. A pod with containers reporting that they are not ready does not receive traffic through Kubernetes Services.</p>
</blockquote>
<p>It means
new traffic should not be routed to
those pods which are currently running but
are not ready yet.</p>
<h3>Using readiness probes in deployment flow</h3>
<p>Here is what we are going to do.</p>
<ul>
<li>We will use readiness probes to deploy our Rails app.</li>
<li>Readiness probes definition has to be specified in pod <code>spec</code> of deployment.</li>
<li>Readiness probe uses health check to detect the pod readiness.</li>
<li>We will create a simple file on our pod with name <code>health_check</code> returning status <code>200</code>.</li>
<li>This health check runs on arbitrary port 81.</li>
<li>We will expose this port in nginx config running on a pod.</li>
<li>When our application is up on nginx this health_check returns <code>200</code>.</li>
<li>We will use above fields to configure health check in pod's spec of deployment.</li>
</ul>
<p>Now let's build test deployment manifest.</p>
<pre><code class="language-yaml">---
apiVersion: v1
kind: Deployment
metadata:
  name: test-staging
  labels:
    app: test-staging
  namespace: test
spec:
  template:
    metadata:
      labels:
        app: test-staging
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-staging
        imagePullPolicy: Always
       env:
        - name: POSTGRES_HOST
          value: test-staging-postgres
        - name: APP_ENV
          value: staging
        - name: CLIENT
          value: test
        ports:
        - containerPort: 80
      imagePullSecrets:
        - name: registrykey

</code></pre>
<p>This is a simple deployment template which will terminate pod on the rolling deployment.
Application may suffer a downtime until the pod is in running state.</p>
<p>Next we will use readiness probe to define that pod is ready to accept the application traffic.
We will add the following block in deployment manifest.</p>
<pre><code class="language-yaml">readinessProbe:
  httpGet:
    path: /health_check
    port: 81
  periodSeconds: 5
  successThreshold: 3
  failureThreshold: 2
</code></pre>
<p>In above rediness probe definition <code>httpGet</code> checks the health check.</p>
<p>Health-check queries application on the file <code>health_check</code> printing <code>200</code> when accessed over port <code>81</code>.
We will poll it for each 5 seconds with the field <code>periodSeconds</code>.</p>
<p>We will mark pod as ready only if we get a successful health_check count for 3 times.
Similarly, we will mark it as a failure if we get failureThreshold twice.
This can be adjusted as per application need.
This helps deployment to determine if the pod is in ready status or not.
With readiness probes for rolling updates, we will use <code>maxUnavailable</code> and <code>maxSurge</code> in deployment strategy.</p>
<p>As per Kubernetes documentation.</p>
<blockquote>
<p><strong><code>maxUnavailable</code></strong> is a field that specifies the maximum number of Pods
that can be unavailable during the update process.
The value can be an absolute number (e.g. 5) or a percentage of desired Pods (e.g. 10%).
The absolute number is calculated from percentage by rounding down.
This can not be 0.</p>
</blockquote>
<p>and</p>
<blockquote>
<p><strong><code>maxSurge</code></strong> is field that specifies
The maximum number of Pods
that can be created above the desired number of Pods.
Value can be an absolute number (e.g. 5) or
a percentage of desired Pods (e.g. 10%).
This cannot be 0 if MaxUnavailable is 0.
The absolute number is calculated from percentage by rounding up.
By default, a value of 25% is used.</p>
</blockquote>
<p>Now we will update our deployment manifests with
two replicas and the rolling update strategy by specifying the following parameters.</p>
<pre><code class="language-yaml">replicas: 2
minReadySeconds: 50
revisionHistoryLimit: 10
strategy:
  type: RollingUpdate
  rollingUpdate:
    maxUnavailable: 50%
    maxSurge: 1
</code></pre>
<p>This makes sure that on deployment one of our pods is always running
and
at most 1 more pod can be created while deployment.</p>
<p>We can read more about rolling-deployments
<a href="https://kubernetes.io/docs/concepts/workloads/controllers/deployment">here</a>.</p>
<p>We can add this configuration in original deployment manifest.</p>
<pre><code class="language-yaml">
apiVersion: v1
kind: Deployment
metadata:
  name: test-staging
  labels:
    app: test-staging
  namespace: test
spec:
  replicas: 2
  minReadySeconds: 50
  revisionHistoryLimit: 10
  strategy:
    type: RollingUpdate
    rollingUpdate:
      maxUnavailable: 50%
      maxSurge: 1
  template:
    metadata:
      labels:
        app: test-staging
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-staging
        imagePullPolicy: Always
       env:
        - name: POSTGREs_HOST
          value: test-staging-postgres
        - name: APP_ENV
          value: staging
        - name: CLIENT
          value: test
        ports:
        - containerPort: 80
        readinessProbe:
          httpGet:
            path: /health_check
            port: 81
          periodSeconds: 5
          successThreshold: 3
          failureThreshold: 2
      imagePullSecrets:
        - name: registrykey

</code></pre>
<p>Let's launch this deployment using the command given below and monitor the rolling deployment.</p>
<pre><code class="language-bash">
$ kubectl apply -f test-deployment.yml
deployment &quot;test-staging-web&quot; configured

</code></pre>
<p>After the deployment is configured we can check the pods and how they are restarted.</p>
<p>We can also access the application to check if we face any down time.</p>
<pre><code class="language-bash">
$ kubectl  get pods
    NAME                                  READY      STATUS  RESTARTS    AGE
test-staging-web-372228001-t85d4           1/1       Running   0          1d
test-staging-web-372424609-1fpqg           0/1       Running   0          50s

</code></pre>
<p>We can see above that only one pod is re-created at the time
and
one of the old pod is serving the application traffic.
Also, new pod is running but not ready as it has not yet passed the readiness probe condition.</p>
<p>After sometime when the new pod is in ready state,
old pod is re-created and traffic is served by the new pod.
In this way, our application does not suffer any down-time and
we can confidently do deployments even at peak hours.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Rails using db:migrate & db:seed on Kubernetes]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/managing-rails-tasks-such-as-db-migrate-and-db-seed-on-kuberenetes-while-performing-rolling-deployments"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/managing-rails-tasks-such-as-db-migrate-and-db-seed-on-kuberenetes-while-performing-rolling-deployments.png"/>
      <id>https://www.bigbinary.com/blog/managing-rails-tasks-such-as-db-migrate-and-db-seed-on-kuberenetes-while-performing-rolling-deployments</id>
      <published>2017-06-16T00:00:00.000Z</published>
      <updated>2017-06-16T00:00:00.000Z</updated>
      <author>
        <name>Vishal Telangre</name>
        <uri>https://www.bigbinary.com/blog/authors/vishaltelangre</uri>
      </author>
      <category term="Kubernetes"/>
      <category term="Rails"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/managing-rails-tasks-such-as-db-migrate-and-db-seed-on-kuberenetes-while-performing-rolling-deployments.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Managing Rails tasks such as 'db:migrate' and 'db:seed' on Kubernetes while performing rolling deployments]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/managing-rails-tasks-such-as-db-migrate-and-db-seed-on-kuberenetes-while-performing-rolling-deployments"><![CDATA[<p>This post assumes that you have basic understanding of
<a href="http://kubernetes.io/">Kubernetes</a> terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a> and
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>.</p>
<h3>Problem</h3>
<p>We want to deploy a Rails application on Kubernetes. We assume that the
<code>assets:precompile</code> task would be run as part of the Docker image build process.</p>
<p>We want to run rake tasks such as <code>db:migrate</code> and <code>db:seed</code> on the initial
deployment, and just <code>db:migrate</code> task on each later deployment.</p>
<p>We cannot run these tasks while building the Docker image as it would not be
able to connect to the database at that moment.</p>
<p>So, how to run these tasks?</p>
<h3>Solution</h3>
<p>We assume that we have a Docker image named <code>myorg/myapp:v0.0.1</code> which contains
the source code for our Rails application.</p>
<p>We also assume that we have included <code>database.yml</code> manifest in this Docker
image with the required configuration needed for connecting to the database.</p>
<p>We need to create a
<a href="https://kubernetes.io/docs/concepts/workloads/controllers/deployment/">Kubernetes deployment</a>
template with the following content.</p>
<pre><code class="language-yaml">apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  name: myapp
spec:
  template:
    spec:
      containers:
        - image: myorg/myapp:v0.0.1
          name: myapp
          imagePullPolicy: IfNotPresent
          env:
            - name: DB_NAME
              value: myapp
            - name: DB_USERNAME
              value: username
            - name: DB_PASSWORD
              value: password
            - name: DB_HOST
              value: 54.10.10.245
          ports:
            - containerPort: 80
      imagePullSecrets:
        - name: docker_pull_secret
</code></pre>
<p>Let's save this template file as <code>myapp-deployment.yml</code>.</p>
<p>We can change the options and environment variables in above template as per our
need. The environment variables specified here will be available to our Rails
application.</p>
<p>To apply above template for the first time on Kubernetes, we will use the
following command.</p>
<pre><code class="language-bash">$ kubectl create -f myapp-deployment.yml
</code></pre>
<p>Later on, to apply the same template after modifications such as change in the
Docker image name or change in the environment variables, we will use the
following command.</p>
<pre><code class="language-bash">$ kubectl apply -f myapp-deployment.yml
</code></pre>
<p>After applying the deployment template, it will create a pod for our application
on Kubernetes.</p>
<p>To see the pods, we use the following command.</p>
<pre><code class="language-bash">$ kubectl get pods
</code></pre>
<p>Let's say that our app is now running in the pod named <code>myapp-4007005961-1st7s</code>.</p>
<p>To execute a rake task, for e.g. <code>db:migrate</code> on this pod, we can run the
following command.</p>
<pre><code class="language-bash">$ kubectl exec myapp-4007005961-1st7s                              \
          -- bash -c                                               \
          'cd ~/myapp &amp;&amp; RAILS_ENV=production bin/rake db:migrate'
</code></pre>
<p>Similarly, we can execute <code>db:seed</code> rake task as well.</p>
<p>If we already have an automated flow for deployments on Kubernetes, we can make
use of this approach to programmatically or conditionally run any rake task as
per the needs.</p>
<h3>Why not to use <a href="https://kubernetes.io/docs/concepts/workloads/controllers/jobs-run-to-completion/">Kubernetes Jobs</a> to solve this?</h3>
<p>We faced some issues while using Kubernetes Jobs to run migration and seed rake
tasks.</p>
<ol>
<li>
<p>If the rake task returns a non-zero exit code, the Kubernetes job keeps
spawning pods until the task command returns a zero exit code.</p>
</li>
<li>
<p>To get around the issue mentioned above we needed to unnecessarily implement
additional custom logic of checking job status and the status of all the
spawned pods.</p>
</li>
<li>
<p>Capturing the command's STDOUT or STDERR was difficult using Kubernetes job.</p>
</li>
<li>
<p>Some housekeeping was needed such as manually terminating the job if it
wasn't successful. If not done, it will fail to create a Kubernetes job with
the same name, which is bound to occur when we perform later deployments.</p>
</li>
</ol>
<p>Because of these issues, we choose not to rely on Kubernetes jobs to solve this
problem.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Kubernetes Configmap with files to deploy Rails apps]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/using-kubernetes-configmap-with-configuration-files-for-deploying-rails-app"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-kubernetes-configmap-with-configuration-files-for-deploying-rails-app.png"/>
      <id>https://www.bigbinary.com/blog/using-kubernetes-configmap-with-configuration-files-for-deploying-rails-app</id>
      <published>2017-05-25T00:00:00.000Z</published>
      <updated>2017-05-25T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-kubernetes-configmap-with-configuration-files-for-deploying-rails-app.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Using Kubernetes Configmap with configuration files for deploying Rails applications]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/using-kubernetes-configmap-with-configuration-files-for-deploying-rails-app"><![CDATA[<p>This post assumes that you have basic understanding of
<a href="http://kubernetes.io/">Kubernetes</a>
terms like
<a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>
and
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a>.</p>
<p>We deploy our Rails applications on Kubernetes and frequently do rolling deployments.</p>
<p>While performing application deployments on kubernetes cluster, sometimes we need to change the application configuration file.
Changing this application configuration file means we
need to change source code, commit the change and then go through the complete deployment process.</p>
<p>This gets cumbersome for simple changes.</p>
<p>Let's take the case of wanting to add queue in sidekiq configuration.</p>
<p>We should be able to change configuration and restart the pod instead of modifying the source-code, creating a new image and then performing a new deployment.</p>
<p>This is where Kubernetes's <a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-pod-configmap/">ConfigMap</a> comes handy.
It allows us to handle configuration files much more efficiently.</p>
<p>Now we will walk you through the process of managing sidekiq configuration file using configmap.</p>
<h2>Starting with configmap</h2>
<p>First we need to create a configmap.
We can either create it using <code>kubectl create configmap</code> command
or
we can use a yaml template.</p>
<p>We will be using yaml template <code>test-configmap.yml</code> which already has sidekiq configuration.</p>
<pre><code class="language-yaml">apiVersion: v1
kind: ConfigMap
metadata:
  name: test-staging-sidekiq
  labels:
    name: test-staging-sidekiq
  namespace: test
data:
  config: |-
    ---
    :verbose: true
    :environment: staging
    :pidfile: tmp/pids/sidekiq.pid
    :logfile: log/sidekiq.log
    :concurrency: 20
    :queues:
      - [default, 1]
    :dynamic: true
    :timeout: 300
</code></pre>
<p>The above template creates configmap in the <code>test</code> namespace and is only accessible in that namespace.</p>
<p>Let's launch this configmap using following command.</p>
<pre><code class="language-bash">
$ kubectl create -f  test-configmap.yml
configmap &quot;test-staging-sidekiq&quot; created

</code></pre>
<p>After that let's use this configmap to create our <code>sidekiq.yml</code> configuration file in deployment template named <code>test-deployment.yml</code>.</p>
<pre><code class="language-yaml">---
apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  name: test-staging
  labels:
    app: test-staging
  namespace: test
spec:
  template:
    metadata:
      labels:
        app: test-staging
    spec:
      containers:
      - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
        name: test-staging
        imagePullPolicy: Always
       env:
        - name: REDIS_HOST
          value: test-staging-redis
        - name: APP_ENV
          value: staging
        - name: CLIENT
          value: test
        volumeMounts:
            - mountPath: /etc/sidekiq/config
              name: test-staging-sidekiq
        ports:
        - containerPort: 80
      volumes:
        - name: test-staging-sidekiq
          configMap:
             name: test-staging-sidekiq
             items:
              - key: config
                path:  sidekiq.yml
      imagePullSecrets:
        - name: registrykey

</code></pre>
<p>Now let's create a deployment using above template.</p>
<pre><code class="language-bash">
$ kubectl create -f  test-deployment.yml
deployment &quot;test-pv&quot; created

</code></pre>
<p>Once the deployment is created, pod running from that deployment will start sidekiq using the <code>sidekiq.yml</code> mounted at <code>/etc/sidekiq/config/sidekiq.yml</code>.</p>
<p>Let's check this on the pod.</p>
<pre><code class="language-bash">
deployer@test-staging-2766611832-jst35:~$ cat /etc/sidekiq/config/sidekiq_1.yml
---
:verbose: true
:environment: staging
:pidfile: tmp/pids/sidekiq_1.pid
:logfile: log/sidekiq_1.log
:concurrency: 20
:timeout: 300
:dynamic: true
:queues:
  - [default, 1]

</code></pre>
<p>Our sidekiq process uses this configuration to start sidekiq.
Looks like configmap did its job.</p>
<p>Further if we want to add one new queue to sidekiq,
we can simply modify the configmap template and restart the pod.</p>
<p>For example if we want to add <code>mailer</code> queue we will modify template as shown below.</p>
<pre><code class="language-yaml">apiVersion: v1
kind: ConfigMap
metadata:
  name: test-staging-sidekiq
  labels:
    name: test-staging-sidekiq
  namespace: test
data:
  config: |-
    ---
    :verbose: true
    :environment: staging
    :pidfile: tmp/pids/sidekiq_1.pid
    :logfile: log/sidekiq_1.log
    :concurrency: 20
    :queues:
      - [default, 1]
      - [mailer, 1]
    :dynamic: true
    :timeout: 300
</code></pre>
<p>Let's launch this configmap using following command.</p>
<pre><code class="language-bash">
$ kubectl apply -f  test-configmap.yml
configmap &quot;test-staging-sidekiq&quot; configured

</code></pre>
<p>Once the pod is restarted, it will use new sidekiq configuration fetched from the configmap.</p>
<p>In this way, we keep our Rails application configuration files out of the source-code and tweak them as needed.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Kubernetes Persistent volume to store persistent data]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/using-kubernetes-persistent-volume-for-persistent-data-storage"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-kubernetes-persistent-volume-for-persistent-data-storage.png"/>
      <id>https://www.bigbinary.com/blog/using-kubernetes-persistent-volume-for-persistent-data-storage</id>
      <published>2017-04-12T00:00:00.000Z</published>
      <updated>2017-04-12T00:00:00.000Z</updated>
      <author>
        <name>Rahul Mahale</name>
        <uri>https://www.bigbinary.com/blog/authors/rahulmahale</uri>
      </author>
      <category term="Kubernetes"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/using-kubernetes-persistent-volume-for-persistent-data-storage.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[This post summarizes how to use the Kubernetes persistent volume in the deployment]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/using-kubernetes-persistent-volume-for-persistent-data-storage"><![CDATA[<p>In one of our projects we are running Rails application on
<a href="http://kubernetes.io/">Kubernetes</a> cluster. It is proven tool for managing and
deploying docker containers in production.</p>
<p>In kubernetes containers are managed using
<a href="http://kubernetes.io/docs/user-guide/deployments/">deployments</a> and they are
termed as <a href="http://kubernetes.io/docs/user-guide/pods/">pods</a>. <code>deployment</code> holds
the specification of pods. It is responsible to run the pod with specified
resources. When <code>pod</code> is restarted or <code>deployment</code> is deleted then data is lost
on pod. We need to retain data out of pods lifecycle when the <code>pod</code> or
<code>deployment</code> is destroyed.</p>
<p>We use docker-compose during development mode. In docker-compose linking between
host directory and container directory works out of the box. We wanted similar
mechanism with Kubernetes to link volumes. In kubernetes we have various types
of <a href="https://kubernetes.io/docs/user-guide/volumes/#types-of-volumes1">volumes</a>
to use. We chose
<a href="http://kubernetes.io/docs/user-guide/persistent-volumes/">persistent volume</a>
with <a href="https://aws.amazon.com/ebs/">AWS EBS</a> storage. We used persistent volume
claim as per the need of application.</p>
<p>As per the
<a href="http://kubernetes.io/docs/user-guide/persistent-volumes/">Persistent Volume's definition</a>
(PV) Cluster administrators must first create storage in order for Kubernetes to
mount it.</p>
<p>Our Kubernetes cluster is hosted on AWS. We created AWS EBS volumes which can be
used to create persistent volume.</p>
<p>Let's create a sample volume using aws cli and try to use it in the deployment.</p>
<pre><code class="language-bash">
aws ec2 create-volume --availability-zone us-east-1a --size 20 --volume-type gp2

</code></pre>
<p>This will create a volume in <code>us-east-1a</code> region. We need to note <code>VolumeId</code>
once the volume is created.</p>
<pre><code class="language-bash">
$ aws ec2 create-volume --availability-zone us-east-1a --size 20 --volume-type gp2
{
    &quot;AvailabilityZone&quot;: &quot;us-east-1a&quot;,
    &quot;Encrypted&quot;: false,
    &quot;VolumeType&quot;: &quot;gp2&quot;,
    &quot;VolumeId&quot;: &quot;vol-123456we7890ilk12&quot;,
    &quot;State&quot;: &quot;creating&quot;,
    &quot;Iops&quot;: 100,
    &quot;SnapshotId&quot;: &quot;&quot;,
    &quot;CreateTime&quot;: &quot;2017-01-04T03:53:00.298Z&quot;,
    &quot;Size&quot;: 20
}


</code></pre>
<p>Now let's create a persistent volume template <code>test-pv</code> to create volume using
this EBS storage.</p>
<pre><code class="language-yaml">kind: PersistentVolume
apiVersion: v1
metadata:
  name: test-pv
  labels:
    type: amazonEBS
spec:
  capacity:
    storage: 10Gi
  accessModes:
    - ReadWriteMany
  awsElasticBlockStore:
    volumeID: &lt;your-volume-id&gt;
    fsType: ext4
</code></pre>
<p>Once we had template to create persistent volume, we used
<a href="http://kubernetes.io/docs/user-guide/kubectl/">kubectl</a> to launch it. Kubectl
is command line tool to interact with Kubernetes cluster.</p>
<pre><code class="language-bash">
$ kubectl create -f  test-pv.yml
persistentvolume &quot;test-pv&quot; created

</code></pre>
<p>Once persistent volume is created you can check using following command.</p>
<pre><code class="language-bash">
$ kubectl get pv
NAME       CAPACITY   ACCESSMODES   RECLAIMPOLICY   STATUS      CLAIM               REASON    AGE
test-pv     10Gi        RWX           Retain          Available                                7s

</code></pre>
<p>Now that our persistent volume is in available state, we can claim it by
creating
<a href="http://kubernetes.io/docs/user-guide/persistent-volumes/#persistentvolumeclaims">persistent volume claim policy</a>.</p>
<p>We can define persistent volume claim using following template <code>test-pvc.yml</code>.</p>
<pre><code class="language-yaml">kind: PersistentVolumeClaim
apiVersion: v1
metadata:
  name: test-pvc
  labels:
    type: amazonEBS
spec:
  accessModes:
    - ReadWriteMany
  resources:
    requests:
      storage: 10Gi
</code></pre>
<p>Let's create persistent volume claim using above template.</p>
<pre><code class="language-bash">$ kubectl create -f  test-pvc.yml

persistentvolumeclaim &quot;test-pvc&quot; created

</code></pre>
<p>After creating the persistent volume claim, our persistent volume will change
from <code>available</code> state to <code>bound</code> state.</p>
<pre><code class="language-bash">
$ kubectl get pv
NAME       CAPACITY   ACCESSMODES   RECLAIMPOLICY   STATUS     CLAIM               REASON    AGE
test-pv    10Gi        RWX           Retain          Bound      default/test-pvc              2m

$kubectl get pvc
NAME        STATUS    VOLUME    CAPACITY   ACCESSMODES   AGE
test-pvc    Bound     test-pv   10Gi        RWX           1m

</code></pre>
<p>Now we have persistent volume claim available on our Kubernetes cluster, Let's
use it in deployment.</p>
<h3>Deploying Kubernetes application</h3>
<p>We will use following deployment template as <code>test-pv-deployment.yml</code>.</p>
<pre><code class="language-yaml">apiVersion: extensions/v1beta1
kind: Deployment
metadata:
  name: test-pv
  labels:
    app: test-pv
spec:
  replicas: 1
  template:
    metadata:
      labels:
        app: test-pv
        tier: frontend
    spec:
      containers:
        - image: &lt;your-repo&gt;/&lt;your-image-name&gt;:latest
          name: test-pv
          imagePullPolicy: Always
          env:
            - name: APP_ENV
              value: staging
            - name: UNICORN_WORKER_PROCESSES
              value: &quot;2&quot;
          volumeMounts:
            - name: test-volume
              mountPath: &quot;/&lt;path-to-my-app&gt;/shared/data&quot;
          ports:
            - containerPort: 80
      imagePullSecrets:
        - name: registrypullsecret
      volumes:
        - name: test-volume
          persistentVolumeClaim:
            claimName: test-pvc
</code></pre>
<p>Now launch the deployment using following command.</p>
<pre><code class="language-bash">
$ kubectl create -f  test-pvc.yml
deployment &quot;test-pv&quot; created

</code></pre>
<p>Once the deployment is up and running all the contents on <code>shared</code> directory
will be stored on persistent volume claim. Further when pod or deployment
crashes for any reason our data will be always retained on the persistent
volume. We can use it to launch the application deployment.</p>
<p>This solved our goal of retaining data across deployments across <code>pod</code> restarts.</p>
]]></content>
    </entry>
</feed>