<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom" xmlns:media="http://search.yahoo.com/mrss/" xml:lang="en-US">
  <title>BigBinary Blog: Misc</title>
  <subtitle>Deep technical writing on Ruby on Rails, performance, scaling, monitoring and engineering.</subtitle>
  <link rel="self" type="application/atom+xml" href="https://www.bigbinary.com/blog/categories/misc/feed.xml"/>
  <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/categories/misc"/>
  <id>https://www.bigbinary.com/blog/categories/misc</id>
  <updated>2024-10-15T00:00:00.000Z</updated>
  <author>
    <name>BigBinary</name>
    <uri>https://www.bigbinary.com/</uri>
  </author>
  <icon>https://www.bigbinary.com/favicon.ico</icon>
  <logo>https://www.bigbinary.com/images/bigbinary_square_big_logo.png</logo>
  <rights>Copyright 2024 Big Binary LLC</rights>
  <generator uri="https://nextjs.org">Next.js</generator>
  <entry>
      <title type="text"><![CDATA[Benchmarking Crunchy Data for latency]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/crunchy-bridge-vs-digital-ocean"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/benchmarking_crunchy_data_for_latency.jpg"/>
      <id>https://www.bigbinary.com/blog/crunchy-bridge-vs-digital-ocean</id>
      <published>2024-10-15T00:00:00.000Z</published>
      <updated>2024-10-15T00:00:00.000Z</updated>
      <author>
        <name>Vishnu M</name>
        <uri>https://www.bigbinary.com/blog/authors/vishnu-m</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/benchmarking_crunchy_data_for_latency.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[In Rails World 2024, DHH unveiled Kamal 2 in his opening keynote. Now, folks want to give Kamal a try, but some people are worried about the data. They want to take one step at a time, and they feel...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/crunchy-bridge-vs-digital-ocean"><![CDATA[<p>In Rails World 2024, DHH unveiled <a href="https://kamal-deploy.org/">Kamal 2</a> in his
<a href="https://www.youtube.com/watch?v=-cEn_83zRFw">opening keynote</a>. Now, folks want
to give Kamal a try, but some people are worried about the data. They want to
take one step at a time, and they feel more comfortable if their database is
managed by someone else.</p>
<p>That's where <a href="https://www.crunchydata.com/">Crunchy Data</a> comes in. They provide
managed Postgres service. Checkout this
<a href="https://x.com/dhh/status/1840901376182009900">tweet</a> from DHH about Crunchy
Data.</p>
<p>In our internal discussion, one of the BigBinary engineers brought up the issue
of &quot;latency&quot;. Since the PostgreSQL server will not be in the same data center,
what would be the latency? How much impact will it have on performance?</p>
<p>We didn't know the answer so we thought we would do some benchmarking.</p>
<h2>Benchmarking</h2>
<p>To do the comparison we needed another hosting provider where we can run
PostgreSQL on the same data center. We chose to work with Digital Ocean.</p>
<p>To compare the two services, we wrote a benchmark script in Ruby similar to the
one <a href="https://x.com/benbjohnson">Ben Johnson</a> wrote in
<a href="https://github.com/benbjohnson/production-sqlite-go/blob/main/postgres-tests/postgres_test.go">Go</a>
for his <a href="https://youtu.be/XcAYkriuQ1o?si=vz-sYjevztb_bnwL">GopherCon talk</a>
in 2021.</p>
<p>In this benchmark, we're using Ruby's Benchmark module to measure the
performance of a series of database operations. Here's what the code does:</p>
<ol>
<li>
<p>It establishes a connection to the database only once, at the beginning of
the script. This is done outside the benchmarked operations because
establishing connections can be a slow operation because of TLS negotiation,
and we don't want to account for that time in our measurements.</p>
</li>
<li>
<p>It then performs the following operations 10,000 times, measuring each one:</p>
<ul>
<li>Drops a table named 't' if it exists.</li>
<li>Creates a new table 't' with two columns: 'id' (an auto-incrementing
primary key) and 'name' (a text field).</li>
<li>Inserts a single row into the table with the name 'jane'.</li>
<li>Selects the 'name' from the table where the 'id' is 1 (which should be
'jane').</li>
</ul>
</li>
<li>
<p>After all 10,000 iterations, it calculates and prints the average time for
each operation in microseconds.</p>
</li>
</ol>
<pre><code class="language-ruby">require &quot;pg&quot;
require &quot;benchmark&quot;

class PostgresBenchmark
  def initialize(connection_string)
    @conn = PG.connect(connection_string)
  end

  def run(iterations = 10_000)
    total_times = Hash.new { |h, k| h[k] = 0 }

    iterations.times do |i|
      puts &quot;Running iteration #{i + 1}&quot; if (i + 1) % 1000 == 0
      times = benchmark_operations
      times.each { |key, time| total_times[key] += time }
    end

    average_times = total_times.transform_values { |time| time / iterations }
    print_results(average_times, iterations)
  ensure
    @conn.close if @conn
  end

  private

  def benchmark_operations
    times = {}

    times[:drop] = Benchmark.measure { @conn.exec(&quot;DROP TABLE IF EXISTS t&quot;) }.real
    times[:create] = Benchmark.measure { @conn.exec(&quot;CREATE TABLE t (id SERIAL PRIMARY KEY, name TEXT)&quot;) }.real
    times[:insert] = Benchmark.measure { @conn.exec(&quot;INSERT INTO t (name) VALUES ('jane')&quot;) }.real
    times[:select] = Benchmark.measure do
      result = @conn.exec(&quot;SELECT name FROM t WHERE id = 1&quot;)
      raise &quot;Unexpected result&quot; unless result[0][&quot;name&quot;] == &quot;jane&quot;
    end.real

    times
  end

  def print_results(times, iterations)
    total_time = times.values.sum

    puts &quot;\nAVERAGE ELAPSED TIME (over #{iterations} iterations)&quot;
    puts &quot;drop    #{(times[:drop] * 1_000_000).round(2)} microseconds&quot;
    puts &quot;create  #{(times[:create] * 1_000_000).round(2)} microseconds&quot;
    puts &quot;insert  #{(times[:insert] * 1_000_000).round(2)} microseconds&quot;
    puts &quot;select  #{(times[:select] * 1_000_000).round(2)} microseconds&quot;
    puts &quot;TOTAL   #{(total_time * 1_000_000).round(2)} microseconds&quot;
  end
end

if __FILE__ == $0
  connection_string = &quot;&lt;DB_CONNECTION_STRING&gt;&quot;
  benchmark = PostgresBenchmark.new(connection_string)
  benchmark.run(10_000)
end
</code></pre>
<h2>Database Specifications and Setup</h2>
<h3>Digital Ocean</h3>
<ul>
<li>Region: NYC3 data center</li>
<li>Specs: 2 vCPU, 4GB Memory</li>
<li>Price: $60 per month</li>
</ul>
<h3>Crunchy Data</h3>
<ul>
<li>Provider: AWS</li>
<li>Region: us-east-1</li>
<li>Specs: 2 vCPU, 4GB Memory (hobby-4 plan)</li>
<li>Price: $70 per month</li>
</ul>
<p>We provisioned a Digital Ocean droplet in the NYC3 data center and invoked the
benchmark script from the machine. The Digital Ocean database was also in the
same NYC3 data center. For Crunchy Data, the availability zone selected was
<code>us-east-1</code> as it was the closest to NYC3.</p>
<h2>Benchmarking results</h2>
<h3>Digital Ocean</h3>
<pre><code class="language-js">AVERAGE ELAPSED TIME (over 10000 iterations)
drop    3448.07 microseconds
create  5048.39 microseconds
insert  891.81 microseconds
select  584.17 microseconds
TOTAL   9972.44 microseconds
</code></pre>
<h3>Crunchy Data</h3>
<pre><code class="language-js">AVERAGE ELAPSED TIME (over 10000 iterations)
drop    10097.89 microseconds
create  16818.63 microseconds
insert  8416.35 microseconds
select  7211.42 microseconds
TOTAL   42544.29 microseconds
</code></pre>
<h2>Benchmarking analysis</h2>
<p>The results of this benchmark do not come as a surprise. Digital Ocean is
performing significantly better than Crunchy Data. This performance difference
can be primarily attributed to network latency.</p>
<p><em>Network latency</em> refers to the round-trip time (RTT) it takes for the data to
travel from its source to its destination and back again across a network. In
the context of database operations, it's the time taken for a query to be sent
from the client to the database server and for the response to return to the
client.</p>
<p>In our benchmarking, the Digital Ocean database and the client machine invoking
the script were both located in the same data center (NYC3), resulting in
minimal network latency. On the other hand, the Crunchy Data database was hosted
in AWS <code>us-east-1</code>, and it had to communicate across a greater physical
distance, adding to latency.</p>
<p>To get a more accurate value for the network latency, we can compare the average
time taken to run the <code>SELECT</code> operation. The <code>SELECT</code> operation in the script
is a point query. <em>A point query refers to type of query that retrieves one or
several rows based on a unique key</em>.</p>
<p>In our script, it retrieves a single <code>name</code> value from the table <code>t</code> where the
<code>id</code> is <code>1</code>(which is the primary key), and is very fast to execute. Thus, the
time taken to execute the <code>SELECT</code> operation can give us an approximate value
for the network latency.</p>
<pre><code>db_time = network_latency + query_execution_time
</code></pre>
<p>For point queries, the <code>query_execution_time</code> is almost zero so all the time
taken is pretty much &quot;network latency&quot;.</p>
<pre><code>db_time ≈ network_latency
</code></pre>
<p>If we look at the benchmarking result, then we can see that for &quot;select&quot;
operation time taken by Digital Ocean is &quot;584 microseconds&quot; and for Crunchy Data
it is &quot;7211 microseconds&quot;.</p>
<p>The difference in network latency is <em>6627 microseconds</em>. That is 6.6
milliseconds.</p>
<p>This value over multiple queries can add up and can have a significant impact on
the overall response time of your application. To put this into perspective, for
a web application that makes 10 sequential database queries to render a page,
this could add up to about <em>66 milliseconds</em> to the page load time. Now, this
could be an acceptable limit if your page loads in 3/4 seconds. However,
if you are trying to load your page in 200 millisecond,s then you need to watch
out.</p>
<p>Ensuring that the database is always up and it's properly backed up is a non-trivial
problem. Latency notwithstanding, Crunchy Data takes care of running the database.
This gives us peace of mind and allows us to exit the cloud one step at a time.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Improving NeetoRecord reach with Twitter player cards]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/adding-twitter-player-cards-to-neetorecord"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/using_twitter_player_cards_to_improve_accessibility_of_neetorecord.jpg"/>
      <id>https://www.bigbinary.com/blog/adding-twitter-player-cards-to-neetorecord</id>
      <published>2024-08-16T00:00:00.000Z</published>
      <updated>2024-08-16T00:00:00.000Z</updated>
      <author>
        <name>Bonnie Simon</name>
        <uri>https://www.bigbinary.com/blog/authors/bonniesimon</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/using_twitter_player_cards_to_improve_accessibility_of_neetorecord.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Using Twitter player cards to improve accessibility of NeetoRecord]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/adding-twitter-player-cards-to-neetorecord"><![CDATA[<p>At Neeto, we're building multiple products, and we love sharing our progress and
updates on Twitter. We often accompany our tweets with NeetoRecord recordings to
give you an even closer look at our work. However, we noticed that users had to
leave Twitter to view our videos, creating unnecessary friction in their
experience.</p>
<h4>The Problem</h4>
<p>Initially, when we shared a NeetoRecord video on Twitter, this is how the tweet
would appear.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/adding-twitter-player-cards-to-neetorecord/no-embed.png" alt="Link with no embed"></p>
<p>As we can see, the links are just plain text, lacking visual appeal and context.
Users had to click away from Twitter and open a new tab to view the recording.
This extra step not only disrupted the user's Twitter experience but also likely
reduced the number of people who actually watched our videos.</p>
<h4>The Solution: Twitter Cards</h4>
<p>To address this issue, we turned to Twitter Cards. Similar to Facebook's Open
Graph protocol, Twitter Cards allows us to showcase interactive media directly
within tweets. While both protocols serve similar purposes, Twitter cards are
designed to directly work in Twitter, so its crawler will look for these tags
and only look for OG tags as a fallback.</p>
<h4>What are Twitter Cards?</h4>
<p>Twitter Cards are a set of meta tags that enable us to embed interactive content
on a tweet. In our case, we want to provide users an embedded video player which
they can use to view the NeetoRecord recording without leaving Twitter. It's not
just about aesthetics. According to Twitter's own data, &quot;tweets with cards have
43% higher engagement rates than regular tweets with links.&quot; This statistic
underscores the impact of providing a seamless, visually appealing experience.</p>
<h4>Implementing Twitter Cards for NeetoRecord</h4>
<p>There are multiple types of cards that we can leverage to enhance our content
such as summary cards, player cards &amp; app cards. However, in this post, we are
going to be discussing about Player cards, which is implemented in NeetoRecord.
This card type allows us to embed an interactive video player directly in the
tweet. Here's how it looks:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/adding-twitter-player-cards-to-neetorecord/player-embed.png" alt="Embed player"></p>
<p>Clicking on this link preview will open our embedded content, in this case, a
player to view the recording directly within Twitter.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/adding-twitter-player-cards-to-neetorecord/player-embed-expanded.png" alt="Expanded player"></p>
<p>As we can see, users can now watch our NeetoRecord videos without leaving
Twitter. This seamless experience has several benefits:</p>
<ul>
<li>Higher Engagement: With the video right there in the tweet, more users are
likely to watch it.</li>
<li>Reduced Friction: No more clicking away or opening new tabs, keeping users
engaged with our content and the Twitter conversation.</li>
<li>Better Branding: The Player Card includes our logo and video title,
reinforcing our brand with every view.</li>
</ul>
<h4>Technical Implementation</h4>
<p>Implementing Twitter Cards is straightforward. We added meta tags to the
<code>&lt;head&gt;</code> section of our web page. For our Player Card, we use tags as shown
below.</p>
<pre><code class="language-html">&lt;meta property=&quot;twitter:card&quot; content=&quot;player&quot; /&gt;
&lt;meta
  property=&quot;twitter:url&quot;
  content=&quot;https://oli.neetorecord.com/watch/864de7fb-2efb-4f2f-a60b-08dca64e4c3&quot;
/&gt;
&lt;meta
  property=&quot;twitter:title&quot;
  content=&quot;Introducing the new video player for NeetoRecord&quot;
/&gt;
&lt;meta property=&quot;twitter:site&quot; content=&quot;@NeetoRecord&quot; /&gt;
&lt;meta property=&quot;twitter:image&quot; content=&quot;https://cdn.neeto.com/hycoe7&quot; /&gt;
&lt;meta
  property=&quot;twitter:player&quot;
  content=&quot;https://oli.neetorecord.com/embeds/864de7fb-2efb-4f2f-a60b-08dca64e4c3&quot;
/&gt;
&lt;meta property=&quot;twitter:player:width&quot; content=&quot;1280&quot; /&gt;
&lt;meta property=&quot;twitter:player:height&quot; content=&quot;720&quot; /&gt;
</code></pre>
<p>These tags tell Twitter's crawler what to display in the card.</p>
<p>Let's break down the purpose and importance of each meta tag:</p>
<pre><code class="language-html">&lt;meta property=&quot;twitter:card&quot; content=&quot;player&quot; /&gt;
</code></pre>
<p>This tag specifies the card type. Setting it to &quot;player&quot; tells Twitter that this
is a Player Card, which is designed for video or audio content.</p>
<pre><code class="language-html">&lt;meta
  property=&quot;twitter:url&quot;
  content=&quot;https://oli.neetorecord.com/watch/864de7fb-2efb-4f2f-a60b-08dca64e4c3&quot;
/&gt;
</code></pre>
<p>This tag provides the URL of the web page that the card is describing. It should
be the page where users can view the full content.</p>
<pre><code class="language-html">&lt;meta
  property=&quot;twitter:title&quot;
  content=&quot;Introducing the new video player for NeetoRecord&quot;
/&gt;
</code></pre>
<p>This tag sets the title of the card, which appears as the main headline.</p>
<pre><code class="language-html">&lt;meta property=&quot;twitter:site&quot; content=&quot;@NeetoRecord&quot; /&gt;
</code></pre>
<p>This tag specifies the Twitter @username the card should be attributed to.</p>
<pre><code class="language-html">&lt;meta property=&quot;twitter:image&quot; content=&quot;https://cdn.neeto.com/hycoe7&quot; /&gt;
</code></pre>
<p>This tag provides the image to be displayed in place of the player on platforms
that don’t support iFrames or inline players.</p>
<pre><code class="language-html">&lt;meta
  property=&quot;twitter:player&quot;
  content=&quot;https://oli.neetorecord.com/embeds/864de7fb-2efb-4f2f-a60b-08dca64e4c3&quot;
/&gt;
</code></pre>
<p>This crucial tag specifies the URL of the video player. This should be an HTTPS
URL to an iframe player that can play the content.</p>
<pre><code class="language-html">&lt;meta property=&quot;twitter:player:width&quot; content=&quot;1280&quot; /&gt;
&lt;meta property=&quot;twitter:player:height&quot; content=&quot;720&quot; /&gt;
</code></pre>
<p>These two tags define the width and height of the video player iframe, in
pixels. They help ensure the video displays correctly in the Twitter feed.</p>
<h4>Conclusion</h4>
<p>Twitter Cards have improved how NeetoRecord videos are shared on Twitter. The
embedded media experience reduces friction and increases engagement, while
enhancing our brand visibility.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Honeybadger frontend integration in Neeto apps]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/honeybadger-frontend-integration-in-neeto-apps"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/honeybadger_frontend_integration_neeto_apps.jpg"/>
      <id>https://www.bigbinary.com/blog/honeybadger-frontend-integration-in-neeto-apps</id>
      <published>2023-12-12T00:00:00.000Z</published>
      <updated>2023-12-12T00:00:00.000Z</updated>
      <author>
        <name>Calvin Chiramal</name>
        <uri>https://www.bigbinary.com/blog/authors/calvinchiramal</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/honeybadger_frontend_integration_neeto_apps.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Honeybadger frontend integration in web apps]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/honeybadger-frontend-integration-in-neeto-apps"><![CDATA[<p>At Neeto, we integrated Honeybadger to track all errors in our applications at
runtime. We also integrated Honeybadger with GitHub to automatically raise
issues in the respective repositories when errors are caught. This blog is an
in-depth guide on how we integrated Honeybadger on the frontend part of our web
apps.</p>
<p>For our apps deployed on Heroku, we used the following command to get the latest
commit hash as an environment variable in the Heroku server on each build:</p>
<pre><code class="language-bash">heroku labs:enable runtime-dyno-metadata -a your-app-name
</code></pre>
<p>With NeetoDeploy, we <a href="https://youtu.be/r4g-a6k5SYY?t=176">didn't need this step</a>
since git is available in the console and we used git commands to set the latest
commit hash as the Honeybadger revision. Honeybadger uses the
<a href="https://docs.honeybadger.io/lib/javascript/guides/using-source-maps/#versioning-your-project">revision</a>
to associate maps with the bundle when the bundle name doesn't change.</p>
<p>Steps to integrate Honeybadger:</p>
<ol>
<li>
<p>Create a new project in the Honeybadger dashboard. We've made a
<a href="https://youtu.be/h5svJ15Vg5Q">video</a> on setting it up following the
<a href="https://docs.honeybadger.io/lib/javascript/integration/react/">React integration guide</a>.</p>
</li>
<li>
<p>Set the environment variable <code>HONEYBADGER_JS_API_KEY</code> with the Honeybadger
project's API key. The API key can be copied from <code>Settings =&gt; API Keys</code>.</p>
</li>
</ol>
<p>In depth guides for Honeybadger integration &amp; sourcemap upload:</p>
<ul>
<li><a href="https://youtu.be/h5svJ15Vg5Q">What is honeybadger</a></li>
<li><a href="https://youtu.be/vtIk6g-NekA">Honeybadger integration basics</a></li>
<li><a href="https://youtu.be/yRrKBnN00Yc">Honeybadger integration in the Neeto ecosystem</a></li>
<li><a href="https://youtu.be/qZD9pus_9ro">Sourcemaps explained</a></li>
<li><a href="https://youtu.be/r4g-a6k5SYY">Uploading sourcemap to honeybadger</a></li>
<li><a href="https://youtu.be/tmnxx7HZ5bw">Sourcemaps in action within Honeybadger errors</a></li>
<li><a href="https://youtu.be/AZZWDMRuuY8">Handling CDN based application bundles</a></li>
</ul>
<p>We've created a YouTube
<a href="https://www.youtube.com/playlist?list=PLRpdquznQk7E6UPRx7yyAAJrPYwxXqPS4">playlist</a>
of the above videos for easy access.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Deep Dive into Redis Data Types]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/redis-data-types-deep-dive"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/deep_dive_into_redis_data_types.jpg"/>
      <id>https://www.bigbinary.com/blog/redis-data-types-deep-dive</id>
      <published>2023-11-14T00:00:00.000Z</published>
      <updated>2023-11-14T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/deep_dive_into_redis_data_types.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Last week, while migrating NeetoGit's production deployment to NeetoDeploy, we faced a challenge. The Redis 7 add-on only had a TLS URL in Heroku. We were not able to get the dump in a...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/redis-data-types-deep-dive"><![CDATA[<p>Last week, while migrating <a href="https://www.neeto.com/neetogit">NeetoGit's</a>
production deployment to <a href="https://www.neeto.com/neetodeploy">NeetoDeploy</a>, we
faced a challenge. The Redis 7 add-on only had a TLS URL in Heroku. We were not
able to get the dump in a straightforward manner using redis-cli, since we
didn't have access to the certificates for making a TLS connection. We were able
to connect to the add-on, so we decided to write a script to manually copy all
the keys and values over to the Redis add-on in NeetoDeploy.</p>
<p>While writing the program, we realized that we'd need a switch-case that checked
what data type each key was. We had to search for the get and set methods for
each data type manually while writing the program. Late,r we used the redis-rb
gem and was able to get the dump with <code>OpenSSL::SSL::VERIFY_NONE</code>, but we had
still faced the issue of having to look up what the command was for different
data types like zset and hash.</p>
<p>I thought this could be a good opportunity to write a blog post summarizing all
the data types and the commands associated with them. The Redis documentation
has a page about the different data types, but all the commands are not
available at a single place.</p>
<h2>Redis key-value database</h2>
<p>When we say that Redis is a key-value database, there is more to it than what
meets the eye. Redis keys can store values of several different data types.
Redis has a set of commands for each of these different data types to do
operations with them. In this post, we’ll go over the different data types, what
they are and how we can work with them.</p>
<h3>What are the different data types?</h3>
<p>Redis has more than a couple of data types, which can be used to store different
data based on your needs. These include the following:</p>
<ul>
<li><code>String</code> - The basic data type we are all familiar with.</li>
<li><code>List</code> - An array of strings.</li>
<li><code>Hash</code> - A collection of key-value pairs, similar to a Ruby <code>Hash</code>.</li>
<li><code>Set</code> - A collection of unique strings.</li>
<li><code>Sorted Set</code> - A collection of unique strings maintaining by each string’s
score.</li>
<li><code>HyperLogLog</code> - Probabilistic estimates of cardinality of large sets.</li>
<li><code>Stream</code> - An append only log.</li>
<li><code>Geospatial Index</code> - Data structure for storing geographic coordinates.</li>
</ul>
<h3>Checking data type of your keys</h3>
<p>You can use the <code>TYPE</code> command to check what data type your key is. Once you
know what type your key is, you can use the commands associated with your key's
data type to interact with it.</p>
<pre><code>127.0.0.1:6379&gt; TYPE schedule
zset
</code></pre>
<h3>Cheatsheet for Redis commands based on data type</h3>
<p>Each Redis data type has its own set of commands for doing operations with the
key and its value. Here's a quick overview of the basic data types you would
encounter and some of the basic commands to set, retrieve and delete data from
them.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/redis-data-types-deep-dive/redis-commands-based-on-data-types.png" alt="A list of Redis commands for doing operations with each data type."></p>
<p>Read more about the different data types in Redis and all the different commands
that are available in their
<a href="https://redis.io/docs/data-types/">official documentation</a>.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Profiling your zsh setup with zprof]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/zsh-profiling"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/profiling_your_zsh_setup_with_zprof.jpg"/>
      <id>https://www.bigbinary.com/blog/zsh-profiling</id>
      <published>2023-10-12T00:00:00.000Z</published>
      <updated>2023-10-12T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/profiling_your_zsh_setup_with_zprof.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[While using frameworks like oh-my-zsh to upgrade your shell, it is pretty easy to get carried away with all the available plugins. This can eventually take a toll on your shell’s performance. One...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/zsh-profiling"><![CDATA[<p>While using frameworks like <a href="https://ohmyz.sh/">oh-my-zsh</a> to upgrade your
shell, it is pretty easy to get carried away with all the available plugins.
This can eventually take a toll on your shell’s performance. One significant way
it can affect your workflow is by slowing everything down. The more items you
add to your <code>.zshrc</code> file, the more time your shell will need to start up.
Profiling your shell is a good start to figuring out what is slowing it down.</p>
<h3>zprof</h3>
<p><a href="https://zsh.sourceforge.io/Doc/Release/Zsh-Modules.html#The-zsh_002fzprof-Module">zprof</a>
is a utility that comes packaged with zsh, which you can use to profile your zsh
script.</p>
<p>Add the following to the top of your <code>.zshrc</code> file to load zprof.</p>
<pre><code class="language-bash">zmodload zsh/zprof
</code></pre>
<p>At the bottom of your <code>.zshrc</code>, add the following.</p>
<pre><code class="language-bash">zprof
</code></pre>
<p>This would profile your zsh script and print a summary of all the commands run
during your shell startup and the time it takes to execute them. Run <code>exec zsh</code>
to apply the changes and restart your shell. Your shell will print something
like this:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/zsh-profiling/zprof-output.webp" alt="Output of the zprof command"></p>
<p>With this you can see which commands are taking the most time to load. Enabling
profiling has helped pinpoint the issue and now you can look into fixing it. In
the above example, you can see that nvm is taking up a considerable amount of
time.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Domain redirects with different crawl rules via Cloudflare]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/domain-redirection-using-cloudflare"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/handling_domain_redirection_using_cloudflare.jpg"/>
      <id>https://www.bigbinary.com/blog/domain-redirection-using-cloudflare</id>
      <published>2023-08-31T00:00:00.000Z</published>
      <updated>2023-08-31T00:00:00.000Z</updated>
      <author>
        <name>Ghouse Mohamed</name>
        <uri>https://www.bigbinary.com/blog/authors/ghousemohamed</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/handling_domain_redirection_using_cloudflare.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Handling domain redirection while maintaining different google crawl attributes using Cloudflare]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/domain-redirection-using-cloudflare"><![CDATA[<p><a href="https://neeto.com">neeto</a> is a collection of different software. Each neeto
product gets its own page. For example, NeetoCal gets the URL
https://www.neeto.com/neetocal.</p>
<p>When it comes to actually using these products, you will be redirected to
<code>https://subdomain.neetocal.com</code>. Here, &quot;subdomain&quot; would be the subdomain
allocated to you when you signed up for Neeto.</p>
<p>We planned to add &quot;Google sign in&quot; feature to make it easier for folks to
both signup and to log in. During testing, it all worked fine. However, when we
asked &quot;Google&quot; to approve the app &quot;NeetoCal&quot; for &quot;Google sign in&quot; Google
demanded that our users should be able to see the &quot;Privacy Policy&quot; and &quot;Terms of
conditions&quot; on the website. In order to make Google happy, we added a redirection
from &quot;neetocal.com&quot; to &quot;neeto.com/neetocal&quot;.</p>
<p>However, Google was not happy with it. The users are logging into
<code>https://subdomain.neetocal.com</code> so the &quot;privacy policy&quot; and &quot;terms of service&quot;
should be visible on the domain &quot;neetocal.com&quot; itself.</p>
<p>We are using Cloudflare as our DNS provider. Using the tools provided to us by
Cloudflare we decided to show the content of &quot;neeto.com/neetocal&quot; on
&quot;neetocal.com&quot; without redirecting the user.</p>
<p>Note that in this case, if you type &quot;neetocal.com&quot;, then you will see the URL
change to &quot;neetocal.com/neetocal&quot; instantly. That's because the URL of the main
marketing site is &quot;neeto.com/neetocal&quot;.</p>
<p>Cloudflare provides
<a href="https://developers.Cloudflare.com/support/page-rules/understanding-and-configuring-Cloudflare-page-rules-page-rules-tutorial/">Page rules</a>
which we will be using to achieve our goals. Below is a video of how it was done.</p>
<p><a href="https://www.youtube.com/watch?v=RodZIBxYBHc"><img src="https://img.youtube.com/vi/RodZIBxYBHc/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=RodZIBxYBHc">Watch on YouTube</a></p>
<h2>SEO duplicate content issue</h2>
<p>The Google search engine doesn't like it when we show exactly the same content
on two different domains. Google thinks that the site is trying to cheat Google
and Google will punish both sites.</p>
<p>We want Google to index our main marketing site https://neeto.com/neetocal and
we want Google to ignore &quot;neetocal.com&quot;. One way to tell Google not index the
site is by adding a <code>noindex</code>
<a href="https://developers.google.com/search/docs/crawling-indexing/robots-meta-tag#noindex">meta tag</a>.</p>
<pre><code>&lt;meta name=&quot;robots&quot; content=&quot;noindex&quot;&gt;
</code></pre>
<p>In the above example, we are asking all bots not to index the page containing
the above meta tag.</p>
<p>We planned to inject this meta tag when a page is rendered for the URL
&quot;neetocal.com&quot; and we will not inject this tag when the page is rendered for the URL
&quot;neeto.com&quot;.</p>
<p>Upon more research, we found that search engines also look at the response
headers. Given below is the sequence that search engines follow for indexing the
web pages.</p>
<ul>
<li>Crawler gets the raw page source as a response to the HTTP request.</li>
<li>Crawler checks if <code>x-robots-tag: noindex, nofollow</code> header is present in the
response.</li>
<li>Crawler checks the meta tags to determine if the page needs to be indexed or
not.</li>
</ul>
<p>If a page has <code>x-robot-tag: noidex, nofollow</code> then the crawler will not index
the page.</p>
<p>Based on this information, we decided to use
<a href="https://developers.Cloudflare.com/rules/transform/response-header-modification/">Response Header Modification Rules</a>
feature of Cloudflare. Below is a video of how it was done.</p>
<p><a href="https://www.youtube.com/watch?v=0AFeM2yyg_A"><img src="https://img.youtube.com/vi/0AFeM2yyg_A/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=0AFeM2yyg_A">Watch on YouTube</a></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Debugging high GitHub action usage]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/high-github-action-usage"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/debugging_high_github_action_usage.jpg"/>
      <id>https://www.bigbinary.com/blog/high-github-action-usage</id>
      <published>2023-08-08T00:00:00.000Z</published>
      <updated>2023-08-08T00:00:00.000Z</updated>
      <author>
        <name>Unnikrishnan KP</name>
        <uri>https://www.bigbinary.com/blog/authors/unni</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/debugging_high_github_action_usage.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[During the development of neeto we noticed arbitrarily very high GitHub action usage. I investigated the matter and made this video to show to my team members how I went about debugging this issue....]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/high-github-action-usage"><![CDATA[<p>During the development of <a href="https://neeto.com">neeto</a> we noticed arbitrarily very
high GitHub action usage. I investigated the matter and made this video to show
to my team members how I went about debugging this issue. The video is being
presented &quot;as it was recorded&quot;.</p>
<p><a href="https://www.youtube.com/watch?v=eS4BAhk7DAo"><img src="https://img.youtube.com/vi/eS4BAhk7DAo/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=eS4BAhk7DAo">Watch on YouTube</a></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Upgrading to TLS 1.2 using Cloudflare]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/upgrading-tls-using-cloudflare"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/upgrading_TLS_using_cloudflare.jpg"/>
      <id>https://www.bigbinary.com/blog/upgrading-tls-using-cloudflare</id>
      <published>2023-08-03T00:00:00.000Z</published>
      <updated>2023-08-03T00:00:00.000Z</updated>
      <author>
        <name>Ghouse Mohamed</name>
        <uri>https://www.bigbinary.com/blog/authors/ghousemohamed</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/upgrading_TLS_using_cloudflare.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[NeetoCal is one of the products built under neeto. NeetoCal makes it easier to manage meetings. We wanted to allow users to use Zoom as one of the ways to have online meetings. We submitted the...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/upgrading-tls-using-cloudflare"><![CDATA[<p><a href="https://neeto.com/neetocal">NeetoCal</a> is one of the products built under
<a href="https://neeto.com">neeto</a>. NeetoCal makes it easier to manage meetings. We
wanted to allow users to use Zoom as one of the ways to have online meetings. We
submitted the NeetoCal app for approval to the Zoom team. The Zoom security team
notified us that they could not approve the app, because the app was supporting
TLS 1.0 and TLS 1.1.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/upgrading-tls-using-cloudflare/zoom-tls-issue.webp" alt="zoom tls issues"></p>
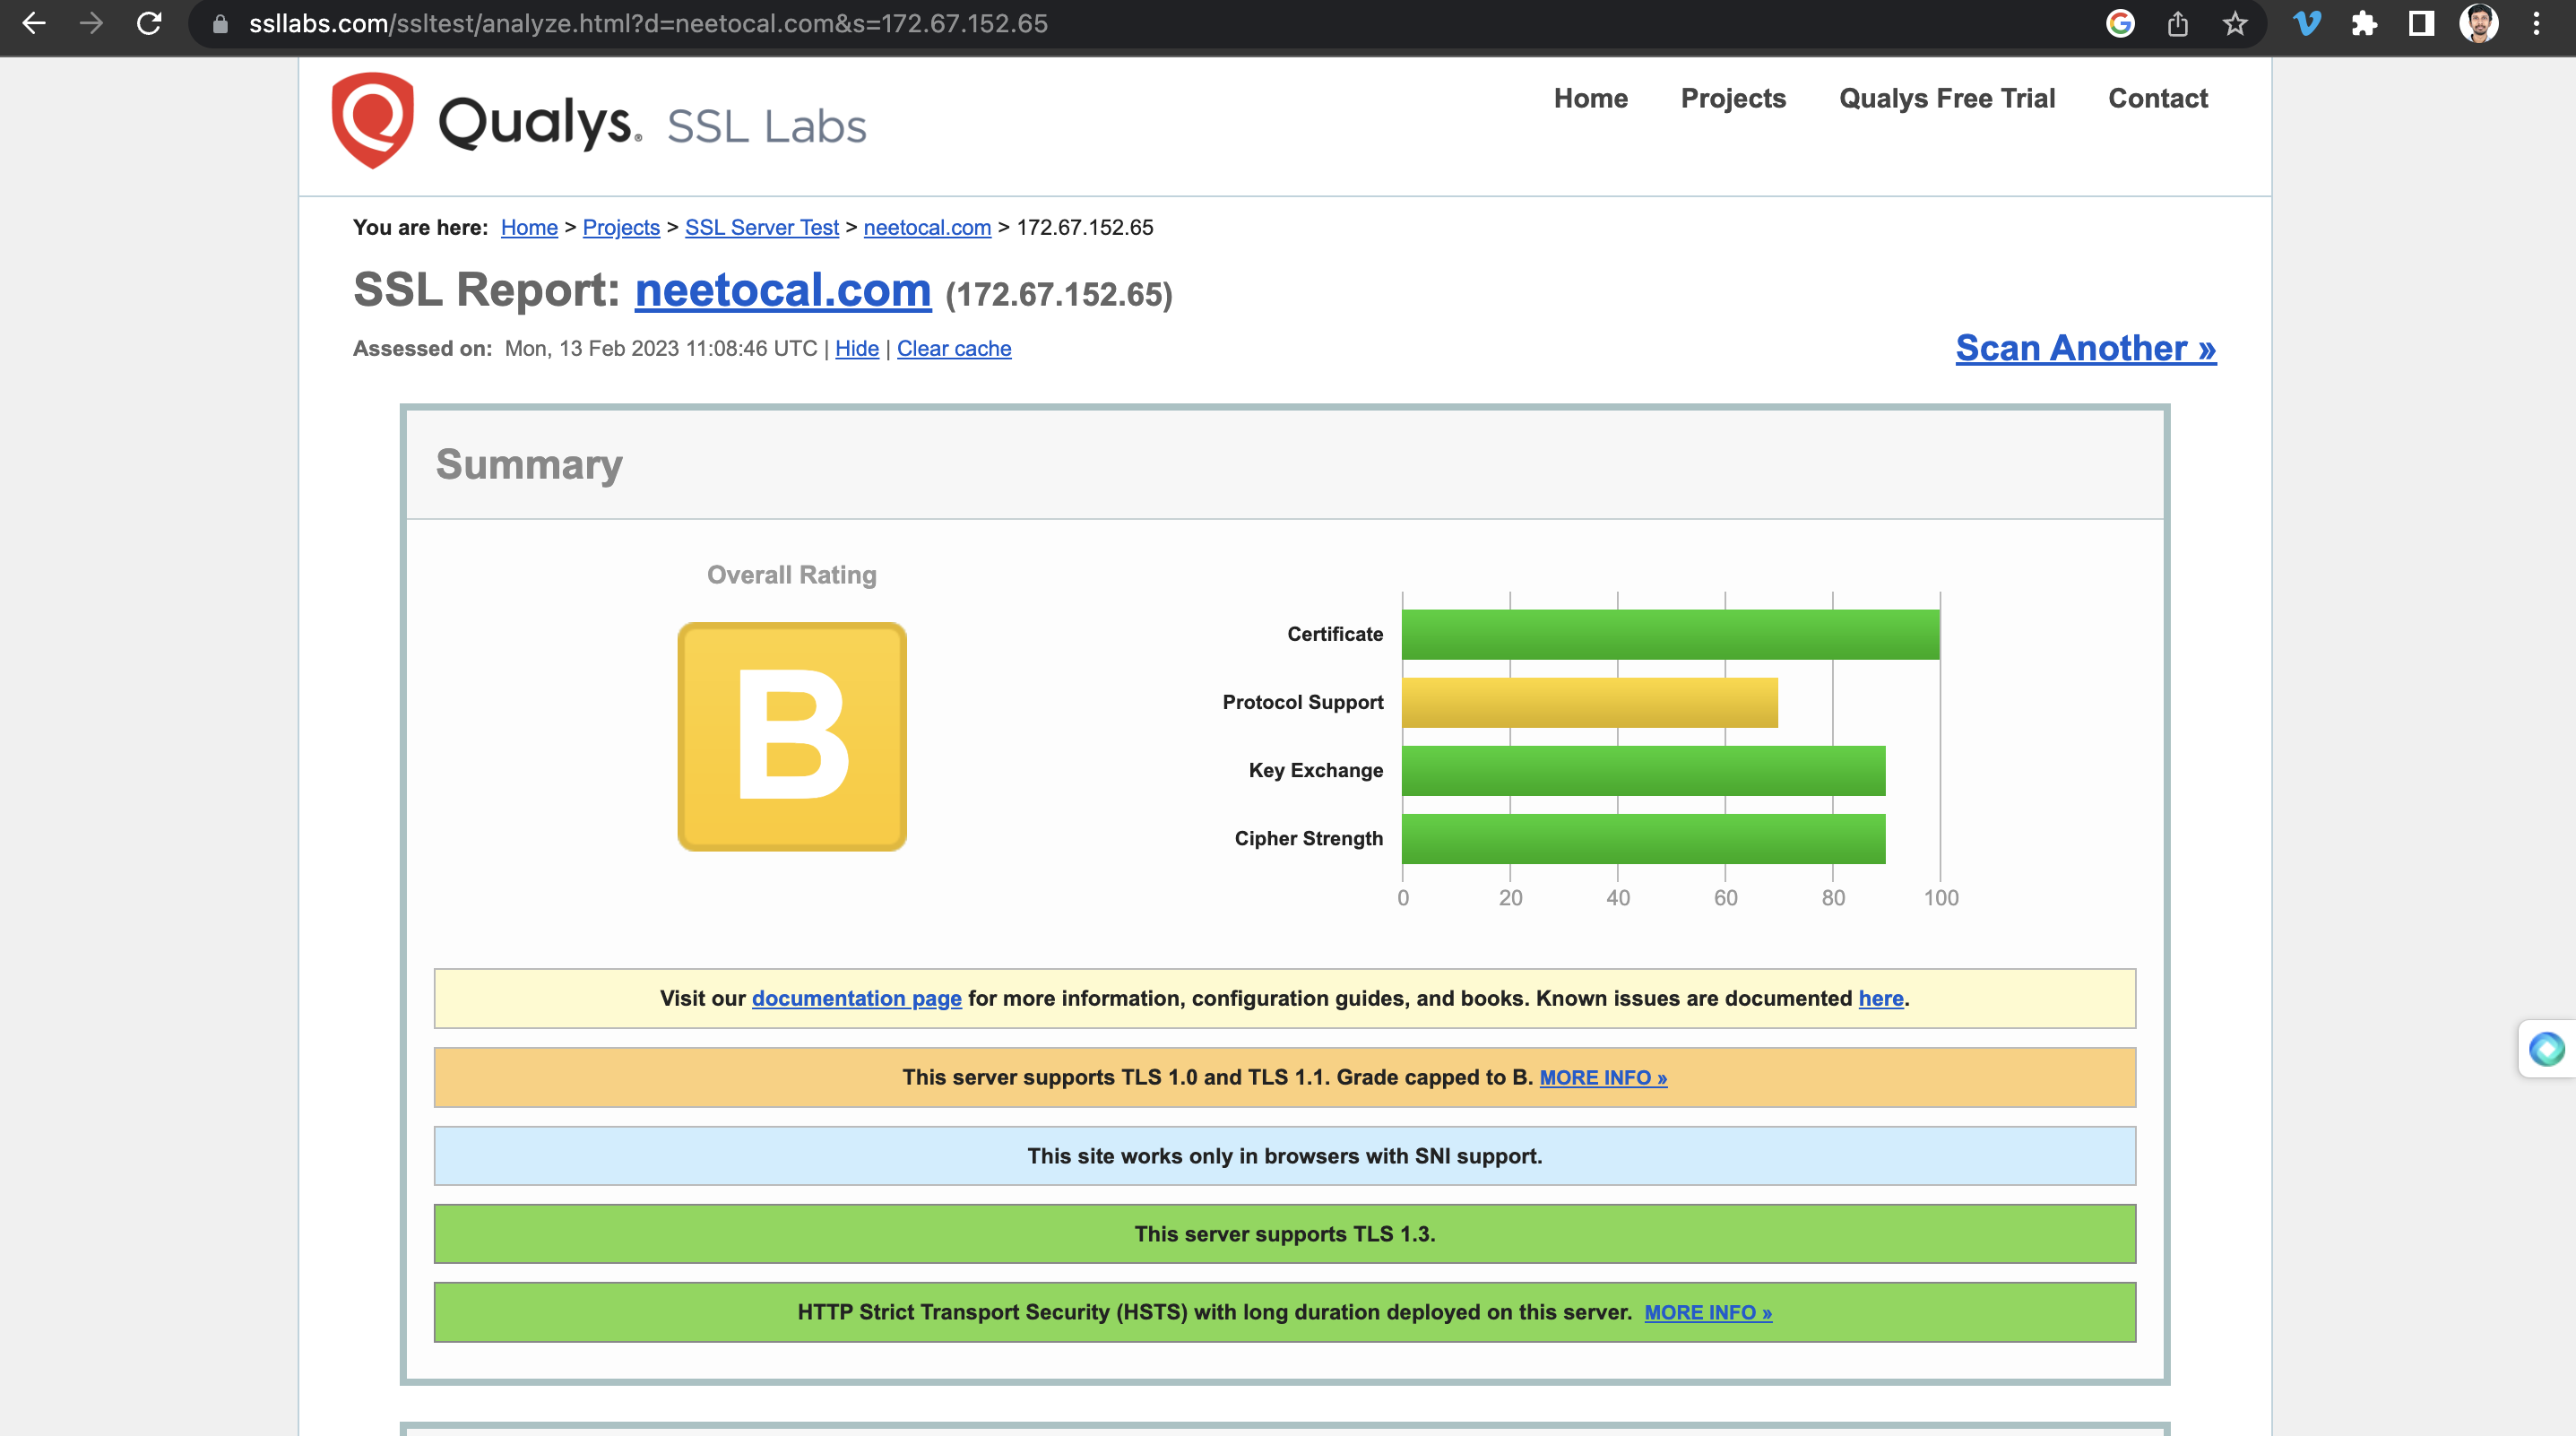
<p>We checked with SSLlabs and it said the same thing: the servers support TLS 1.0
and TLS 1.1.
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/upgrading-tls-using-cloudflare/older-tls-support.png" alt="support for older TLS"></p>
<p>TLS 1.0 was published in 1999, and TLS 1.1 was published in 2006. Microsoft and
other companies don't support these two versions of TLS. Even Heroku
<a href="https://help.heroku.com/G0YVUNPG/how-do-i-disable-support-for-tls-1-0-or-1-1-on-a-heroku-app">doesn't support</a>
it.</p>
<p>All our Neeto applications are hosted on Heroku. If Heroku doesn't support TLS
1.0 and TLS 1.1, how come the server supports these older versions of TLS?</p>
<h2>Solving the TLS issue using Cloudflare</h2>
<p>We use <a href="https://www.cloudflare.com/">Cloudflare</a> as our DNS server for all Neeto
products. Cloudflare allows us to proxy the request. It means that when the user
hits neetocal.com, their request is not going to Heroku. Cloudflare will
intercept the request, and then Cloudflare will make a request to the Heroku
server on behalf of the user. When Cloudflare makes this request to Heroku will
use its own SSL certificate.</p>
<p>Cloudflare allows us to have control over the &quot;Minimum TLS version&quot; to support.
We configured Cloudflare to not support TLS 1.0 and TLS 1.1.</p>
<p>The following video goes into step-by-step detail on how we configured this in
Cloudflare.</p>
<p><a href="https://www.youtube.com/watch?v=sED8_Qwmi2w"><img src="https://img.youtube.com/vi/sED8_Qwmi2w/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=sED8_Qwmi2w">Watch on YouTube</a></p>
<p><a href="https://www.cdn77.com/tls-test">CDN77</a> is the service we used in the video to
check the TLS version.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Deleting all staging apps and building automatic backups]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/routine-db-exports-neetodeploy"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/why_and_how_we_built_routine_DB_exports.jpg"/>
      <id>https://www.bigbinary.com/blog/routine-db-exports-neetodeploy</id>
      <published>2023-07-14T00:00:00.000Z</published>
      <updated>2023-07-14T00:00:00.000Z</updated>
      <author>
        <name>Subin Siby</name>
        <uri>https://www.bigbinary.com/blog/authors/subins2000</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/why_and_how_we_built_routine_DB_exports.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Why and how we built routine DB exports]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/routine-db-exports-neetodeploy"><![CDATA[<p>We are building <a href="https://neeto.com/neetodeploy">NeetoDeploy</a>, an alternative for
Heroku makes it easy to deploy and manage applications on the cloud. It is built with a
mix of Kubernetes and Rails.</p>
<p>We switched our pull-request
<a href="https://devcenter.heroku.com/articles/github-integration-review-apps">review apps from Heroku</a>
to NeetoDeploy a couple of months ago, and it has been doing well. As the next
step of the process, we are building features to target staging and production.
We had an essential staging set up in March, and by the end of the month, we had
migrated staging deployments of all Neeto from Heroku to NeetoDeploy. Everything
was working fine for a week until I made a grave mistake.</p>
<h2>What happened</h2>
<p>Whenever a PR is opened or a new commit is pushed, NeetoDeploy receives a
webhook call from GitHub. Review/staging apps are created/updated on NeetoDeploy
in response to these webhook calls.</p>
<p>On 2023 April 5, a misconfiguration caused NeetoDeploy's webhook handler to
malfunction for an hour. As a result, some review apps were not deleted even
after the corresponding PRs were closed or merged. The solution was
cross-checking review apps with the open PRs and deleting the unwanted apps.
Using <code>rails console</code>, this could be done live on the server.</p>
<p>Here is what that solution looked like:</p>
<pre><code class="language-ruby">GithubRepository.find_each do |github_repository|
  access_token = github_repository.github_integration.access_token
  github_client = Octokit::Client.new(access_token:)

  open_pr_numbers = github_client
    .pull_requests(github_repository.name, state: :open)
    .pluck(:number)

  github_repository.project.apps.find_each do |app|
    next if open_pr_numbers.include?(app.pr_number)
    Apps::DestroyService.new(app).process!
  end
end
</code></pre>
<p>But there is a terrible mistake in the above code. See if you can spot that.</p>
<p>I'm going to wait...</p>
<p>A bit more waiting... Enough waiting; here's the mistake:</p>
<p>There is no filter in the apps that were picked to be destroyed. This snippet
was written at a time when we only had review apps. So
<code>github_repository.project.apps</code> was expected to return review apps. But we now
also had staging apps in the database. And those staging apps weren't filtered
out here. After running the snippet and noticing it took longer than expected, I
realized the mistake and instantly pressed<code>CTRL + C</code>. Of course, it was taking
time since it was deleting all the staging app databases and dynos 🤦.</p>
<p>In the end, out of 33 staging apps, only five remained. And thus started, the
procedure to restore all of them.</p>
<h2>The recovery</h2>
<p>NeetoDeploy already had the feature to do manual
<a href="https://help.neetodeploy.com/articles/database-exports">DB exports</a> but this
wasn't being done routinely. We were only hosting review apps (whose data need
not be persisted reliably), and staging had only started just a week before.</p>
<p>We had database backups from a week before (when we ultimately migrated staging
apps off Heroku), and one by one, our small team of 4 brought back all the apps
in 2 days. The next step is to try not to let this happen again; if it were to
happen, we have a contingency plan. We thought of two types of contingency
plans:</p>
<ul>
<li>Automatic scheduled backups</li>
<li>Disk snapshots of the DB</li>
</ul>
<h2>Automatic scheduled backups</h2>
<p>The idea is that the database would be exported at a particular time every day.
Backups older than a month would be deleted automatically to save space.</p>
<p>We implemented this in a week. Every day at 12 AM UTC, all staging+production
databases would be exported and uploaded to an S3 bucket.</p>
<p>While this feature was being implemented, I used the Rails console to manually
export all the apps. The exported file URLs of each DB were manually
copied to a text file. <a href="https://aria2.github.io/">aria2c</a> was then used to
download them in parallel to a local folder:</p>
<pre><code class="language-bash">aria2c -c --input-file export_urls.txt
</code></pre>
<p>aria2c is a smart downloader. It will resume interrupted downloads, wouldn’t
duplicate downloads, and do everything in parallel.</p>
<h2>Disk snapshots of the DB</h2>
<p>The other contingency method is to do periodic snapshots of the volume holding
the DB. We are working on this.</p>
<p>You can refer to this
<a href="https://about.gitlab.com/blog/2017/02/10/postmortem-of-database-outage-of-january-31/#broken-recovery-procedures">blog post of GitLab</a>
to know their recovery procedures when they faced a significant data loss
in 2017.</p>
<h2>Lessons</h2>
<p>The core lesson here is to call destructive methods very carefully. Instead of
calling the <code>DestroyService</code> instantly, there could have been an intermediate
human check:</p>
<pre><code class="language-ruby">apps = []
GithubRepository.find_each do |github_repository|
  access_token = github_repository.github_integration.access_token
  github_client = Octokit::Client.new(access_token:)

  open_pr_numbers = github_client
    .pull_requests(github_repository.name, state: :open)
    .pluck(:number)

  github_repository.project.apps.review.find_each do |app|
    next if open_pr_numbers.include?(app.pr_number)
    apps.append(app)
  end
end
</code></pre>
<p>This would populate the list of apps to delete in <code>apps</code> variable, it can be
displayed, verified and then we can destroy them individually:</p>
<pre><code class="language-ruby">apps.map do |app|
  Apps::DestroyService.new(app).process!
end
</code></pre>
<p>The other takeaway here is to have proper recovery mechanisms in place.
Human/system errors are possible; we should be prepared when it happens.</p>
<p><a href="https://neeto.com/neetodeploy">NeetoDeploy</a> is still not production-ready.
However, if you want to give NeetoDeploy a try, then tweet to us at
<a href="https://twitter.com/neetodeploy">@neetoDeploy</a> or send us an email at
<code>invite@neeto.com</code>.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[How SPF protects domain reputation and email delivery]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/how-spf-protects-domain-reputation"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/how_spf_protects_domain_reputation.jpg"/>
      <id>https://www.bigbinary.com/blog/how-spf-protects-domain-reputation</id>
      <published>2023-04-26T00:00:00.000Z</published>
      <updated>2023-04-26T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/how_spf_protects_domain_reputation.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[How SPF protects domain reputation and helps in email deliverability]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/how-spf-protects-domain-reputation"><![CDATA[<p>Email is a wonderful thing. Anyone can send an email to anyone, and it all works
beautifully. In the early stages of the Internet, we didn't have to worry about
security and scammers. As emails started to play a more vital role in our life
scammers started to con people to steal their money.</p>
<p>Not only can anyone send an email to anyone, but anyone can pretend to be anyone. I
can send an email to you and the email will come to you as if it were sent by
&quot;Elon Musk&quot; and the from address could be &quot;elon@musk.com&quot;.</p>
<p>I can send an email to you pretending that the email is from your bank and you
need to change your password. In one case, a hacker sent an email to a company's
finance team telling them that the company's bank account number has changed.
The hacker walked away with millions of dollars.</p>
<p>Hackers can also do damage to one's domain reputation.</p>
<p>Let's assume that there is a business called &quot;PrixPapers&quot; and they have
thousands of customers all over the country. Malicious folks can start sending
emails to people pretending to be &quot;PrixPapers&quot;. When people receive an email
like this they might buy the item. The item could be &quot;fake goods&quot;. Ideally, no
one should be able to send any email pretending to be someone else.</p>
<p>Since these malicious folks don't have the actual list of the customers of
PrixPapers will in general spam people. Some people receiving this email will
mark these emails as &quot;spam&quot;. As more and more people mark these emails as &quot;spam&quot;
the domain reputation of &quot;prixpapers.com&quot; will go down. It means that when
&quot;prixpapers.com&quot; will send out a legitimate newsletter to its customers some of
these emails will be marked as &quot;spam&quot; because of the nefarious work done by the
previous scammer.</p>
<p>The challenge presented to the Internet authorities is that they want to keep
email simple but safe at the same time. They came up with certain policies to
make emails safe and secure. In this blog, we will see how SPF helps in keeping
email secure. However, first, we need to know what is &quot;Return-path&quot;. We'll later
see how it is used in blocking fake emails.</p>
<h3>Return-path</h3>
<p>Let's say that we are dealing with a company called
<a href="https://www.neeto.com/neetocal">NeetoCal</a>. They have the domain <em>neetocal.com</em>.</p>
<p>Let's say that <em>brian@neetocal.com</em> sent an email to <em>peter@gmail.com</em>. Let's
pretend that for some reason Peter's mailbox is full and the email sent by Brian
bounces. In that case, Brain will get an email that the message bounced. We all
have seen these kinds of messages.</p>
<p>Now let's imagine that it's end of the year sale time and NeetoCal decided to
send an email campaign to all its customers giving them a 10% discount. This
email will go out to their 5000 customers. Some of these emails are bound to
bounce. If all the bounced emails come to Brain then Brain's inbox would be
filled with such bounced emails.</p>
<p>To solve this problem email protocol allows us to set a hidden field called
<em>Return-path</em>. This value can be set in the email header. <em>Return-path</em> set in
the email header indicates how to process bounced emails. Anytime an email
server detects that an email can't be delivered for reasons like &quot;mailbox is
full&quot; or &quot;the email doesn't exist&quot; then that email server can send an email to
the email address mentioned in <em>Return-path</em>. The business owner can look at
<em>Return-path</em> emails to analyze how many emails are bouncing and why.</p>
<p>If you are sending an email using &quot;Gmail&quot;, &quot;outlook&quot;, &quot;yahoo&quot; etc then the
<em>Return-path</em> is set as your email so that you get to know if there is a bounced
email. Email service providers allow us to customize <em>Return-path</em> in case one
is running a big marketing campaign. For example here is a
<a href="https://sendgrid.com/blog/what-is-return-path">document</a> from SendGrid
describing how to set <em>Return-path</em>.</p>
<p>Why are we talking about how bounced emails are processed when we are dealing
with the subject of &quot;email deliverability&quot;. That's because <em>Return-path</em> plays a
dual role as we will see next.</p>
<h2>What is SPF record</h2>
<p>Before we get into the SPF record, let's take a simple real-world example of how it
works.</p>
<p>Let's say there's a gatekeeper at the NeetoCal office. This gatekeeper
will only allow the people who work there. It means the gatekeeper has a list of
approved people and for each person getting through the gate, the gatekeeper
checks if the person is in the approved list or not.</p>
<p>SPF works similarly. SPF policy is a mechanism to tell the email server if the
email is coming from a trusted source, then accept the email or reject the email.
A sender policy framework (SPF) record is a type of DNS TXT record that lists
all the servers authorized to send emails from a particular domain.</p>
<p>Let's take a real-world example. The SPF record of neetocal.com looks like
<code>v=spf1 include:spf.messagingengine.com -all</code>. We can see this data
<a href="https://mxtoolbox.com/SuperTool.aspx?action=spf%3aneetocal.com&amp;run=toolpage">using mxtoolbox</a>.</p>
<h3>How the SPF record is used</h3>
<p>Let's look at the following case.</p>
<p>Step 1. <em>notifications@neetocal.com</em> sends an email to <em>elon@gmail.com</em>.</p>
<p>Step 2. This email is sent to <a href="https://fastmail.com">Fastmail</a> since NeetoCal is
using the Fastmail services.</p>
<p>Step 3. The Fastmail email server receives this email as an outgoing email.</p>
<p>Step 4. Fastmail email server adds email header <em>Return-path</em> value to
&quot;notifiations@neetocal.com&quot;.</p>
<p>Step 5. The Fastmail email server sends this email to the gmail server.</p>
<p>Step 6. The Gmail server gets this email.</p>
<p>Step 7. The Gmail server extracts the <em>Return-path</em> key and finds that the
domain is &quot;neetocal.com&quot;.</p>
<p>Step 8. The Gmail server finds the TXT DNS records of &quot;neetocal.com&quot;. This lists
all the approved IP addresses.</p>
<p>Step 9. The Gmail server will check if the email server which sent the email is
in the approved IP addresses or not.</p>
<p>Step 10. If the IP address is in the approved IP addresses list then the email
is approved for further processing. Otherwise, the email is rejected.</p>
<p>We can go to https://dmarcian.com/spf-survey/ and enter &quot;neetocal.com&quot; here.
They get the IP addresses published for &quot;messagingengine.com&quot; and then they show
the list of the approved IPs.</p>
<h3>Allowing the third party to send emails on your behalf</h3>
<p>Let's say that Brian decides to use <a href="https://www.mailerlite.com">Mailerlite</a> to
send marketing emails. Now if Mailerlite sends an email then the receiving email
server will notice that the IP address of Mailerlite is not in the approved list
of ips and the email will be rejected.</p>
<p>A domain is allowed to have only one SPF record. So if NeetoCal wants to use
Mailerlite for marketing then the spf records need to be updated. If you signup
for a domain in Mailerlite then Mailerlite will check if that domain has an
existing SPF record or not. If there is no SPF record then Mailerlite won't do
anything. However, if there is an existing SPF record then Mailerlite will
insist that first you update the SPF record to include Mailerlite so that the
emails from Mailerlite are not rejected.</p>
<p><a href="https://bigbinary.com">BigBinary</a> uses Mailerlite to email newly published
blogs to the subscribers. Given below is what the SPF record of BigBinary looks
like. We can also see this result
<a href="https://mxtoolbox.com/SuperTool.aspx?action=spf%3abigbinary.com&amp;run=toolpage">online</a>.</p>
<pre><code>v=spf1 include:_spf.mlsend.com include:_spf.google.com -all
</code></pre>
<p>BigBinary uses google workspace so the second include is for that reason. The
first include is to ensure that Mailerlite is in the allowed ip list.</p>
<p>If we look at the result for &quot;bigbinary.com&quot; by visiting
https://dmarcian.com/spf-survey/ then we will that all these includes are like
regular programming language &quot;imports&quot;. They allow the third party to include
other third parties in the chain. The end result is that we have a finite list
of approved IP addresses which can send email.</p>
<h2>spf record standard</h2>
<p>Let's take a look at NeetoCal's SPF record.</p>
<pre><code>v=spf1 include:spf.messagingengine.com -all
</code></pre>
<p><code>v=spf1</code> tells the server that this record contains an SPF record. Every SPF
record must begin with this string.</p>
<p><code>include:spf.messagingengine.com</code> tells the server what third-party
organizations are authorized to send emails on behalf of the domain. This tag
signals that the content of the SPF record for the included domain
(messagingengine.com in this case) should be checked and the IP addresses it
contains should also be considered authorized. Multiple domains can be included
within an SPF record.</p>
<p><code>-all</code> tells the server that addresses not listed in the SPF record is not
authorized to send emails and should be rejected. Alternative options here
include <code>~all</code>, which states that unlisted emails will be marked as insecure or
spam but still accepted. <code>+all</code> signifies that any server can send emails on
behalf of the domain.</p>
<p>Here is another format of SPF record.</p>
<pre><code>v=spf1 ip4=192.0.2.0 ip4=192.0.2.1 include:messagingengine.email -all
</code></pre>
<p>In this example, the SPF record is telling the server that ip4=192.0.2.0 and
ip4=192.0.2.1 are also authorized to send emails on behalf of the domain.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Redirecting URL using cloudflare redirect rules]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/redirecting-url-using-cloudflare"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/redirecting-url-using-cloudflare.png"/>
      <id>https://www.bigbinary.com/blog/redirecting-url-using-cloudflare</id>
      <published>2023-03-14T00:00:00.000Z</published>
      <updated>2023-03-14T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/redirecting-url-using-cloudflare.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Redirecting url using cloudflar redirect rules]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/redirecting-url-using-cloudflare"><![CDATA[<p>At BigBinary, we had been using AceInvoice as our time tracking and invoicing
tool for years. Last year, we migrated all the data to
<a href="https://neeto.com/neetoinvoice">NeetoInvoice</a>.</p>
<p>All this time, the AceInvoice website was not redirecting to NeetoInvoice. Today
we did that using <a href="https://cloudflare.com">Cloudflare</a>. The URL forwarding or
redirecting with
<a href="https://developers.cloudflare.com/support/page-rules/configuring-url-forwarding-or-redirects-with-page-rules/">page rule</a>
is a neat feature of Cloudflare. Below are the screenshots of the steps taken to
redirect the URLs. More details are covered in the video.</p>
<h3>Handling www version</h3>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/redirecting-url-using-cloudflare/www-version.png" alt="WWW version"></p>
<h3>Handling no www version</h3>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/redirecting-url-using-cloudflare/no-www-version.png" alt="No WWW version"></p>
<p><a href="https://www.youtube.com/watch?v=R6-qnYN6PUs"><img src="https://img.youtube.com/vi/R6-qnYN6PUs/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=R6-qnYN6PUs">Watch on YouTube</a></p>
<p>We didn't mention it in the video, but it's worth knowing that we need to have a
<code>CNAME</code> record for a subdomain that needs forwarding. For examples let's say
that we need to forward all traffic from <code>https://videos.bigbinary.com</code> to
<code>https://bigbinary.com/video</code>. We can't add a page rule for this directly. For
we need to add a DNS entry for subdomain <code>videos</code> and this entry must have
cloudflare &quot;proxy&quot; checked so that you see <code>Proxied</code> next to it. If you see &quot;DNS
only&quot; then that means Cloudflare will not be able to do any forwarding.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[How to use JWT to secure your GitHub OAuth callback endpoint]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/how-to-use-jwt-to-secure-your-github-oauth-callback-endpoint"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/how-to-use-jwt-to-secure-your-github-oauth-callback-endpoint.png"/>
      <id>https://www.bigbinary.com/blog/how-to-use-jwt-to-secure-your-github-oauth-callback-endpoint</id>
      <published>2023-03-07T00:00:00.000Z</published>
      <updated>2023-03-07T00:00:00.000Z</updated>
      <author>
        <name>Jagannath Bhat</name>
        <uri>https://www.bigbinary.com/blog/authors/jagannathbhat</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/how-to-use-jwt-to-secure-your-github-oauth-callback-endpoint.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Sending data to OAuth servers using JWT enables applications to verify the authenticity of the data that is sent back to the callback endpoint.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/how-to-use-jwt-to-secure-your-github-oauth-callback-endpoint"><![CDATA[<p>JSON Web Tokens (JWTs) have become a popular way to manage user authentication
and authorization. In this blog, we will explore how to use JWTs in GitHub OAuth
process, including how to encode additional parameters in the JWT to improve the
security and functionality of your GitHub OAuth integration. Let's start by
looking into what OAuth is.</p>
<h2>OAuth 2.0</h2>
<p>OAuth 2.0 is an authorization framework that enables an application to access
data from a server on behalf of a user. For example, OAuth enables applications
to access data from Google, Facebook, GitHub, etc., on behalf of users having
accounts in that service.</p>
<p>Let's say you have an application that requires access to a user's data on
GitHub. The following are the steps involved in authorizing your application
with GitHub:</p>
<ol>
<li>
<p>The application requests authorization from GitHub. The following are some of
the parameters this request should contain:</p>
<ul>
<li><code>client_id</code> - This is an ID used by GitHub for identifying the application.
You need to register your application with GitHub to get this ID.</li>
<li><code>redirect_uri</code> - The URI to which GitHub should send back a request once
the authorization is approved.</li>
<li><code>login</code> - This is a username on GitHub. The application requires access to
data on behalf of the user with this username.</li>
<li><code>state</code> - This should ideally be a string of random characters. Store this
string in memory because it will be used in another step. This parameter is
optional but highly recommended. We'll look into why later.</li>
</ul>
</li>
<li>
<p>GitHub then asks the user to grant the authorization. The user might be
prompted to log in to GitHub if they have not already logged in. Then GitHub
displays information on the application and lists all the data the
application wants to access. If the user denies authorization, the process
ends here. If the user approves, we move on to the next step.</p>
</li>
<li>
<p>GitHub sends a request to the application through the URI passed as
<code>redirect_uri</code> in the first step. This request will contain a <code>code</code>
parameter that serves as a temporary authorization code and a <code>state</code>
parameter.</p>
</li>
<li>
<p>The OAuth process must be dropped immediately if the value of the <code>state</code>
parameter from the previous step does not match the random string stored in
memory in step 1. This ensures that the OAuth process was initiated by your
application. We'll look more into this later.</p>
</li>
<li>
<p>The application should send another request to GitHub to generate a permanent
authentication token. This request should contain the <code>code</code> sent by GitHub
in step 3.</p>
</li>
<li>
<p>GitHub responds with an authentication token that can be used by the
application to access data on behalf of the user.</p>
</li>
</ol>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/how-to-use-jwt-to-secure-your-github-oauth-callback-endpoint/github_oauth_process.png" alt="GitHub OAuth process"></p>
<h2>The state parameter</h2>
<p>The <code>state</code> parameter plays a crucial role in ensuring that the GitHub OAuth
process was initiated by your application or a trusted source. An unauthorized
third party could pose as your application by using your <code>client_id</code>. The value
of <code>client_id</code> is not exactly a secret. GitHub treats any OAuth process
initiated using your ID as an OAuth process started by your application.</p>
<p>Let's see how the OAuth process would play out when initiated by an unauthorized
third party:</p>
<ol>
<li>
<p>Third-party requests authorization from GitHub. The third party would pass
your ID as <code>client_id</code>. This would lead GitHub to believe the request is from
your application. The third party may or may not pass a <code>state</code> parameter.</p>
</li>
<li>
<p>GitHub then asks the user to grant the authorization. If the third party uses
one of their own accounts, they could grant the authorization. The third
party could also convince a user to grant permission using social
engineering. For example, they could perform a phishing attack using an email
designed to trick the user into believing that the email was from your
application.</p>
</li>
<li>
<p>GitHub sends a request to the application through the URI passed as
<code>redirect_uri</code> in the first step. This request would contain the <code>code</code>
parameter, and the <code>state</code> parameter if it was passed in step 1.</p>
</li>
<li>
<p>It would be clear that the process was not initiated by your application if
the <code>state</code> parameter is missing. Even if there was a <code>state</code> parameter, it
would not be found in memory. This is because the state parameter was
generated by a third party and not your application. Only those state
parameters generated by your application will be found in your memory.</p>
</li>
</ol>
<h2>JSON Web Tokens</h2>
<p>JSON Web Tokens (JWT) is a structured format that contains header, payload, and
signature components. Let's take a look at the significance of these components:</p>
<ol>
<li>
<p><strong>Header</strong> - The header is a JSON string that typically contains the signing
algorithm used, such as HMAC, SHA256, or RSA.</p>
</li>
<li>
<p><strong>Payload</strong> - The payload is a JSON string that contains claims and
additional data. Claims can be used to enforce security constraints and
validate the authenticity of the token and its contents. For example, a
claims can specify the token expiration time. The expiration time, most
commonly represented by <code>exp</code>, represents the date and time after which the
token will no longer be considered valid.</p>
</li>
<li>
<p><strong>Signature</strong> - The signature is used to verify that the sender of the JWT is
who it says it is and to ensure that the token has not been tampered with
along the way. Just like the hand signature of a person, it is hard to forge
a JWT signature. (Digital signatures are significantly harder to forge
compared to a person's hand signature)</p>
</li>
</ol>
<h3>Generating a JWT</h3>
<p>The following steps outline the process of generating a JWT:</p>
<ol>
<li>
<p>The header and the payload of the JWT are first encoded using Base64
encoding. So now we have two strings - the encoded header and the encoded
payload.</p>
</li>
<li>
<p>The encoded header and the encoded payload are concatenated into a single
string, with dots (.) separating each part. The concatenated string is signed
using the signing algorithm specified in the header. The signing algorithm
uses a secret key, that is known only to the issuer (your application), which
ensures that only the issuer can generate a valid signature. The result of
the signing process is a signature, which is also a string.</p>
</li>
<li>
<p>The encoded header, the encoded payload, and the signature are concatenated
into a single string, with dots (.) separating each part. The resulting
string is the JWT, which can be transferred securely between parties.</p>
</li>
</ol>
<p>For example, let's say we have the following header:</p>
<pre><code class="language-json">{ &quot;alg&quot;: &quot;RS256&quot; }
</code></pre>
<p>The value of <code>alg</code> contains the algorithm used for signing the JWT. Also, let's
say we have the following payload:</p>
<pre><code class="language-json">{ &quot;username&quot;: &quot;sam@example.com&quot;, &quot;exp&quot;: 1676263763 }
</code></pre>
<p>The <code>username</code> is data that needs to be transferred. <code>exp</code> contains the
expiration time claim of the JWT.</p>
<p>When both these components are encoded, we get:</p>
<ul>
<li>Header - &quot;eyJhbGciOiJSUzI1NiJ9&quot;</li>
<li>Payload - &quot;eyJ1c2VyIjoic2FtQGV4YW1wbGUuY29tIiwiZXhwIjoxNjc2MjYzNzYzfQ&quot;</li>
</ul>
<p>When these are signed using the RS256 algorithm and a secret key, a signature is
produced. The following signature was generated using the RS256 algorithm and a
secret key (which will remain secret):</p>
<pre><code class="language-text">NlAT6awp68dCEcFXbDeeLTzZekqUmB3f6kr3jkGSFmrKa5zvLmFGeraWba_fUuQLVhRtcXUPZbRR1DKnKH0HVf1rRDvOqezwbhe-hR1wlz6vZkHuPjtYSCLx_aybGm7dy2ijfTQwYd14cD9ZiMI5vf6XcDDfE7mkhu0ogCOnqR1v3KOEWJkMkvGBHfHKuf9FKYbWltHtUE6bAEO1orq0JayD8UNUKxdGkElXA7mkuIEexmBuieG9PJ2ow_uo05QCsqDvxlzOCMMIe7WdT7gmz4myiZ7lVuUcL1V2-Y1PJqWDyqDZbKNxd4X_CwW0RLOF1pw9S2URgybqHZFG0murNw
</code></pre>
<p>So the final JWT would be:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/how-to-use-jwt-to-secure-your-github-oauth-callback-endpoint/jwt_decoded.png" alt="Screenshot of decoded JWT"></p>
<p>The image above was captured from the decoding tool in
<a href="https://jwt.io/">jwt.io</a>.</p>
<p>JWT is basically a Base64 encoded string with a signature attached to it. Having
that signature component makes JWT a secure format for transferring data. It is
possible to simply encode data with Base64 and transfer that string. From the
example above, transferring the encoded payload
&quot;eyJ1c2VyIjoic2FtQGV4YW1wbGUuY29tIiwiZXhwIjoxNjc2MjYzNzYzfQ&quot; can also get the
data to the other party. However, the party that receives the data have no way
of ensuring that the data was sent by a trusted source and that the data was not
tampered with along the way.</p>
<h3>Verifying JWT tokens</h3>
<p>Anyone who has the secret key used to sign a JWT, can verify the integrity of
the JWT. The steps involved in verifying the signature of a JSON Web Token (JWT)
are:</p>
<ol>
<li>
<p>Split the JWT into the encoded header, the encoded payload and the signature,
using the dot (.) used to separate the three components.</p>
</li>
<li>
<p>Decode the encoded header and the encoded payload using Base64 to get the
header and payload JSON strings.</p>
</li>
<li>
<p>The application recreates the signature by signing the encoded header and the
encoded payload using the signing algorithm in the header and the secret key.
If the signature created in this step is the same as the signature in the
JWT, the JWT is valid.</p>
</li>
<li>
<p>The application validates the claims in the payload if there are any.</p>
</li>
</ol>
<p>It can be verified that the JWT was generated by your application and has not
been tampered with, if the signature is valid. If the JWT header or payload was
tampered with, the signature produced while verifying would be different from
the one in the JWT.</p>
<h2>Using JWT for the state parameter</h2>
<p>We can generate a JWT token and pass that as the state parameter in the GitHub
OAuth authorizing process. Here's how the process will be different when using
JWT:</p>
<ol>
<li>
<p>The application requests authorization from GitHub. This time the <code>state</code>
parameter will be a JWT signed using a secure algorithm and a secret key. The
JWT need not be stored in memory.</p>
</li>
<li>
<p>GitHub gets the approval of the user.</p>
</li>
<li>
<p>GitHub sends a request to the application through the URI passed as
<code>redirect_uri</code> in the first step. This request will contain the <code>code</code> and
the <code>state</code> parameters. Here, the state parameter would be a JWT.</p>
</li>
<li>
<p>Validate the JWT from the <code>state</code> parameter. If the JWT is invalid, drop the
authorization process immediately.</p>
</li>
</ol>
<h2>Advantages of using JWT for the state parameter</h2>
<ol>
<li>
<p><strong>No Storage requirement</strong> - When using a random string for the state
parameter, that string has to be stored, so that it can be used later for
verification. However, JWTs can be verified without storing them once they
are generated.</p>
</li>
<li>
<p><strong>Ability to send additional data</strong> - The payload component of JWT can be
used to send additional data such as user data, permissions data, etc.</p>
</li>
<li>
<p><strong>Security</strong> - Using JWT can ensure that the OAuth process was initiated by
your application or a trusted source. In addition, JWT also ensures the
integrity of the data. This means that we can ensure that the payload in the
JWT has not been tampered with.</p>
</li>
<li>
<p><strong>Flexibility</strong> - The claims in the payload component of JWT can be used
further enhance the security of the JWT by implementing custom security
checks based on the claims in the payload.</p>
</li>
<li>
<p><strong>Standardization</strong> - JWT is a widely used format for transferring data.
Using JWT would be beneficial when there are different applications and
services involved in the OAuth process.</p>
</li>
</ol>
<h2>References</h2>
<ol>
<li>
<p>OAuth 2.0 -
<a href="https://www.digitalocean.com/community/tutorials/an-introduction-to-oauth-2">https://www.digitalocean.com/community/tutorials/an-introduction-to-oauth-2</a></p>
</li>
<li>
<p>GitHub OAuth Authorization process -
<a href="https://docs.github.com/en/developers/apps/building-oauth-apps/authorizing-oauth-apps">https://docs.github.com/en/developers/apps/building-oauth-apps/authorizing-oauth-apps</a></p>
</li>
<li>
<p>Phishing Attack -
<a href="https://www.imperva.com/learn/application-security/phishing-attack-scam/">https://www.imperva.com/learn/application-security/phishing-attack-scam/</a></p>
</li>
</ol>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Setting up Heroku DNS using cloudflare]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/setting-up-heroku-dns-using-clouflare"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/setting-up-heroku-dns-using-clouflare.png"/>
      <id>https://www.bigbinary.com/blog/setting-up-heroku-dns-using-clouflare</id>
      <published>2022-09-26T00:00:00.000Z</published>
      <updated>2022-09-26T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/setting-up-heroku-dns-using-clouflare.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Setting up Heroku DNS using cloudlfare]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/setting-up-heroku-dns-using-clouflare"><![CDATA[<p>Lots of folks know <a href="https://www.cloudflare.com/">cloudflare</a> for the DDoS
protection, rate limiting etc services it provides. Here at BigBinary, we also
use Cloudflare for DNS management.</p>
<p>DNS management is a free service by Cloudflare. However, on first glance, it
might not appear that it's a free service. Once we add a site, then we see a
screen like this. Here, we need to remember to scroll down to see the free
option.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2022/setting-up-heroku-dns-using-clouflare/pricing.png" alt="cloudflare pricing page"></p>
<p>Now let's see how we can map the DNS settings from Heroku to Cloudflare. We will
look at both a standard domain name and then we will take a look at a wildcard
domain name.</p>
<h3>Standard domain name</h3>
<p>We are hosting <a href="https://www.gitemit.com/">GitEmit</a> using Heroku. We are letting
Heroku manages the SSL for this domain.</p>
<p>After setting up domains in Heroku, here is what we see.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2022/setting-up-heroku-dns-using-clouflare/heroku-dns-gitemit.png" alt="Heroku DNS gitemit"></p>
<p>In Cloudflare, we can set it up using two CNAMEs. It looks like this.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2022/setting-up-heroku-dns-using-clouflare/cloudflare-heroku-gitemit.png" alt="Heroku DNS"></p>
<h3>Wild card domain name</h3>
<p>We are hosting <a href="https://www.neeto.com/neetochat/">NeetoChat</a> application using
Heroku.</p>
<p>Since it's a wild card domain, we had to
<a href="https://www.bigbinary.com/blog/wild-card-ssl-on-heroku">generate the certificates</a>
ourselves.</p>
<p>After setting up domains in Heroku, here is what we see.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2022/setting-up-heroku-dns-using-clouflare/heroku-dns-neetochat.png" alt="Heroku DNS NeetoChat"></p>
<p>In Cloudflar,e we can set it up using three CNAMEs. It looks like this.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2022/setting-up-heroku-dns-using-clouflare/cloudflare-heroku-neetochat.png" alt="Heroku DNS"></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Configure cypress to run tests in multiple environments]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/cypress-environment-config"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/cypress-environment-config.png"/>
      <id>https://www.bigbinary.com/blog/cypress-environment-config</id>
      <published>2022-03-30T00:00:00.000Z</published>
      <updated>2022-03-30T00:00:00.000Z</updated>
      <author>
        <name>Datt Dongare</name>
        <uri>https://www.bigbinary.com/blog/authors/datt</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/cypress-environment-config.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Do you want to configure cypress to run the tests in multiple application environments? This article will help you to configure them step-by-step.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/cypress-environment-config"><![CDATA[<p>When we write tests, we want to run them in the local environment first. There are
few reasons for this. We need to add <code>data-cy</code>, verify and run the tests. Also,
we need to make sure that tests are running fine on the local/development
environment before running them in test/staging environment. Another case might
be the one where we need to set the CI pipeline to execute in different
environments.</p>
<p>In such scenarios, the <code>baseUrl</code> will be different in both environments. But
cypress allows us to configure <code>baseUrl</code> only once in <code>cypress.json</code> . Then, how
do we configure <code>baseUrl</code> specific for each of the environments? In this blog,
we will see how to configure cypress step by step so that we can run cypress
tests in multiple environments.</p>
<h2>1. Add environment specific configuration</h2>
<p>To configure Cypress for different environments, we can follow the two simple
steps.</p>
<ol>
<li>Create <code>config</code> folder in cypress.</li>
<li>Create separate files for each of the environments.</li>
</ol>
<pre><code class="language-javascript">// cypress/config/cypress.development.json

{
  &quot;baseUrl&quot;: &quot;https://localhost:9006&quot;,
  &quot;env&quot;: {
    &quot;environment&quot;: &quot;development&quot;
  },
  &quot;execTimeout&quot;: 18000,
  &quot;defaultCommandTimeout&quot;: 300000,
  &quot;requestTimeout&quot;: 10000,
  &quot;pageLoadTimeout&quot;: 30000,
  &quot;responseTimeout&quot;: 10000,
  &quot;viewportWidth&quot;: 1200,
  &quot;viewportHeight&quot;: 1200,
  &quot;videoUploadOnPasses&quot;: false,
  &quot;retries&quot;: {
    &quot;runMode&quot;: 1,
    &quot;openMode&quot;: 2
  }
}
</code></pre>
<pre><code class="language-javascript">// cypress/config/cypress.test.json

{
  &quot;baseUrl&quot;: &quot;https://test.example.com&quot;,
  &quot;env&quot;: {
    &quot;environment&quot;: &quot;test&quot;
  },
  &quot;execTimeout&quot;: 300000,
  &quot;defaultCommandTimeout&quot;: 60000,
  &quot;requestTimeout&quot;: 20000,
  &quot;pageLoadTimeout&quot;: 60000,
  &quot;responseTimeout&quot;: 20000,
  &quot;viewportWidth&quot;: 1200,
  &quot;viewportHeight&quot;: 1200,
  &quot;videoUploadOnPasses&quot;: true,
  &quot;retries&quot;: {
    &quot;runMode&quot;: 2,
    &quot;openMode&quot;: 1
  }
}
</code></pre>
<pre><code class="language-javascript">// cypress/config/cypress.production.json

{
  &quot;baseUrl&quot;: &quot;https://live.example.com&quot;,
  &quot;env&quot;: {
    &quot;environment&quot;: &quot;production&quot;
  },
  &quot;execTimeout&quot;: 300000,
  &quot;defaultCommandTimeout&quot;: 60000,
  &quot;requestTimeout&quot;: 20000,
  &quot;pageLoadTimeout&quot;: 60000,
  &quot;responseTimeout&quot;: 20000,
  &quot;viewportWidth&quot;: 1200,
  &quot;viewportHeight&quot;: 1200,
  &quot;videoUploadOnPasses&quot;: true,
  &quot;retries&quot;: {
    &quot;runMode&quot;: 2,
    &quot;openMode&quot;: 1
  }
}
</code></pre>
<h2>2. Initialize config files</h2>
<p>After adding config folder, we need to tell cypress about those config files. We
can do that by updating <code>plugins/index.js</code> with following code. This file gets
executed after we start the cypress server.</p>
<pre><code class="language-javascript">// cypress/plugins/index.js

const fs = require(&quot;fs-extra&quot;);
const path = require(&quot;path&quot;);

const fetchConfigurationByFile = file =&gt; {
  const pathOfConfigurationFile = `config/cypress.${file}.json`;

  return (
    file &amp;&amp; fs.readJson(path.join(__dirname, &quot;../&quot;, pathOfConfigurationFile))
  );
};

module.exports = (on, config) =&gt; {
  const environment = config.env.configFile || &quot;development&quot;;
  const configurationForEnvironment = fetchConfigurationByFile(environment);

  return configurationForEnvironment || config;
};
</code></pre>
<p>In the above code, <code>Cypress</code> loads the configuration file based on the
environment. When we run <code>Cypress</code> we can pass environment variables. In this
case, we need to pass <code>configFile</code> as an environment variable. If we don't pass
<code>configFile</code>, by default <code>Cypress</code> will consider <code>development</code> as the current
environment.</p>
<h2>3. Setup scripts</h2>
<p>Cypress can accept command-line arguments. We can set the environment by passing
these arguments in the <code>cypress run</code> or <code>cypress open</code> command e.g.
<code>cypress open --env configFile=test</code>. This command looks lengthy. Also,
sometimes we need to pass more command-line arguments along with <code>configFile</code>.
We can create short and handy commands by configuring the <code>package.json</code>.</p>
<p>For example: <code>yarn run cy:open:dev</code>.</p>
<pre><code class="language-javascript">// cypress/package.json

&quot;cy:open:dev&quot;: &quot;cypress open --env configFile=development&quot;,
&quot;cy:open:dev:chrome&quot;: &quot;cypress open --browser chrome --env configFile=development&quot;,
&quot;cy:run:dev&quot;: &quot;cypress run --env configFile=development&quot;,
&quot;cy:open:staging&quot;: &quot;cypress open --env configFile=test&quot;,
&quot;cy:run:staging&quot;: &quot;cypress run --env configFile=test&quot;,
</code></pre>
<h2>4. Precedence of configuration</h2>
<p>By default, we have <code>cypress.json</code> in Cypress where some config can be added.
The precedence of configuration is higher for the files in the <code>config</code> folder
than the <code>cypress.json</code>. So if we have some key <code>execTimeout</code> defined in both
<code>cypress.json</code> and <code>cypress.test.json</code>. The value of <code>execTimeout</code> in the
<code>cypress.test.json</code> will be considered.</p>
<p>Generally, the rule of thumb is that a common configuration for all the
environments can be kept in the <code>cypress.json</code>. The environment-specific config
can be kept in <code>config/</code> folder.</p>
<h2>Conclusion</h2>
<p>We saw that how we can configure the cypress in multiple environments. In this
way we can run Cypress for each environment without much hassle. This definitely
helps us in running Cypress in both local as well as in the production
environment.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Using Cookies with Postgraphile]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/cookies-with-postgraphile"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/cookies-with-postgraphile.png"/>
      <id>https://www.bigbinary.com/blog/cookies-with-postgraphile</id>
      <published>2021-06-01T00:00:00.000Z</published>
      <updated>2021-06-01T00:00:00.000Z</updated>
      <author>
        <name>Agney Menon</name>
        <uri>https://www.bigbinary.com/blog/authors/agneym</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/cookies-with-postgraphile.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Tutorial on reading and setting cookies on Postgraphile]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/cookies-with-postgraphile"><![CDATA[<p>This blog details usage of cookies on a Postgraphile-based application. We will
be using Postgraphile with Express for processing the cookies, but any similar
library can be used.</p>
<p>Cookies can be a very safe method for storage on the client side. They can be
set as:</p>
<ul>
<li>HTTP only: cannot be accessed through client-side JavaScript, saving it from
any third party client-side scripts or web extensions.</li>
<li>Secure: The web browser ensures that the cookies are set only on a <em>secure</em>
channel.</li>
<li>Signed: We can sign the content to make sure it isn't changed on the client
side.</li>
<li>Same Site: Make sure that the cookie is sent only if the site matches your
domain/subdomain (<a href="https://web.dev/samesite-cookies-explained/">details</a>)</li>
</ul>
<h2>Prerequisites</h2>
<ul>
<li>Postgraphile - Generates an instant GraphQL API from a Postgres database</li>
<li>Express - Minimalistic backend framework for NodeJS</li>
</ul>
<h2>Setup</h2>
<p>We will start off with a base Express setup generated with
<a href="https://expressjs.com/en/starter/generator.html">express-generator</a>.</p>
<pre><code class="language-javascript">const createError = require(&quot;http-errors&quot;);
const express = require(&quot;express&quot;);
const path = require(&quot;path&quot;);
const cookieParser = require(&quot;cookie-parser&quot;);
const logger = require(&quot;morgan&quot;);

const app = express();

require(&quot;dotenv&quot;).config();

app.use(logger(&quot;dev&quot;));
app.use(express.json());
app.use(express.urlencoded({ extended: false }));
app.use(express.static(path.join(__dirname, &quot;public&quot;)));

// Use secret key to sign the cookies on creation and parsing
app.use(cookieParser(process.env.SECRET_KEY));

// Catch 404 and forward to error handler
app.use(function (req, res, next) {
  next(createError(404));
});

// Error handler
app.use(function (err, req, res) {
  // Set locals, only providing error in development
  res.locals.message = err.message;
  res.locals.error = req.app.get(&quot;env&quot;) === &quot;development&quot; ? err : {};

  // Render the error page
  res.status(err.status || 500);
  res.render(&quot;error&quot;);
});

module.exports = app;
</code></pre>
<p>From
<a href="https://www.graphile.org/postgraphile/usage-library/">Postgraphile's usage library page</a>
for adding Postgraphile to an express app:</p>
<pre><code class="language-javascript">app.use(
  postgraphile(
    process.env.DATABASE_URL || &quot;postgres://user:pass@host:5432/dbname&quot;,
    &quot;public&quot;,
    {
      watchPg: true,
      graphiql: true,
      enhanceGraphiql: true,
    }
  )
);
</code></pre>
<p>Now for the table setup. We need a private <code>user_accounts</code> table and a method
named <code>authenticate_user</code> that will return a JWT token of the form:</p>
<pre><code>{
  token: 'jwt_token_here',
  username: '',
  ...anyOtherDetails
}
</code></pre>
<p>We will not be detailing table creation or authentication as there are many ways
to go about it. But if you need help,
<a href="https://www.graphile.org/postgraphile/security/">Postgraphile security</a> is the
page to rely on.</p>
<h2>Adding the Plugin library</h2>
<p>To attach a cookie to the request, we will use the <code>@graphile/operation-hooks</code>
library which is open-sourced
<a href="https://github.com/graphile/operation-hooks">on Github</a>.</p>
<pre><code class="language-bash">npm install @graphile/operation-hooks
# OR
yarn add @graphile/operation-hooks
</code></pre>
<p>To add the library to the app:</p>
<pre><code class="language-javascript">const { postgraphile, makePluginHook } = require(&quot;postgraphile&quot;);

const pluginHook = makePluginHook([
  require(&quot;@graphile/operation-hooks&quot;).default,
  // Any more PostGraphile server plugins here
]);

app.use(
  postgraphile(
    process.env.DATABASE_URL || &quot;postgres://user:pass@host:5432/dbname&quot;,
    &quot;public&quot;,
    {
      watchPg: true,
      graphiql: true,
      enhanceGraphiql: true,
      pluginHook,
      appendPlugins: [
        // You will be adding the hooks here
      ],
    }
  )
);
</code></pre>
<h2>Adding the Plugin</h2>
<p>The plugin allows for two different types of hooks:</p>
<ol>
<li><a href="https://github.com/graphile/operation-hooks#sql-hooks">SQL Hooks</a></li>
<li><a href="https://github.com/graphile/operation-hooks#implementing-operation-hooks-in-javascript">JavaScript Hooks</a></li>
</ol>
<p>Since accessing cookies is a JavaScript operation, we will be concentrating on
the second type.</p>
<p>To hook the plugin into the build system, we can use the <code>addOperationHook</code>
method.</p>
<pre><code class="language-javascript">module.exports = function OperationHookPlugin(builder) {
  builder.hook(&quot;init&quot;, (_, build) =&gt; {
    // Register our operation hook (passing it the build object):
    // setAuthCookie is a function we will define later.
    build.addOperationHook(useAuthCredentials(build));

    // Graphile Engine hooks must always return their input or a derivative of
    // it.
    return _;
  });
};
</code></pre>
<p>If this is contained in a file named <code>set-auth-cookie.js</code>, then the plugin can
be added to the append plugins array as follows:</p>
<pre><code class="language-javascript">{
  appendPlugins: [
    require('./set-auth-cookie.js'),
  ],
}
</code></pre>
<h2>Designing the hook</h2>
<p>The function to be executed receives two arguments: <code>build</code> process and the
current <code>fieldContext</code>.</p>
<p>The <code>fieldContext</code> consists of fields that can be used to narrow down the
mutation or query that we want to target; e.g. if the hook is to run only on
mutations, we can use the <code>fieldContext.isRootMutation</code> field.</p>
<pre><code class="language-javascript">const useAuthCredentials = build =&gt; fieldContext =&gt; {
  const { isRootMutation } = fieldContext;
  if (!isRootMutation) {
    // No hook added here
    return null;
  }
};
</code></pre>
<p>To direct the system on usage of the plugin, we have to return an object with
<code>before</code>, <code>after</code> or <code>error</code> fields. Here is how these keywords can be used:</p>
<p>(comments are from
<a href="https://github.com/graphile/operation-hooks-example/blob/master/hooks/logger.js">the example repository</a>)</p>
<pre><code class="language-javascript">return {
  // An optional list of callbacks to call before the operation
  before: [
    // You may register more than one callback if you wish. They will be mixed in with the callbacks registered from other plugins and called in the order specified by their priority value.
    {
      // Priority is a number between 0 and 1000. If you're not sure where to put it, then 500 is a great starting point.
      priority: 500,
      // This function (which can be asynchronous) will be called before the operation. It will be passed a value that it must return verbatim. The only other valid return is `null` in which case an error will be thrown.
      callback: logAttempt,
    },
  ],

  // As `before`, except the callback is called after the operation and will be passed the result of the operation; you may return a derivative of the result.
  after: [],

  // As `before`; except the callback is called if an error occurs; it will be passed the error and must return either the error or a derivative of it.
  error: [],
};
</code></pre>
<p>Since we want our action to happen after we get result from the mutation, we
will add it to the <code>after</code> array.</p>
<pre><code class="language-javascript">const useAuthCredentials = build =&gt; fieldContext =&gt; {
  const { isRootMutation, pgFieldIntrospection } = fieldContext;
  if (!isRootMutation) {
    // No hook added here
    return null;
  }

  if (
    !pgFieldIntrospection ||
    // Name of the mutation is authenticateUser
    pgFieldIntrospection.name !== &quot;authenticateUser&quot;
  ) {
    // narrowing the scope down to the mutation we want
    return null;
  }

  return {
    before: [],
    after: [
      {
        priority: 1000,
        callback: (result, args, context) =&gt; {
          // The result is here, so we can access accessToken and username.
          console.log(result);
        },
      },
    ],
    error: [],
  };
};
</code></pre>
<p>Since the functionality is inside the plugin hook, we do not have the express
result to set the cookie 😞.</p>
<p>But we do have an escape hatch with the third argument: <code>context</code>. Postgraphile
allows us to pass functions or values into the context variable from the
postgraphile instance.</p>
<pre><code class="language-javascript">app.use(
  postgraphile(process.env.DATABASE_URL, &quot;public&quot;, {
    async additionalGraphQLContextFromRequest(req, res) {
      return {
        // Function to set the cookie passed into the context object
        setAuthCookie: function (authCreds) {
          res.cookie(&quot;app_creds&quot;, authCreds, {
            signed: true,
            httpOnly: true,
            secure: true,
            // Check if you want to include SameSite cookies here, depending on your hosting.
          });
        },
      };
    },
  })
);
</code></pre>
<p>We can now set the cookie inside the plugin hook.</p>
<pre><code class="language-javascript">{
  priority: 1000,
  callback: (result, args, context) =&gt; {
    // This function is passed from additionalGraphQLContextFromRequest as detailed in the snippet above
    context.setAuthCookie(result);
  }
}
</code></pre>
<h2>Reading from the Cookie 🍪</h2>
<p>We have already added the <code>cookieParser</code> with <code>SECRET_KEY</code>, so express will
parse the cookies for us.</p>
<p>But we probably want them to be accessible inside SQL functions for
Postgraphile. That is how we can determine if the user is signed in or what
their permissions are. To do that, Postgraphile provides a <code>pgSettings</code> object.</p>
<pre><code class="language-javascript">app.use(
  postgraphile(process.env.DATABASE_URL, &quot;public&quot;, {
    pgSettings: async req =&gt; ({
      user: req.signedCookies[&quot;app_creds&quot;],
    }),
  })
);
</code></pre>
<p>Inside an SQL function, the variables passed from settings can be accessed like
this:</p>
<pre><code class="language-sql">current_setting('user')
</code></pre>
<hr>
<p>That's all 🎉. We can store any details in cookies, retrieve them on the Express
end and use them inside Postgres functions for authentication or authorization.</p>
<p>Check out <a href="https://github.com/graphile/operation-hooks">operation-hooks</a> plugin
for more details.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Authorization in REST vs Postgraphile]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/authorization-in-rest-vs-postgraphile"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/authorization-in-rest-vs-postgraphile.png"/>
      <id>https://www.bigbinary.com/blog/authorization-in-rest-vs-postgraphile</id>
      <published>2021-01-20T00:00:00.000Z</published>
      <updated>2021-01-20T00:00:00.000Z</updated>
      <author>
        <name>Amal Jose</name>
        <uri>https://www.bigbinary.com/blog/authors/amaljosea</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/authorization-in-rest-vs-postgraphile.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Postgraphile is a great tool for making instant GraphQL from a PostgreSQL database. When I started working with Postgraphile, its authorization part felt a bit different compared to the REST based...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/authorization-in-rest-vs-postgraphile"><![CDATA[<p><a href="https://www.graphile.org/postgraphile/">Postgraphile</a> is a great tool for
making instant GraphQL from a PostgreSQL database. When I started working with
Postgraphile, its authorization part felt a bit different compared to the REST
based backends which I had worked with before. Here I will share some
differences that I noted.</p>
<p>First, let's see <strong>Authentication</strong> vs <strong>Authorization</strong>.</p>
<p><strong>Authentication</strong> is determining whether a user is logged in or not.
<strong>Authorization</strong> is then deciding what the users has permission to do or see.</p>
<h2>Comparing the implementation of a blog application using Postgraphile vs REST</h2>
<p>Suppose we have to build a blog application with the below schema.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2021/authorization-in-rest-vs-postgraphile/blog-application.png" alt="event delegation"></p>
<h6>Features of the blog application.</h6>
<ul>
<li>
<p>Display <strong>published</strong> blogs with <strong>is_published = true</strong> to all users.</p>
</li>
<li>
<p>Display <strong>unpublished</strong> blogs with <strong>is_published = false</strong> to its creator
only.</p>
</li>
</ul>
<h2>REST Implementation</h2>
<p>The REST implementation with JavaScript and
<a href="https://sequelize.org/master/manual/model-querying-basics.html">sequelize</a> can
be like below.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2021/authorization-in-rest-vs-postgraphile/rest-implementation.jpeg" alt="REST implementation"></p>
<p>The <strong>client</strong> requests the blogs using an endpoint, it also attaches the access
token received from the authentication service.</p>
<pre><code class="language-js">const getBlogs = () =&gt;
  requestData({
    endpoint: `/api/blogs`,
    accessToken: &quot;***&quot;,
  });
</code></pre>
<p>The backend code in the <strong>server</strong> receives the request, finds the current
logged in user from the access token, and requests the data based on the current
logged in user from the database.</p>
<pre><code class="language-js">const userEmail = findEmail(accessToken);
const blogs = await models.Blogs.findAll({
  where: { [Op.or]: [{ creatorEmail: userEmail }, { isPublished: true }] },
});

res.send(blogs);
</code></pre>
<p>Here, the backend code finds the user’s email from the access token, then
requests the database to give the list of blogs that have creatorEmail matching
to the current user's email or the field isPublished is true.</p>
<p>The <strong>database</strong> will return whatever data the server requests.</p>
<p>Similarly, for creating, editing, and deleting blogs, we can have different
end-points to handle the authorization logic in the backend code.</p>
<h2>Postgraphile Implementation</h2>
<p>The postgraphile implementation can be like below.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2021/authorization-in-rest-vs-postgraphile/postgraphile-implementation.jpeg" alt="postgraphile implementation"></p>
<p>The <strong>client</strong> requests the blogs using a GraphQL query. It also attaches the
access token received from the authentication service.</p>
<pre><code class="language-js">const data = requestQuery({
 query: &quot;allBlogs {
         nodes {
            content
            creatorEmail
            visiblityType
           }
        }&quot;
 accessToken: '***'
})
</code></pre>
<p>In the <strong>server,</strong> we configure Postgraphile to pass the user information to the
database.</p>
<pre><code class="language-js">export postgraphile(DATABASE_URL, schemaName, {
  pgSettings: (req) =&gt; {
     const userEmail = findEmail(accessToken);
     return({
         'current_user_email': userEmail
     })
  }
})
</code></pre>
<p>We can pass a function as Postgraphile’s pg
<a href="https://www.graphile.org/postgraphile/usage-library/#pgsettings-function">Settings</a>
property, whose return value will be accessible from the connected Postgres
database by calling the current_setting function.</p>
<p>In the <strong>database,</strong> the row-level security policies can be defined to control
the data access.</p>
<p><a href="https://www.postgresql.org/docs/12/ddl-rowsecurity.html">Row-level security policies</a>
are basically just SQL that either evaluates to true or false. If a policy is
created and enabled for a table, that policy will be checked before doing an
operation on the table.</p>
<pre><code class="language-pgsql">create policy blogs_policy_select
on public.blogs for select to users
USING (
 isPublished OR
 creator_email = current_setting('current_user_email')
);
ALTER TABLE blogs ENABLE ROW LEVEL SECURITY;
</code></pre>
<p>Here the policy named <em>blogs_policy_select</em> will be checked before selecting a
row in the table <em>public.blogs.</em> A row will be selected only if the
<em>isPublished</em> field is <em>true</em> or <em>creator_email</em> matches with the current user's
email.</p>
<p>Similarly, for creating, editing, and deleting blogs, we can have row level
security policies for INSERT, UPDATE, and DELETE operations on the table.</p>
<h2>Conclusion</h2>
<p>The REST implementation does the authorization on the server level but the
Postgraphile does it on the database level. Each implementation has its own
advantages and disadvantages, which is a topic for another day.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Sort query data on associated table in PostGraphile]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/sort-query-data-on-associated-tables-in-postgraphile-using-order-by-plugin"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/sort-query-data-on-associated-tables-in-postgraphile-using-order-by-plugin.png"/>
      <id>https://www.bigbinary.com/blog/sort-query-data-on-associated-tables-in-postgraphile-using-order-by-plugin</id>
      <published>2021-01-19T00:00:00.000Z</published>
      <updated>2021-01-19T00:00:00.000Z</updated>
      <author>
        <name>Taha Husain</name>
        <uri>https://www.bigbinary.com/blog/authors/taha</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/sort-query-data-on-associated-tables-in-postgraphile-using-order-by-plugin.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[How to sort query data on associated tables in PostGraphile.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/sort-query-data-on-associated-tables-in-postgraphile-using-order-by-plugin"><![CDATA[<p><a href="https://www.graphile.org/postgraphile/">PostGraphile</a> provides sorting on all
columns of a table in a GraqhQL query by default with <code>orderBy</code> argument.</p>
<p>Although, sorting based on associated table’s columns or adding a custom sort
can be achieved via plugins. In this blog we will explore two such plugins.</p>
<h3>Using <code>pg-order-by-related</code> plugin</h3>
<p><a href="https://github.com/graphile-contrib/pg-order-by-related">pg-order-by-related</a>
plugin allows us to sort query result based on associated table's columns. It
does that by adding enums for all associated table's columns. Here's what we
need to do to use this plugin.</p>
<h4>Installation</h4>
<pre><code class="language-shell">npm i @graphile-contrib/pg-order-by-related
</code></pre>
<h4>Adding the plugin</h4>
<pre><code class="language-javascript">const express = require(&quot;express&quot;);
const { postgraphile } = require(&quot;postgraphile&quot;);
const PgOrderByRelatedPlugin = require(&quot;@graphile-contrib/pg-order-by-related&quot;);

const app = express();

app.use(
  postgraphile(process.env.DATABASE_URL, &quot;public&quot;, {
    appendPlugins: [PgOrderByRelatedPlugin],
  })
);
</code></pre>
<h4>Using associated table column enum with <code>orderBy</code> argument</h4>
<pre><code class="language-graphql">query getPostsSortedByUserId {
  posts: postsList(orderBy: AUTHOR_BY_USER_ID__NAME_ASC) {
    id
    title
    description
    author: authorByUserId {
      id
      name
    }
  }
}
</code></pre>
<p><code>pg-order-by-related</code> plugin is useful only when we want to sort data based on
first level association. If we want to apply <code>orderBy</code> on second level table
columns or so, we have to use <code>makeAddPgTableOrderByPlugin</code>.</p>
<h3>Using <code>makeAddPgTableOrderByPlugin</code></h3>
<p><a href="https://www.graphile.org/postgraphile/make-add-pg-table-order-by-plugin/">makeAddPgTableOrderByPlugin</a>
allows us to add custom enums that are accessible on specified table's <code>orderBy</code>
argument. We can write our custom select queries using this plugin.</p>
<p>We will use a complex example to understand the use-case of custom <code>orderBy</code>
enum.</p>
<p>In our posts list query, we want posts to be sorted by author's address. Address
has country, state and city columns. We want list to be sorted by country, state
and city in the same order.</p>
<p>Here's how we can achieve this using <code>makeAddPgTableOrderByPlugin</code>.</p>
<p><code>plugins/orderBy/orderByPostAuthorAddress.js</code></p>
<pre><code class="language-javascript">import { makeAddPgTableOrderByPlugin, orderByAscDesc } from &quot;graphile-utils&quot;;

export default makeAddPgTableOrderByPlugin(
  &quot;public&quot;,
  &quot;post&quot;,
  ({ pgSql: sql }) =&gt; {
    const author = sql.identifier(Symbol(&quot;author&quot;));
    const address = sql.identifier(Symbol(&quot;address&quot;));
    return orderByAscDesc(
      &quot;AUTHOR_BY_USER_ID__ADDRESS_ID__COUNTRY__STATE__CITY&quot;,
      ({ queryBuilder }) =&gt; sql.fragment`(
            SELECT
              CONCAT(
                ${address}.city,
                ', ',
                ${address}.state,
                ', ',
                ${address}.country
              ) AS full_address
            FROM public.user as ${author}
            JOIN public.address ${address} ON ${author}.address_id = ${address}.id
            WHERE ${author}.id = ${queryBuilder.getTableAlias()}.user_id
            ORDER BY ${address}.country DESC, ${address}.state DESC, ${address}.city DESC
            LIMIT 1
          )`
    );
  }
);
</code></pre>
<h4>Export all custom <code>orderBy</code> plugins</h4>
<p><code>plugins/orderBy/index.js</code></p>
<pre><code class="language-javascript">export { default as orderByPostAuthorAddress } from &quot;./orderByPostAuthorAddress&quot;;
</code></pre>
<h4>Append custom <code>orderBy</code> plugins to <code>postgraphile</code></h4>
<pre><code class="language-javascript">const express = require(&quot;express&quot;);
const { postgraphile } = require(&quot;postgraphile&quot;);
import * as OrderByPlugins from &quot;./plugins/orderby&quot;;

const app = express();

app.use(
  postgraphile(process.env.DATABASE_URL, &quot;public&quot;, {
    appendPlugins: [...Object.values(OrderByPlugins)],
  })
);
</code></pre>
<h4>Using custom enum with <code>orderBy</code> argument</h4>
<pre><code class="language-graphql">query getPostsSortedByAddress {
  posts: postsList(
    orderBy: AUTHOR_BY_USER_ID__ADDRESS_ID__COUNTRY__STATE__CITY
  ) {
    id
    title
    description
    author: authorByUserId {
      id
      name
      address {
        id
        country
        state
        city
      }
    }
  }
}
</code></pre>
<p>Please head to
<a href="https://github.com/graphile-contrib/pg-order-by-related">pg-order-by-related</a>
and
<a href="https://www.graphile.org/postgraphile/make-add-pg-table-order-by-plugin/">makeAddPgTableOrderByPlugin</a>
pages for detailed documentation.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Setting up wild card SSL on heroku]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/wild-card-ssl-on-heroku"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/wild-card-ssl-on-heroku.png"/>
      <id>https://www.bigbinary.com/blog/wild-card-ssl-on-heroku</id>
      <published>2020-12-01T00:00:00.000Z</published>
      <updated>2020-12-01T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/wild-card-ssl-on-heroku.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Seeting up wild card SSL on heroku]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/wild-card-ssl-on-heroku"><![CDATA[<p>Setting up wild card SSL on heroku can be complicated. Recently I had to set it
up for a new domain and this time I recorded the whole process.</p>
<p>The ssl certificate in this example was bought from namecheap but the same
process would apply for other vendors too.</p>
<p>The video of the whole process is available here.</p>
<p><a href="https://www.youtube.com/watch?v=A6URYtDWZhg"><img src="https://img.youtube.com/vi/A6URYtDWZhg/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=A6URYtDWZhg">Watch on YouTube</a></p>
<h3>Script to generate keys</h3>
<pre><code class="language-bash">openssl req -new -newkey rsa:2048 -nodes -keyout server.key -out server.csr
</code></pre>
<p>When the prompt asks for <code>Common name(full qualified host name)</code> then enter
<code>*.yourdomainname.com</code>. Since we are setting up a wild card certificate it's
important that the common name starts with a <code>*</code>. Otherwise later we are going
to get an error.</p>
<p>Except the above mentioned question the answer to other questions do not matter
at all. You can enter junk values and the SSL will work just fine.</p>
<p>Hit enter when a challenge password is requested.</p>
<h3>Script to generate ssl bundle</h3>
<pre><code class="language-bash">$ cat __neetohelp_net.crt __neetohelp_net.ca-bundle &gt; ssl-bundle.crt
</code></pre>
<p>Note that the order of the crt and bundle files matters when combining them.</p>
<p>Secondly, as shown in the video, we might have to split the combined line. Now
let's examine the contents of the combined file.</p>
<pre><code class="language-bash">$ cat ssl-bundle.crt
</code></pre>
<p>If we see a line like the one below:</p>
<pre><code class="language-plaintext">-----END CERTIFICATE----------BEGIN CERTIFICATE-----
</code></pre>
<p>Then we need to split the line such that <code>END</code> and <code>BEG</code> align vertically like
so:</p>
<pre><code class="language-plaintext">-----END CERTIFICATE-----
-----BEGIN CERTIFICATE-----
</code></pre>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[This is how our workspace looks like]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/this-is-how-our-workspace-looks-like"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/this-is-how-our-workspace-looks-like.png"/>
      <id>https://www.bigbinary.com/blog/this-is-how-our-workspace-looks-like</id>
      <published>2019-09-26T00:00:00.000Z</published>
      <updated>2019-09-26T00:00:00.000Z</updated>
      <author>
        <name>Rishi Mohan</name>
        <uri>https://www.bigbinary.com/blog/authors/rishimohan</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/this-is-how-our-workspace-looks-like.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Sneak peek at remote workspaces setup of team BigBinary]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/this-is-how-our-workspace-looks-like"><![CDATA[<p>BigBinary has been remote and flexible since the start, and it's one of the best
things a company can offer. You don't need to spend hours commuting, you can
work when you feel productive. Working remotely also means that you have the
flexibility of working from Starbucks, from a library or from your home. You can
set up your own workspace at home and still have the office-like feeling.</p>
<p>We recently got a chance to see workspaces of our colleagues and everyone shared
photos of environments they work in on Slack and it was fun seeing everyone's
desk and the setup they have. We thought it would be fun to share a peek at the
home offices we have. Here we go.</p>
<h2>Akhil Gautam</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpeg" alt="BigBinary Remote Workspace"></p>
<h2>Amit Choudhary</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Chimed Palden</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Chirag Shah</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_1.jpg" alt="BigBinary Remote Workspace">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_2.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Ershad Kunnakkadan</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpeg" alt="BigBinary Remote Workspace"></p>
<h2>Mohit Natoo</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Navaneeth PK</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_1.jpg" alt="BigBinary Remote Workspace">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_2.png" alt="BigBinary Remote Workspace"></p>
<h2>Neeraj Singh</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_1.jpg" alt="BigBinary Remote Workspace">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_2.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Nitin Kalasannavar</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Paras Bansal</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Pranav Raj</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Prathamesh Sonpatki</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Rahul Mahale</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Rishi Mohan</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_1.jpg" alt="BigBinary Remote Workspace">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_2.jpg" alt="BigBinary Remote Workspace">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_3.jpg" alt="BigBinary Remote Workspace">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_4.jpg" alt="BigBinary Remote Workspace">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup_5.webp" alt="BigBinary Remote Workspace"></p>
<h2>Shibin Madassery</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Sony Mathew</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Sunil Kumar</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Tyler and Naiara</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Unnikrishnan KP</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
<h2>Vishal Telangre</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/this-is-how-our-workspace-looks-like/setup.jpg" alt="BigBinary Remote Workspace"></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Marketing strategy at BigBinary]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/marketing-strategy-at-bigbinary"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/marketing-strategy-at-bigbinary.png"/>
      <id>https://www.bigbinary.com/blog/marketing-strategy-at-bigbinary</id>
      <published>2019-03-18T00:00:00.000Z</published>
      <updated>2019-03-18T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/marketing-strategy-at-bigbinary.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[BigBinary started in 2011. Here are our revenue numbers for the last 7 years. We achieved this to date without having any outbound marketing and sales strategy. - We have never sent a cold email. -...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/marketing-strategy-at-bigbinary"><![CDATA[<p>BigBinary started in 2011. Here are our revenue numbers for the last 7 years.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2019/marketing-strategy-at-bigbinary/revenue.png" alt="BigBinary revenue"></p>
<p>We achieved this to date without having any outbound marketing and sales
strategy.</p>
<ul>
<li>We have never sent a cold email.</li>
<li>We have never sent a cold LinkedIn message.</li>
<li>The only time we advertised was a period of two months when we tried Google
advertisements, with no outcomes.</li>
<li>We do not sponsor any podcast.</li>
<li>We have not had a sales person.</li>
<li>We have not had a marketing person.</li>
</ul>
<p>We have kept our head down and have focused on what we do best, such as
designing, developing, debugging, devops, and blogging.</p>
<p>This is what has worked out for us so far:</p>
<ul>
<li>We contribute to the community through
<a href="https://blog.bigbinary.com">blog posts</a> and open source.</li>
<li>We sponsor community events like Rails Girls and Ruby Conf India.</li>
<li>We sponsor many React and Ruby meetups.</li>
<li>We focus on keeping our existing clients happy.</li>
</ul>
<p>Over the years I have come across many people who aspire to be freelancers.
While it is not for everyone, I encourage them to give freelancing a try.</p>
<p>The greatest hindrance I have seen is that they stress over sales and marketing,
and as it should be. Being a freelancer means constant need to find your next
client.</p>
<p>I'm not here to say what others ought to do. I'm here to say what has worked out
for BigBinary over the last 7 years.</p>
<p>While we plan to experiment with new forms of marketing, networking, and sales
channel as we grow, it is not the end-all-be-all for freelancers. While
marketing, networking, and sales may be effective for some, it was not how we
started BigBinary and may not be how you want to start as well.</p>
<p>For us at BigBinary, it has been writing blogs. When we come across a
potentially intriguing blog topic, we save the topic by creating a Github issue.
When we have downtime, we pick up a topic from our issues list. It’s as simple
as that and has been our primary driver of growth thus far.</p>
<p>While you should experiment to find out what works best for you, you need to
find out what suits your personality. If you are good at teaching through
videos, consider creating your own YouTube channel. If you contribute to open
source, try creating a blog about your efforts and learnings. If you are good at
concentrating on a niche technology, build your marketing and business around
that.</p>
<p>I can confidently say that majority of people I met and who want to be
freelancer would do fine if they simply share what they are learning. Most of
these people do technical work. Some of them already blog and others can blog. A
blog is a decent start nearly everybody will say. I'm saying that it is a good
end too.</p>
<p>If you do not want to do any other form of marketing then that's fine too. Just
blogging will work out fine for you just like it has worked out fine for us at
BigBinary.</p>
<p>Just because you are going to be a freelancer you don’t have to change who you
are. If you don't like sending cold emails then don't. If you do not like
networking then that’s alright as well. Write personal emails, dump corporate
talk, show compassion and be genuine.</p>
<p>So go on and do some freelancing. It would teach you a lot about software
development, business, life, managing money, creating value and capturing value.
It will be rough at times. And it would be hard at times. But it would also be a
ton of fun.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Resolve foreign key constraint conflict]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/resolve-foreign-key-constraint-conflict-while-copying-data-using-topological-sort"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/resolve-foreign-key-constraint-conflict-while-copying-data-using-topological-sort.png"/>
      <id>https://www.bigbinary.com/blog/resolve-foreign-key-constraint-conflict-while-copying-data-using-topological-sort</id>
      <published>2019-02-05T00:00:00.000Z</published>
      <updated>2019-02-05T00:00:00.000Z</updated>
      <author>
        <name>Narendra Rajput</name>
        <uri>https://www.bigbinary.com/blog/authors/bknarendra</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/resolve-foreign-key-constraint-conflict-while-copying-data-using-topological-sort.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Resolve foreign key constraint conflict while copying data for subset of tables between databases using topological sort]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/resolve-foreign-key-constraint-conflict-while-copying-data-using-topological-sort"><![CDATA[<p>We have a client that uses multi-tenant database
where each database holds data for each of their customers.
Whenever a new customer is added, a service dynamically creates a new database.
In order to seed this new database we were tasked
to implement a feature to copy data from existing &quot;demo&quot; database.</p>
<p>The &quot;demo&quot; database is actually a live client where sales team does demo.
This ensures that the data that is copied is fresh and not stale.</p>
<p>We implemented a solution where we simply listed all the tables in namespace and used <a href="https://github.com/zdennis/activerecord-import">activerecord-import</a>
to copy the table data.
We used <code>activerecord-import</code> gem to keep code agnostic of underlying database as we used different databases in development from production.
Production is &quot;SQL Server&quot; and development database is &quot;PostgreSQL&quot;.
Why this project ended up having different database in development and in production
is worthy of a separate blog.</p>
<p>When we started using the above mentioned strategy then
we quickly ran into a problem.
Inserts for some tables were failing.</p>
<pre><code class="language-plaintext">insert or update on table &quot;dependent_table&quot; violates foreign key constraint &quot;fk_rails&quot;
Detail: Key (column)=(1) is not present in table &quot;main_table&quot;.
</code></pre>
<p>The issue was we had foreign key constraints on some tables and &quot;dependent&quot; table was being processed before the &quot;main&quot; table.</p>
<p>So initially we thought of simply hard coding the sequence in which to process the tables. It means if any new table is added then we will have to update the service to include the newly added table. So we needed a way to identify the foreign key dependencies and determine the sequence to copy the tables at runtime. To resolve this issue, we thought of using
<a href="https://en.wikipedia.org/wiki/Topological_sorting">Topological Sorting</a>.</p>
<h2>Topological Sorting</h2>
<p>To get started we need the list of dependencies of &quot;main&quot; and &quot;dependent&quot; tables.
In Postgresql, this sql query fetches the table dependencies.</p>
<pre><code class="language-sql">SELECT
    tc.table_name AS dependent_table,
    ccu.table_name AS main_table
FROM
    information_schema.table_constraints AS tc
    JOIN information_schema.key_column_usage AS kcu
      ON tc.constraint_name = kcu.constraint_name
      AND tc.table_schema = kcu.table_schema
    JOIN information_schema.constraint_column_usage AS ccu
      ON ccu.constraint_name = tc.constraint_name
      AND ccu.table_schema = tc.table_schema
WHERE constraint_type = 'FOREIGN KEY'
and (tc.table_name like 'namespace_%' or ccu.table_name like 'namespace_%');

=&gt; dependent_table  | main_table
-----------------------------------
   dependent_table1 | main_table1
   dependent_table2 | main_table2
</code></pre>
<p>The above query fetches all the dependencies for only the tables have namespace or the tables we are interested in.
The output of above query was <code>[[dependent_table1, main_table1], [dependent_table2, main_table2]]</code>.</p>
<p>Ruby has a <code>TSort</code> module that for implementing topological sorts.
So we needed to run the topological sort on the dependencies. So we inserted the dependencies into a hash and included the <code>TSort</code> functionality into the hash. Following is the way to include the <code>TSort</code> module into hash by subclassing the <code>Hash</code>.</p>
<pre><code class="language-ruby">require &quot;tsort&quot;

class TsortableHash &lt; Hash
  include TSort

  alias tsort_each_node each_key

  def tsort_each_child(node, &amp;block)
    fetch(node).each(&amp;block)
  end
end
# Borrowed from https://www.viget.com/articles/dependency-sorting-in-ruby-with-tsort/
</code></pre>
<p>Then we simply added all the tables to dependency hash, as below</p>
<pre><code class="language-ruby">tables_to_sort = [&quot;dependent_table1&quot;, &quot;dependent_table2&quot;, &quot;main_table1&quot;]
dependency_graph = tables_to_sort.inject(TsortableHash.new) {|hash, table| hash[table] = []; hash }

table_dependency_map = fetch_table_dependencies_from_database
=&gt; [[&quot;dependent_table1&quot;, &quot;main_table1&quot;], [&quot;dependent_table2&quot;, &quot;main_table2&quot;]]

# Add missing tables to dependency graph
table_dependency_map.flatten.each {|table| dependency_graph[table] ||= [] }

table_dependency_map.each {|constraint| dependency_graph[constraint[0]] &lt;&lt; constraint[1] }

dependency_graph.tsort
=&gt; [&quot;main_table1&quot;, &quot;dependent_table1&quot;, &quot;main_table2&quot;, &quot;dependent_table2&quot;]
</code></pre>
<p>The output above, is the dependency resolved sequence of tables.</p>
<p>Topological sorting is pretty useful in situations where we need to resolve dependencies and Ruby provides a really helpful tool <code>TSort</code> to implement it without going into implementation details. Although I did spend time in understanding the underlying algorithm for fun.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Inline Installation of Firefox Extension]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/inline-installation-of-firefox-extension"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/inline-installation-of-firefox-extension.png"/>
      <id>https://www.bigbinary.com/blog/inline-installation-of-firefox-extension</id>
      <published>2018-09-27T00:00:00.000Z</published>
      <updated>2018-09-27T00:00:00.000Z</updated>
      <author>
        <name>Chirag Shah</name>
        <uri>https://www.bigbinary.com/blog/authors/chiraggshah</uri>
      </author>
      <category term="JavaScript"/>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/inline-installation-of-firefox-extension.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[The blog explains how to enable inline installation of a Firefox extension's latest version]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/inline-installation-of-firefox-extension"><![CDATA[<h2>Inline Installation</h2>
<p>Firefox extensions,
similar to Chrome extensions,
help us modify
and
personalize our browsing experience
by adding new features
to the existing sites.</p>
<p>Once we've published
our extension to the
<a href="https://addons.mozilla.org/">Mozilla's Add-on store(AMO)</a>,
users who browse the AMO
can find the extension
and install it with one-click.
But,
if a user is already on our site
where a link is provided
to the extension's AMO listing page,
they would need to
navigate away from our
website to the AMO,
complete the install process,
and then return back to our site.
That is a bad user experience.</p>
<p>The inline installation enables us to
initiate the extension installation
from our site.
The extension can still be hosted on the AMO
but users
would no longer have to
leave our site to install it.</p>
<p>We had to try out a few suggested approaches
before we got it working.</p>
<h2>InstallTrigger</h2>
<p><code>InstallTrigger</code> (Link is not available)
is an interface
included in the Mozilla's Apps API
for installing extensions.
Using JavaScript,
the <code>install</code> method
of <code>InstallTrigger</code> can be used
to start the download and installation
of an extension (or anything packaged in a .xpi file)
from a Web page.</p>
<p>A XPI(pronounced as &quot;zippy&quot;)
is similar to a zip file,
which contains manifest file and
the install script for the extension.</p>
<p>So, let's try to install the
Grammarly Extension for Firefox.
To use it,
we first need its .xpi file's location.
Once we have published our extension on the AMO,
we can navigate to the listings page
for it and get the link for the .xpi.</p>
<p>For our present example,
here's the listing page for
<a href="https://addons.mozilla.org/en-US/firefox/addon/grammarly-1/">Grammarly Extension</a>.</p>
<p>Here,
we can get the .xpi file's location
by right clicking on the
<code>+ Add to Firefox</code> button
and clicking on <code>Copy Link Location</code>.
Note that the <code>+ Add to Firefox</code> button
would only be visible
if we browse the link on a Firefox browser.
Otherwise, it would be replaced by
a <code>Get Firefox Now</code> button.</p>
<p>Once we have the URL,
we can trigger the installation via JavaScript
on our web page.</p>
<pre><code class="language-javascript">InstallTrigger.install({
  &quot;Name of the Extension&quot;: {
    URL: &quot;url pointing to the .xpi file's location on AMO&quot;,
  },
});
</code></pre>
<h2>Pointing to the latest version of the Extension</h2>
<p>When we used the URL in the above code,
the .xpi file's URL
was specific to the extension's current version.
If the extension has an update,
the installed extensions for existing users
would be updated automatically.
But the URL to the .xpi on our website
would be pointing to the older version.
Although the old link would still work,
we would always want new users to download
the latest version.</p>
<p>To do that,
we can either fetch the listing page
in the background and parse the HTML
to get the latest link.
But that approach can break if the HTML changes.</p>
<p>Or we can query the Addons Services API,
which returns the information for the extension in XML format.</p>
<p>For the Grammarly Extension, we first need its slug-id.
We can get it by looking at its listing page's URL.
From <code>https://addons.mozilla.org/en-US/firefox/addon/grammarly-1/</code>,
we can note down the slug which is <code>grammarly-1</code></p>
<p>Using this slug id, we can now get the extension details using
<code>https://services.addons.mozilla.org/en-US/firefox/api/1.5/addon/grammarly-1</code>.
It returns the info for the Grammarly Extension.
What we are particularly interested in is the value in the <code>&lt;install&gt;</code> node.
That is what the desired value is for the latest version for our .xpi.</p>
<p>Let's see how we can implement the whole thing using React.</p>
<pre><code class="language-javascript">import axios from &quot;axios&quot;;
import cheerio from &quot;cheerio&quot;;

const FALLBACK_GRAMMARLY_EXTENSION_URL =
  &quot;https://addons.mozilla.org/firefox/downloads/file/1027073/grammarly_for_firefox-8.828.1757-an+fx.xpi&quot;;
const URL_FOR_FETCHING_XPI = `https://services.addons.mozilla.org/en-US/firefox/api/1.5/addon/grammarly-1`;

export default class InstallExtension extends Component {
  state = {
    grammarlyExtensionUrl: FALLBACK_GRAMMARLY_EXTENSION_URL,
  };

  componentWillMount() {
    axios.get(URL_FOR_FETCHING_XPI).then((response) =&gt; {
      const xml = response.data;
      const $ = cheerio.load(xml);
      const grammarlyExtensionUrl = $(&quot;addon install&quot;).text();
      this.setState({ grammarlyExtensionUrl });
    });
  }

  triggerInlineInstallation = (event) =&gt; {
    InstallTrigger.install({
      Grammarly: { URL: this.state.grammarlyExtensionUrl },
    });
  };

  render() {
    return (
      &lt;Button onClick={this.triggerInlineInstallation}&gt;
        Install Grammarly Extension
      &lt;/Button&gt;
    );
  }
}
</code></pre>
<p>In the above code,
we are using the npm packages
<a href="https://github.com/axios/axios">axios</a>
for fetching the xml and
<a href="https://github.com/cheeriojs/cheerio">cheerio</a>
for parsing the xml.
Also, we have set a fallback URL as the initial value
in case the fetching of the new URL
from the xml response fails.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Debug failing puppeteer tests due to background tab]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/debugging-failing-tests-in-background-tab-in-puppeteer"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/debugging-failing-tests-in-background-tab-in-puppeteer.png"/>
      <id>https://www.bigbinary.com/blog/debugging-failing-tests-in-background-tab-in-puppeteer</id>
      <published>2018-08-15T00:00:00.000Z</published>
      <updated>2018-08-15T00:00:00.000Z</updated>
      <author>
        <name>Rohit Kumar</name>
        <uri>https://www.bigbinary.com/blog/authors/rkr090</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/debugging-failing-tests-in-background-tab-in-puppeteer.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Debugging failing tests in puppeteer because of background tab]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/debugging-failing-tests-in-background-tab-in-puppeteer"><![CDATA[<p>We have been using puppeteer in one of our projects to write end-to-end tests.
We run our tests in headful mode to see the browser in action.</p>
<p>If we start puppeteer tests and do nothing in our laptop (just watch the tests
being executed) then all the tests will pass.</p>
<p>However if we are doing our regular work in our laptop while tests are running
then tests would fail randomly. This was quite puzzling.</p>
<p>Debugging such flaky tests is hard. We first suspected that the test cases
themselves needed more of implicit waits for element/text to be present/visible
on the DOM.</p>
<p>After some debugging using puppeteer protocol logs, it seemed like the browser
was performing certain actions very slowly or was waiting for the browser to be
active ( in view ) before performing those actions.</p>
<p>Chrome starting with version 57 introduced
<a href="https://developers.google.com/web/updates/2017/03/background_tabs">throttling of background tabs</a>
for improving performance and battery life. We execute one test per browser
meaning we didn't make use of multiple tabs. Also tests failed only when the
user was performing some other activities while the tests were executing in
other background windows.
<a href="https://developer.mozilla.org/en-US/docs/Web/API/Page_Visibility_API">Pages were hidden</a>
only when user switched tabs or minimized the browser window containing the tab.</p>
<p>After observing closely we noticed that the pages were making requests to the
server. The issue was the page was not painting if the page is not in view. We
added flag <code>--disable-background-timer-throttling</code> but we did not notice any
difference.</p>
<p>After doing some searches we noticed the flag <code>--disable-renderer-backgrounding</code>
was being used in
<a href="https://github.com/karma-runner/karma-chrome-launcher/blob/01c7efc870e64733d81347d4996fb9bcbf099825/index.js#L42-L46">karma-launcher</a>.
The comment states that it is specifically required on macOS. Here is the
<a href="https://cs.chromium.org/chromium/src/content/browser/renderer_host/render_widget_host_impl.cc?l=684-689">code</a>
responsible for lowering the priority of the renderer when it is hidden.</p>
<p>But the new flag didn't help either.</p>
<p>While looking at all the available command line switches for chromium, we
stumbled upon <code>--disable-backgrounding-occluded-windows</code>. Chromium also
backgrounds the renderer while the window is not visible to the user. It seems
from the comment that the flag
<a href="https://cs.chromium.org/chromium/src/content/public/common/content_switches.cc?l=99-102">kDisableBackgroundingOccludedWindowsForTesting</a>
is specifically added to avoid non-deterministic behavior during tests.</p>
<p>We have added following flags to chromium for running our integration suite and
this solved our problem.</p>
<pre><code class="language-js">const chromeArgs = [
  &quot;--disable-background-timer-throttling&quot;,
  &quot;--disable-backgrounding-occluded-windows&quot;,
  &quot;--disable-renderer-backgrounding&quot;,
];
</code></pre>
<p>References</p>
<ul>
<li><a href="https://docs.google.com/document/d/18_sX-KGRaHcV3xe5Xk_l6NNwXoxm-23IOepgMx4OlE4/pub">Background tabs &amp; offscreen frames </a></li>
<li><a href="https://www.chromium.org/developers/design-documents/mac-occlusion">Mac Window Occlusion API Use</a></li>
</ul>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Auto-format Elm code with elm-format before commit]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/format-your-elm-code-with-elm-format-before-committing"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/format-your-elm-code-with-elm-format-before-committing.png"/>
      <id>https://www.bigbinary.com/blog/format-your-elm-code-with-elm-format-before-committing</id>
      <published>2018-07-09T00:00:00.000Z</published>
      <updated>2018-07-09T00:00:00.000Z</updated>
      <author>
        <name>Ritesh Pillai</name>
        <uri>https://www.bigbinary.com/blog/authors/ritesh</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/format-your-elm-code-with-elm-format-before-committing.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Automatically Format your Elm code with elm-format before committing]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/format-your-elm-code-with-elm-format-before-committing"><![CDATA[<p>In one of our earlier posts
<a href="https://blog.bigbinary.com/2017/06/12/using-prettier-and-rubocop-in-ruby-on-rails-to-format-javascript-css-ruby-files.html">we talked about</a>
how we set up <a href="https://github.com/prettier/prettier">prettier</a> and
<a href="https://github.com/bbatsov/rubocop">rubocop</a> to automatically format our
JavaScript and Ruby code on git commit.</p>
<p>Recently we started working with Elm in a couple of our projects -
<a href="https://github.com/bigbinary/apisnapshot">APISnapshot</a> and
<a href="https://github.com/bigbinary/acehelp">AceHelp</a>.</p>
<p>Tools like prettier and rubocop have really helped us take a load off our mind
with regards to formatting code. And one of the very first things we wanted to
sort out when we started doing Elm was pretty printing our Elm code.</p>
<p><a href="https://github.com/avh4/elm-format">elm-format</a> created by
<a href="https://github.com/avh4">Aaron VonderHaar</a> formats Elm source code according to
a standard set of rules based on the official
<a href="http://elm-lang.org/docs/style-guide">Elm Style Guide</a>.</p>
<h2>Automatic code formatting</h2>
<p>Let's setup git hook to automatically take care of code formatting. We can
achieve this much like how we did it in our previous
<a href="https://blog.bigbinary.com/2017/06/12/using-prettier-and-rubocop-in-ruby-on-rails-to-format-javascript-css-ruby-files.html">post</a>,
using <a href="https://github.com/typicode/husky/tree/v0.14.3">Husky</a> and
<a href="https://github.com/okonet/lint-staged">Lint-staged</a>.</p>
<p>Let's add Husky and lint-staged as dev dependencies to our project. And for
completeness also include elm-format as a dev dependency.</p>
<pre><code class="language-javascript">npm install --save-dev husky lint-staged elm-format
</code></pre>
<p>Husky makes it real easy to create git hooks. Git hooks are scripts that are
executed by git before or after an event. We will be using the <code>pre-commit</code> hook
which is run after you do a <code>git commit</code> command but before you type in a commit
message.</p>
<p>This way we can change and format files that's about to be committed by running
elm-format using Husky.</p>
<p>But there is one problem here. The changed files do not get added back to our
commit.</p>
<p>This is where Lint-staged comes in. Lint-staged is built to run linters on
staged files. So instead of running elm-format on a pre-commit hook we would run
lint-staged. And we can configure lint-staged such that elm-format is run on all
staged elm files.</p>
<p>We can also include Prettier to take care of all staged JavaScript files too.</p>
<p>Lets do this by editing our <code>package.json</code> file.</p>
<pre><code class="language-json">{
  &quot;scripts&quot;: {
    &quot;precommit&quot;: &quot;lint-staged&quot;
  },
  &quot;lint-staged&quot;: {
    &quot;*.elm&quot;: [&quot;elm-format --yes&quot;, &quot;git add&quot;],
    &quot;*.js&quot;: [&quot;prettier --write&quot;, &quot;git add&quot;]
  }
}
</code></pre>
<p>All set and done!</p>
<p>Now whenever we do a <code>git commit</code> command, all our staged elm and JavaScript
files will get properly formatted before the commit goes in.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Continuous release of a chrome extension using CircleCI]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/continuously-upload-chrome-extension-with-circleci"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/continuously-upload-chrome-extension-with-circleci.png"/>
      <id>https://www.bigbinary.com/blog/continuously-upload-chrome-extension-with-circleci</id>
      <published>2018-06-27T00:00:00.000Z</published>
      <updated>2018-06-27T00:00:00.000Z</updated>
      <author>
        <name>Amit Choudhary</name>
        <uri>https://www.bigbinary.com/blog/authors/amit</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/continuously-upload-chrome-extension-with-circleci.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[We have recently worked on many chrome extensions. Releasing new chrome extensions manually gets tiring after a while. So, we thought about automating it with CircleCI, similar to continuous...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/continuously-upload-chrome-extension-with-circleci"><![CDATA[<p>We have recently worked on many chrome extensions. Releasing new chrome
extensions manually gets tiring after a while.</p>
<p>So, we thought about automating it with CircleCI, similar to continuous
deployment.</p>
<p>We are using the following configuration in <code>circle.yml</code> to continuously release
chrome extensions from the master branch.</p>
<pre><code class="language-yaml">workflows:
  version: 2
  main:
    jobs:
      - test:
          filters:
            branches:
              ignore: []
      - build:
          requires:
            - test
          filters:
            branches:
              only: master
      - publish:
          requires:
            - build
          filters:
            branches:
              only: master

version: 2
jobs:
  test:
    docker:
      - image: cibuilds/base:latest
    steps:
      - checkout
      - run:
          name: &quot;Install Dependencies&quot;
          command: |
            apk add --no-cache yarn
            yarn
      - run:
          name: &quot;Run Tests&quot;
          command: |
            yarn run test
  build:
    docker:
      - image: cibuilds/chrome-extension:latest
    steps:
      - checkout
      - run:
          name: &quot;Install Dependencies&quot;
          command: |
            apk add --no-cache yarn
            apk add --no-cache zip
            yarn
      - run:
          name: &quot;Package Extension&quot;
          command: |
            yarn run build
            zip -r build.zip build
      - persist_to_workspace:
          root: /root/project
          paths:
            - build.zip

  publish:
    docker:
      - image: cibuilds/chrome-extension:latest
    environment:
      - APP_ID: &lt;APP_ID&gt;
    steps:
      - attach_workspace:
          at: /root/workspace
      - run:
          name: &quot;Publish to the Google Chrome Store&quot;
          command: |
            ACCESS_TOKEN=$(curl &quot;https://accounts.google.com/o/oauth2/token&quot; -d &quot;client_id=${CLIENT_ID}&amp;client_secret=${CLIENT_SECRET}&amp;refresh_token=${REFRESH_TOKEN}&amp;grant_type=refresh_token&amp;redirect_uri=urn:ietf:wg:oauth:2.0:oob&quot; | jq -r .access_token)
            curl -H &quot;Authorization: Bearer ${ACCESS_TOKEN}&quot; -H &quot;x-goog-api-version: 2&quot; -X PUT -T /root/workspace/build.zip -v &quot;https://www.googleapis.com/upload/chromewebstore/v1.1/items/${APP_ID}&quot;
            curl -H &quot;Authorization: Bearer ${ACCESS_TOKEN}&quot; -H &quot;x-goog-api-version: 2&quot; -H &quot;Content-Length: 0&quot; -X POST -v &quot;https://www.googleapis.com/chromewebstore/v1.1/items/${APP_ID}/publish&quot;
</code></pre>
<p>We have created three jobs named as <code>test</code>, <code>build</code> and <code>publish</code> and used these
jobs in our workflow to run tests, build the extension, and publish them to the
chrome store, respectively. Every step requires the previous step to run
successfully.</p>
<p>Let's check each job one by one.</p>
<pre><code class="language-yaml">test:
  docker:
    - image: cibuilds/base:latest
  steps:
    - checkout
    - run:
        name: &quot;Install Dependencies&quot;
        command: |
          apk add --no-cache yarn
          yarn
    - run:
        name: &quot;Run Tests&quot;
        command: |
          yarn run test
</code></pre>
<p>We use <a href="https://github.com/cibuilds/base">cibuilds</a> docker image for this job.
First, we do a checkout to the branch and then use <code>yarn</code> to install
dependencies. Alternatively, we can use <code>npm</code> to install dependencies as well.
Then, as the last step, we are use <code>yarn run test</code> to run tests. We can skip
this step if running tests is not needed.</p>
<pre><code class="language-yaml">build:
  docker:
    - image: cibuilds/chrome-extension:latest
  steps:
    - checkout
    - run:
        name: &quot;Install Dependencies&quot;
        command: |
          apk add --no-cache yarn
          apk add --no-cache zip
          yarn
    - run:
        name: &quot;Package Extension&quot;
        command: |
          yarn run build
          zip -r build.zip build
    - persist_to_workspace:
        root: /root/project
        paths:
          - build.zip
</code></pre>
<p>For building chrome extensions, we use the
<a href="https://github.com/cibuilds/chrome-extension">chrome-extension</a> image. Here, we
also first do a checkout and then, install dependencies using yarn. Note, we are
install zip utility along with yarn because we need to zip our chrome extension
before publishing it in next step. Also, we are not generating version numbers
on our own. The version number will be picked from the manifest file. This step
assumes that we have a task named <code>build</code> in <code>package.json</code> to build our app.</p>
<p>The Chrome store rejects multiple uploads with the same version number. So, we
have to make sure to update the version number, which should be unique in the
manifest file before this step.</p>
<p>In the last step, we use <code>persist_to_workspace</code> to make <code>build.zip</code> available
for the next step, publishing.</p>
<pre><code class="language-yaml">publish:
  docker:
    - image: cibuilds/chrome-extension:latest
  environment:
    - APP_ID: &lt;APP_ID&gt;
  steps:
    - attach_workspace:
        at: /root/workspace
    - run:
        name: &quot;Publish to the Google Chrome Store&quot;
        command: |
          ACCESS_TOKEN=$(curl &quot;https://accounts.google.com/o/oauth2/token&quot; -d &quot;client_id=${CLIENT_ID}&amp;client_secret=${CLIENT_SECRET}&amp;refresh_token=${REFRESH_TOKEN}&amp;grant_type=refresh_token&amp;redirect_uri=urn:ietf:wg:oauth:2.0:oob&quot; | jq -r .access_token)
          curl -H &quot;Authorization: Bearer ${ACCESS_TOKEN}&quot; -H &quot;x-goog-api-version: 2&quot; -X PUT -T /root/workspace/build.zip -v &quot;https://www.googleapis.com/upload/chromewebstore/v1.1/items/${APP_ID}&quot;
          curl -H &quot;Authorization: Bearer ${ACCESS_TOKEN}&quot; -H &quot;x-goog-api-version: 2&quot; -H &quot;Content-Length: 0&quot; -X POST -v &quot;https://www.googleapis.com/chromewebstore/v1.1/items/${APP_ID}/publish&quot;
</code></pre>
<p>For publishing of the chrome extension, we use the
<a href="https://github.com/cibuilds/chrome-extension">chrome-extension</a> image.</p>
<p>We need <code>APP_ID</code>, <code>CLIENT_ID</code>, <code>CLIENT_SECRET</code> and
<code>REFRESH_TOKEN</code>/<code>ACCESS_TOKEN</code> to publish our app to the chrome store.</p>
<p><code>APP_ID</code> needs to be fetched from
<a href="https://chrome.google.com/webstore/developer/dashboard">Google Webstore Developer Dashboard</a>.
<code>APP_ID</code> is unique for each app whereas <code>CLIENT_ID</code>, <code>CLIENT_SECRET</code> and
<code>REFRESH_TOKEN</code>/<code>ACCESS_TOKEN</code> can be used for multiple apps. Since <code>APP_ID</code> is
generally public, we specify that in the yml file. <code>CLIENT_ID</code>, <code>CLIENT_SECRET</code>
and <code>REFRESH_TOKEN</code>/<code>ACCESS_TOKEN</code> are stored as private environment variables
using CircleCI UI. For cases when our app is unlisted in the chrome store, we
need to store <code>APP_ID</code> as a private environment variable.</p>
<p><code>CLIENT_ID</code> and <code>CLIENT_SECRET</code> need to be fetched from
<a href="https://console.developers.google.com/">Google API console</a>. There, we need to
select a project and then click on the credentials tab. If there is no project,
we need to create one and then access the credentials tab.</p>
<p><code>REFRESH_TOKEN</code> needs to be fetched from Google API. It also defines the scope
of access for Google APIs. We need to refer to
<a href="https://developers.google.com/identity/protocols/OAuth2WebServer">Google OAuth2</a>
for obtaining the refresh token. We can use any language library.</p>
<p>In the first step of the <code>publish</code> job, we are attaching a workspace to access
<code>build.zip</code>, which was created previously. Now, by using all the required tokens
obtained previously, we need to obtain an access token from Google OAuth API
(Link is not available), which must be used to push the app to the chrome store.
Then, we make a <code>PUT</code> request to the Chrome store API to push the app, and then
use the same API again, to publish the app.</p>
<p>Uploading via API has one more advantage over manual upload. Manual upload
generally takes up to 1 hour to show the app in the chrome store. Whereas
uploading using Google API generally reflects the app within 5-10 minutes,
considering app does not go for a review by Google.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Our Thoughts on iOS 12]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/ios-12"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/ios-12.png"/>
      <id>https://www.bigbinary.com/blog/ios-12</id>
      <published>2018-06-11T00:00:00.000Z</published>
      <updated>2018-06-11T00:00:00.000Z</updated>
      <author>
        <name>Rishi Mohan</name>
        <uri>https://www.bigbinary.com/blog/authors/rishimohan</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/ios-12.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Our favorite features from iOS 12 and a guide on how you can install it on your iPhone]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/ios-12"><![CDATA[<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/ios-12/ios-12-lock-home-screen.png" alt="iOS 12 on iPhone 8 Red"></p>
<p>Apple announced iOS 12 at WWDC 2018 a few days back. Being honest, it was a bit
disappointing to see some of the most requested features not being there in
iOS 12. Like users have been asking for Dark mode since before iOS 11, and the
ability to set default apps. It’s more of an update focussed on performance
improvements, usability, and compatibility. The fact that iOS 12 is also
available for the iPhones Apple released 5 years back is a great effort from
Apple to keep users happy. And unlike last couple of years, this time we decided
to calm our curiosities and installed iOS 12 beta 1 on our devices right away
after Apple released it for developers. This blog is based on our experience
with iOS 12 on iPhone 8 Plus.</p>
<h2>Installing iOS 12 on your iPhone</h2>
<p>First things first, make sure you have iPhone 5s or newer. And before getting
started, plug-in your phone to iTunes and take a full-backup in case your phone
gets bricked while installing iOS 12, which is very unlikely.</p>
<p>Once done, download and install
<a href="https://beta.thuthuatios.com/en/">beta profile</a>{:target=&quot;_blank&quot;} for iOS 12
and then download and update from “Software Update” section just like you
install a regular iOS update. It’s a straightforward OTA update process which
you’re already familiar with.</p>
<p><strong>Note: This beta profile is from a third-party developer and is not officially
from Apple. Apple will officially release public beta in around a month.</strong></p>
<p>We’ve been running iOS 12 since last week now and here are our thoughts on the
additions and changes introduced in iOS 12.</p>
<h3>iOS 12 is fast</h3>
<p>The performance improvements are significant and definitely noticeable.
Previously on iOS 11, while accessing spotlight by swiping down from home
screen, it used to lag. And not just that, sometimes keyboard didn’t even used
to show up and we had to repeat the same action to make it work. But things are
faster and better in iOS 12. The keyboard gets up as soon as spotlight shows up.</p>
<p>Another thing that we’ve noticed is the multitasking shortcut for switching to
the last app by 3d touching on left wasn't that reliable in iOS 11, so much that
it was easy to ignore the feature altogether than to use it, but in iOS 12 the
same shortcut is very smooth. Although there are times when it still doesn’t
work well, but that's very rare.</p>
<p>Spotlight widgets load faster in iOS 12 than they used to in iOS 11. Apart from
this, 3d touch feels pretty smooth too. It’s good to see Apple squeezing out the
power to improve the already good performance in iOS.</p>
<h3>Notifications</h3>
<section>
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/ios-12/ios-12-notifications.png" alt="Notifications in iOS 12">
</section>
<p>Notifications in iOS 11 are a mess, there’s no grouping, there’s no way to
quickly control notifications, there’s no way to set priorities. Apple has added
notifications grouping and better notification management in iOS 12, so now
notifications from the same app are grouped together and you can control how
often you want to get notifications from the apps right from the notification.</p>
<p>We think the implementation can be a whole lot better. For the notifications
that are grouped, you get to see only the last notification from that app, a
better way would’ve been to show two or three notifications and cut the rest.
There’s no Notification pinning or snoozing which could've been very useful
features.</p>
<h3>Screen time and App limits</h3>
<p>There’s a new feature in iOS 12 called Screen Time which is more like bird's-eye
view of your phone usage. There’s a saying that you can’t improve something that
you can’t measure. Screen Time is a feature that’s going to be very useful for
everyone who wants to cut down time on Social apps or overall phone usage. It
shows you every little detail of how many apps you use and for how much time and
at what times. Not only this, it also keeps track of how many times you picked
up your phone, and how many notifications you receive from the apps you have on
your phone.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/ios-12/ios-12-screen-time.png" alt="Screen Time in iOS 12"></p>
<p>Other useful sub-feature of Screen time is App limits, which allows you to set
limit on app usage based on app or category. So let’s say you don’t want to use
WhatsApp for more than 30 mins a day, you can do that through App limits. It
works for app categories including Games, Social Networking, Entertainment,
Creativity, Productivity, Education, Reading &amp; Reference, Health &amp; Fitness. So
you can limit it via category which works across apps. Plus, it syncs across
your other iOS devices, so you can’t cheat that way.</p>
<h3>Siri and Shortcuts app</h3>
<section>
  <img src='https://www.bigbinary.com/blog/images/images_used_in_blog/2018/ios-12/ios-12-siri-shortcuts.png' alt='Siri Shortcuts in iOS 12'>
</section>
<p>In iOS 12, you can assign custom shortcuts to Siri to trigger specific actions,
which not only works for System apps but also with third-party apps. So now if
you want to send a specific message to someone on WhatsApp, you can assign a
command for that to Siri and you can trigger that action just from Siri using
that command.</p>
<p>Apple has also introduced a new app in iOS 12 called Shortcuts. Shortcuts app
lets you group actions and run those actions quickly. Although Shortcuts app
isn’t there in iOS 12 beta 1 but we think it’s one of best addition in iOS 12.</p>
<h3>Updated Photos app</h3>
<p>Photos app now has new section called &quot;For you&quot;, where it shows all the new
Albums, your best moments, share suggestions, photos and effect suggestions.
This is more like the Assistant tab of Google Photos app. Also you can share
selected photos or albums with your friends right from the Photos app.</p>
<p>The Album tab in Photos app is redesigned for easier navigation. Also there's a
new tab for Search which has been advanced, so you can now search photos using
tags like &quot;surfing&quot; and &quot;vacation&quot;.</p>
<p>It's good to see Apple paying attention to up the Photos app but we still think
Google Photos is a better option for average person considering it lets you
store photos in Cloud for free. Also photo organization in Google Photos is much
better than in new Photos app in iOS 12.</p>
<h3>Enhanced Do Not Disturb Mode</h3>
<p>Do Not Disturb in iOS 12 is enhanced to be more flexible. You can now enable Do
Not Disturb mode to end automatically in an hour, or at night, or according to
your Calendar events, or even based on your location.</p>
<p>Not just that, Do Not Disturb has a new <em>Bedtime mode</em> enabling which will shut
all your notifications during bed time and dim your display. And when you will
wake up, it'll show you a welcome back message along with weather details on the
lock screen.</p>
<h3>Conclusion</h3>
<p>There are other updates and under the hood improvements as well, like <em>new
Measure app, redesigned iBooks app, tracking prevention, group FaceTime</em> etc.
Overall, we think it’s an okay update considering there are not as many bugs as
there should be according to Apple standards. The force touch in the keyboard to
drag cursor doesn’t work, Skype and some other apps crash, but for the most
part, it’s good enough to be installed on your primary device.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Modelling state in Elm to reflect business logic]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/modelling-state-in-elm-to-reflect-business-logic"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/modelling-state-in-elm-to-reflect-business-logic.png"/>
      <id>https://www.bigbinary.com/blog/modelling-state-in-elm-to-reflect-business-logic</id>
      <published>2018-06-04T00:00:00.000Z</published>
      <updated>2018-06-04T00:00:00.000Z</updated>
      <author>
        <name>Ritesh Pillai</name>
        <uri>https://www.bigbinary.com/blog/authors/ritesh</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/modelling-state-in-elm-to-reflect-business-logic.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[We recently made ApiSnapshot open source. As mentioned in that blog we ported code from React.js to Elm. One of the features of ApiSnapshot is support for Basic Authentication. While we were...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/modelling-state-in-elm-to-reflect-business-logic"><![CDATA[<p>We recently made
<a href="https://blog.bigbinary.com/2018/05/25/apisnapshot-built-using-elm-and-ruby-on-rails-is-open-source.html">ApiSnapshot open source</a>.
As mentioned in that blog we ported code from React.js to Elm.</p>
<p>One of the features of <code>ApiSnapshot</code> is support for <code>Basic Authentication</code>.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2018/modelling-state-in-elm-to-reflect-business-logic/apisnapshot-with-basic-authentication.png" alt="ApiSnapshot with basic authentication"></p>
<p>While we were rebuilding the whole application in Elm, we had to port the &quot;Add
Basic Authentication&quot; feature. This feature can be accessed from the &quot;More&quot;
drop-down on the right-hand side of the app and it lets user add username and
password to the request.</p>
<p>Let's see how the <code>Model</code> of our Elm app looks.</p>
<pre><code class="language-elm">type alias Model =
{ request : Request.MainRequest.Model
, response : Response.MainResponse.Model
, route : Route
}
</code></pre>
<p>Here is the Model in <em>Request.MainRequest</em> module.</p>
<pre><code class="language-elm">type alias APISnapshotRequest =
{ url : String
, httpMethod : HttpMethod
, requestParameters : RequestParameters
, requestHeaders : RequestHeaders
, username : Maybe String
, password : Maybe String
, requestBody : Maybe RequestBody
}

type alias Model =
{ request : APISnapshotRequest
, showErrors : Bool
}
</code></pre>
<p><code>username</code> and <code>password</code> fields are optional for the users so we kept them as
<code>Maybe</code> types.</p>
<p>Note that API always responds with <code>username</code> and <code>password</code> whether user
clicked to add <code>Basic Authentication</code> or not. The API would respond with a
<strong><em>null</em></strong> for both username and password when a user tries to retrieve a
snapshot for which user did not fill <code>username</code> and <code>password</code>.</p>
<p>Here is a sample API response.</p>
<pre><code class="language-json">{
  &quot;url&quot;: &quot;http://dog.ceo/api/breed/affenpinscher/images/random&quot;,
  &quot;httpMethod&quot;: &quot;GET&quot;,
  &quot;requestParams&quot;: {},
  &quot;requestHeaders&quot;: {},
  &quot;requestBody&quot;: null,
  &quot;username&quot;: &quot;alanturning&quot;,
  &quot;password&quot;: &quot;welcome&quot;,
  &quot;assertions&quot;: [],
  &quot;response&quot;: {
    &quot;response_headers&quot;: {
      &quot;age&quot;: &quot;0&quot;,
      &quot;via&quot;: &quot;1.1 varnish (Varnish/6.0), 1.1 varnish (Varnish/6.0)&quot;,
      &quot;date&quot;: &quot;Thu, 03 May 2018 09:43:11 GMT&quot;,
      &quot;vary&quot;: &quot;&quot;,
      &quot;cf_ray&quot;: &quot;4151c826ac834704-EWR&quot;,
      &quot;server&quot;: &quot;cloudflare&quot;
    },
    &quot;response_body&quot;: &quot;{\&quot;status\&quot;:\&quot;success\&quot;,\&quot;message\&quot;:\&quot;https:\\/\\/images.dog.ceo\\/breeds\\/affenpinscher\\/n02110627_13221.jpg\&quot;}&quot;,
    &quot;response_code&quot;: &quot;200&quot;
  }
}
</code></pre>
<p>Let's look at the view code which renders the data received from the API.</p>
<pre><code class="language-elm">view : (Maybe String, Maybe String) -&gt; Html Msg
view usernameAndPassword =
case usernameAndPassword of
(Nothing, Nothing) -&gt; text &quot;&quot;
(Just username, Nothing) -&gt; basicAuthenticationView username &quot;&quot;
(Nothing, Just password) -&gt; basicAuthenticationView &quot;&quot; password
(Just username, Just password) -&gt; basicAuthenticationView username password

basicAuthenticationView : String -&gt; String -&gt; Html Msg
basicAuthenticationView username password =
[ div [ class &quot;form-row&quot; ]
[ input
[ type_ &quot;text&quot;
, placeholder &quot;Username&quot;
, value username
, onInput (UpdateUsername)
]
[]
, input
[ type_ &quot;password&quot;
, placeholder &quot;Password&quot;
, value password
, onInput (UpdatePassword)
]
[]
, a
[ href &quot;javascript:void(0)&quot;
, onClick (RemoveBasicAuthentication)
]
[ text &quot;×&quot; ]
]
]
</code></pre>
<p>To get the desired view we apply following rules.</p>
<ol>
<li>Check if both the values are string.</li>
<li>Check if either of the values is string.</li>
<li>Assume that both the values are <code>null</code>.</li>
</ol>
<p>This works but we can do a better job of modelling it.</p>
<p>What's happening here is that we were trying to translate our API responses
directly to the Model . Let's try to club username and password together into a
new type called <em>BasicAuthentication</em>.</p>
<p>In the model add a parameter called <em>basicAuthentication</em> which would be of type
<code>Maybe BasicAuthentication</code>. This way if user has opted to use basic
authentication fields then it is a <em>Just BasicAuthentication</em> and we can show
the input boxes. Otherwise it is <em>Nothing</em> and we show nothing!</p>
<p>Here is what the updated Model for <em>Request.MainRequest</em> would look like.</p>
<pre><code class="language-elm">type alias BasicAuthentication =
{ username : String
, password : String
}

type alias APISnapshotRequest =
{ url : String
, httpMethod : HttpMethod
, requestParameters : RequestParameters
, requestHeaders : RequestHeaders
, basicAuthentication : Maybe BasicAuthentication
, requestBody : Maybe RequestBody
}

type alias Model =
{ request : APISnapshotRequest
, showErrors : Bool
}
</code></pre>
<p>Elm compiler is complaining that we need to make changes to JSON decoding for
<em>APISnapshotRequest</em> type because of this change.</p>
<p>Before we fix that let's take a look at how JSON decoding is currently being
done.</p>
<pre><code class="language-elm">import Json.Decode as JD
import Json.Decode.Pipeline as JP

decodeAPISnapshotRequest : Response -&gt; APISnapshotRequest
decodeAPISnapshotRequest hitResponse =
let
result =
JD.decodeString requestDecoder hitResponse.body
in
case result of
Ok decodedValue -&gt;
decodedValue

            Err err -&gt;
                emptyRequest

requestDecoder : JD.Decoder APISnapshotRequest
requestDecoder =
JP.decode Request
|&gt; JP.optional &quot;username&quot; (JD.map Just JD.string) Nothing
|&gt; JP.optional &quot;password&quot; (JD.map Just JD.string) Nothing
</code></pre>
<p>Now we need to derive the state of the application from our API response .</p>
<p>Let's introduce a type called <em>ReceivedAPISnapshotRequest</em> which would be the
shape of our old <em>APISnapshotRequest</em> with no <em>basicAuthentication</em> field. And
let's update our <em>requestDecoder</em> function to return a Decoder of type
<em>ReceivedAPISnapshotRequest</em> instead of <em>APISnapshotRequest</em>.</p>
<pre><code class="language-elm">type alias ReceivedAPISnapshotRequest =
{ url : String
, httpMethod : HttpMethod
, requestParameters : RequestParameters
, requestHeaders : RequestHeaders
, username : Maybe String
, password : Maybe String
, requestBody : Maybe RequestBody
}

requestDecoder : JD.Decoder ReceivedAPISnapshotRequest
</code></pre>
<p>We need to now move our earlier logic that checks to see if a user has opted to
use the basic authentication fields or not from the view function to the
<em>decodeAPISnapshotRequest</em> function.</p>
<pre><code class="language-elm">decodeAPISnapshotRequest : Response -&gt; APISnapshotRequest
decodeAPISnapshotRequest hitResponse =
let
result =
JD.decodeString requestDecoder hitResponse.body
in
case result of
Ok value -&gt;
let
extractedCreds =
( value.username, value.password )

                    derivedBasicAuthentication =
                        case extractedCreds of
                            ( Nothing, Nothing ) -&gt;
                                Nothing

                            ( Just receivedUsername, Nothing ) -&gt;
                                Just { username = receivedUsername, password = &quot;&quot; }

                            ( Nothing, Just receivedPassword ) -&gt;
                                Just { username = &quot;&quot;, password = receivedPassword }

                            ( Just receivedUsername, Just receivedPassword ) -&gt;
                                Just { username = receivedUsername, password = receivedPassword }
                in
                    { url = value.url
                    , httpMethod = value.httpMethod
                    , requestParameters = value.requestParameters
                    , requestHeaders = value.requestHeaders
                    , basicAuthentication = derivedBasicAuthentication
                    , requestBody = value.requestBody
                    }

            Err err -&gt;
                emptyRequest

</code></pre>
<p>We extract the username and password into <em>extractedCreds</em> as a Pair from
<em>ReceivedAPISnapshotRequest</em> after decoding and construct our
<em>APISnapshotRequest</em> from it.</p>
<p>And now we have a clean view function which just takes a <em>BasicAuthentication</em>
type and returns us a <em>Html Msg</em> type.</p>
<pre><code class="language-elm">view : BasicAuthentication -&gt; Html Msg
view b =
[ div [ class &quot;form-row&quot; ]
[ input
[ type_ &quot;text&quot;
, placeholder &quot;Username&quot;
, value b.username
, onInput (UpdateUsername)
]
[]
, input
[ type_ &quot;password&quot;
, placeholder &quot;Password&quot;
, value b.password
, onInput (UpdatePassword)
]
[]
, a
[ href &quot;javascript:void(0)&quot;
, onClick (RemoveBasicAuthentication)
]
[ text &quot;×&quot; ]
]
]
</code></pre>
<p>We now have a Model that better captures the business logic. And should we
change the logic of basic authentication parameter selection in the future, We
do not have to worry about updating the logic in the view .</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[APISnapshot built on Elm & Rails is open source]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/apisnapshot-built-using-elm-and-ruby-on-rails-is-open-source"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/apisnapshot-built-using-elm-and-ruby-on-rails-is-open-source.png"/>
      <id>https://www.bigbinary.com/blog/apisnapshot-built-using-elm-and-ruby-on-rails-is-open-source</id>
      <published>2018-05-25T00:00:00.000Z</published>
      <updated>2018-05-25T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/apisnapshot-built-using-elm-and-ruby-on-rails-is-open-source.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[APISnapshot built using Elm and Ruby on Rails is open source]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/apisnapshot-built-using-elm-and-ruby-on-rails-is-open-source"><![CDATA[<p>APISnapshot (Link not available) is built using Elm and Ruby on Rails. Today
we’re happy to announce that the code is publicly
<a href="https://github.com/bigbinary/apisnapshot">available on GitHub</a>.</p>
<p>We built APISnapshot for two reasons.</p>
<p>We wanted to work with <a href="http://elm-lang.org">Elm</a>.</p>
<p>We wanted to have a tool that is easy to use and that will help us capture what
response we are getting from the API in a format that is easy to share in github
issue, in slack or in an email. As a consulting company we work with various
teams around the world and during development phase either API is unstable or
they do not do what they should be doing.</p>
<p>We originally built this tool using <a href="https://reactjs.org">React</a>. Elm compiler
is quite strict and forced us to take into consideration all possibilities. This
lead us to notice a few bugs which were still present in React code. In this way
Elm compiler helped us produce &quot;correct&quot; software by eliminating some of the
bugs that we would have found later.</p>
<p>JSON encoding/decoding is a hard problem in Elm in general. In most of the cases
we know the shape of the API response we are going to get.</p>
<p>In the case of APISnapshot we do not know the shape of the JSON response we will
get. Because of that it took us a bit longer to build the application. However,
this forced us to really dig deep into JSON encoding/decoding issue in Elm and
we learned a lot.</p>
<p>We would like to thank all the
<a href="https://github.com/bigbinary/apisnapshot/graphs/contributors">contributors</a> to
the project. Special shout out goes to <a href="https://github.com/jasim">Jasim</a> for the
discussion and the initial work on parsing the JSON file.</p>
<p>We like the combination of Elm and Ruby on Rails so much so that we are building
<a href="https://www.acehelp.com">AceHelp</a> using the same technologies. AceHelp is
<a href="https://github.com/bigbinary/acehelp">open source</a> from day one.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Generating filmstrip using puppeteer for better debugging]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/generating-filmstrip-using-puppeteer-for-better-debugging"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/generating-filmstrip-using-puppeteer-for-better-debugging.png"/>
      <id>https://www.bigbinary.com/blog/generating-filmstrip-using-puppeteer-for-better-debugging</id>
      <published>2018-05-24T00:00:00.000Z</published>
      <updated>2018-05-24T00:00:00.000Z</updated>
      <author>
        <name>Rohit Kumar</name>
        <uri>https://www.bigbinary.com/blog/authors/rkr090</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/generating-filmstrip-using-puppeteer-for-better-debugging.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[We are writing a lot of automation tests using Puppeteer. Since puppeteer scripts execute so fast certain tests fail when they should be passing. Debugging those tests can be a challenge. Chrome...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/generating-filmstrip-using-puppeteer-for-better-debugging"><![CDATA[<p>We are writing a lot of automation tests using
<a href="https://github.com/GoogleChrome/puppeteer">Puppeteer</a>.</p>
<p>Since puppeteer scripts execute so fast certain tests fail when they should be
passing. Debugging those tests can be a challenge.</p>
<p>Chrome devtools comes with
<a href="https://www.youtube.com/watch?v=r1LVAu1BB8Y">filmstrip feature</a>. In
&quot;Performance&quot; tab we can see screenshots of the site as they change over time.</p>
<p>We wanted puppeteer to generate similar filmstrip so that we can visually
identify the source of the problem.</p>
<p>It turns out that puppeteer makes it very easy. Here is the full code.</p>
<pre><code class="language-javascript">import puppeteer from &quot;puppeteer&quot;;

(async () =&gt; {
  const browser = await puppeteer.launch({ headless: false });
  const page = await browser.newPage();
  await page.setViewport({ width: 1280, height: 1024 });

  await page.tracing.start({ path: &quot;trace.json&quot;, screenshots: true });

  await page.goto(&quot;https://www.bigbinary.com&quot;);
  await Promise.all([
    page.waitForNavigation(),
    page.click(&quot;#navbar &gt; ul &gt; li:nth-child(1) &gt; a&quot;),
  ]);

  await page.tracing.stop();

  await browser.close();
})();
</code></pre>
<p>If we execute this script then it will generate a file called <code>trace.json</code>. This
file has images embedded in it which are base64 encoded.</p>
<p>To see the filmstrip drag the <code>trace.json</code> file to &quot;Performance&quot; tab in the
Chrome devtool. Here is a quick video explaining this.</p>
<p><a href="https://www.youtube.com/watch?v=hZGTIyc3Xak"><img src="https://img.youtube.com/vi/hZGTIyc3Xak/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=hZGTIyc3Xak">Watch on YouTube</a></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Practical usage of identity function]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/practical-usage-of-identity-function"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/practical-usage-of-identity-function.png"/>
      <id>https://www.bigbinary.com/blog/practical-usage-of-identity-function</id>
      <published>2018-03-20T00:00:00.000Z</published>
      <updated>2018-03-20T00:00:00.000Z</updated>
      <author>
        <name>Rohit Kumar</name>
        <uri>https://www.bigbinary.com/blog/authors/rkr090</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/practical-usage-of-identity-function.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[If you are learning functional programming then you can't go far without running into "identity function". An identity function is a very basic function that - takes one argument - returns the...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/practical-usage-of-identity-function"><![CDATA[<p>If you are learning functional programming then you can't go far
<a href="https://gist.github.com/Avaq/1f0636ec5c8d6aed2e45">without running into</a>
&quot;identity function&quot;.</p>
<p>An identity function is a very basic function that</p>
<ul>
<li>takes one argument</li>
<li>returns the argument</li>
</ul>
<pre><code class="language-javascript">f(x) = x;
</code></pre>
<p>This seems like the most useless function in the world. We never needed any
function like this while building any application. Then what's the big deal
about this identity function.</p>
<p>In this blog we will see how this identity concept is used in the real world.</p>
<p>For the implementation we will be using <a href="http://ramdajs.com/">Ramda.js</a>. We
previously
<a href="https://blog.bigbinary.com/2017/10/06/optimize-javascript-code-for-composability-with-ramdajs.html">wrote about</a>
how we, at BigBinary, write JavaScript code using Ramda.js.</p>
<p>Again please note that in the following code <code>R</code> stands for <code>Ramda</code> and not for
<a href="https://www.r-project.org">programming language R</a>.</p>
<h3>Example 1</h3>
<p>Here is JavaScript code.</p>
<pre><code class="language-javascript">if (x) return x;
return [];
</code></pre>
<p>Here is same code using Ramda.js.</p>
<pre><code class="language-javascript">R.ifElse(R.isNil, () =&gt; [], R.identity);
</code></pre>
<p><a href="http://ramdajs.com/repl/?v=0.25.0#?const%20fn%20%3D%20R.ifElse%28%0A%20%20R.isNil%2C%0A%20%20%28%29%20%3D%3E%20%5B%5D%2C%0A%20%20R.identity%0A%20%29%3B%0A%0Afn%28null%29%3B%0Afn%28%22hello%22%29%3B">try it</a></p>
<h3>Example 2</h3>
<p>Here we will use identity as the return value in the default case.</p>
<pre><code class="language-javascript">R.cond([
  [R.equals(0), R.always(&quot;0&quot;)],
  [R.equals(10), R.always(&quot;10&quot;)],
  [R.T, R.identity],
]);
</code></pre>
<p><a href="http://ramdajs.com/repl/?v=0.25.0#?const%20fn%20%3D%20R.cond%28%5B%0A%20%20%5BR.equals%280%29%2C%20R.always%28%220%22%29%5D%2C%0A%20%20%5BR.equals%2810%29%2C%20R.always%28%2210%22%29%5D%2C%0A%20%20%5BR.T%2C%20R.identity%5D%0A%5D%29%3B%0A%0A%0Afn%280%29%3B%0Afn%2810%29%3B%0Afn%285%29%3B">try it</a></p>
<h3>Example 3</h3>
<p>Get the unique items from the list.</p>
<pre><code class="language-javascript">R.uniqBy(R.identity, [1, 1, 2]);
</code></pre>
<p><a href="http://ramdajs.com/repl/?v=0.25.0#?R.uniqBy%28R.identity%2C%20%5B1%2C1%2C2%5D%29">try it</a></p>
<h3>Example 4</h3>
<p>Count occurrences of items in the list.</p>
<pre><code class="language-javascript">R.countBy(R.identity, [&quot;a&quot;, &quot;a&quot;, &quot;b&quot;, &quot;c&quot;, &quot;c&quot;, &quot;c&quot;]);
</code></pre>
<p><a href="http://ramdajs.com/repl/?v=0.25.0#?R.countBy%28R.identity%2C%20%5B%22a%22%2C%22a%22%2C%22b%22%2C%22c%22%2C%22c%22%2C%22c%22%5D%29%3B">try it</a></p>
<h3>Example 5</h3>
<p>Begin value from zero all the way to n-1.</p>
<pre><code class="language-javascript">R.times(R.identity, 5);
</code></pre>
<p><a href="http://ramdajs.com/repl/?v=0.25.0#?R.times%28R.identity%2C%205%29">try it</a></p>
<h3>Example 6</h3>
<p>Filter truthy values.</p>
<pre><code class="language-javascript">R.filter(R.identity, [
  { a: 1 },
  false,
  { b: 2 },
  true,
  &quot;&quot;,
  undefined,
  null,
  0,
  {},
  1,
]);
</code></pre>
<p><a href="http://ramdajs.com/repl/#?R.filter%28R.identity%2C%20%5B%7Ba%3A1%7D%2C%20false%2C%20%7Bb%3A2%7D%2C%20true%2C%20%27%27%2C%20undefined%2C%20null%2C%200%2C%20%7B%7D%2C%201%5D%29%3B">try it</a></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Fixing CORS issue with AWS services]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/fixing-cors-issue-with-aws-services"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/fixing-cors-issue-with-aws-services.png"/>
      <id>https://www.bigbinary.com/blog/fixing-cors-issue-with-aws-services</id>
      <published>2017-10-31T00:00:00.000Z</published>
      <updated>2017-10-31T00:00:00.000Z</updated>
      <author>
        <name>Narendra Rajput</name>
        <uri>https://www.bigbinary.com/blog/authors/bknarendra</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/fixing-cors-issue-with-aws-services.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Explains how to fix the CORS issue when working with AWS Cloudfront and S3]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/fixing-cors-issue-with-aws-services"><![CDATA[<p>While working on a client project, we started facing an issue where the JWPlayer
stopped playing videos when we switched to
<a href="https://en.wikipedia.org/wiki/HTTP_Live_Streaming">hls</a> version of videos. We
found a
<a href="https://developer.mozilla.org/en-US/docs/Web/HTTP/Access_control_CORS">CORS</a>
error in the JS console as shown below.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2017/fixing-cors-issue-with-aws-services/cors_error.png" alt="cors error"></p>
<p>After researching we found that JWPlayer makes an AJAX request to load the
<a href="https://en.wikipedia.org/wiki/M3U#M3U8">m3u8</a> file. To fix the issue, we needed
to enable CORS and for that we needed to make changes to S3 and Cloudfront
configurations.</p>
<h2>S3 configuration changes</h2>
<p>We can configure CORS for the S3 bucket by allowing requests originating from
specified hosts. As show in the image below we can find the CORS configuration
option in Permissions tab of the S3 bucket.
<a href="http://docs.aws.amazon.com/AmazonS3/latest/dev/cors.html">Here</a> is the official
documentation on configuring CORS for S3.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2017/fixing-cors-issue-with-aws-services/s3_cors_configuration.png" alt="s3 cors configuration"></p>
<p>S3 bucket will now allow requests originating from the specified hosts.</p>
<h2>Cloudfront configuration changes</h2>
<p><a href="http://docs.aws.amazon.com/AmazonCloudFront/latest/DeveloperGuide/Introduction.html">Cloudfront</a>
is a CDN service provided by AWS which uses edge locations to speed up the
delivery of static content. Cloudfront takes content from S3 buckets and caches
it at edge locations and delivers it to the end user. For enabling CORS we need
to configure Cloudfront to allow forwarding of required headers.</p>
<p>We can configure the behavior of Cloudfront by clicking on Cloudfront
Distribution's &quot;Distribution Settings&quot;. Then from the &quot;Behaviour&quot; tab click on
&quot;Edit&quot;. Here we need to whitelist the headers that need to be forwarded. Select
the &quot;Origin&quot; header to whitelist which is required for CORS, as shown in the
image below.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2017/fixing-cors-issue-with-aws-services/cloudfront_behaviour.png" alt="cloudfront behaviour"></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Elm Conf 2017 Summary]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/elm-conf-2017-summary"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/elm-conf-2017-summary.png"/>
      <id>https://www.bigbinary.com/blog/elm-conf-2017-summary</id>
      <published>2017-10-04T00:00:00.000Z</published>
      <updated>2017-10-04T00:00:00.000Z</updated>
      <author>
        <name>Prathamesh Sonpatki</name>
        <uri>https://www.bigbinary.com/blog/authors/prathamesh</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/elm-conf-2017-summary.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Summary of Elm Conf 2017 that took place on Sept. 28 2017 in St. Loius, MO, USA]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/elm-conf-2017-summary"><![CDATA[<p>I attended <a href="https://www.elm-conf.us">Elm Conf 2017 US</a> last week alongside
<a href="https://www.thestrangeloop.com/">Strangeloop conference</a>. I was looking forward
to the conference to know what the Elm community is working on and what problems
people are facing and what are they doing to overcome those.</p>
<p>After attending the conference, I can say that Elm community is growing strong.
The conference was attended by around 350 people and many were using Elm in
production. More number of people wanted to try Elm in production.</p>
<p>There was a lot of enthusiasm about starting new Elm meetups. As a Ruby on Rails
and React meetup organizer myself, I was genuinely interested in hearing
experiences of seasoned meetup organizers. In general Evan and Richard prefer
meetup to be a place where people form small groups and hack on something rather
than one person teaching the whole group something.</p>
<p>I liked all the <a href="https://www.elm-conf.us/talks/">talks</a>. There was variety in
the topics and the speakers were all seasoned. Kudos to the organizers for
putting up a great program. Below is a quick summary of my thoughts from the
conference.</p>
<h3>Keynote by Evan</h3>
<p><a href="https://twitter.com/czaplic">Evan</a> talked about the work he has been doing for
the upcoming release of Elm. He discussed the optimization work related to code
splitting, code generation and minification for speeding up building and
delivering single page apps using Elm. He made another interesting point that he
changed the codegen which generates the JS code from Elm code twice but nobody
noticed it. Things like this can give a huge opportunity to change and improve
existing designs which he has been doing for the upcoming release.</p>
<p>In the end he mentioned that his philosophy is not to rush things. It's better
to do things right than doing it now.</p>
<p>After the keynote, he encouraged people to talk to him about what they are
working on which was really nice.</p>
<h3>Accessibility with Elm</h3>
<p><a href="https://twitter.com/t_kelly9">Tessa</a> talked about her work around adding
<a href="http://package.elm-lang.org/packages/tesk9/elm-html-a11y">accessibility support</a>
for Elm apps. She talked about design decisions, prior art and some of the
challenges she faced while working on the library like working with tabs,
interactive elements and images. There was a question at the end about whether
this will be incorporated into Elm core but Evan mentioned that it might take
some time.</p>
<h3>Putting the Elm Platform in the Browser</h3>
<p><a href="https://twitter.com/ellie_editor">Luke</a>, the creator of
<a href="https://ellie-app.com/">Ellie</a> - a way to easily share your elm code with
others online - talked about how he started with Ellie. He talked about the
problems he had to face for implementing and sustaining Ellie through ads.
During the talk, he also open sourced the code, so we can see it on
<a href="https://github.com/lukewestby/ellie">Github</a> now.</p>
<p>Luke mentioned how he changed the architecture of Ellie from mostly running on
the server to running in the browser using service workers. He discussed future
plans about sustaining Ellie, building an Elm editor instead of using
Codemirror, getting rid of ads and making Ellie better for everyone.</p>
<h3>The Importance of Ports</h3>
<p>In other frameworks like <a href="http://www.purescript.org/">PureScript</a> and
<a href="https://bucklescript.github.io/">BuckleScript</a> invoking native JavaScript
functions is easy. In Elm one has to use &quot;Ports&quot;. Using Ports requires some
extra stuff. In return we get more safety.</p>
<p><a href="https://twitter.com/splodingsocks">Murphy Randle</a> presented a case where he was
using too many ports which was resulting in fragmented code. He discussed how
port is based on <a href="https://en.wikipedia.org/wiki/Actor_model">Actor Model</a> and
once we get that then using port would be much easier. He also showed refactored
code.</p>
<p>Murphy also runs Elm Town Podcast (Link is not available). Listen to episode 13
to know more about Ports.</p>
<h3>Keynote by Richard Feldman</h3>
<p><a href="https://twitter.com/rtfeldman">Richard</a> talked about his experiences in
teaching beginners about Elm. He has taught Elm a lot. He has done an extensive
Elm course on <a href="https://frontendmasters.com/workshops/elm">Front end masters</a>. He
is currently writing
<a href="https://www.manning.com/books/elm-in-action">Elm in Action book</a>.</p>
<p>He talked about finding motivation to teach using the
<a href="http://edglossary.org/swbat/">SWBAT technique</a>. It helped him in deciding the
agenda and finding the direct path for teaching. He mentioned that in the
beginning being precise and detailed is not important. This resonated with me as
the most important thing for anyone who is getting started is getting started
with the most basic things and then iterating over it again and again.</p>
<h3>Parting thoughts</h3>
<p>Elm community is small, tight, very friendly and warm. Lots of people are trying
a lot of cool things. <a href="https://elmlang.herokuapp.com/">Elm Slack</a> came in the
discussions again and again as a good place to seek out help for beginners.</p>
<p>When I heard about Elm first, it was about good compiler errors and having run
time safety. However after attending the conference I am mighty impressed with
the Elm community.</p>
<p>Big props to <a href="https://twitter.com/brianhicks">Brian</a> and
<a href="https://twitter.com/ellie_editor">Luke</a> for organizing the conference!</p>
<p>All the videos from the conference are already getting
<a href="https://www.youtube.com/watch?v=P3pL85n9_5s&amp;list=PLglJM3BYAMPFTT61A0Axo_8n0s9n9CixA">uploaded here</a>.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Difference between type and type alias in Elm]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/difference-between-type-and-type-alias-in-elm"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/difference-between-type-and-type-alias-in-elm.png"/>
      <id>https://www.bigbinary.com/blog/difference-between-type-and-type-alias-in-elm</id>
      <published>2017-07-12T00:00:00.000Z</published>
      <updated>2017-07-12T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/difference-between-type-and-type-alias-in-elm.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[type alias vs type in Elm]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/difference-between-type-and-type-alias-in-elm"><![CDATA[<p>What is the difference between <code>type</code> and <code>type alias</code>.</p>
<p>Elm FAQ has
<a href="http://faq.elm-community.org/#what-is-the-difference-between-type-and-type-alias">an answer</a>
to this question. However I could not fully understand the answer.</p>
<p>This is my attempt in explaining it.</p>
<h2>What is type</h2>
<p>In Elm everything has a type. Fire up <code>elm-repl</code> and you will see 4 is a
<code>number</code> and &quot;hello&quot; is a <code>String</code>.</p>
<pre><code class="language-elm">&gt; 4
4 : number

&gt; &quot;hello&quot;
&quot;hello&quot; : String
</code></pre>
<p>Let's assume that we are working with users records and we have following
attributes of those users.</p>
<ul>
<li>Name</li>
<li>Age</li>
<li>Status (Active or Inactive)</li>
</ul>
<p>It's pretty clear that &quot;Name&quot; should be of type &quot;String&quot; and &quot;Age&quot; should be of
type &quot;number&quot;.</p>
<p>Let's think about a moment what is the type of &quot;Status&quot;. What is &quot;Active&quot; and
&quot;Inactive&quot; in terms of type.</p>
<p><code>Active</code> and <code>Inactive</code> are two valid values of <code>Status</code>. In other programming
languages we might represent <code>Status</code> as an enum.</p>
<p>In Elm we need to create a new type. And that can be done as shown here.</p>
<pre><code class="language-elm">type Status = Active | Inactive
</code></pre>
<p>Second thing we are doing is that we are stating that the valid values for this
new type are <code>Active</code> and <code>Inactive</code>.</p>
<p>When I discussed this code with my team members they asked me to show where is
<code>Active</code> and <code>Inactive</code> defined. Good question.</p>
<p>The simple answer is that they are not defined anywhere. They do not need to be
defined. What needs definition is the new type that is being created.</p>
<p>What makes understanding it a bit hard for people coming from Ruby, Java and
such background is that these people (including me) are looking at <code>Active</code> and
<code>Inactive</code> as a class or a constant which is not the right way to look at.</p>
<p><code>Active</code> and <code>Inactive</code> are the valid values for type <code>Status</code>.</p>
<pre><code class="language-elm">&gt; Active
-- NAMING ERROR ----------

Cannot find variable `Active`

3|   Active
     ^^^^^^
</code></pre>
<p>As you can see repl is not sure what <code>Active</code> is.</p>
<p>We can solve this by pasting following code in repl.</p>
<pre><code class="language-elm">type Status = Active | Inactive
</code></pre>
<p>Now we can run the same code again. This time no error.</p>
<pre><code class="language-elm">&gt; Active
Active : Repl.Status
</code></pre>
<h2>What is type alias</h2>
<p>Let's see a simple application which just prints name and age of a single user.</p>
<p><a href="https://gist.github.com/neerajsingh0101/60627801877312ea95e328f704e5245a">Here</a>
is the code. I'm posting screenshot of the same below with certain part
highlighted.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2017/difference-between-type-and-type-alias-in-elm/code-without-type-alias.png" alt="code without type alias"></p>
<p>As you can see <code>{ name : String, age : Int }</code> is repeated at four different
places. In a bigger application it might get repeated more often.</p>
<p>This is what <code>type alias</code> does. It removes repetition. It removes verbosity.</p>
<p>As the name suggests this is just an alias. Note that <code>type</code> creates a new type
whereas <code>type alias</code> is literally saving keystrokes. <code>type alias</code> does not
create a new <code>type</code>.</p>
<p>Now if you read the FAQ answer again then hopefully it will make morse sense
now.</p>
<p><a href="https://gist.github.com/neerajsingh0101/8e7756a1b7588538ac16526ce2bfc772">Here</a>
is modified code using <code>type alias</code>.</p>
<h2>Why use type alias Username : String</h2>
<p>While browsing Elm code in general, I came across following code.</p>
<pre><code class="language-elm">type alias Username = String
</code></pre>
<p>Question is what does code like this buy us. All it does is that instead of
<code>String</code> I can now type <code>Username</code>.</p>
<p>First let's see how it might be used.</p>
<p>Let's assume that we have a function which returns <code>Status</code> of a user for the
given username.</p>
<p>The function might have implementation as shown below.</p>
<pre><code class="language-elm">getUserStatus username =
  make_db_call_and_return_user_status
</code></pre>
<p>Now let's think about what the type annotation (rubyist think of it as method
signature ) of function <code>getUserStatus</code> might look like.</p>
<p>It takes <code>username</code> as input and returns user record.</p>
<p>So the type annotation might look like</p>
<pre><code class="language-elm">getUserStatus : String -&gt; Status
</code></pre>
<p>This works. However the issue is that <code>String</code> is not expressive enough. It can
be made more expressive if the signature were</p>
<pre><code class="language-elm">getUserStatus : Username -&gt; Status
</code></pre>
<p>Now that we know about <code>type alias</code> all we need to do is</p>
<pre><code class="language-elm">type alias Username = String
</code></pre>
<p>This makes code more expressive.</p>
<h2>No recursion with type alias</h2>
<p>An example of where we might need recursion is while designing commenting
system. A comment can have sub-comments. However since <code>type alias</code> is just a
substitution and recursion does not work with it.</p>
<pre><code class="language-elm">&gt; type alias Comment = { message : String, responses : List Comment }

This type alias is recursive, forming an infinite type!

2| type alias Comment = { message : String, responses : List Comment }
   ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
When I expand a recursive type alias, it just keeps getting bigger and bigger.
So dealiasing results in an infinitely large type! Try this instead:

    type Comment
        = Comment { message : String, responses : List Comment }

This is kind of a subtle distinction. I suggested the naive fix, but you can
often do something a bit nicer. So I would recommend reading more at:
&lt;https://github.com/elm-lang/elm-compiler/blob/0.18.0/hints/recursive-alias.md&gt;
</code></pre>
<p><a href="https://github.com/elm-lang/elm-compiler/blob/master/hints/recursive-alias.md">Hint for Recursive Type Aliases</a>
discusses this issue in greater detail and it also has solution to the problem
of recursion.</p>
<h2>Dual role of type alias as constructor and type</h2>
<p>Let's say that we have following code.</p>
<pre><code class="language-elm">type alias UserInfo =
    { name : String, age : Int }
</code></pre>
<p>Now we can use <code>UserInfo</code> as a constructor to create records.</p>
<pre><code class="language-elm">&gt; type alias UserInfo = { name : String, age : Int }
&gt; sam = UserInfo &quot;Sam&quot; 24
{ name = &quot;Sam&quot;, age = 24 } : Repl.UserInfo
</code></pre>
<p>In the above case we used <code>UserInfo</code> as a <strong>constructor</strong> to create new user
records. We did not use <code>UserInfo</code> as a <code>type</code>.</p>
<p>Now let's see another function.</p>
<pre><code class="language-elm">type alias UserInfo =
    { name : String, age : Int }


getUserAge : UserInfo -&gt; Int
getUserAge userinfo =
    userinfo.age
</code></pre>
<p>In this case <code>UserInfo</code> is being used in <strong>type annotation</strong> as <strong>type</strong> and not
as <strong>constructor</strong>.</p>
<h2>Which one to use type or type alias</h2>
<p>Both of them serve different purpose. Let's see an example.</p>
<p>Let's say that we have following code.</p>
<pre><code class="language-elm">type alias UserInfo =
    { name : String, age : Int }

type alias Coach =
    { name : String, age : Int, sports : String }
</code></pre>
<p>Now let's write a function that gets age of the given userinfo.</p>
<pre><code class="language-elm">getUserAge : UserInfo -&gt; Int

getUserAge UserInfo =
    UserInfo.age
</code></pre>
<p>Now let's create two types of users.</p>
<pre><code class="language-elm">sam = UserInfo &quot;Sam&quot; 24
charlie = Coach &quot;Charlie&quot; 52 &quot;Basketball&quot;
</code></pre>
<p>Now let's try to get age of both of these people.</p>
<pre><code class="language-elm">getUserAge sam
getUserAge charlie
</code></pre>
<p>Here is
<a href="https://gist.github.com/neerajsingh0101/83f26c0c32c310ab01fe9a27f5bc9e98">the complete version</a>
if you want to run it.</p>
<p><strong>Please note that elm-repl
<a href="https://github.com/elm-lang/elm-repl/issues/86">does not support type annotation</a>
so you can't test this code in elm-repl.</strong></p>
<p>The main point here is that since we used <code>type alias</code>, function <code>getUserAge</code>
works for both <code>UserInfo</code> as well as <code>Coach</code>. It would be a stretch to say that
this sounds like &quot;duck typing in Elm&quot; but it comes pretty close.</p>
<p>Yes Elm is statically typed language and it enforces type. However the point
here is the <code>type alias</code> is not exactly a type.</p>
<p>So why did this code work.</p>
<p>It worked because of Elm's support for
<a href="http://elm-lang.org/docs/records#pattern-matching">pattern matching</a> for
records.</p>
<p>As mentioned earlier <code>type alias</code> is just a shortcut for typing the verbose
version. So let's expand the type annotation of <code>getUserAge</code>.</p>
<p>If we were not using <code>type alias UserInfo</code> then it might have looked like as
shown below.</p>
<pre><code class="language-elm">getUserAge : { name : String, age : Int } -&gt; Int
</code></pre>
<p>Here the argument is a record. Here is
<a href="http://elm-lang.org/docs/records">official guide on Records</a>. While dealing
with records Elm looks at the argument and if that argument is a record and has
all the matching attributes then Elm will not complain because of its support
for pattern matching.</p>
<p>Since <code>Coach</code> has both <code>name</code> and <code>age</code> attribute <code>getUserAge charlie</code> works.</p>
<p>You can test it by removing the attribute <code>age</code> from <code>Coach</code> and then you will
see that Compiler will complain.</p>
<p>In summary if we want strict type enforcement then we should go for <code>type</code>. If
we need something so that we do not need to type all the attributes all the time
and we want pattern matching then we should go for <code>type alias</code>.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Arrows in Elm's method signature]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/arrows-in-method-signature-of-elm"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/arrows-in-method-signature-of-elm.png"/>
      <id>https://www.bigbinary.com/blog/arrows-in-method-signature-of-elm</id>
      <published>2017-07-11T00:00:00.000Z</published>
      <updated>2017-07-11T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/arrows-in-method-signature-of-elm.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Let's look at the documentation of length function of String in Elm. It's here and it looks like this. If we look at the similar feature in Ruby world then we get length method. Method signature in...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/arrows-in-method-signature-of-elm"><![CDATA[<p>Let's look at the documentation of <code>length</code> function of <code>String</code> in Elm.</p>
<p>It's
<a href="http://package.elm-lang.org/packages/elm-lang/core/5.1.1/String#length">here</a>
and it looks like this.</p>
<pre><code class="language-elm">length : String -&gt; Int

&gt; String.length &quot;Hello World&quot;
11 : Int
</code></pre>
<p>If we look at the similar feature in Ruby world then we get
<a href="https://ruby-doc.org/core-2.2.0/String.html#method-i-length">length</a> method.</p>
<pre><code class="language-ruby">length -&gt; integer
</code></pre>
<p>Method signature in ruby's documentation and Elm's documentation is quite
similar. Both return an integer.</p>
<p>In Elm's world method definitions are called &quot;Type Annotations&quot;. Going forward
that's what I'm going to use in this blog.</p>
<p>Now let's look at method definition of <code>slice</code> method in Ruby.</p>
<p>It looks like <a href="https://ruby-doc.org/core-2.2.0/String.html#slice-method">this</a>.</p>
<pre><code class="language-ruby">slice(start, length) -&gt; new_str or nil

irb(main):006:0&gt; &quot;snakes on a plane!&quot;.slice(0,6)
=&gt; &quot;snakes&quot;
</code></pre>
<p>In Elm world it looks like
<a href="http://package.elm-lang.org/packages/elm-lang/core/5.1.1/String#slice">this</a>.</p>
<pre><code class="language-ruby">slice : Int -&gt; Int -&gt; String -&gt; String

&gt; String.slice  0  6 &quot;snakes on a plane!&quot;
&quot;snakes&quot; : String
</code></pre>
<p>Questions is what's up with all those arrows.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Rails 5 blogs and the art of story telling]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/rails-5-blogs-and-the-art-of-story-telling"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/rails-5-blogs-and-the-art-of-story-telling.png"/>
      <id>https://www.bigbinary.com/blog/rails-5-blogs-and-the-art-of-story-telling</id>
      <published>2016-09-19T00:00:00.000Z</published>
      <updated>2016-09-19T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <category term="Rails"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/rails-5-blogs-and-the-art-of-story-telling.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Rails 5 blogs and  the art of story telling]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/rails-5-blogs-and-the-art-of-story-telling"><![CDATA[<p>Between October 31,2015 and Sep 5, 2016 we wrote 80 blogs on changes in
<a href="https://www.bigbinary.com/blog/categories/rails-5">Rails 5</a>.</p>
<p>Producing a blog every 4 days consistently over 310 days takes persistence and
time - lots of it.</p>
<p>We needed to go through all the commits and then pick the ones which are worth
writing about and then write about it. Going into this I knew it would be a hard
task. Ruby on Rails is now a well crafted machine. In order to fully understand
what's going on in the code base we need to spend sufficient time on it.</p>
<p>However I was surprised by the thing that turned to be the hardest - telling
story of the code change.</p>
<p>Every commit has a story. There is a reason for it. The commit itself might be
minor but that code change in itself does not tell the full story.</p>
<p>For example take
<a href="https://github.com/rails/rails/commit/a71350cae0082193ad8c66d65ab62e8bb0b7853b">this commit</a>.
This commit is so simple that you might think it is not worth writing about.
However in order to fully understand what it does we need to tell the full story
which was captured in
<a href="https://www.bigbinary.com/blog/rails-5-disables-autoloading-after-booting-the-app-in-production">this blog</a>.</p>
<p>Or take the case of
<a href="https://www.bigbinary.com/blog/rails-5-official-supports-mariadb">Rails 5 officially supports MariaDB</a> . The
blog captures the full story and not just the code that changed.</p>
<p>Now you might say that I have cherry picked blog posts that favor my case. So
let's pick a blog <a href="https://www.bigbinary.com/blog/skip-mailers-while-generating-rails-5-app">which is simple</a>.</p>
<p>You might wonder what could go wrong with a blog like this. As it turns out,
plenty. That's because writing a blog also requires defining the boundary of the
blog. Deciding what to include and what to leave out is hard. One gets a feel
for it only after writing it. And after having typed the words on screen,
<a href="https://m.signalvnoise.com/the-writing-class-id-like-to-teach-11b259f44a5d#.mk324kxym">pruning is hard</a>.</p>
<p>A good written article is simple writing. The problem with article which are
simple to readers is that - well it is simple. So it feels to readers that
writing it must be simple. Nothing can be further from the truth. It takes a lot
of hard work to produce anything simple. It's true in writing. And it's true in
producing software.</p>
<p>Coming back to the &quot;Skipping Mailer&quot; blog, it took quite a bit of back and forth
to bring the blog to its essence. So yes the final output is quite short but
that does not mean that it took short amount of time to produce it.</p>
<h2>Tell a story even if you have 10 seconds</h2>
<p>John Lasseter was working as an animator at Disney in 1984. He was just fired
from Disney for promoting computer animations at Disney. Lasseter joins
Lucasfilm. Lucasfilm renamed itself to Pixar Graphics Group and sold itself to
Steve Jobs for $5 million.</p>
<p>Lasseter was tasked with producing a short film that would show the power of
what computer animations could do so that Pixar Graphics Group can get some
projects like producing TV commercials with cartoon characters and earn some
money. Lasseter needed to produce a short film for the upcoming computer
graphics animation conference.</p>
<p>His initial idea was to have a short movie having a plotless character. He
presented this idea to a conference in Brussels. There Belgian animator Raoul
Servais commented in slightly harsh tone that</p>
<blockquote>
<p>No matter how short it is, it should have a beginning, a middle, and an end.
Don't forget the story.</p>
</blockquote>
<p>Lasseter complained that it's a pretty short movie and there might not be time
to present a story.</p>
<p>Raoul Servais replied</p>
<blockquote>
<p>You can tell a story in ten seconds.</p>
</blockquote>
<p>Lasseter started developing a character. He came up with the idea of <em>Luxo Jr.</em></p>
<p><a href="https://www.youtube.com/watch?v=6G3O60o5U7w">Here is</a> final production of
<strong>Luxo Jr.</strong></p>
<p>Luxo Jr. was a major hit at the conference. Crowd was on its feet in applause
even before the two minutes film was over. Remember this is 1986 and Computer
Animation was not much advanced at that time and this was the first movie ever
made with the use of just computer graphics.</p>
<p>Lasseter later said that when audience was watching the movie they forgot that
they were watching a computer animated film because the story took over them. He
learned the lesson that technology should enable better story telling and
technology in itself divorced from story telling would not advance the cause of
Pixar.</p>
<p>Later John Lasseter went on to produce hits like Toy Story, A bug's life, Toy
Story 2, Cars, Cars 2, Monsters Inc, Finding Nemo and many more.</p>
<p>So you see even a great John Lasseter had to be reminded to tell a story.</p>
<h2>Actual content over bullet points</h2>
<p><a href="https://en.wikipedia.org/wiki/Jeff_Bezos">Jeff Bezos</a> is so focused on knowing
the full story that he banned usage of PowerPoint in internal meetings and
discussions. As per him it is easy to hide behind bullet points in a PowerPoint
presentation.</p>
<p>He insisted on writing the full story in word document and distribute it to
meeting attendees. The meetings starts with everyone head down reading the
document.</p>
<p>He is also known for saying that if we are building a feature then we first need
to know how it would be presented to the consumers when it is unveiled. We need
to know the story we are going to tell them. Without the story we won't have
full picture of what we are going to build.</p>
<h2>Learning to tell story is a journey</h2>
<p>I'm glad that during the last 310 days 16 people contributed to the blog posts.
The process of writing the posts at times was frustrating for a bunch of them.
They had done the work of digging into the code and had posted their findings.
Continuously getting feedback to edit the blog to build a nice coherent story
where each paragraph is an extension of the previous paragraph is a downer. Some
were dismayed at why we are spending so much energy on a technical blog.</p>
<p>However in the end we all are happy that we underwent this exercise. We could
see the initial draft of the blog and the final version and we all could see the
difference.</p>
<p>By no means we have mastered the art of storytelling. It's a long journey.
However we believe we are on the right path. Hopefully in coming months and
years we at BigBinary would be able to bring to you more stories from changes in
Rails and other places.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Configure PostgreSQL to allow remote connection]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/configure-postgresql-to-allow-remote-connection"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/configure-postgresql-to-allow-remote-connection.png"/>
      <id>https://www.bigbinary.com/blog/configure-postgresql-to-allow-remote-connection</id>
      <published>2016-01-23T00:00:00.000Z</published>
      <updated>2016-01-23T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/configure-postgresql-to-allow-remote-connection.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Sometimes we need PostgreSQL to allow remote connection. This blog describes how to get that done.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/configure-postgresql-to-allow-remote-connection"><![CDATA[<p>By default PostgreSQL is configured to be bound to &quot;localhost&quot;.</p>
<pre><code class="language-plaintext">
$ netstat -nlt
Proto Recv-Q Send-Q Local Address           Foreign Address         State
tcp        0      0 0.0.0.0:443             0.0.0.0:*               LISTEN
tcp        0      0 127.0.0.1:11211         0.0.0.0:*               LISTEN
tcp        0      0 0.0.0.0:80              0.0.0.0:*               LISTEN
tcp        0      0 0.0.0.0:22              0.0.0.0:*               LISTEN
tcp        0      0 127.0.0.1:5432          0.0.0.0:*               LISTEN
tcp        0      0 127.0.0.1:3737          0.0.0.0:*               LISTEN
tcp6       0      0 :::22                   :::*                    LISTEN

</code></pre>
<p>As we can see above port <code>5432</code> is bound to <code>127.0.0.1</code>. It means any attempt to
connect to the postgresql server from outside the machine will be refused. We
can try hitting the port <code>5432</code> by using telnet.</p>
<pre><code class="language-plaintext">
$ telnet 107.170.11.79 5432
Trying 107.170.11.79...
telnet: connect to address 107.170.11.79: Connection refused
telnet: Unable to connect to remote host

</code></pre>
<h2>Configuring postgresql.conf</h2>
<p>In order to fix this issue we need to find <code>postgresql.conf</code>. In different
systems it is located at different place. I usually search for it.</p>
<pre><code class="language-plaintext">
$ find / -name &quot;postgresql.conf&quot;
/var/lib/pgsql/9.4/data/postgresql.conf

</code></pre>
<p>Open <code>postgresql.conf</code> file and replace line</p>
<pre><code class="language-plaintext">
listen_addresses = 'localhost'

</code></pre>
<p>with</p>
<pre><code class="language-plaintext">
listen_addresses = '*'

</code></pre>
<p>Now restart postgresql server.</p>
<pre><code class="language-plaintext">
$ netstat -nlt
Proto Recv-Q Send-Q Local Address           Foreign Address         State
tcp        0      0 127.0.0.1:11211         0.0.0.0:*               LISTEN
tcp        0      0 0.0.0.0:80              0.0.0.0:*               LISTEN
tcp        0      0 0.0.0.0:22              0.0.0.0:*               LISTEN
tcp        0      0 0.0.0.0:5432            0.0.0.0:*               LISTEN
tcp        0      0 127.0.0.1:25            0.0.0.0:*               LISTEN
tcp        0      0 127.0.0.1:2812          0.0.0.0:*               LISTEN
tcp6       0      0 ::1:11211               :::*                    LISTEN
tcp6       0      0 :::22                   :::*                    LISTEN
tcp6       0      0 :::5432                 :::*                    LISTEN
tcp6       0      0 ::1:25                  :::*                    LISTEN

</code></pre>
<p>Here we can see that &quot;Local Address&quot; for port <code>5432</code> has changed to <code>0.0.0.0</code>.</p>
<h2>Configuring pg_hba.conf</h2>
<p>Let's try to connect to remote postgresql server using &quot;psql&quot;.</p>
<pre><code class="language-plaintext">
$ psql -h 107.170.158.89 -U postgres
psql: could not connect to server: Connection refused
	Is the server running on host &quot;107.170.158.89&quot; and accepting
	TCP/IP connections on port 5432?

</code></pre>
<p>In order to fix it, open <code>pg_hba.conf</code> and add following entry at the very end.</p>
<pre><code class="language-plaintext">
host    all             all              0.0.0.0/0                       md5
host    all             all              ::/0                            md5

</code></pre>
<p>The second entry is for IPv6 network.</p>
<p>Do not get confused by &quot;md5&quot; option mentioned above. All it means is that a
password needs to be provided. If you want client to allow collection without
providing any password then change &quot;md5&quot; to &quot;trust&quot; and that will allow
connection unconditionally.</p>
<p>Restart postgresql server.</p>
<pre><code class="language-plaintext">
$ psql -h 107.170.158.89 -U postgres
Password for user postgres:
psql (9.4.1, server 9.4.5)
Type &quot;help&quot; for help.

postgres=# \l

</code></pre>
<p>You should be able to see list of databases.</p>
<p>Now we are able to connect to postgresql server remotely.</p>
<p>Please note that in the real world you should be using extra layer of security
by using &quot;iptables&quot;.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Year in review 2015]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/year-in-review-2015"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/year-in-review-2015.png"/>
      <id>https://www.bigbinary.com/blog/year-in-review-2015</id>
      <published>2016-01-04T00:00:00.000Z</published>
      <updated>2016-01-04T00:00:00.000Z</updated>
      <author>
        <name>Vipul</name>
        <uri>https://www.bigbinary.com/blog/authors/vipulnsward</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/year-in-review-2015.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Activities of the BigBinary Team in 2015.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/year-in-review-2015"><![CDATA[<p>Year 2015 was an exciting year for BigBinary !</p>
<p>We added more <a href="https://bigbinary.com/clients">clients</a>. We increased
<a href="https://bigbinary.com/team">our team</a> size. We wrote more <a href="https://www.bigbinary.com/blog">blogs</a>, spoke
at more <a href="https://bigbinary.com/presentations">conferences</a>, and made even
<a href="https://bigbinary.com/videos">more videos</a> !</p>
<p>Here is the breakdown.</p>
<h2>We love conferences</h2>
<p>We presented at 10 conferences across 7 countries, on topics from
<a href="http://rubyonrails.org/">Rails</a> to
<a href="https://facebook.github.io/react/">ReactJS</a>.</p>
<ul>
<li><a href="http://www.gardencityruby.org/">Garden City RubyConf, India</a></li>
<li><a href="http://rubyconf.ph/">RubyConf, Philippines</a></li>
<li><a href="http://rubyconfindia.org/">RubyConf, India</a></li>
<li><a href="http://www.reddotrubyconf.com/">Reddot RubyConf, Singapore</a></li>
<li><a href="http://www.deccanrubyconf.org/">Deccan RubyConf, India</a></li>
<li><a href="http://2015.fullstackfest.com/">Full Stack Fest, Spain</a></li>
<li><a href="http://2015.rubyconf.tw/">RubyConf, Taiwan</a></li>
<li><a href="http://rockymtnruby.com/">Rocky Mountain Ruby, Colorado</a></li>
<li><a href="http://www.rubyconf.co/">RubyConf, Colombia</a></li>
</ul>
<h2>We are all in ReactJS</h2>
<p>We at BigBinary adopted ReactJS pretty early. Early in the year we published
series of videos titled
<a href="https://bigbinary.com/videos/learn-reactjs-in-steps">Learn ReactJS in steps</a>
which takes a &quot;Hello World&quot; app into a full TODO application using ReactJS in
incremental steps.</p>
<p>Vipul and Prathamesh are currently authoring a book on ReactJS. Check it out at
<a href="https://www.packtpub.com/web-development/reactjs-example-building-modern-web-applications-react">ReactJS by Example- Building Modern Web Applications with React Book</a></p>
<p>We also started an ios app using React Native. It's coming along pretty good and
soon we should see it in app store.</p>
<h2>We authored many blogs</h2>
<p>We love sharing our experiences via blogs on various topics like ReactJS, Rails,
React Native and Robot framework etc. Here are some of our blogs from 2015.</p>
<ul>
<li><a href="https://www.bigbinary.com/blog/how-to-obtain-current-time-from-a-different-timezone-in-selenium-ide-using-javascript">How to obtain current time from a different timezone in Selenium IDE using javascript</a>,
Prabhakar, Jan 2015</li>
<li><a href="https://www.bigbinary.com/blog/author-information-in-jekyll-blog">Author information in jekyll blog</a>,
Neeraj, Jan 2015</li>
<li><a href="https://www.bigbinary.com/blog/phone-verification-using-twilio">Phone verification using SMS via Twilio</a>,
Santosh, Jan 2015</li>
<li><a href="https://www.bigbinary.com/blog/blue-border-around-jwplayer-video">Blue border around JWPLAYER video</a>,
Prathamesh, Feb 2015</li>
<li><a href="https://www.bigbinary.com/blog/gotcha-with-after_commit-callback-in-rails">Gotcha with after_commit callback in Rails</a>,
Prathamesh, March 2015</li>
<li><a href="https://www.bigbinary.com/blog/voice-based-phone-verification-using-twilio">Voice based phone verification using twilio</a>,
Santosh, March 2015</li>
<li><a href="https://www.bigbinary.com/blog/verifying-pubsub-services-from-rails-redis">Verifying PubSub Services from Rails using Redis</a>,
Vipul, May 2015</li>
<li><a href="https://www.bigbinary.com/blog/using-reactjs-with-rails-actioncable">Using ReactJS with Rails Action Cable</a>,
Vipul, July 2015</li>
<li><a href="https://www.bigbinary.com/blog/how-to-test-react-native-app-on-real-iphone">How to test React Native App on a real iPhone</a>,
Chirag, Aug 2015</li>
<li><a href="https://www.bigbinary.com/blog/code-optimize-javascript-code-using-babeljs">Optimize JavaScript code using BabelJS</a>,
Prathamesh, Aug 2015</li>
<li><a href="https://www.bigbinary.com/blog/configuring-pycharm-to-run-tests">Configuring Pycharm IDE to run a Robot Framework test suite or a single test script</a>,
Prabhakar, Oct 2015</li>
<li><a href="https://www.bigbinary.com/blog/migrating-from-postgresql-to-sqlserver">Migrating rails app from postgresql to sql server</a>,
Rohit, Oct 2015</li>
<li><a href="https://www.bigbinary.com/blog/getting-around-apple-ituneconnect-activation-issue">Getting around Apple iTunesConnect account activation issue</a>,
Prathamesh, Oct 2015</li>
<li><a href="https://www.bigbinary.com/blog/rails-5-allows-setting-custom-http-headers-for-assets">Rails 5 allows setting custom HTTP Headers for assets</a>,
Vipul, Oct 2015</li>
<li><a href="https://www.bigbinary.com/blog/using-stripe-api-in-react-native-with-fetch">Using Stripe API in React Native with fetch</a>,
Chirag, Nov 2015</li>
<li><a href="https://www.bigbinary.com/blog/how-constant-lookup-happens-in-rails">How constant lookup and resolution works in Ruby on Rails</a>,
Mohit, Nov 2015</li>
<li><a href="https://www.bigbinary.com/blog/explicitly-ssh-into-vagrant-machine">Explicitly ssh into vagrant machine</a>,
Neeraj, Dec 2015</li>
<li><a href="https://www.bigbinary.com/blog/application-record-in-rails-5">ApplicationRecord in Rails 5</a>, Prathamesh, Dec
2015</li>
</ul>
<h2>Video Summary</h2>
<ul>
<li><a href="https://bigbinary.com/videos/learn-ruby-on-rails">Learn Ruby on Rails</a>
<ul>
<li><a href="https://bigbinary.com/videos/learn-ruby-on-rails/use-uuid-x-request-id-and-tagged-logging-to-debug-rails-application">Use uuid, X-Request-Id and tagged logging to debug rails application</a>.</li>
<li><a href="https://bigbinary.com/videos/learn-ruby-on-rails/rails-development-using-vagrant">Rails development using vagrant</a>.</li>
<li><a href="https://bigbinary.com/videos/learn-ruby-on-rails/using-es6-in-rails-application">Using ES6 in Rails application</a>.</li>
</ul>
</li>
<li><a href="https://bigbinary.com/videos/learn-reactjs-in-steps">Learn ReactJS in step</a></li>
<li><a href="https://bigbinary.com/videos/keep-up-with-reactjs">Keep up with ReactJS</a></li>
<li><a href="https://bigbinary.com/videos/learn-javascript">Learn JavaScript</a>
<ul>
<li><a href="https://bigbinary.com/videos/learn-javascript/refactor-javascript-code-using-module-pattern">Refactor JavaScript code using module pattern</a></li>
<li><a href="https://bigbinary.com/videos/learn-javascript/a-review-of-tools-to-test-es6">A review of tools to test ES6</a></li>
</ul>
</li>
<li><a href="https://bigbinary.com/videos/learn-selenium">Learn Selenium</a></li>
</ul>
<h2>Open Source</h2>
<p>Apart from our team members contributing to various OpenSource projects, we also
support some projects from our team. This year, we added and helped build
following projects-</p>
<ul>
<li><a href="https://github.com/bigbinary/wheel">Wheel</a> : Wheel is our Rails template for
new Ruby on Rails projects, with sane defaults and setups for different
environments, and common functionalities like image uploaders, debugging, etc.</li>
<li><a href="https://github.com/bigbinary/mail_interceptor">Mail Interceptor</a> :
Interception, Forwarding emails in Ruby on Rails application</li>
<li><a href="https://github.com/bigbinary/handy">Handy</a> : A collection handy tools and
Rails tasks for your Project.</li>
<li><a href="https://github.com/bigbinary/learn-reactjs-in-steps">Learn ReactJS in Steps</a>
: Collection of examples from
<a href="https://bigbinary.com/videos/learn-reactjs-in-steps">Learn ReactJS in step</a>
video series.</li>
<li>Doctsplit Chef(Link is not available) : Check cookbox
for <a href="https://documentcloud.github.io/docsplit/">docsplit</a> ruby gem</li>
<li>Fixtures Dumper(Link is not available) : Dump your
Rails data to fixtures easily to a database to populate data.</li>
</ul>
<h2>Community Engagement</h2>
<p>Along with speaking at various conferences, we also helped organize, our Fun
edition of Pune's regional RubyConf,
<a href="http://www.deccanrubyconf.org/">DeccanRubyConf</a>, and supported other Indian
Conferences, including <a href="http://rubyconfindia.org/">RubyConfIndia</a>,
<a href="http://www.gardencityruby.org/">GardenCity RubyConf</a>.</p>
<p>We also help Pune's local <a href="http://www.meetup.com/punerailsmeetup/">ruby meetup</a>,
which had a splendid engagement this year.</p>
<p>Overall we are super excited about what we accomplished in year 2015. We are
looking forward to an exciting year of 2016!</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Explicitly ssh into vagrant machine]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/explicitly-ssh-into-vagrant-machine"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/explicitly-ssh-into-vagrant-machine.png"/>
      <id>https://www.bigbinary.com/blog/explicitly-ssh-into-vagrant-machine</id>
      <published>2015-12-27T00:00:00.000Z</published>
      <updated>2015-12-27T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/explicitly-ssh-into-vagrant-machine.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Sometimes one need to explicitly ssh into vagrant machines. This blog discusses how to get that done.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/explicitly-ssh-into-vagrant-machine"><![CDATA[<p>After building vagrant machine the command to ssh into the guest machine is
pretty simple.</p>
<pre><code class="language-plaintext">vagarnt ssh
</code></pre>
<p>While working with chef I needed to explicitly ssh into the vagrant machine. It
took me sometime to figure it out.</p>
<p>The key is command <code>vagrant ssh-config</code>. The output might look like this.</p>
<pre><code class="language-plaintext">$ vagrant ssh-config
Host vmachine
  HostName 127.0.0.1
  User vagrant
  Port 2222
  UserKnownHostsFile /dev/null
  StrictHostKeyChecking no
  PasswordAuthentication no
  IdentityFile /Users/nsingh/code/vagrant-machine/.vagrant/machines/vmachine/virtualbox/private_key
  IdentitiesOnly yes
  LogLevel FATAL
  ForwardAgent yes
</code></pre>
<p>Open <code>~/.ssh/config</code> and paste the output at the end of the file and save the
file.</p>
<p>Now I can ssh into vagrant machine using ssh command as shown below.</p>
<pre><code class="language-plaintext">ssh vmachine
</code></pre>
<p>If you are wondering from where the name <code>vmachine</code> came then this is the name I
had given to
<a href="https://github.com/bigbinary/vagrant-machine/blob/f5257dc088dfdf07c73e57130425c28a363dc399/Vagrantfile#L17">my vagrant machine</a>
.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Configuring Pycharm IDE to run a Robot Framework test]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/configuring-pycharm-to-run-tests"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/configuring-pycharm-to-run-tests.png"/>
      <id>https://www.bigbinary.com/blog/configuring-pycharm-to-run-tests</id>
      <published>2015-10-11T00:00:00.000Z</published>
      <updated>2015-10-11T00:00:00.000Z</updated>
      <author>
        <name>Prabhakar Battula</name>
        <uri>https://www.bigbinary.com/blog/authors/prabhakarbattula</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/configuring-pycharm-to-run-tests.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[How to configure Pycharm IDE to run a Robot Framework test suite or a single test script]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/configuring-pycharm-to-run-tests"><![CDATA[<p><a href="https://www.jetbrains.com/pycharm">Pycharm</a> is a convenient IDE to work with
<a href="http://robotframework.org">Robot framework</a>. To run a test suite or a test
script, one can do so only through console. Running tests through console is
very demanding. If user can run tests from Pycharm itself then that helps
improve productivity. This blog explains how to configure Pycharm to be able to
run test suite or a single test from the IDE itself.</p>
<h2>Configuration to run a single test script</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2015/configuring-pycharm-to-run-tests/p1.png" alt="pycharm robot 1">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2015/configuring-pycharm-to-run-tests/p2.png" alt="pycharm robot 2">
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2015/configuring-pycharm-to-run-tests/p3.png" alt="pycharm robot 3"></p>
<p>Running a single test script</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2015/configuring-pycharm-to-run-tests/p4.png" alt="pycharm robot 4"></p>
<h2>Configuration to run a particular test suite</h2>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2015/configuring-pycharm-to-run-tests/p5.png" alt="pycharm robot 5"></p>
<p>Running a particular test suite</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2015/configuring-pycharm-to-run-tests/p6.png" alt="pycharm robot 6"></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Blue border around JWPLAYER video]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/blue-border-around-jwplayer-video"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/blue-border-around-jwplayer-video.png"/>
      <id>https://www.bigbinary.com/blog/blue-border-around-jwplayer-video</id>
      <published>2015-02-21T00:00:00.000Z</published>
      <updated>2015-02-21T00:00:00.000Z</updated>
      <author>
        <name>Prathamesh Sonpatki</name>
        <uri>https://www.bigbinary.com/blog/authors/prathamesh</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/blue-border-around-jwplayer-video.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[How to remove blue border around JWPlayer]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/blue-border-around-jwplayer-video"><![CDATA[<p>Latest versions of JWPlayer(6.9 onwards)
adds blue border around the video
when it is in focus.</p>
<p>This is because of the CSS class <code>jwplayer-tab-focus</code>.</p>
<p>The blue border
around currently selected video
allows to identify
which instance of JWPlayer is in focus.</p>
<p>But with a single JWPlayer instance, it can be annoying.</p>
<p>To remove this blue border,
we can override the default JWPlayer CSS as follows.</p>
<pre><code class="language-css">.jw-tab-focus:focus {
  outline: none;
}
</code></pre>
<p>To keep all the overridden CSS in once place,
we can add this change in a separate file such as <code>jwplayer_overrides.css</code>.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[2014 - Year in Community Engagement]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/2014-year-in-community-engagement"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/2014-year-in-community-engagement.png"/>
      <id>https://www.bigbinary.com/blog/2014-year-in-community-engagement</id>
      <published>2015-01-01T00:00:00.000Z</published>
      <updated>2015-01-01T00:00:00.000Z</updated>
      <author>
        <name>Vipul</name>
        <uri>https://www.bigbinary.com/blog/authors/vipulnsward</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/2014-year-in-community-engagement.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[At BigBinary our team loves to engage with the community as well as help out in different ways. We love contributing to OpenSource, speak and attend different conferences, and help out in community...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/2014-year-in-community-engagement"><![CDATA[<p>At BigBinary our team loves to engage with the community as well as help out in
different ways. We love contributing to <a href="https://bigbinary.com/open-source">OpenSource</a>,
<a href="https://bigbinary.com/presentations">speak and attend different conferences</a>, and help
out in community meetups, <a href="https://www.bigbinary.com/blog/deccanrubyconf">organizing conferences</a>,
and events like <a href="https://www.bigbinary.com/blog/rails-girls-pune-2014">RailsGirls</a> .</p>
<h2>Short summary</h2>
<p>In year 2014
we presented at
following 8 conferences
across 6 countries.</p>
<ul>
<li>RubyConf Goa, India</li>
<li>RubyConf Philippines</li>
<li>RedDotRubyConf Singapore</li>
<li>DeccanRubyConf Pune, India</li>
<li>Madion+Ruby Wisconsin, USA</li>
<li>RubyConf Brazil</li>
<li>RubyKaigi Tokyo, Japan</li>
<li>Golden Gate Ruby Conference San Francisco, USA</li>
</ul>
<h2>Rails and Ruby Conferences</h2>
<p><a href="https://www.mapquest.com/embed?hk=1x7D17Q">View the embedded content</a></p>
<p>At the start of our travel, we visited <a href="http://rubyconfindia.org">RubyConfIndia 2014</a>.
The conference took place at an amazing beach resort in Goa. The two days of conference
were full of fun and interactions with the best ruby people around India. During the
conference our team announced launch of <a href="http://www.rubyindia.org/">Ruby India</a> to help
spread ideas and experiments from the Ruby Indian Community, as well as highlight
content from people.</p>
<p>Soon after, I visited Philippines, to conduct a workshop on &quot;Contributing to Rails&quot; at
<a href="http://rubyconf.ph">RubyConf Philippines</a>. It was amazing to meet the growing
Philippines community. I was happy to spend time with some amazing Rubyists, like
<a href="https://twitter.com/apotonick">Nick Sutterer</a>, <a href="https://twitter.com/_zzak">Zachary Scott</a>,
<a href="https://twitter.com/konstantinhaase">Konstantin Hasse</a>,
<a href="https://twitter.com/_ko1">Koichi Sasada San</a>,
<a href="https://twitter.com/aspleenic">PJ Hagerty</a>,
<a href="https://twitter.com/indirect">Andre Arko</a> and so on.</p>
<p>After that I and Prathamesh went to Singapore to speak at
<a href="http://reddotrubyconf.com">RedDotRubyConf</a>. We spoke on Arel and
ActiveRecord. &quot;RedDorRubyConf&quot; was our first joint talk together at a conference.
Again we met a lot of awesome people like <a href="https://twitter.com/_solnic_">Piotr Solnica</a>,
<a href="https://twitter.com/arnvald">Grzegorz Witek</a>,
<a href="https://twitter.com/yinquanteo">Yinquan Teo</a>,
<a href="https://twitter.com/sayanee_">Sayanee Basu</a>,
<a href="https://twitter.com/ntt">Chinmay Pendharkar</a>
and <a href="https://twitter.com/winstonyw">Winston Teo Yong Wei</a>.
We also visited Marina Sand Bay and Sentosa Island.</p>
<p>Back in Pune, we hosted the first ever <a href="http://www.deccanrubyconf.org/">DeccanRubyConf</a>.
Our team was busy working on tasks right from building the website, inviting speakers,
planning, and other arrangements. The conference had good talks and some really useful workshops.
it was a fun one day conference, with attendance of over 170+ people.</p>
<p>The conference also saw our team announce the launch of RubyIndia Podcast,
which does regular podcast interviews with notable people from the Ruby Community and
Indian Community.</p>
<p><a href="https://bigbinary.com/team">Prathamesh</a> and I, then left on around a one and a half month
travel, to attend and speak at multiple conferences.</p>
<p>We started with <a href="http://madisonpl.us/">Madison+Ruby</a>, in Madison, WI. After several
missed flights, and a storm, we visited our first US conference after a travel of 48
hours. MadisonRuby was a conference like no other. Several topics touched the humane
side of Ruby and the community. We spoke on 'Building an own ORM using ARel'. Set in the
cultural town of Madison, we immensely enjoyed the cheese-curds, farmers markets and game night
arranged by the Conf team. A huge thanks to <a href="https://twitter.com/jremsikjr">Jim</a> and
<a href="https://twitter.com/JenRemsik">Jennifer Remsik</a>,
for hosting such an amazing event. Thanks also to <a href="https://twitter.com/ruttencutter">Scott Ruttencutter</a>
for giving us space to work from his office and giving us a tour of the state capital.</p>
<p>We then visited Sao Paulo, Brazil for <a href="http://rubyconf.com.br">RubyConf Brazil</a> and presented a talk
on Building an ORM using ARel. It was a pleasure to meet <a href="https://twitter.com/AkitaOnRails">Fabio Akita</a>
and the CodeMiner team. We made friends with <a href="https://twitter.com/celsovjf">Celso Fernandes</a>
and <a href="https://twitter.com/plribeiro3000">Paulo</a>
who were kind enough to help us around, since in Brazil primarily
portuguese is spoken. We also met <a href="https://twitter.com/rafaelfranca">Rafael Franca</a> and
<a href="https://twitter.com/cantoniodasilva">Carlos Antonio da Silva</a>
who have helped us a lot with Rails issue tracker.</p>
<p>Next Prathamesh headed to <a href="http://rubykaigi.org">RubyKaigi</a>, being held in Tokyo, Japan.
He presented on
<a href="https://www.bigbinary.com/blog/tricks-and-tips-for-using-fixtures-in-rails">Fixtures in Rails</a>.
He met Matz, creator of Ruby on his first day in Japan. Mostly all the
core Ruby contributors attended RubyKaigi. He got to interact with
Koichi Sasada San, <a href="https://twitter.com/1337807">Jonan Scheffler</a>,
<a href="https://twitter.com/a_matsuda">Akira Matsuda</a>,
<a href="https://twitter.com/chancancode">Godfrey Chan</a>,
<a href="https://twitter.com/schneems">Richard Schneeman</a> and lot of awesome Rubyists.
He also met with his JRuby Core <a href="https://twitter.com/tom_enebo">Tom Enebo</a> for the first time.
Thanks to <a href="https://twitter.com/yahonda">Yasuo Honda</a>, <a href="https://twitter.com/mreinsch">Michael Reinsch</a> for helping with Japanese food.</p>
<p>From Brazil, I first visited Miami, and was happy to visit <a href="http://thelabmiami.com/">The Lab Miami</a>,
<a href="http://wyncode.co/">WynCode</a> and interact with Rubyists from Miami.</p>
<p>Before heading to San Francisco, for GoGaRuco, I was able to make a quick stop in Boston and visit
<a href="http://www.alterconf.com/sessions/boston-ma">AlterConf Boston</a>. The theme of the conference was around
diversity in tech and gaming industry.</p>
<p>My latest conference was in the amazing city on San Francisco. I presented about 'Building an ORM',
at <a href="http://gogaruco.com">GoGaRuCo</a>, which incidentally was the last ever GoGaRuCo. The conference
taking place in San Francisco, saw an amazing turnout of crowd. I was able to interact with
<a href="https://twitter.com/ultrasaurus">Sarah Allen</a>, <a href="https://twitter.com/wycats">Yehuda Katz</a>,
<a href="https://twitter.com/pat">Pat Allen</a>, <a href="https://twitter.com/sarahmei">Sarah Mei</a>,
<a href="https://twitter.com/the_zenspider">Ryan Davis</a>. I spent most of the time along with
<a href="https://twitter.com/sleeplessgeek">Nathan Long</a>, <a href="https://twitter.com/randycoulman">Randy Coulman</a>,
and Nathan's friend <a href="http://sorryrobot.com/">Michael Gundlach</a>,
who is the creator of popular
plugin <a href="https://getadblock.com">Adblock</a>.
I also ran into <a href="https://twitter.com/chriseppstein">Chris Eppstein</a>, creator of <a href="http://compass-style.org">compass</a>.
All around it was one of the most amazing interactions I had in a conference.</p>
<p>2014, was an amazing year for our team. Together we presented or were part of 8 conferences,
launched RubyIndia Newsletter as well as the RubyIndia Podcast, started with 6 new video
series on topics from <a href="https://www.bigbinary.com/videos/learn-reactjs-in-steps">ReactJS</a> to
<a href="https://www.bigbinary.com/videos/learn-rubymotion">Rubymotion</a> to
<a href="https://www.bigbinary.com/videos/learn-selenium">Selenium</a>, published <a href="https://www.bigbinary.com/blog">numerous blogs</a>,
and contributed to a number of OpenSource projects.</p>
<p>2015, starts with our team presenting at <a href="http://gardencityruby.org">GardenCityRuby Conf</a>.
We hope to get more such chances to interact and help out the community. Onwards to a new year!</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Selenium IDE - Reducing time from 58 min to 15 min]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/how-i-reduced-selenium-test-run-time-from-58-minutes-to-15-minutes"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/how-i-reduced-selenium-test-run-time-from-58-minutes-to-15-minutes.png"/>
      <id>https://www.bigbinary.com/blog/how-i-reduced-selenium-test-run-time-from-58-minutes-to-15-minutes</id>
      <published>2014-09-08T00:00:00.000Z</published>
      <updated>2014-09-08T00:00:00.000Z</updated>
      <author>
        <name>Prabhakar Battula</name>
        <uri>https://www.bigbinary.com/blog/authors/prabhakarbattula</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/how-i-reduced-selenium-test-run-time-from-58-minutes-to-15-minutes.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[This post is about hastening the execution of selenium tests.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/how-i-reduced-selenium-test-run-time-from-58-minutes-to-15-minutes"><![CDATA[<p>I wrote a bunch of selenium tests using
<a href="http://www.seleniumhq.org/download">Selenium IDE</a> for a project. The selenium
tests have proven to be very useful. However the tests take around 58 minutes to
complete the full run.</p>
<p>Here are the specific steps I took which brought the running time to under 15
minutes.</p>
<h2>Set to run at the maximum speed</h2>
<table>
  <tr>
    <td> Command </td>
    <td> Target </td>
    <td> Value </td>
  </tr>
  <tr>
    <td>setSpeed </td>
    <td>0 </td>
    <td></td>
  </tr>
</table>
<p><code>setSpeed</code> command takes <code>Target</code> value in milliseconds. By setting the value to
zero, I set the speed to maximum and the tests indeed ran fast. However, now I
had lots of tests failing which were previously passing.</p>
<p>What happened.</p>
<p>In our tests real firefox browser is fired up and real elements are clicked. The
application does make round trip to the rails server hosted on heroku.</p>
<p>By setting the selenium tests to the maximum speed the selenium tests started
asserting for elements on the page even before the pages were fully loaded by
the browser.</p>
<p>I needed sets of instructions using which I could tell selenium how long to wait
for before asserting for elements.</p>
<p>Selenium provides a wonderful suite of commands which helped me fine tune the
test run. Here I'm discussing some of those commands.</p>
<h2>waitForVisible</h2>
<p>This command is used to tell selenium to wait until the specified element is
visible on the page.</p>
<p>In the below mentioned case, the Selenium IDE will wait until the element
<code>css=#text-a</code> is visible on the page.</p>
<table>
  <tr>
    <td> Command</td>
    <td> Target</td>
    <td> Value</td>
  </tr>
  <tr>
    <td>waitForVisible</td>
    <td>css=#text-a</td>
    <td> </td>
  </tr>
</table>
<h2>waitForText</h2>
<p>This command is used to tell selenium to wait until a particular text is visible
in the specified element.</p>
<p>In the case mentioned below, Selenium IDE will wait until the text <code>violet</code> is
displayed in the element <code>css=#text-a</code>.</p>
<table>
  <tr>
    <td> Command</td>
    <td> Target</td>
    <td> Value</td>
  </tr>
  <tr>
    <td>waitForText</td>
    <td>css=#text-a</td>
    <td>violet</td>
  </tr>
</table>
<br />
<p>The difference between <em>waitForVisible</em> and <em>waitForText</em> is that
<strong>waitForVisible waits until the specified element is visible on the page</strong>
while <strong>waitForText waits until a particular text is visible in the specified
element on the page</strong>.</p>
<h2>waitForElementPresent</h2>
<p>This command is used to tell Selenium to wait until the specified element is
displayed on the page.</p>
<p>In the below mentioned case, the Selenium IDE will wait until the element
<code>css=a.button</code> is displayed on the page.</p>
<table>
  <tr>
    <td> Command</td>
    <td> Target</td>
    <td> Value</td>
  </tr>
  <tr>
    <td>waitForElementPresent</td>
    <td>css=a.button</td>
    <td></td>
  </tr>
</table>
<p><em>waitForVisible</em> and <em>waitForElementPresent</em> seem very similar. It seems both of
these commands do the same thing. There is a subtle difference though.</p>
<p><em>waitForVisible</em> waits until the specified element is visible. Visibility of an
element is manipulated by the settings of CSS properties. For example using
<code>display none;</code> one can make an element not be visible at all.</p>
<p>In contrast the command <em>waitForElementPresent</em> waits until the specified
element is present on the page in the form of html markup. This command does not
give consideration to css settings.</p>
<h2>refreshAndWait</h2>
<p>This command is used to tell Selenium to wait until the page is refreshed and
the targeted element is displayed on the web page.</p>
<p>In the example mentioned below, the Selenium IDE will wait until the page is
refreshed and the targeted element <code>css=span.button</code> is displayed on the page.</p>
<table>
  <tr>
    <td> Command</td>
    <td> Target</td>
    <td> Value</td>
  </tr>
  <tr>
    <td>refreshAndWait</td>
    <td>css=span.button</td>
    <td></td>
  </tr>
</table>
<h2>clickAndWait</h2>
<p>This command is used to tell selenium to wait until a particular button is
clicked for submitting the form and the page starts reloading. The subsequent
commands are paused until, the page is reloaded after the element is clicked on
the page.</p>
<p>In the case mentioned below, Selenium IDE will wait until the page is reloaded
after the specified element <code>css=input#edit</code> is clicked.</p>
<table>
  <tr>
    <td> Command</td>
    <td> Target</td>
    <td> Value</td>
  </tr>
  <tr>
    <td>clickAndWait</td>
    <td>css=input#edit</td>
    <td></td>
  </tr>
</table>
<p>Selenium IDE commands used above and more are available at
<a href="http://docs.seleniumhq.org/docs/02_selenium_ide.jsp#selenium-commands-selenese">Selenium documentation</a>
.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Do not allow force push to master]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/do-not-allow-force-push-to-master"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/do-not-allow-force-push-to-master.png"/>
      <id>https://www.bigbinary.com/blog/do-not-allow-force-push-to-master</id>
      <published>2013-09-19T00:00:00.000Z</published>
      <updated>2013-09-19T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/do-not-allow-force-push-to-master.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Force push is dangerous. But it is needed sometimes. And sometimes one can force push to master by mistake. A look at how to avoid that.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/do-not-allow-force-push-to-master"><![CDATA[<p>At BigBinary we create a branch for every issue. We deploy that branch and only
when it is approved that branch is merged into master.</p>
<p>Time to time we rebase the branch. And after rebasing we need to do <code>force</code> push
to send the changes to github. And once in a while someone <code>force</code> pushes into
master by mistake. We recommend to set <a href="https://www.bigbinary.com/how-we-work">push.default to current</a>
to avoid such issues but still sometimes force push does happen in master.</p>
<p>In order to prevent such mistakes in future we are using
<a href="https://github.com/bigbinary/tiny_scripts/blob/master/git-hooks/hooks/pre-push">pre-push hook</a>.
This is a small ruby program which runs before any <code>git push</code> command. If you
are force pushing to <code>master</code> then it will reject the push like this.</p>
<pre><code class="language-plaintext">*************************************************************************
Your attempt to FORCE PUSH to MASTER has been rejected.
If you still want to FORCE PUSH then you need to ignore the pre_push git hook by executing following command.
git push master --force --no-verify
*************************************************************************
</code></pre>
<h2>Requirements</h2>
<p><code>pre-push</code> hook was
<a href="https://github.com/git/git/blob/master/Documentation/RelNotes/1.8.2.txt#L167">added to git</a>
in version 1.8.2. So you need git 1.8.2 or higher. You can easily upgrade git by
executing <code>brew upgrade git</code> .</p>
<pre><code class="language-plaintext">$ git --version
git version 1.8.2.3
</code></pre>
<h2>Setting up hooks</h2>
<p>In order for these hooks to kick in they need to be setup.</p>
<p>First step is to clone the <a href="https://github.com/bigbinary/tiny_scripts">repo</a> to
your local machine. Now open <code>~/.gitconfig</code> and add following line.</p>
<pre><code class="language-plaintext">[init]
  templatedir= /Users/neeraj/code/tiny_scripts/git-hooks
</code></pre>
<p>Change the value <code>/Users/neeraj/code/tiny_scripts/git-hooks</code> to match with the
directory of your machine.</p>
<h2>Making existing repositories aware of this hook</h2>
<p>Now <code>pre-push</code> hook is setup. Any new repository that you clone will have the
feature of not being able to force push to master.</p>
<p>But existing repositories do not know about this git-hook. To make existing
repositories aware of this hook execute following command on all repositories.</p>
<pre><code class="language-plaintext">$ git init
Reinitialized existing Git repository in /Users/nsingh/dev/projects/streetcommerce/.git/
</code></pre>
<p>Now if you look into the <code>.git/hooks</code> directory of your project you should see a
file called <code>pre-push</code>.</p>
<pre><code class="language-plaintext">$ ls .git/hooks/pre-push
.git/hooks/pre-push
</code></pre>
<p>It means this project is all set with <code>pre-push</code> hook.</p>
<h2>New repositories</h2>
<p>When you clone a repository then <code>git init</code> is invoked automatically and you
will get <code>pre-push</code> already copied for you. So you are all set for all future
repositories too.</p>
<h2>How to ignore pre-push hook</h2>
<p>To ignore <code>pre-push</code> hook all you need to do is</p>
<pre><code class="language-plaintext"># Use following command to ignore pre-push check and to force update master.
git push master --force --no-verify
</code></pre>
<p><a href="https://github.com/bigbinary/tiny_scripts/blob/master/git-hooks/hooks/pre-push">The hook is here</a>
.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[How to keep your fork up-to-date]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/how-to-keep-your-fork-uptodate"/>
      <link rel="enclosure" type="image/png" href="https://www.bigbinary.com/blog/images/social_preview_images/generated/how-to-keep-your-fork-uptodate.png"/>
      <id>https://www.bigbinary.com/blog/how-to-keep-your-fork-uptodate</id>
      <published>2013-09-13T00:00:00.000Z</published>
      <updated>2013-09-13T00:00:00.000Z</updated>
      <author>
        <name>Neeraj Singh</name>
        <uri>https://www.bigbinary.com/blog/authors/neerajsingh0101</uri>
      </author>
      <category term="Misc"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/generated/how-to-keep-your-fork-uptodate.png" width="1200" height="630"/>
      <summary type="text"><![CDATA[Keeping the fork up-to-date is no easy task. This blog can help.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/how-to-keep-your-fork-uptodate"><![CDATA[<p>Let's say that I'm forking repo <code>rails/rails</code>. After the repo has been forked to
my repository I will clone it on my local machine.</p>
<pre><code class="language-plaintext">git clone git@github.com:neerajsingh0101/rails.git
</code></pre>
<p>Now <code>cd rails</code> and execute <code>git remote -v</code> . This is what I see.</p>
<pre><code class="language-plaintext">origin git@github.com:neerajsingh0101/rails.git (fetch)
origin git@github.com:neerajsingh0101/rails.git (push)
</code></pre>
<p>Now I will add <code>upstream remote</code> by executing following command.</p>
<pre><code class="language-plaintext">git remote add upstream git@github.com/rails/rails.git
</code></pre>
<p>After having done that when I execute <code>git remote -v</code> then I see</p>
<pre><code class="language-plaintext">origin git@github.com:neerajsingh0101/rails.git (fetch)
origin git@github.com:neerajsingh0101/rails.git (push)
upstream git://github.com/rails/rails.git (fetch)
upstream git://github.com/rails/rails.git (push)
</code></pre>
<p>Now I want to make some changes to the code. After all this is why I forked the
repo.</p>
<p>Let's say that I want to add exception handling to the forked code I have
locally. Then I create a branch called <code>exception-handling</code> and make all your
changes in this branch. <strong>The key here is to not to make any changes to <code>master</code>
branch</strong>. I try to keep master of my forked repository in sync with the master
of the original repository where I forked it.</p>
<p>So now let's create a branch and I will put in all my changes there.</p>
<pre><code class="language-plaintext">git checkout -b exception-handling
</code></pre>
<p>In the <code>Gemfile</code> I will use this code like this</p>
<pre><code class="language-plaintext">gem 'rails', github: 'neerajsingh0101/rails', branch: 'exception-handling'
</code></pre>
<p>A month has passed. In the meantime rails master has tons of changes. I want
those changes in my <code>exception-handling</code> branch. In order to achieve that first
I need to bring my local master up-to-date with rails master.</p>
<p>I need to switch to master branch and then I need to execute following commands.</p>
<pre><code class="language-plaintext">git checkout master
git fetch upstream
git rebase upstream/master
git push
</code></pre>
<p>Now the master of forked repository is in-sync with the master of <code>rails/rails</code>.
Now that master is up-to-date I need to pull in the changes in master in my
<code>exception-handling</code> branch.</p>
<pre><code class="language-plaintext">git checkout exception-handling
git rebase master
git push -f
</code></pre>
<p>Now my branch <code>exception-handling</code> has my fix on top of rails master.</p>
]]></content>
    </entry>
</feed>