<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom" xmlns:media="http://search.yahoo.com/mrss/" xml:lang="en-US">
  <title>BigBinary Blog: NeetoDeploy</title>
  <subtitle>Deep technical writing on Ruby on Rails, performance, scaling, monitoring and engineering.</subtitle>
  <link rel="self" type="application/atom+xml" href="https://www.bigbinary.com/blog/categories/neetodeploy/feed.xml"/>
  <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/categories/neetodeploy"/>
  <id>https://www.bigbinary.com/blog/categories/neetodeploy</id>
  <updated>2024-07-09T00:00:00.000Z</updated>
  <author>
    <name>BigBinary</name>
    <uri>https://www.bigbinary.com/</uri>
  </author>
  <icon>https://www.bigbinary.com/favicon.ico</icon>
  <logo>https://www.bigbinary.com/images/bigbinary_square_big_logo.png</logo>
  <rights>Copyright 2024 Big Binary LLC</rights>
  <generator uri="https://nextjs.org">Next.js</generator>
  <entry>
      <title type="text"><![CDATA[How we fixed app downtime issue in NeetoDeploy]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/how-we-fixed-app-down-time-in-neeto-deploy"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/how_we_fixed_app_downtime_in_neetoDeploy.jpg"/>
      <id>https://www.bigbinary.com/blog/how-we-fixed-app-down-time-in-neeto-deploy</id>
      <published>2024-07-09T00:00:00.000Z</published>
      <updated>2024-07-09T00:00:00.000Z</updated>
      <author>
        <name>Abhishek T</name>
        <uri>https://www.bigbinary.com/blog/authors/abhishekt98</uri>
      </author>
      <category term="NeetoDeploy"/>
      <category term="Kubernetes"/>
      <category term="DevOps"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/how_we_fixed_app_downtime_in_neetoDeploy.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[We are building NeetoDeploy, a compelling alternative to Heroku. Stay updated by following NeetoDeploy on Twitter and reading our blog. At neeto we are building 20+ applications, and most of our...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/how-we-fixed-app-down-time-in-neeto-deploy"><![CDATA[<p><em>We are building <a href="https://neeto.com/neetoDeploy">NeetoDeploy</a>, a compelling
alternative to Heroku. Stay updated by following NeetoDeploy on
<a href="https://twitter.com/neetodeploy">Twitter</a> and reading our
<a href="https://www.bigbinary.com/blog/categories/neetodeploy">blog</a>.</em></p>
<p>At <a href="https://www.neeto.com/">neeto</a> we are building 20+ applications, and most of
our applications are running in NeetoDeploy. Once we migrated from Heroku to
NeetoDeploy, we started getting 520 response code for our applications. This
issue was occurring randomly and rarely.</p>
<h3>What is 520 response code?</h3>
<p>A 520 response code happens when the connection is started on the origin web
server, but the request is not completed. This could be due to server crashes or
the inability to handle the incoming requests because of insufficient resources.</p>
<p>When we looked at our logs closely, we found that all the 520 response code
situations occurred when we restarted or deployed the app. From this, we
concluded that the new pods are failing to handle requests from the client
initially and working fine after some time.</p>
<h3>What is wrong with new pods?</h3>
<p>Once our investigation narrowed down to the new pods, we quickly realized that
requests are arriving at the server even when the server is not fully ready yet
to take new requests.</p>
<p>When we create a new pod in Kubernetes, it is marked as &quot;Ready&quot;, and requests
are sent to it as soon as its containers start. However, the servers initiated
within these containers may require additional time to boot up and to become
ready to accept the requests fully.</p>
<h4>Let's try restarting the application</h4>
<pre><code class="language-bash">$ kubectl rollout restart deployment bling-staging-web
</code></pre>
<p>As we can see, a new container is getting created for the new pod. The READY
status for the new pod is 0. It means it's not yet READY.</p>
<pre><code class="language-bash">NAME                               READY  STATUS             RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  1/1    Running            0         2m8s
bling-staging-web-79fc6f978-cdjf5  0/1    ContainerCreating  0         5s
</code></pre>
<p>Now we can see that the new pod is marked as READY (1 out of 1), and the old one
is terminating.</p>
<pre><code class="language-bash">NAME                               READY  STATUS             RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  0/1    Terminating        0         2m9s
bling-staging-web-79fc6f978-cdjf5  1/1    Running            0         6s
</code></pre>
<p>The new pod is shown as <code>READY</code> as soon as the container was created. But on
checking the logs, we could see that the server was still starting up and not
ready yet.</p>
<pre><code>[1] Puma starting in cluster mode...
[1] Installing dependencies...
</code></pre>
<p>From the above observation, we understood that the pod is marked as &quot;READY&quot;
right after the container is created. Consequently, requests are received even
before the server is fully prepared to serve them, and they get a 520 response
code.</p>
<h2>Solution</h2>
<p>To fix this issue, we must ensure that pods are marked as &quot;Ready&quot; only after the
server is up and ready to accept the requests. We can do this by using
Kubernetes
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/">health probes</a>.
More than six years ago we wrote
<a href="https://www.bigbinary.com/blog/deploying-rails-applications-using-kubernetes-with-zero-downtime">a blog</a>
on how we can leverage the readiness and liveness probes of Kubernetes.</p>
<h3>Adding Startup probe</h3>
<p>Initially, we only added
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#define-startup-probes">Startup probe</a>
since we had a problem with the boot-up phase. You can read more about the
configuration settings
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#configure-probes">here</a>.</p>
<p>The following configuration will add the Startup probe for the deployments:</p>
<pre><code class="language-yaml">startupProbe:
  failureThreshold: 10
  httpGet:
    path: /health_check
    port: 3000
    scheme: HTTP
  periodSeconds: 5
  successThreshold: 1
  timeoutSeconds: 60
  initialDelaySeconds: 10
</code></pre>
<p><code>/health_check</code> is a route in the application that is expected to return a 200
response code if all is going well. Now, let's restart the application again
after adding the Startup probe.</p>
<p>Container is created for the new pod, but the pod is still not &quot;Ready&quot;.</p>
<pre><code class="language-bash">NAME                               READY  STATUS            RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  1/1    Running           0         2m8s
bling-staging-web-79fc6f978-cdjf5  0/1    Running           0         5s
</code></pre>
<p>The new pod is marked as &quot;Ready&quot;, and the old one is &quot;Terminating&quot;.</p>
<pre><code class="language-bash">NAME                               READY  STATUS            RESTARTS  AGE
bling-staging-web-656f74d9d-6kpzz  0/1    Terminating       0         2m38s
bling-staging-web-79fc6f978-cdjf5  1/1    Running           0         35s
</code></pre>
<p>If we check the logs, we can see the health check request:</p>
<pre><code>  [1] Puma starting in cluster mode...
  [1] Installing dependencies...
  [1] * Puma version: 6.3.1 (ruby 3.2.2-p53) (&quot;Mugi No Toki Itaru&quot;)
  [1] *  Min threads: 5
  [1] *  Max threads: 5
  [1] *  Environment: heroku
  [1] *   Master PID: 1
  [1] *      Workers: 1
  [1] *     Restarts: (✔) hot (✔) phased
 [1] * Listening on http://0.0.0.0:3000
 [1] Use Ctrl-C to stop
 [2024-02-10T02:40:48.944785 #23]  INFO -- : [bb9e756a-51cc-4d6b-9a4a-96b0464f6740] Started GET &quot;/health_check&quot; for 192.168.120.195 at 2024-02-10 02:40:48 +0000
 [2024-02-10T02:40:48.946148 #23]  INFO -- : [bb9e756a-51cc-4d6b-9a4a-96b0464f6740] Processing by HealthCheckController#healthy as */*
 [2024-02-10T02:40:48.949292 #23]  INFO -- : [bb9e756a-51cc-4d6b-9a4a-96b0464f6740] Completed 200 OK in 3ms (Allocations: 691)
</code></pre>
<p>Now, the pod is marked as &quot;Ready&quot; only after the health check succeeds, in other
words, only when the server is prepared to accept the requests.</p>
<h3>Fixing the Startup probe for production applications</h3>
<p>Once we released the health check for our deployments, we found that health
checks were failing for all production applications but working for staging and
review applications.</p>
<p>We were getting the following error in our production applications.</p>
<pre><code class="language-bash">Startup probe failed: Get &quot;https://192.168.43.231:3000/health_check&quot;: http: server gave HTTP response to HTTPS client

2024-02-12 06:40:04 +0000 HTTP parse error, malformed request: #&lt;Puma::HttpParserError: Invalid HTTP format, parsing fails. Are you trying to open an SSL connection to a non-SSL Puma?&gt;
</code></pre>
<p>From the above logs, it was clear that the issue was related to SSL
configuration. On comparing the production environment configuration with the
others, we figured out that we had enabled
<a href="https://guides.rubyonrails.org/configuring.html#config-force-ssl">force_ssl</a>
for production applications. The <code>force_ssl=true</code> setting ensures that all
incoming requests are SSL encrypted and will automatically redirect to their SSL
counterparts.</p>
<p>The following diagram broadly shows the path of an incoming request.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/how-we-fixed-app-down-time-in-neeto-deploy/image4.png" alt="HTTPS request path"></p>
<p>From the above diagram, we can infer the following things:</p>
<ul>
<li>SSL verification is happening in the ingress controller and not in the server.</li>
<li>Client requests are going through the ingress controller before reaching the
server.</li>
<li>Request from ingress controller to the pod is an HTTP request.</li>
<li>The HTTP health check requests are directly sent from Kubelet to the pod and
do not go through the ingress controller.</li>
</ul>
<p>Here is how our health check request works.</p>
<ol>
<li><a href="https://kubernetes.io/docs/reference/command-line-tools-reference/kubelet/">Kubelet</a>
sends an HTTP request to the server directly.</li>
<li>Since <code>force_ssl</code> is enabled,
<a href="https://api.rubyonrails.org/v7.1.2/classes/ActionDispatch/SSL.html">ActionDispatch::SSL</a>
middleware redirects the request to HTTPS.</li>
<li>When the HTTPS request reaches the server, <a href="https://puma.io/">Puma</a> throws
<code>Are you trying to open an SSL connection to a non-SSL Puma?</code> error since no
SSL certificates are configured with the server.</li>
</ol>
<p>The solution to our problem lies in understanding why only the health check
request is rejected, whereas the request from the ingress controller is not,
even though both are HTTP requests. This is because ingress controller sets some
headers before forwarding to the pod, and the header we are concerned about is
<a href="https://developer.mozilla.org/en-US/docs/Web/HTTP/Headers/X-Forwarded-Proto">X-FORWARDED-PROTO</a>.
The <code>X-Forwarded-Proto</code> header contains the HTTP/HTTPS scheme the client used to
access the application. When a client makes an HTTPS request, the ingress
controller terminates the SSL/TLS connection and forwards the request to the
backend service using plain HTTP after adding the<code>X-Forwarded-Proto</code> along with
the other headers.</p>
<p>Everything started working after adding the <code>X-Forwarded-Proto</code> header to our
startup probe request.</p>
<pre><code class="language-yaml">startupProbe:
  failureThreshold: 10
  httpGet:
    httpHeaders:
      - name: X-FORWARDED-PROTO
        value: https
    path: &lt;%= health_check_url %&gt;
    port: &lt;%= port %&gt;
    scheme: HTTP
  periodSeconds: 5
  successThreshold: 1
  timeoutSeconds: 60
  initialDelaySeconds: 10
</code></pre>
<p>We also added
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#define-readiness-probes">Readiness</a>
and
<a href="https://kubernetes.io/docs/tasks/configure-pod-container/configure-liveness-readiness-startup-probes/#define-a-liveness-http-request">Liveness</a>
probes for our deployments.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">Twitter</a>. You can also join our
Slack community to chat with us about any Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Adding sleep when idle to NeetoDeploy to cut costs]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/how_we_added_sleep_when_idle_feature_to_neetoDeploy_and_reduced_cost.jpg"/>
      <id>https://www.bigbinary.com/blog/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps</id>
      <published>2024-01-19T00:00:00.000Z</published>
      <updated>2024-01-19T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="NeetoDeploy"/>
      <category term="Kubernetes"/>
      <category term="DevOps"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/how_we_added_sleep_when_idle_feature_to_neetoDeploy_and_reduced_cost.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[How we added sleep when idle feature to NeetoDeploy and reduced cost]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps"><![CDATA[<p><em>We are building <a href="https://neeto.com/neetoDeploy">NeetoDeploy</a>, a compelling
Heroku alternative. Stay updated by following NeetoDeploy on
<a href="https://twitter.com/neetodeploy">Twitter</a> and reading our
<a href="https://www.bigbinary.com/blog/categories/neetodeploy">blog</a>.</em></p>
<h2>What is sleep when idle feature</h2>
<p>&quot;Sleep when idle&quot; is a feature of NeetoDeploy, which puts the deployed
application to sleep when there is no hit to the server for 5 minutes. This
helps reduce the cost of the server.</p>
<p>&quot;Sleep when idle&quot; feature can be enabled not only for the pull request review
applications, but for staging and production applications too. Many folks build
applications to learn and for hobby. In such cases, there is no point in running
the server when the server is not likely to get any traffic. Since NeetoDeploy
billing is based on the usage &quot;Sleep when idle&quot; feature helps keep the bill low
for the users.</p>
<p>Let's say you build something and you deployed to production. You shared it with
your friends. For a day or two you got a bit of traffic, and after that you
moved on to other things. If &quot;sleep when idle&quot; is enabled then you don't need to
worry about anything. If the server is not getting any traffic then you will not
be billed.</p>
<h2>How is Neeto using sleep when idle feature</h2>
<p>At <a href="https://neeto.com">neeto</a>, we are building 20+ applications at the same
time. It means lots of pull requests for all these products and thus lots of PR
review apps are created.</p>
<p>For a long time, we were using Heroku to build the review apps. However when
NeetoDeploy started to become stable, we movedto generating PR review apps from
Heroku to NeetoDeploy. This helped reduce cost.</p>
<h2>How to make deployments sleep when idle?</h2>
<p>This video describes how &quot;sleep when idle&quot; feature is implemented.</p>
<p><a href="https://www.youtube.com/watch?v=trn2DJyTjnw"><img src="https://img.youtube.com/vi/trn2DJyTjnw/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=trn2DJyTjnw">Watch on YouTube</a></p>
<p>Keeping the apps running only when they're being used involves two steps:</p>
<ol>
<li>Scaling the deployments down and bringing them back up again</li>
<li>Figuring out when to do the scaling</li>
</ol>
<p>The deployments can be scaled easily using the <code>kubectl scale</code> command. For
example, if we want to turn our deployment off, we can run the following to
update our deployment to zero replicas, essentially destroying all the pods.</p>
<pre><code class="language-bash">kubectl scale deployment/nginx --replicas=0
</code></pre>
<p>We can also delete our service, ingress or any other resource we might have
created for our deployment. The configuration of the deployment itself would
still be present in the cluster even when we make it sleep, since the Kubernetes
Deployment is not deleted.</p>
<p>When we want to bring our app back up again, we can use the same command to spin
up new pods:</p>
<pre><code class="language-bash">kubectl scale deployment/nginx --replicas=1
</code></pre>
<p>The challenge was to figure out <em>when</em> to do this. We decided that we'd have a
threshold based on the time the app is last accessed by users. If the
application is not accessed for more than five minutes, we consider the
application to be idle and we will scale it down. It'll be brought back up when
a user tries to access it again.</p>
<h2>Exploring existing solutions</h2>
<p>There are existing CNCF projects like <a href="https://knative.dev/">Knative</a> and
<a href="https://keda.sh/">Keda</a>, which can potentially be used to achieve what we want
here. We spent some time exploring these but realized that these solutions
weren't exactly suitable for our requirements. Kubernetes also natively has a
<code>HPAScaleToZero</code>
<a href="https://kubernetes.io/docs/reference/command-line-tools-reference/feature-gates">feature gate</a>
which enables the
<a href="https://www.bigbinary.com/blog/solving-scalability-in-neeto-deploy#understanding-kubernetes-autoscalers">Horizontal Pod Autoscaler</a>
to scale down deployments to zero pods, but this is still in alpha and, hence is
not available in EKS yet.</p>
<p>Ultimately, we decided to write our own service for achieving this. The entire
backend of NeetoDeploy was designed as
<a href="https://www.bigbinary.com/blog/neeto-deploy-zero-to-one">a collection of microservices</a>
from day one. So it made sense to build our <em>pod idling service</em> as another
microservice that runs in our cluster.</p>
<h2>Figuring out when to make applications sleep</h2>
<p>To know when applications can be idled, we need to know when people are
accessing the applications from their browsers. Since all the requests to
applications deployed on NeetoDeploy would go through our load balancer, it
would contain the information of when every app was last accessed.</p>
<p>We use <a href="https://traefik.io/traefik/">Traefik</a> as our load balancer and we used
Traefik's <a href="https://doc.traefik.io/traefik/middlewares/overview/">middlewares</a> to
retrieve and process the information of when apps are being accessed. We wrote a
custom middleware to send all the request information to the pod idling service,
whenever an app is being accessed. The pod idling service would store all the
URLs, along with the timestamp at which they were accessed, in a Redis cache.
The following graphic shows how the request information would be collected and
stored by the pod idling service into its Redis cache, both of which are running
within the cluster.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/pod-idling-new-architecture.png" alt="The architecture of the pod idling service"></p>
<p>The pod idling service would then filter the apps that were last accessed more
than five minutes ago. It then sends a request to the cluster to scale all these
apps down. We'd also delete any related resources like the Services and the
IngressRoutes used to configure networking for the deployments.</p>
<p>We first tested this by running the service manually, and sure enough, all the
inactive deployments are filtered and scaled properly. We then added this as a
cron job in the pod idling service, which would run every five minutes. This
means that no app would run for more than five minutes if they're not being
used.</p>
<p>But wait! How would we bring the app back up after scaling it down?</p>
<h2>Building the downtime service</h2>
<p>As we discussed above, we use Traefik's IngressRoutes to route traffic to the
application being accessed. We made use of the
<a href="https://doc.traefik.io/traefik/v2.10/routing/routers/#priority_1">priority parameter</a>
of IngressRoutes to boot up apps that are sleeping. Essentially, we created a
wildcard Traefik IngressRoute that points to a &quot;downtime service&quot; deployment,
which is a React app that serves a message of <code>There's nothing here, yet</code> to let
users know that the app they're trying to access doesn't exist. You can see this
in action if you visit a random URL in NeetoDeploy, say something like
<a href="https://nonexistent-appname.neetodeployapp.com">nonexistent-appname.neetodeployapp.com</a></p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/downtime-service-page.png" alt="The downtime service page"></p>
<p>Wildcard IngressRoutes have the least priority by default. So if we create a
&quot;catch-all&quot; wildcard IngressRoute, any invalid url without an IngressRoute of
its own, can be redirected to a single Service in Kubernetes. This is how we're
redirecting non-existent apps to the page shown above. In the following graphic,
we can see how a request to a random URL is routed to the downtime service with
the wildcard IngressRoute.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/downtime-service-architecture.png" alt="Architecture of how the downtime service works in NeetoDeploy"></p>
<p>This also means that if an app is scaled down by the pod idling service and gets
its IngressRoute deleted, the next time a user tries to access the app, the
request would instead be routed to the downtime service. We need to handle the
scale up logic from the downtime service.</p>
<p>Whenever a user requests a URL that doesn't have an IngressRoute, there are two
possibilities.</p>
<ol>
<li>The app doesn't exist.</li>
<li>The app exists, but is currently scaled down.</li>
</ol>
<p>The downtime service would first check the cluster if the requested app is
present in the cluster in a sleeping state. If not then the user will be served
the &quot;There's nothing here, yet&quot; page. If there is a sleeping deployment,
however, we boot it back up. The downtime service sends the scale up request to
the cluster. We keep redirecting the user back to the url till the app is up and
running. This redirection would keep happening until the app is scaled up since
we create the Service and IngressRoute only after the pods of the app are
running. At this point, the request will be routed to the correct pod by the
app's IngressRoute, since it has a higher priority than the wildcard
IngressRoute of the downtime service. All of these steps are illustrated in the
GIF below:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/cost-reduction-in-neeto-deploy-by-turning-off-inactive-apps/downtime-service.gif" alt="Illustration of how the downtime service works"></p>
<p>This design worked flawlessly and we were able to bring back scaled down
applications with as low as 20-30 seconds of wait time.</p>
<h2>Conclusion</h2>
<p>We've been running this setup for almost a year now, and it has been working
smoothly so far. Pod idling service and the downtime service started as simpler
microservices and continue to evolve, adapting to the increasing demand as we
grow.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
invite@neeto.com.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">X</a>. You can also join our
<a href="https://launchpass.com/neetohq">community Slack</a> to chat with us about any
Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Building the NeetoDeploy metrics dashboard with Prometheus]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/using-prometheus-in-neeto-deploy"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/building_metrics_dashboard_in_neetoDeploy.jpg"/>
      <id>https://www.bigbinary.com/blog/using-prometheus-in-neeto-deploy</id>
      <published>2024-01-09T00:00:00.000Z</published>
      <updated>2024-01-09T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="NeetoDeploy"/>
      <category term="Kubernetes"/>
      <category term="DevOps"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/building_metrics_dashboard_in_neetoDeploy.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Building the metrics dashboard in NeetoDeploy with Prometheus]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/using-prometheus-in-neeto-deploy"><![CDATA[<p><em>We are building <a href="https://neeto.com/neetoDeploy">NeetoDeploy</a>, a compelling
alternative to Heroku. Stay updated by following NeetoDeploy on
<a href="https://twitter.com/neetodeploy">Twitter</a> and reading our
<a href="https://www.bigbinary.com/blog/categories/neetodeploy">blog</a>.</em></p>
<p>One of the features that we wanted in our cloud deployment platform,
<strong>NeetoDeploy</strong> was an application metrics. We decided to use
<a href="https://prometheus.io/">Prometheus</a> for building this feature. Prometheus is an
open source monitoring and alerting toolkit and is a CNCF graduated project.
Venturing into the Cloud Native ecosystem of projects apart from Kubernetes was
something we had never done before. We ended up learning a lot about Prometheus
and how to use it during the course of building this feature.</p>
<h2>Initial setup</h2>
<p>We installed Prometheus in our Kubernetes cluster by writing a deployment
configuration YAML and applying it to our cluster. We also provisioned an AWS
Elastic Block Store volume using a PersistentVolumeClaim to store the metrics
data collected by Prometheus. Prometheus needed a
<a href="https://github.com/prometheus/prometheus/blob/main/documentation/examples/prometheus-kubernetes.yml">configuration file</a>
where we defined what all targets it will be scraping metrics from. This is a
YAML file which we stored in a ConfigMap in our cluster.</p>
<p>Targets in Prometheus can be anything that exposes metrics data in the
Prometheus format at a <code>/metrics</code> endpoint. This can be your application
servers, Kubernetes API servers or even Prometheus itself. Prometheus would
scrape the data at the defined <code>scrape_interval</code> and store it in the volume as
time series data. This can be queried and visualized in the Prometheus dashboard
that comes bundled in the Prometheus deployment.</p>
<p>We used <code>kubectl port-forward</code> command to test that Prometheus is working
locally. Once everything was tested and we confirmed, we exposed Prometheus with
an ingress so that we can hit its APIs with that url.</p>
<p>Initially we had configured the following targets:</p>
<ol>
<li><a href="https://github.com/prometheus/node_exporter">node_exporter</a> from Prometheus,
which would scrape the metrics of the machine the deployment is running on.</li>
<li><a href="https://github.com/kubernetes/kube-state-metrics">kube-state-metrics</a> which
would listen to the Kubernetes API and store metrics of all the objects.</li>
<li><a href="https://traefik.io/traefik/">Traefik</a> for all the network-related metrics
(like the number of requests etc.) since we are using Traefik as our ingress
controller.</li>
<li>kubernetes-nodes</li>
<li>kubernetes-pods</li>
<li>kubernetes-cadvisor</li>
<li>kubernetes-service-endpoints</li>
</ol>
<p>The last 4 scrape jobs would be collecting metrics from the Kubernetes REST API
related to nodes, pods, containers and services respectively.</p>
<p>For scraping metrics from all of these targets, we had set a resource request of
500 MB of RAM and 0.5 vCPU to our Prometheus deployment.</p>
<p>After setting up all of this, the Prometheus deployment was running fine, and we
were able to see the data from the Prometheus dashboard. Seeing this, we were
satisfied and happily started hacking with PromQL, Prometheus's query language.</p>
<h2>The CrashLoopBackOff crime scene</h2>
<p><code>CrashLoopBackOff</code> is when a Kubernetes pod is going into a loop of crashing,
restarting itself and then crashing again - and this was what was happening to
the Prometheus deployment we had created. From what we could see, the pod had
crashed, and when it gets recreated, Prometheus would initialize itself and do a
reload of the
<a href="https://prometheus.io/docs/prometheus/latest/storage/">Write Ahead Log (WAL)</a>.</p>
<p>The WAL is there for adding additional durability to the database. Prometheus
stores the metrics it scrapes in-memory before persisting them to the database
as chunks, and the WAL makes sure that the in-memory data will not be lost in
the case of a crash. In our case, the Prometheus deployment was crashing and it
would get recreated. It would try to load the data from WAL into memory, and
then crash again before this was completed, leading to the CrashLoopBackOff
state.</p>
<p>We tried deleting the WAL blocks manually from the volume, even though this
would incur some data loss. This was able to bring the deployment back up again
since WAL replay needn't be done. The deployment went into CrashLoopBackOff
again after a while.</p>
<h2>Investigating the error</h2>
<p>The first line of approach we took was to monitor the CPU, memory, and disk
usage of the deployment. The disk usage seemed to be normal. We had provisioned
a 100GB volume and it wasn't anywhere near getting used up. The CPU usage also
seemed normal. The memory usage, however, was suspicious.</p>
<p>After the pods had crashed initially, we recreated the deployment and monitored
it using kubectl's <code>--watch</code> flag for following all the pod updates. While doing
this we were able to see that the pods were going into CrashLoopBackOff because
they were getting OOMKilled first. The <code>OOMKilled</code> error in Kubernetes is when a
pod is terminated because it tries to use more memory than it is allotted in its
resource limits. We were consistently seeing the <code>OOMKilled</code> error so memory
must be the culprit here.</p>
<p>We added Prometheus itself as a target in Prometheus so that we could monitor
the memory usage of the Prometheus deployment. The following was the general
trend of how Prometheus's memory was increasing over time. This would go on
until the memory would cross the specified limit, and then the pod would go into
CrashLoopBackOff.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/memory_usage.png" alt="Memory usage of the Prometheus deployment"></p>
<p>Now that we knew that memory was the issue, we started looking into what was
causing the memory leak. After talking with some folks from the Kubernetes Slack
workspace, we were asked to look at the TSDB status of the Prometheus
deployment. We monitored the stats in real time and saw that the number of time
series data stored in the database was growing in tens of thousands by each
second! This lined up with the increase in the memory usage graph from earlier.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/tsdb.png" alt="Prometheus TSDB stats"></p>
<h2>How we fixed it</h2>
<p>We can calculate the memory requirement for Prometheus based on the number of
targets we are scraping metrics from and the frequency at which we are scraping
the data. The memory requirement of the deployment is a function of both of
these parameters. In our case ,this was definitely higher than what we could
afford to allocate (based on the nodegroup's machine type) since we were
scraping a lot of data at a scrape interval of 15 seconds, which was set in the
default configuration for Prometheus.</p>
<p>We increased the scrape interval to 60 seconds and removed all the targets from
the Prometheus configuration whose metrics we didn't need for building the
dashboard. Within the targets that we were scraping from, we used the
<code>metric_relabel_configs</code> option to persist in the database only those metrics
which we needed and to drop everything else. We only needed the
<code>container_cpu_usage_seconds_total</code>, <code>container_memory_usage_bytes</code> and the
<code>traefik_service_requests_total</code> metrics - so we configured Prometheus so that
only these three would be stored in our database, and by extension the WAL.</p>
<p>We redeployed Prometheus after making these changes and the memory showed great
stability afterwards. The following is the memory usage of Prometheus over the
last few days. It has not exceeded 1GB.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/memory_usage_after_fix.png" alt="Memory usage of the Prometheus deployment after the fix"></p>
<h2>The aftermath</h2>
<p>Once Prometheus was stable we were able to build the metrics dashboard with the
Prometheus API in a straightforward manner. The metrics dashboard came to use
within a couple of days, when the staging deployment of
<a href="https://neetocode.com/">NeetoCode</a> had faced a downtime. You can see the
changes in the metrics from the time when the outage had occurred</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2024/using-prometheus-in-neeto-deploy/neetocode_metrics.png" alt="NeetoCode metrics showing the downtime"></p>
<p>The quintessential learning that we got from this experience is to always be
wary of the resources that are being used up when it comes to tasks like
scraping metrics over an extended period of time. We were scraping all the
metrics initially in order to explore everything, even though all the metrics
were not being used. But because of this, we were able to read a lot about how
Prometheus works internally, and also learn some Prometheus best practices the
hard way.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">Twitter</a>. You can also join our
<a href="https://neetohq.slack.com/">community Slack</a> to chat with us about any Neeto
product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Building NeetoDeploy CLI]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/building-neeto-deploy-cli"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/building_neetoDeploy_CLI.jpg"/>
      <id>https://www.bigbinary.com/blog/building-neeto-deploy-cli</id>
      <published>2023-12-26T00:00:00.000Z</published>
      <updated>2023-12-26T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="NeetoDeploy"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/building_neetoDeploy_CLI.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[How we built the CLI for NeetoDeploy]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/building-neeto-deploy-cli"><![CDATA[<p><em>We are building <a href="https://neeto.com/neetoDeploy">NeetoDeploy</a>, a compelling
Heroku alternative. Stay updated by following NeetoDeploy on
<a href="https://twitter.com/neetodeploy">Twitter</a> and reading our
<a href="https://www.bigbinary.com/blog/categories/neetodeploy">blog</a>.</em></p>
<p>Building the CLI tool for <a href="https://neetodeploy.com">NeetoDeploy</a> became our top
priority after we had built all the basic features in NeetoDeploy. Once we
started migrating our apps from Heroku to NeetoDeploy, the need for a CLI tool
arose, since previously developers were using Heroku CLI for their scripts etc.</p>
<p>We started building the CLI as a Ruby gem using <a href="http://whatisthor.com/">Thor</a>.
Installing the gem and using it would be as simple as running
<code>gem install neetodeploy</code>. We wanted the users to be authenticated via Neeto's
authentication system before they could do anything else with the CLI. For this,
we added a <code>neetodeploy login</code> command, which would create a session and
redirect you to the browser where you can log in. The CLI would be polling the
session login status, and once you have logged in, it would store the session
token and your email address inside the <code>~/.config/neetodeploy</code> directory. This
will be used to authenticate your request when you run everything else.</p>
<h3>The basic CLI functionality</h3>
<p>The v1 release of the NeetoDeploy CLI shipped the following commands:</p>
<ul>
<li><code>config</code> : For listing, creating, and deleting environment variables for your
apps.</li>
<li><code>exec</code> : For getting access to a shell running inside your deployed app.</li>
<li><code>logs</code> : For streaming the application logs right to your terminal.</li>
</ul>
<p>Let's look at each of them in detail.</p>
<h3>Setting environment vars</h3>
<p>Building the <code>config</code> command was the most straightforward of the three. The
central source or truth for all the environment variables of the apps is stored
in the web dashboard of NeetoDeploy. There are APIs already in place for doing
CRUD operations on these from the dashboard app. This could be expanded for the
use of the CLI as well.</p>
<p>We first added API endpoints in the dashboard app, under a CLI namespace, to
list, create, and delete config variables. We then added different commands in
the CLI to send HTTP requests to the respective endpoints in the dashboard app.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/building-neeto-deploy-cli/cli-demo.gif" alt="The NeetoDeploy config command in action"></p>
<p>You can pass the app name as an argument, and the CLI will send a request to the
dashboard app along with the session token generated when you logged in. At the
backend, this session token would be used to check if you have access to the app
you're requesting, before doing anything else.</p>
<p>If you have used Heroku CLI, then you would be very comfortable since
NeetoDeploy CLI follows the same style.</p>
<h3>Architecting the <code>neetodeploy exec</code> command</h3>
<p>The <code>exec</code> command is used to get access to a shell inside your deployed app.
The NeetoDeploy web dashboard already has a functioning console feature with
which you can get access to the shell inside your application’s dynos. This was
built using websockets. We would deploy a &quot;console&quot; pod with the same image and
environment variables as the app, to which we'll connect with websockets. We
have a dyno-console-manager app which spawns a new process inside the console
dyno and handles the websocket connections, etc. When we started building the
exec feature for the CLI however, we explored a few options and learnt a lot of
things before finally settling back on the websockets approach.</p>
<p>We’ve been using the <code>kubectl exec</code> command on a daily basis to get access to
shells inside pods running in the cluster. Since <code>kubectl exec</code> is cosmetically
similar to how we use SSH to access remote machines, the first approach we took
involved using SSH to expose containers outside the cluster.</p>
<p>We can expose our deployment outside the cluster using SSH in two ways. The
first approach would be running an SSH server as a
<a href="https://www.google.com/search?q=kubernetes+sidecar+container+pattern">sidecar container</a>
within the console pod. The second approach would be to bundle
<a href="https://man7.org/linux/man-pages/man8/sshd.8.html">sshd</a> within the image for
the console pod using a custom buildpack. With either of these two methods, you
would be able to SSH into your console deployment if you have the correct SSH
keys. We ran <code>sshd</code> inside a pod using a
<a href="https://github.com/jkutner/sshd-buildpack">custom sshd buildpack</a>. We then
configured the SSH public key inside the pod manually with <code>kubectl exec</code>. With
this, we were able to SSH into the pod after port forwarding the sshd process’s
port to localhost using <code>kubectl port-forward</code>.</p>
<p>Great! Now that the SSH connection works, the part of the puzzle that remained
now was how we would actually expose the deployment outside the cluster in
production. We tried doing this in a couple of different ways.</p>
<h4>1. LoadBalancer</h4>
<p>We were able to SSH into the pod after exposing it as a
<a href="https://kubernetes.io/docs/tasks/access-application-cluster/create-external-load-balancer">LoadBalancer</a>
service. This was out of the question for production however, since AWS has a
hard limit on the number of application load balancers (ALB) we can create per
region. We’d also have to pay for each load balancer we create. This approach
wouldn’t scale at all.</p>
<h4>2. NodePort</h4>
<p>The next option was to expose the pod as a <code>NodePort</code> service. A NodePort
service in Kubernetes means that the pod would be exposed through a certain port
number through <em>every node</em> in the cluster. We could SSH into the pod with the
external IP of any of the nodes. We tried exposing the test console pod we
created with a NodePort service as well. We were able to SSH into the pod from
outside the cluster without having to do the port forward. There was one
limitation for using NodePorts that we knew would render this method suboptimal
for building a Platform as a Service. The range of ports that can be allocated
for NodePort services is from 30000 to 32768 by default. This means that we’d
only be able to run 2768 instances of <code>neetodeploy exec</code> at any given time in
our current cluster setup in EKS.</p>
<h4>3. Bastion host, the SSH proxy server</h4>
<p>We thought of deploying an SSH proxy server to circumvent the hard limits on the
LoadBalancer and NodePort approaches. Such proxy servers are usually called
bastion hosts or jump servers. These are servers that are designed to provide
access to a private network from a public network. The name &quot;bastion&quot; comes from
the military structure that projects outwards from a castle or a fort. In a
similar sense, our bastion host will be a Kubernetes deployment that is exposed
to the public network and acts as an interface between our private cluster and
the public internet. For our requirement, we can proxy SSH connections to
console pods through this bastion host deployment. We only needed to expose the
bastion host as a single LoadBalancer or a NodePort service, to which the CLI
can connect. This would solve the issue of having a hard limit on the number of
LoadBalancer or NodePort services we can create.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/building-neeto-deploy-cli/bastion-host.png" alt="The bastion host architecture for exposing deployments"></p>
<p>We quickly set up a bastion host and tested the whole idea. It was working
seamlessly! However, there were a lot of edge cases we'd have to handle if we
are going to release this to the public. Ideally, we would want a new pair of
SSH keys for each console pod. We could generate this and store it as secrets in
the cluster. Apart from the hassle of handling all the SSH keys and updating the
bastion host each time, we would have to make sure that users will not be able
to get SSH access to the bastion host deployment manually, outside the CLI. This
was difficult since the CLI would need access to the private key in order to
connect to the bastion host anyway. This would mean that users could SSH into
the bastion host after digging through the CLI gem's source, and possibly even
exec into any deployment in the cluster if they knew what they were looking for.
Users with malicious intent could possibly bring down the bastion host itself
once they're inside, rendering the exec command unusable.</p>
<p>We thought about installing kubectl inside the bastion host with a restrictive
<a href="https://kubernetes.io/docs/reference/access-authn-authz/rbac/">RBAC</a> so that we
can run <code>kubectl exec</code> from inside the bastion host, also while making sure that
users could not run anything destructive from inside the bastion host. But this
just adds more moving parts to the system. The SSH proxy approach makes sense if
you have to expose your cluster among developers for internal use, but it is not
ideal when you are building a CLI for public use.</p>
<p>After figuring out <em>how not to solve the problem</em>, we came to the conclusion
that using websockets was the better approach for now. We already have the
dyno-console-manager app, which we are using for the shell access from the web
dashboard, we updated the same to handle connections from the CLI. From the
CLI's end, we wrote a simple WebSocket client and handled the parsing of user
inputs and printing the responses from the shell. All of the commands you enter
would be run on the console pod through the websocket connection.</p>
<h3>Streaming logs to the terminal</h3>
<p>Live logs were streamed to the web dashboard using websockets too. This was also
handled by the above-mentioned dyno-console-manager. Since we had written a Ruby
websocket client for the <code>exec</code> command, we decided to use the same approach
with logs too.</p>
<p>The CLI would send a request to the dyno-console-manager with the app’s name and
the dyno-console-manager would run <code>kubectl logs</code> for your app's deployment and
stream it back to the CLI via a websocket connection it creates.</p>
<p>We took our time with architecting the NeetoDeploy CLI, but thanks to that we
learnt a lot about designing robust systems that would scale in the long term.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">X</a>. You can also join our
<a href="https://launchpass.com/neetohq">community Slack</a> to chat with us about any
Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Optimizing NeetoDeploy's Cluster Autoscaler]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/optimizing-neeto-deploy-autoscaler"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/optimizing_neetoDeploy_cluster_autoscaler.jpg"/>
      <id>https://www.bigbinary.com/blog/optimizing-neeto-deploy-autoscaler</id>
      <published>2023-10-10T00:00:00.000Z</published>
      <updated>2023-10-10T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="NeetoDeploy"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/optimizing_neetoDeploy_cluster_autoscaler.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Optimizing NeetoDeploy's Cluster Autoscaler using overprovisioning deployments.]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/optimizing-neeto-deploy-autoscaler"><![CDATA[<p>Once we
<a href="https://bigbinary.com/blog/solving-scalability-in-neeto-deploy">configured the Cluster Autoscaler</a>
to scale NeetoDeploy according to the load, the next challenge was how to do
this efficiently. The primary issue we had to solve was to reduce the time we
had to wait for the nodes to scale up.</p>
<h2>Challenges faced</h2>
<p>The Cluster Autoscaler works by monitoring the pods and checking if they are
waiting to get scheduled. If no nodes are available to schedule the waiting
pods, they will be in <code>Pending</code> state, until the <code>kube-scheduler</code> finds a
suitable node.</p>
<p>With our default Cluster Autoscaler setup, if a pod is provisioned when the
cluster is at maximum capacity, the pod will go into <code>Pending</code> state and remain
there until the cluster has scaled up. This entire flow consists of the
following steps:</p>
<ul>
<li>The Cluster Autoscaler scans the pods and identifies the un-schedulable pods.</li>
<li>The Cluster Autoscaler provisions a new node. We have configured the
autoscaler deployment with the necessary permissions for the autoscaling
groups in EC2, with which the autoscaler can provision new EC2 machines.</li>
<li>Kubernetes adds the newly provisioned node to the cluster’s control plane, and
the cluster is “scaled up.”</li>
<li>The pending pod gets scheduled to the newly added node.</li>
</ul>
<p>From the perspective of a user who wants to get their application deployed, a
considerable amount of time is taken to complete all these steps in addition to
the time taken to build and release their code. We can only optimize it so much
by decreasing the scan interval of the Cluster Autoscaler. We need a mechanism
by which we can always have some buffer nodes ready so that the users’
deployments never go into <code>Pending</code> state and wait for the nodes to be
provisioned.</p>
<h2>Pod Priority, Preemption and Overprovisioning</h2>
<p>Kubernetes allows us to assign different priorities to pods. By default, all the
pods have a priority of <code>0</code>. When a pod is scheduled, it can preempt or evict
other pods with lower priority than itself and take its place. We will use this
feature of pod preemption to reserve resources for incoming deployments.</p>
<p>We created a new pod priority class with a priority of <code>-1</code> and used this to
“overprovision”
<a href="https://www.ianlewis.org/en/almighty-pause-container">pause pods</a>. We allocated
a fixed amount of CPU and memory resources to these pause pods. The pause
container is a placeholder container used by Kubernetes internally and doesn’t
do anything by itself.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/optimizing-neeto-deploy-autoscaler/overprovisioned-cluster.png" alt="Illustration of overprovisioning a Kubernetes cluster"></p>
<p>Now if the cluster is at full capacity and a new deployment is created,
technically the newly created pod doesn't have space to be scheduled in the
cluster. In normal cases, this would warrant a scale-up to be triggered by the
Cluster Autoscaler and the pod would be <code>Pending</code> until the new node is
provisioned and attached to the cluster.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/optimizing-neeto-deploy-autoscaler/overprovisioner-stage-1.png" alt="Illustration of a new pod getting created in an overprovisioned cluster"></p>
<p>We can save a lot of time from this process since we have the overprovisioned
pods with a lower pod priority. The newly created deployment would have a pod
priority of <code>0</code> by default, and our placeholder pause pods with a priority of
<code>-1</code> would be evicted in favor of this application pod. This means that new pods
can be scheduled without having to wait for the Cluster Autoscaler to do its
magic. Some space would always be reserved in our cluster.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/optimizing-neeto-deploy-autoscaler/overprovisioner-stage-2.png" alt="Illustration of a pod evicting an overprovisioning pod with lesser priority"></p>
<p>The pause pods would now move to <code>Pending</code> state after being evicted, which the
Cluster Autoscaler will pick up, and it will start provisioning a new node. This
way, the autoscaler doesn’t have to wait for a user to create a new deployment
to scale up the cluster. Instead, it would do it in advance to reserve some
space for potential deployments.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/optimizing-neeto-deploy-autoscaler/overprovisioner-stage-3.png" alt="Illustration of how an evicted overprovisioning pod triggering cluster scale up"></p>
<h2>Trade-offs</h2>
<p>Now that we have the overprovisioning deployments configured to reserve some
space in NeetoDeploy's cluster, we had to decide how much space to reserve. If
we increase the CPU and memory limit for the overprovisioning pods or their
number of replicas, we will have more space reserved in our cluster. This means
that we can handle more user deployments concurrently, but we will incur the
cost of keeping the extra buffer running. The trade-off here is between the cost
we are willing to pay and the load we want to handle.</p>
<p>For running NeetoDeploy, we started with three copies of overprovisioning pods
with 500 milli vCPUs, and later scaled it to 10 replicas after we moved the
review apps of all the <a href="https://neeto.com">Neeto products</a> to NeetoDeploy. We
have been running all our internal staging deployments and review apps for the
past eleven months, and this configuration has been working pretty well for us
so far.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">Twitter</a>. You can also join our
<a href="https://launchpass.com/neetohq">community Slack</a> to chat with us about any
Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Scaling NeetoDeploy with the Cluster Autoscaler]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/solving-scalability-in-neeto-deploy"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/solving_scaling_challenges_in_neetoDeploy.jpg"/>
      <id>https://www.bigbinary.com/blog/solving-scalability-in-neeto-deploy</id>
      <published>2023-08-29T00:00:00.000Z</published>
      <updated>2023-08-29T00:00:00.000Z</updated>
      <author>
        <name>Sreeram Venkitesh</name>
        <uri>https://www.bigbinary.com/blog/authors/sreeram-venkitesh</uri>
      </author>
      <category term="NeetoDeploy"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/solving_scaling_challenges_in_neetoDeploy.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[At NeetoDeploy we solved the scaling problem using Cluster Autoscaler]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/solving-scalability-in-neeto-deploy"><![CDATA[<p>We are building <a href="https://www.neeto.com/neetodeploy">NeetoDeploy</a>. It's a Heroku
alternative. Check out our previous blog to see
<a href="https://www.bigbinary.com/blog/neeto-deploy-zero-to-one">how we started</a>
building NeetoDeploy.</p>
<p>We started using NeetoDeploy internally for all our staging applications and the
&quot;pull request review&quot; applications. Very soon, we ran into scaling challenges.
Some days, we have too many pull requests, and some days, very few pull
requests. Some days, the staging sites have an extra load.</p>
<p>Scaling is a fundamental problem in container orchestration. We need to ensure
that we have enough computing resources to handle the load, and at the same
time, we need to make sure we are not spending money on resources that are not
being utilized. If we need to run 10 applications, we should only have to pay
for as much computing as is required for running 10 applications. But if this
number increases to 100 one day, our system should be able to provision new
computing resources.</p>
<h2>Understanding Kubernetes Autoscalers</h2>
<p>When we need to scale, we can manually allocate resources. This is
time-consuming and repetitive. Kubernetes excels in autoscaling. It provides
many different options to meet our scaling needs.</p>
<p>We can define autoscalers of different types to make our cluster and our
deployments scale up or down based on various parameters and handle traffic
gracefully. Kubernetes has three kinds of autoscalers operating at different
levels.</p>
<h3>Horizontal Pod Autoscaler (HPA)</h3>
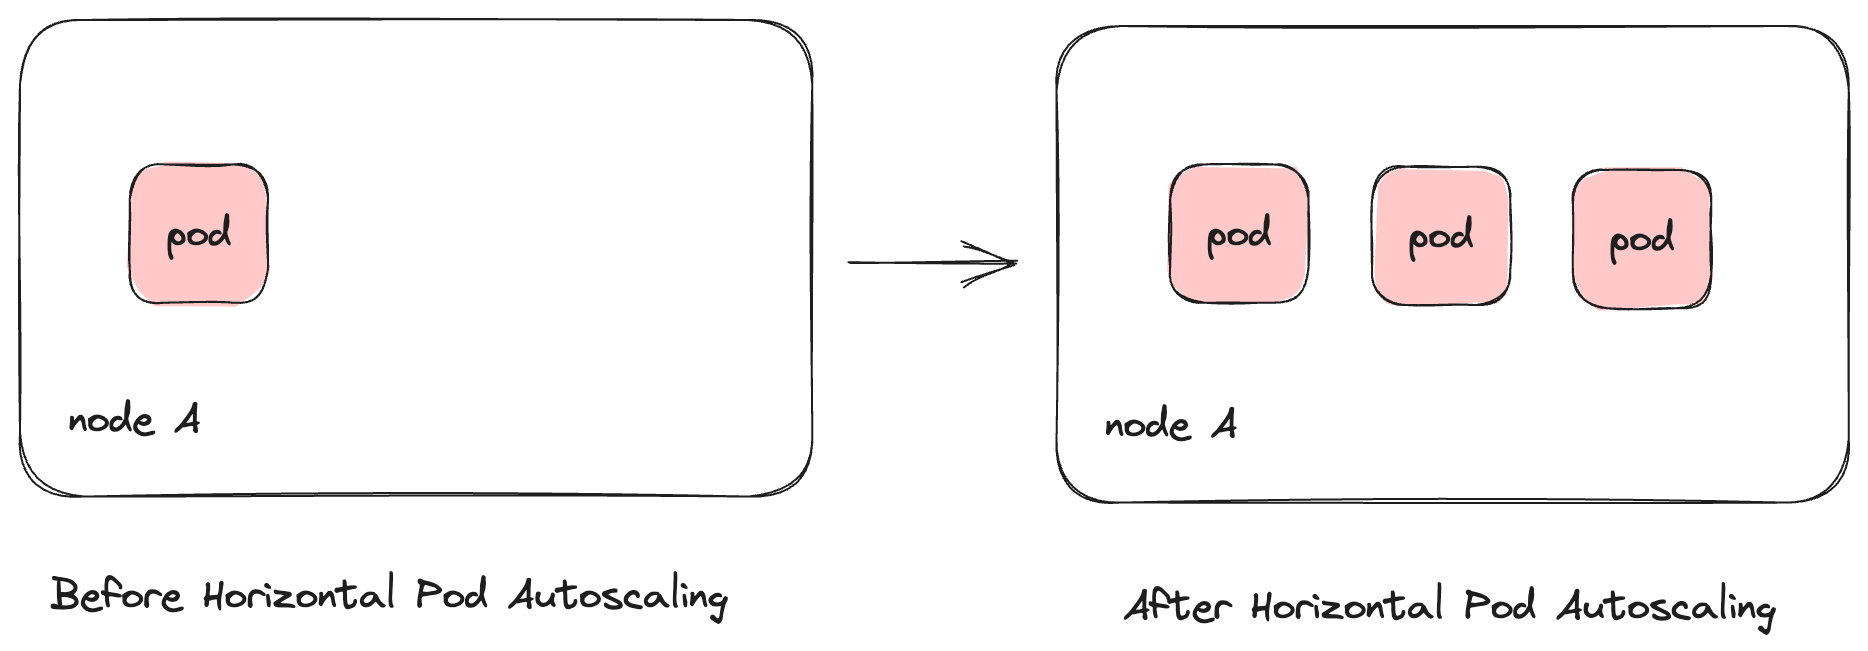
<p>The Horizontal Pod Autoscaler can scale up our Kubernetes deployments by
increasing the number of copies of our app's container, known as
<a href="https://kubernetes.io/docs/concepts/workloads/controllers/replicaset/">replicas</a>.
We can configure our Horizontal Pod Autoscaler to scale up our apps based on
metrics like increased memory usage, network load, or even the time of the day
when we expect more traffic. Incoming traffic would be redirected to any of the
replicas and Kubernetes takes care of this.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/hpa.png" alt="Illustration of how horizontal pod autoscaling works"></p>
<h3>Vertical Pod Autoscaler (VPA)</h3>
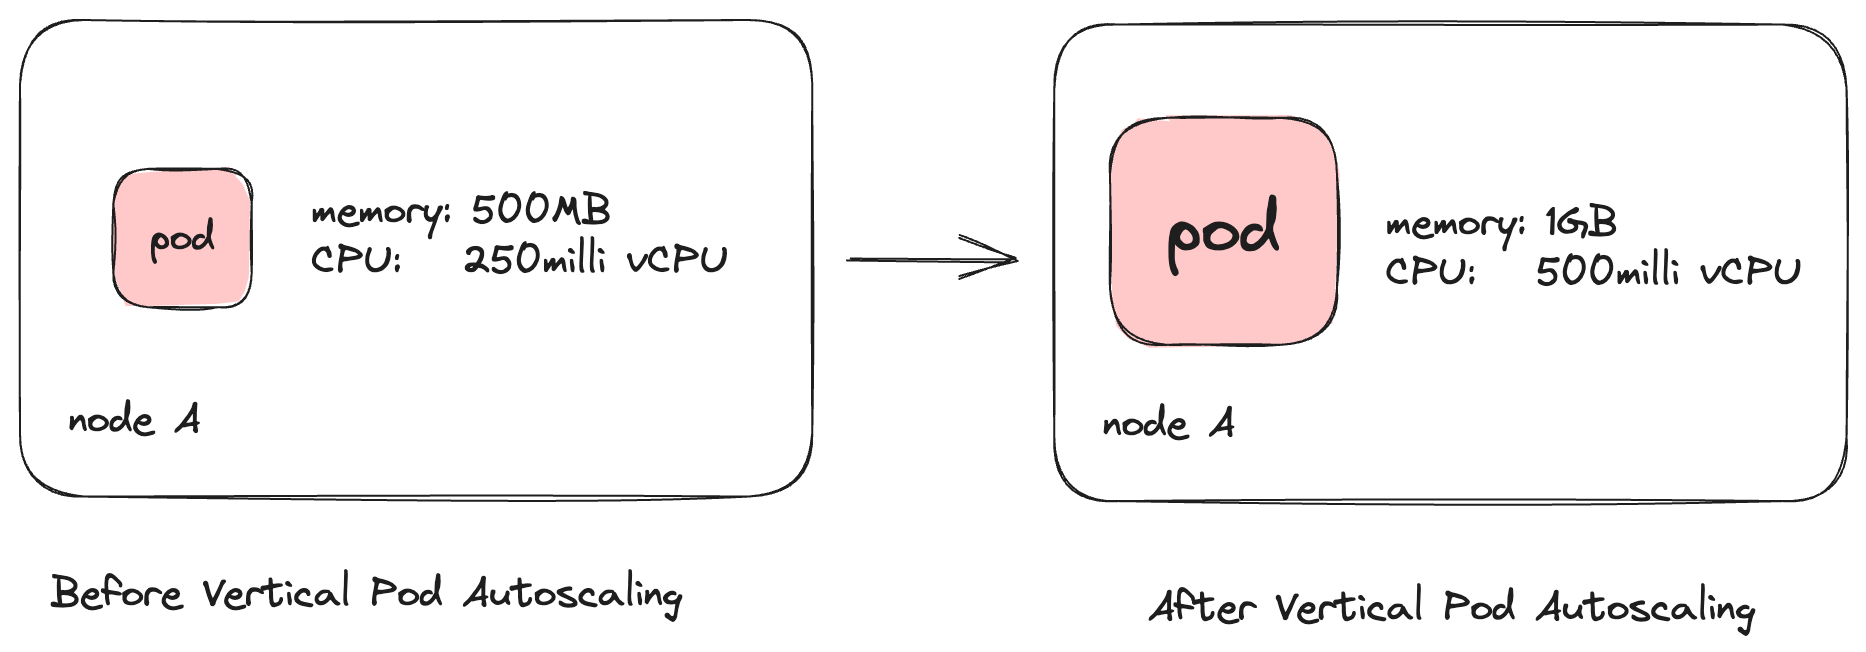
<p>The Vertical Pod Autoscaler takes a different approach to the same problem
solved by the Horizontal Pod Autoscaler. The Vertical Pod Autoscaler increases
the CPU and memory resources allocated to our pod based on the load. The number
of containers running would remain the same, but they would have more resources
to work with and, hence, would be able to handle increased loads.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/vpa.png" alt="Illustration of how vertical pod autoscaling works"></p>
<h3>Cluster Autoscaler</h3>
<p>While horizontal and vertical pod autoscaling operate on the level of individual
deployments, the Cluster Autoscaler scales in the context of the entire cluster.
It increases or decreases the number of nodes in the cluster, making space for
more deployments.</p>
<h2>The need for Cluster Autoscaler</h2>
<p>Suppose our Kubernetes cluster has three nodes. When we create deployments, our
applications will be deployed to any of these three nodes based on the resource
availability in the nodes. Without the Cluster Autoscaler, the number of
machines running in our cluster will be fixed at 3.</p>
<p>If there is a sudden surge in traffic and we have to deploy 100 apps instead of
10, the resources needed would overflow the three nodes' combined CPU and memory
resources. Essentially, our cluster will not have enough resources to
accommodate all the deployments, and the pods for our deployments will be stuck
in the <code>Pending</code> state.</p>
<h2>How Cluster Autoscaler works</h2>
<p>The Cluster Autoscaler increases and decreases the number of nodes in our
cluster based on the number of deployments created. So in the above example, if
we had the Cluster Autoscaler running, it would check if any pods are stuck in a
<code>Pending</code> state, and if so, it'll spawn a new node in the cluster. If three
nodes are not enough to accommodate all our deployments, the Cluster Autoscaler
would detect this and scale the cluster to four nodes.</p>
<p><strong>Let us see step by step how cluster autoscaler would work:</strong></p>
<ol>
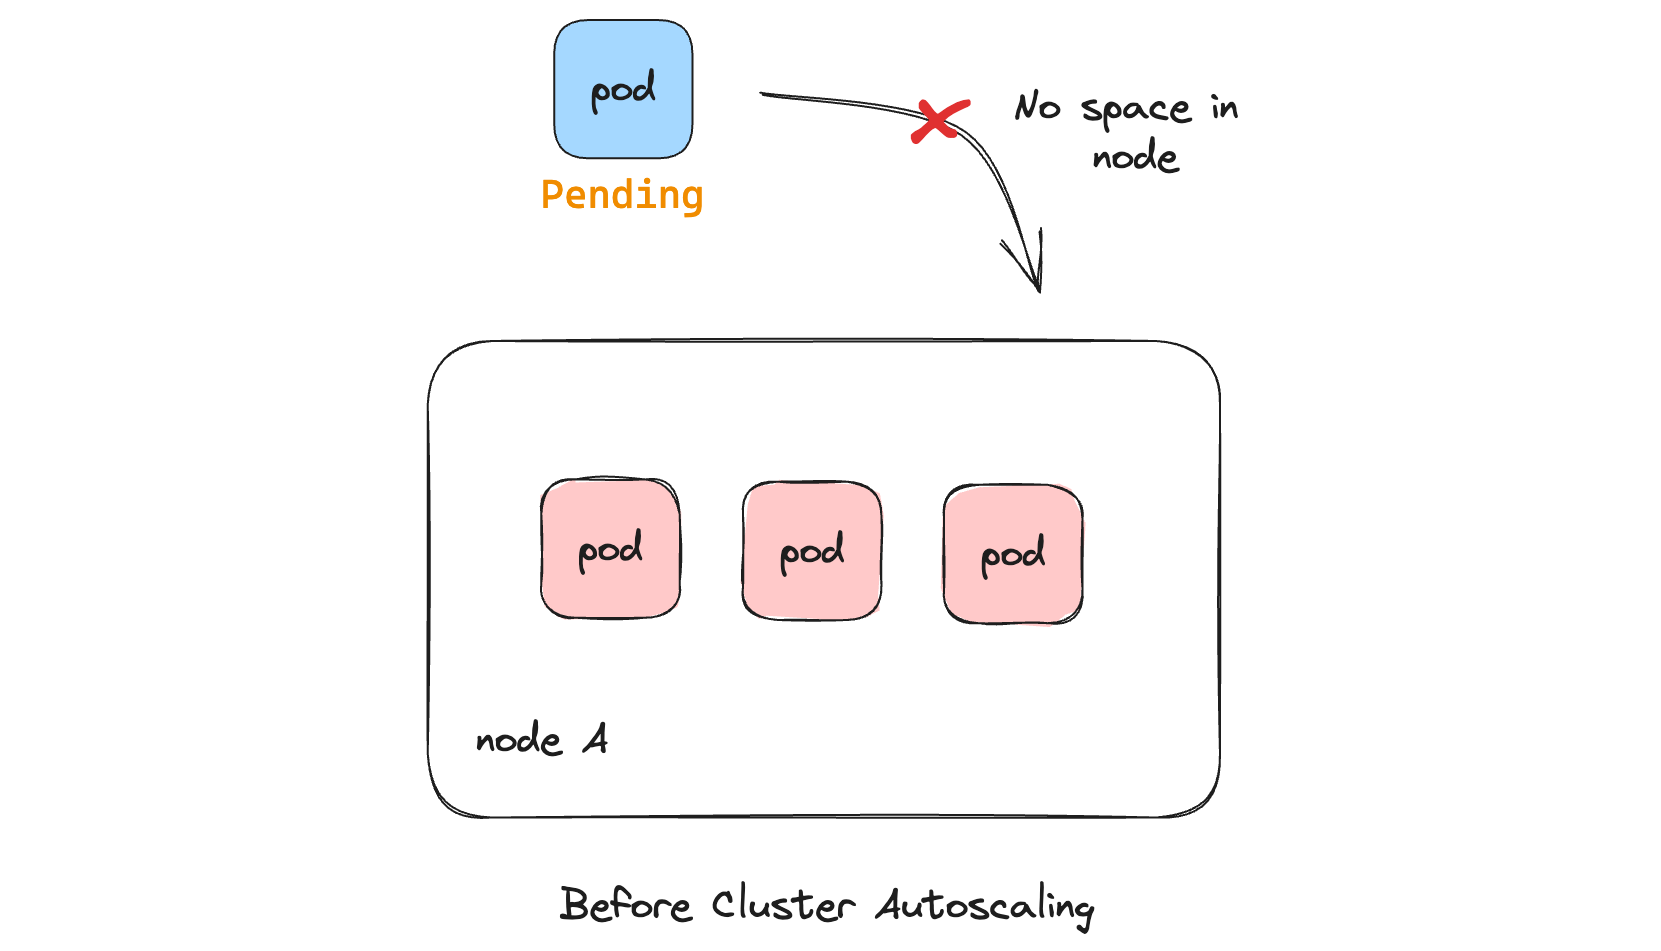
<li>If our Kubernetes cluster is running at full capacity, the pods of a newly
created deployment would have no space to fit in the cluster. In this case,
the pod would be stuck in the <code>Pending</code> state and wouldn't be &quot;scheduled&quot; to
any node.</li>
</ol>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/cluster-autoscaler-1.png" alt="Illustration of pod stuck in pending state"></p>
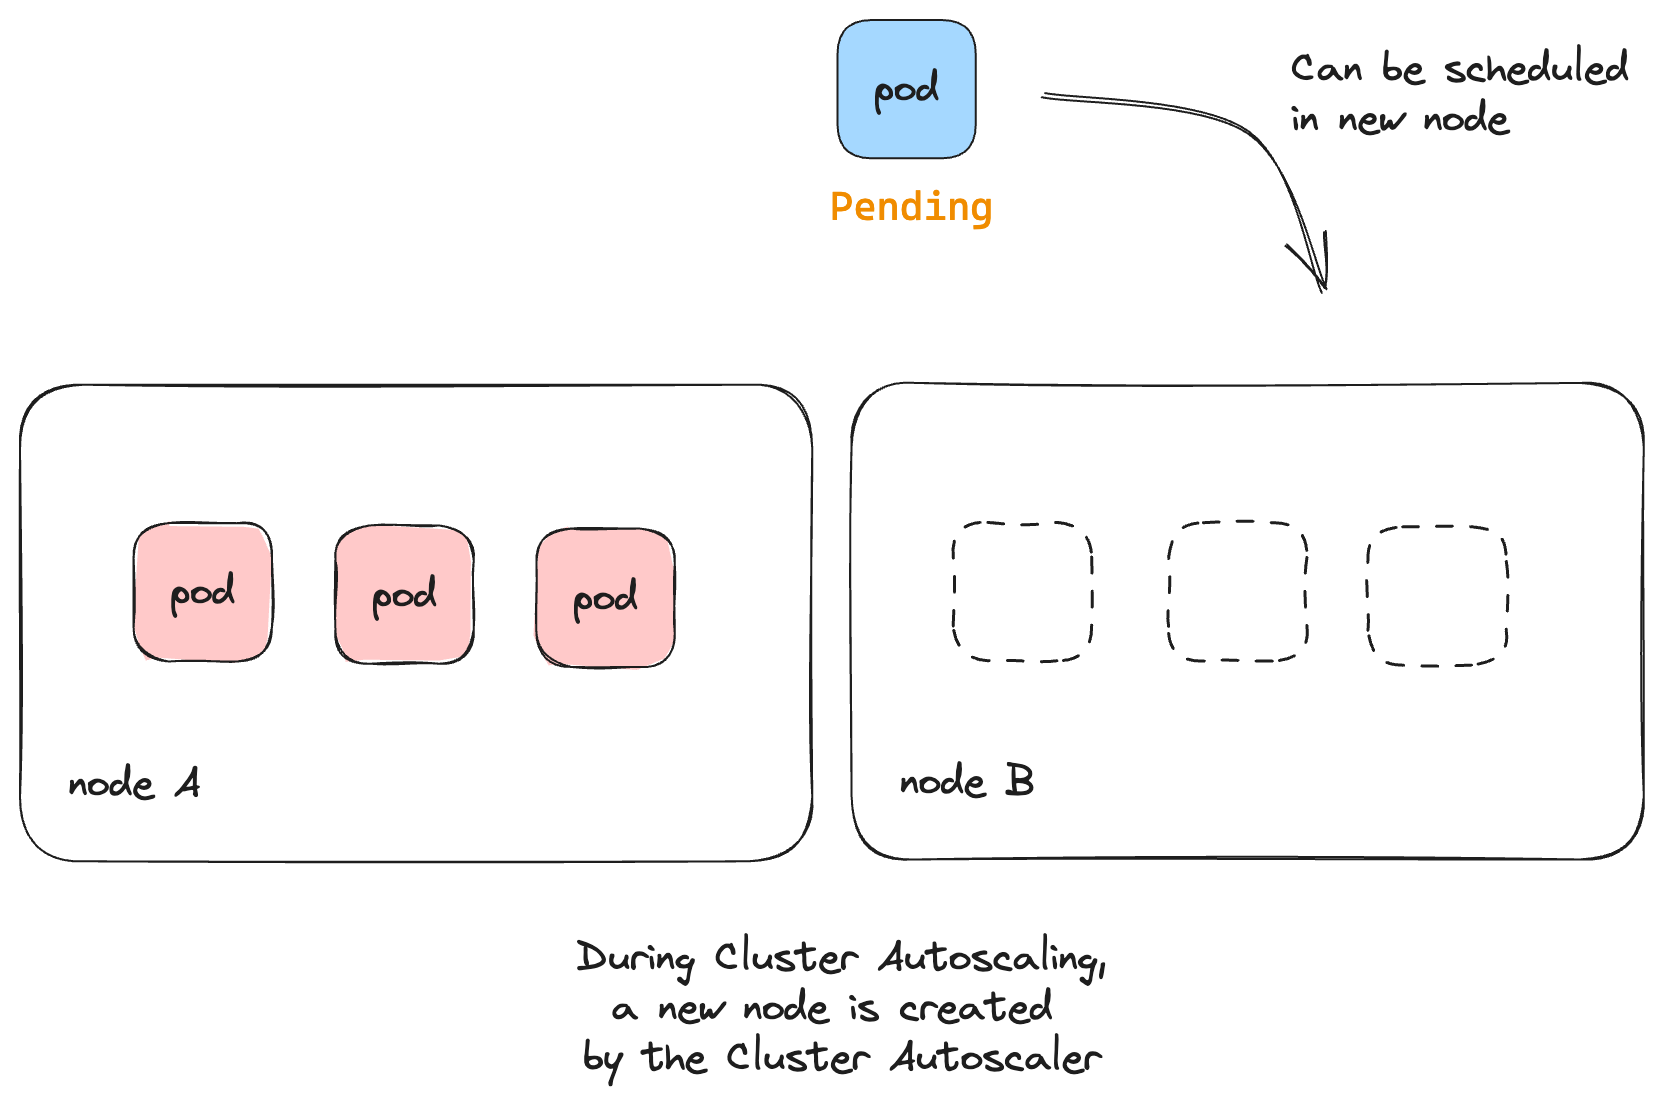
<ol start="2">
<li>The Cluster Autoscaler keeps checking if there are unscheduled pods. If so,
the Cluster Autoscaler triggers a scale-up by provisioning a new node and
attaching it to the cluster.</li>
</ol>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/cluster-autoscaler-2.png" alt="Illustration of cluster autoscaler provisioning a new node"></p>
<ol start="3">
<li>Once the new node has been provisioned, the capacity of the cluster has
increased, and the pod, which was previously in the <code>Pending</code> state, will be
scheduled to the newly created node.</li>
</ol>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/cluster-autoscaler-3.png" alt="Illustration of the pending pod being scheduled to the newly provisioned node"></p>
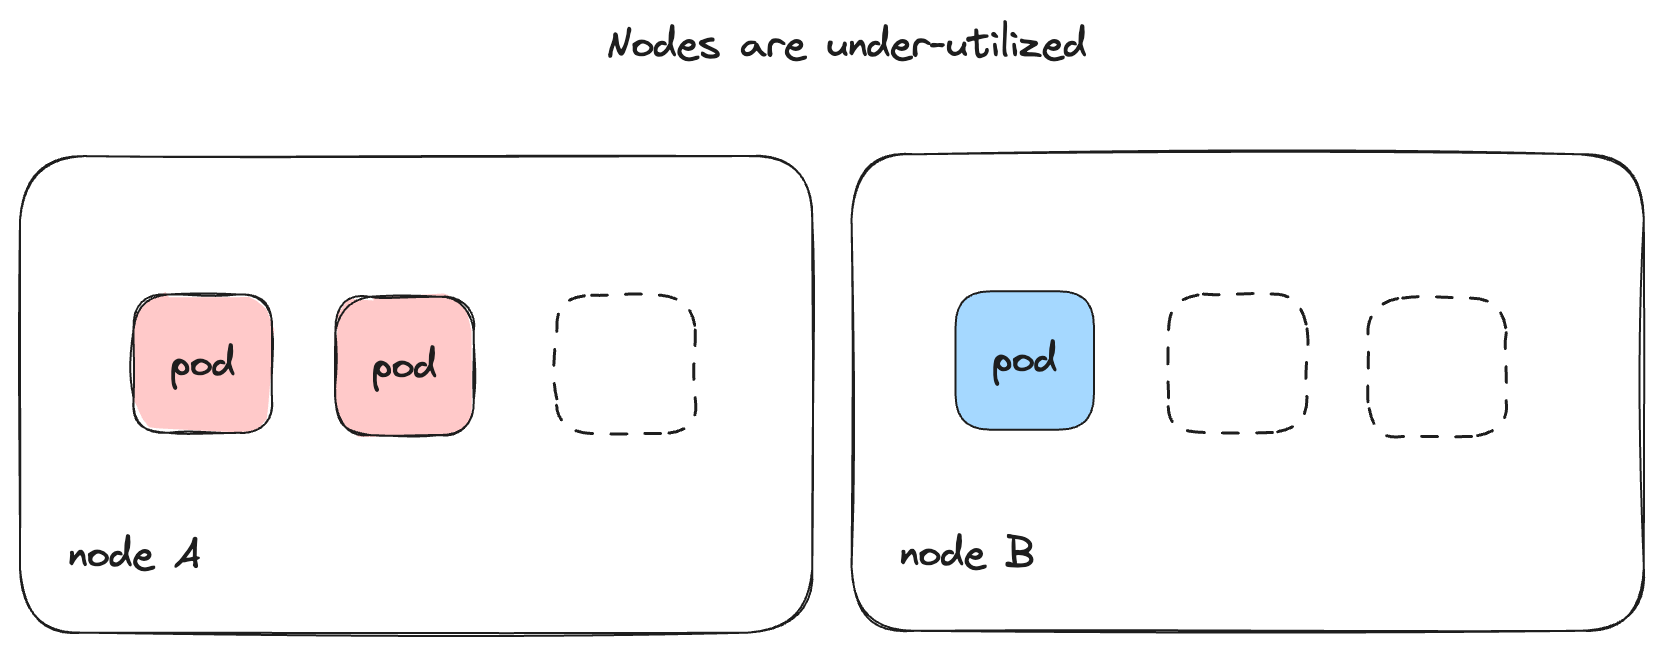
<p>The same thing can happen in reverse as well. Consider the case where
deployments are deleted or scaled down, and our nodes are not utilized
completely.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/cluster-autoscaler-4.png" alt="Illustration of nodes being under-utilized"></p>
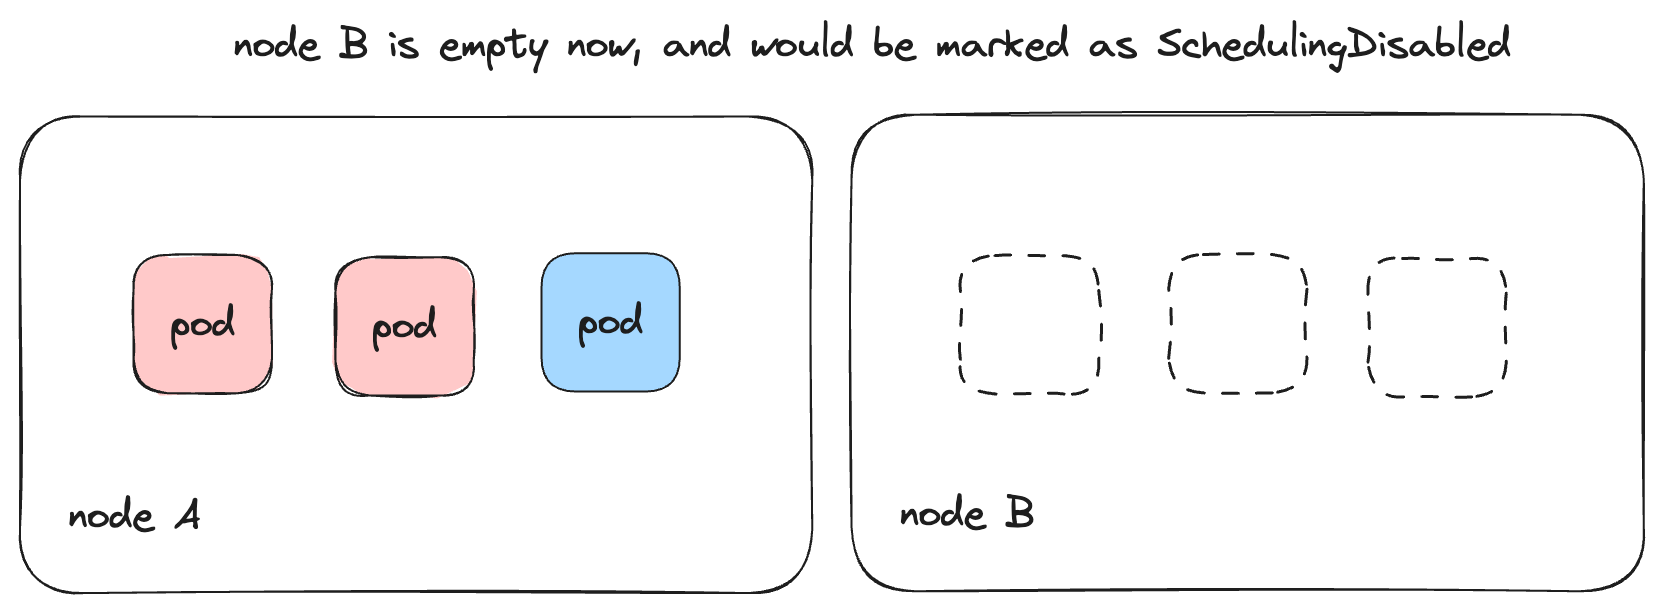
<p>In such a scenario, the Cluster Autoscaler would scale down the nodes so that
only the minimum required resources are running. Existing deployments from
different nodes would be rescheduled and &quot;packed&quot; into a smaller number of nodes
before the unwanted machines are terminated. The Cluster Autoscaler marks unused
nodes as <code>SchedulingDisabled</code> so that no pods are scheduled or moved into this
node.</p>
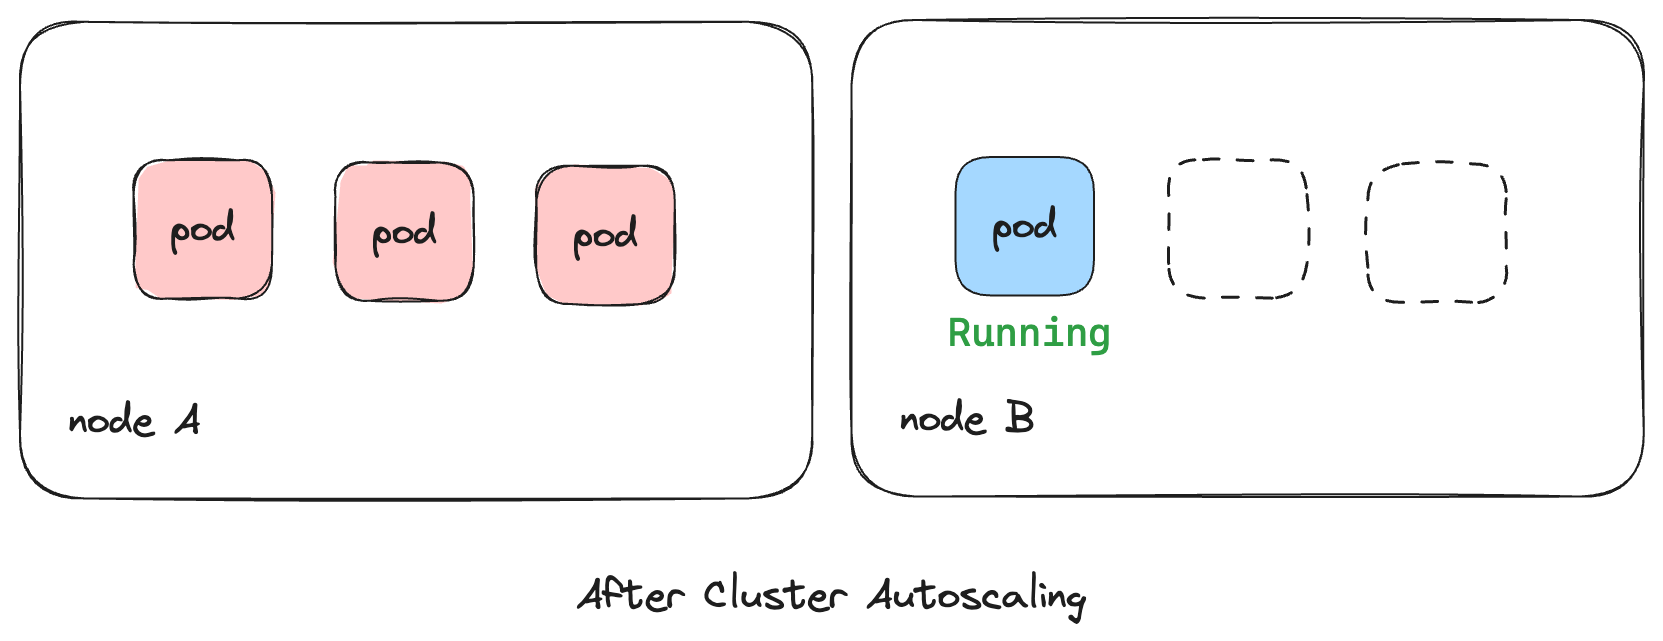
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/cluster-autoscaler-6.png" alt="Illustration of how pods are packed into minimum number required"></p>
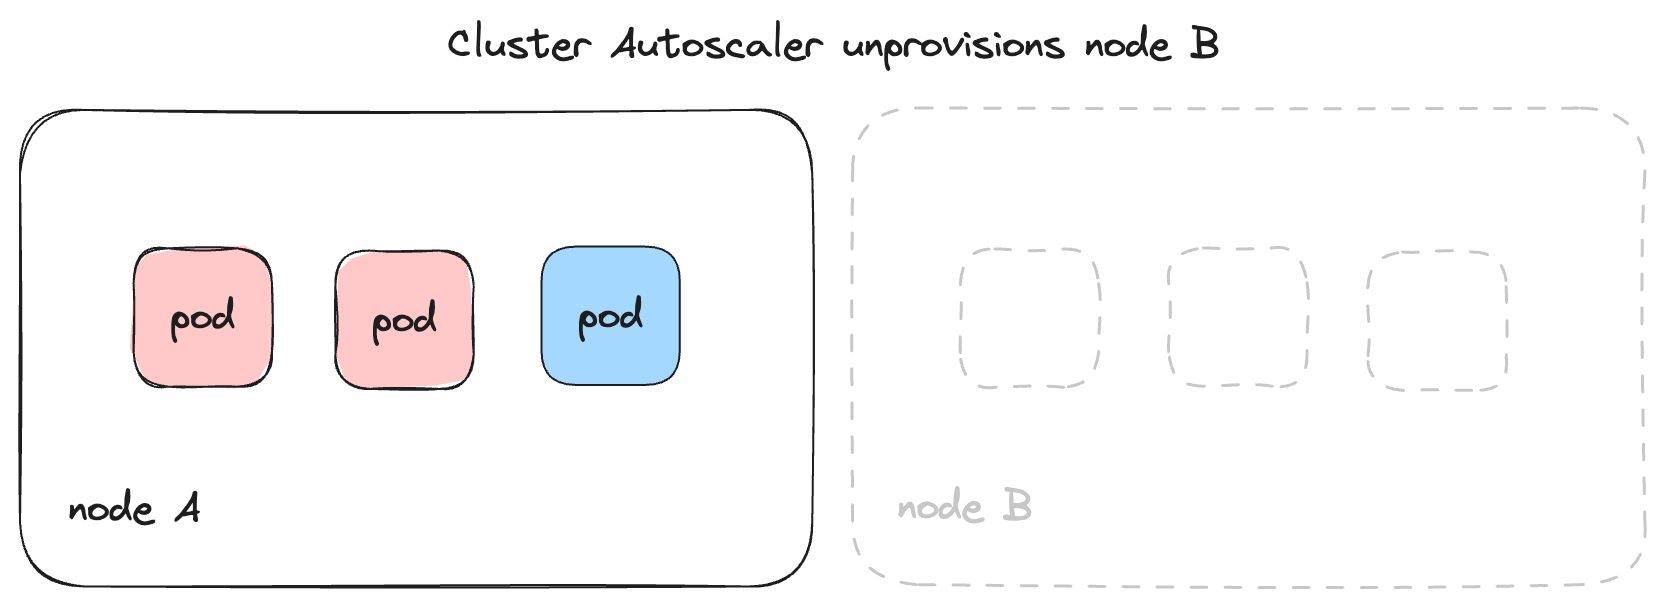
<p>The Cluster Autoscaler then unprovisions the unused node.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/solving-scalability-in-neeto-deploy/cluster-autoscaler-7.png" alt="Illustration of how unused nodes are unprovisioned"></p>
<p>The Cluster Autoscaler ensures that the cluster is in a stable state where no
pods are stuck in the <code>Pending</code> state, and no under-utilized resources are kept
running. By default, the Cluster Autoscaler checks for pending pods and scales
down candidates every 10 seconds, but we can configure this to increase or
decrease the speed at which the cluster autoscales.</p>
<h2>Deploying the Cluster Autoscaler</h2>
<p>The code for Cluster Autoscaler is available at
<a href="https://github.com/kubernetes/autoscaler">kubernetes/autoscaler</a>, and this can
be used to set up Cluster Autoscaler with any Kubernetes cluster.</p>
<p>All major cloud platforms like AWS, GCP, Azure, and DigitalOcean have Cluster
Autoscaler support in their managed Kubernetes services. For example, if the
Cluster Autoscaler is deployed on Amazon’s Elastic Kubernetes Service (EKS). It
would spawn new EC2 instances as needed and attach them to the EKS cluster’s
control plane. The complete list of all cloud providers is
<a href="https://github.com/kubernetes/autoscaler/tree/master/cluster-autoscaler#deployment">here</a>.</p>
<p>Since we are running NeetoDeploy on EKS, we referred to the documentation for
setting up autoscaler with EKS and created an OIDC identity provider in IAM. We
then created an IAM policy for using the autoscaler with the necessary
permissions, such as <code>DescribeAutoScalingGroups</code> for describing autoscaling
groups in AWS and <code>setDesiredCapacity</code> to change the desired limit of nodes in
the cluster, etc.</p>
<p>We then created an IAM role with the IAM policy and OIDC provider created
earlier and used this role to set up RBAC in the cluster, along with the Cluster
Autoscaler deployment. This ensures that the Cluster Autoscaler deployment has
all the permissions it needs for inspecting pending pods and working with nodes.</p>
<h2>Seeing the autoscaler in action</h2>
<p>Once all of this was done, we tried creating multiple deployments with more
significant memory and CPU limits consecutively to see if the cluster could
handle the increased load. Even though the autoscaler took some time to react to
the increased load, the cluster was getting scaled up according to the
requirement, and none of the pods were stuck in the <code>Pending</code> state for long.
Once we deleted our test deployments, the cluster automatically scaled back
down.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">Twitter</a>. You can also join our
<a href="https://launchpass.com/neetohq">community Slack</a> to chat with us about any
Neeto product.</p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Continuous backup of PostgreSQL in NeetoDeploy]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/postgresql-continuos-rollback-feature"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/continuous_backup_of_PostgreSQL.jpg"/>
      <id>https://www.bigbinary.com/blog/postgresql-continuos-rollback-feature</id>
      <published>2023-08-01T00:00:00.000Z</published>
      <updated>2023-08-01T00:00:00.000Z</updated>
      <author>
        <name>Abhishek T</name>
        <uri>https://www.bigbinary.com/blog/authors/abhishekt98</uri>
      </author>
      <category term="NeetoDeploy"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/continuous_backup_of_PostgreSQL.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[NeetoDeploy is a Heroku alternative for deploying web applications. Currently, NeetoDeploy is being used by Neeto for all pull request review applications and the staging application. NeetoDeploy is...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/postgresql-continuos-rollback-feature"><![CDATA[<p><a href="https://neeto.com/neetodeploy">NeetoDeploy</a> is a Heroku alternative for
deploying web applications. Currently, NeetoDeploy is being used by Neeto for all
pull request review applications and the staging application. NeetoDeploy is a
platform as a service (PaaS) solution that makes it easy to manage and deploy
applications with features like database backup, auto deployment from GitHub,
live logs, SSL certificates management, auto scaling, and more.</p>
<p>NeetoDeploy's PostgreSQL add-on has a continuous backup feature. This feature
allows you to roll your database back to a specific time in the past. We can
split the continuous backup process into data backup and recovery. Let's discuss
these steps in detail.</p>
<h2>Initial setup</h2>
<p>Let us create a new PostgreSQL cluster and populate it with some data.</p>
<h4>Creating parent database</h4>
<pre><code class="language-bash">initdb /usr/local/var/postgresql-parent
</code></pre>
<h4>Creating some sample data</h4>
<p>Start the PostgreSQL server and log in using <code>psql</code>. Provide the role and password if
needed.</p>
<pre><code class="language-bash">pg_ctl -D /usr/local/var/postgresql-parent start
psql -d postgres
</code></pre>
<h4>Create a new table</h4>
<pre><code class="language-sql">postgres=#
CREATE TABLE customers (
  user_id SERIAL PRIMARY KEY,
  username VARCHAR(50),
  email VARCHAR(100),
  registration_date DATE
);
</code></pre>
<h4>Seed sample data</h4>
<pre><code class="language-sql">postgres=#
INSERT INTO customers  (username, email, registration_date)
VALUES
('johndoe', 'johndoe@example.com', '2021-01-01'),
('janedoe', 'janedoe@example.com', '2021-02-15'),
('bobsmith', 'bobsmith@example.com', '2021-03-10'),
('sarahlee', 'sarahlee@example.com', '2021-04-05'),
('maxwell', 'maxwell@example.com', '2021-05-20');
</code></pre>
<h2>Data backup</h2>
<p>To perform recovery, we need to have access to the existing data. Hence we must
store all the database changes in a separate location, allowing us to utilize
this data for recovery.</p>
<p>This is where the
<a href="https://www.postgresql.org/docs/current/wal-intro.html">Write Ahead Log (WAL)</a>
in PostgreSQL comes into play. PostgreSQL follows a mechanism that writes all
transactions to the WAL before committing them to the table data files. By
preserving the WAL, we can reconstruct the data by traversing the logged
transactions. Utilizing the information stored in the WAL, we can systematically
reapply the recorded transactions to recreate the data and achieve the desired
recovery. Your WAL files are in your PostgreSQL data directory's <code>pg_wal</code>
folder.</p>
<h3>WAL archiving</h3>
<p>As data modifications occur in the databases, new WAL files are generated while
older WAL files are eventually discarded. Therefore, it is crucial to store the
WAL files before they are deleted. Here we will use an
<a href="https://aws.amazon.com/s3/">AWS S3 bucket</a> to store our WAL files. Also, we
will use <a href="https://github.com/wal-e/wal-e">wal-e</a> and
<a href="https://pypi.org/project/envdir/">envdir</a> to simplify the process.</p>
<h4>Install helper modules</h4>
<pre><code class="language-bash">python3 -m pip install wal-e envdir
</code></pre>
<p>If you face any dependency issues, please refer
<a href="https://github.com/wal-e/wal-e">wal-e</a> to fix them.</p>
<h4>Store AWS S3 credentials</h4>
<p>To use &quot;envdir&quot; with your AWS credentials, store them in a folder. The following
code snippet demonstrates how to accomplish this:</p>
<pre><code class="language-bash">mkdir ~/wal-e.env
echo &quot;YOUR_AWS_REGION&quot; &gt; ~/wal-e.env/AWS_REGION
echo &quot;YOUR_AWS_SECRET_ACCESS_KEY&quot; &gt; ~/wal-e.env/AWS_SECRET_ACCESS_KEY
echo &quot;YOUR_AWS_ACCESS_KEY_ID&quot; &gt; ~/wal-e.env/AWS_ACCESS_KEY_ID
echo &quot;YOUR_AWS_STORAGE_PATH&quot; &gt; ~/wal-e.env/WALE_S3_PREFIX
</code></pre>
<h4>Configure WAL archiving</h4>
<p>Now, let's configure PostgreSQL to store the WAL files in your S3 bucket before
they are deleted. Open your PostgreSQL configuration file &quot;postgresql.conf&quot;,
which is located in your data directory i.e.,
&quot;/usr/local/var/postgresql-parent&quot;, and make the following changes.</p>
<pre><code class="language-bash"># To enable WAL archiving.
archive_mode = on

# Determines how much information is written to the WAL.
wal_level = replica

# Force PostgreSQL to switch WAL file in every 60 seconds
archive_timeout = 60

# Command for pushing the wal files to the S3 bucket.
archive_command = 'envdir ~/wal-e.env wal-e wal-push %p'
</code></pre>
<p>You can find more information about the above configurations by referring to
this
<a href="https://www.postgresql.org/docs/current/runtime-config-wal.html#GUC-ARCHIVE-COMMAND">documentation</a>.</p>
<p>Now let's restart the server.</p>
<pre><code class="language-bash"> data_directory=&quot;/usr/local/var/postgresql-parent&quot;
 pg_ctl -D $data_directory restart -l $data_directory/postgresql.log
</code></pre>
<p>You can watch the PostgreSQL logs like this.</p>
<pre><code class="language-bash"> tail -f /usr/local/var/postgresql-parent/postgresql.log
</code></pre>
<p>After starting your server, monitor the PostgreSQL logs. If you don't observe
any WAL archive logs even after 60 seconds, it is because a WAL file switch will
only occur if there are any modifications. To generate the desired outcome, make
updates in the database. Upon doing so, you will be able to see lines similar to
the following in your PostgreSQL logs:</p>
<pre><code>Message: 'MSG: completed archiving to a file\nDETAIL: Archiving to &quot;s3://neeto-deploy-backups/local/wal_005/000000020000000000001.lzo&quot; complete at 158.209KiB/s.\nSTRUCTURED: time=2023-05-18T06:22:27.613242-00 pid=263 action=push-wal key=s3://neeto-deploy-backups/local/wal_005/000000020000000000001.lzo prefix=local/ rate=158.209 seg=000000020000000000001 state=complete'
</code></pre>
<h3>Base backup</h3>
<p>Since we have enabled WAL archiving, all new changes are stored in the bucket as
WAL files. However, what about the data we created before configuring WAL
archiving? To ensure a complete recovery, we also need that data. Therefore, we
need to take a base backup of our database. The following code will initiate the
base backup process and push it to the S3 bucket.</p>
<pre><code class="language-bash">envdir ~/wal-e.env wal-e backup-push /usr/local/var/postgresql-parent
</code></pre>
<p>Running the above command yields the following output.</p>
<pre><code>wal_e.main   INFO     MSG: starting WAL-E
DETAIL: The subcommand is &quot;backup-push&quot;.
STRUCTURED: time=2023-05-18T06:24:27.613242-00 pid=41178
wal_e.worker.upload INFO     MSG: begin uploading a base backup volume

DETAIL: Uploading to &quot;s3://neeto-deploy-backups/local/basebackups_005/
base_000000010000000000005_00000040/tar_partitions/part_00000000.tar.lzo&quot;.
STRUCTURED: time=2023-05-18T06:24:29.527622-00 pid=41178
wal_e.worker.upload INFO     MSG: finish uploading a base backup volume

DETAIL: Uploading to &quot;s3://neeto-deploy-backups/local/basebackups_005/
base_000000010000000000005_00000040/tar_partitions/part_00000000.tar.lzo&quot;
complete at 1459.68KiB/s.
STRUCTURED: time=2023-05-18T06:24:33.121716-00 pid=41178
NOTICE:  all required WAL segments have been archived

</code></pre>
<p>After completing the base backup, you can verify the presence of the base backup
folder in your S3 bucket. Now we have the backup and new WAL files are being
pushed to our bucket.</p>
<h2>Data recovery</h2>
<p>Let's consider a scenario where you need to perform a rollback. Suppose you
accidentally deleted a table from your database that contained multiple records,
making it impractical to recall and reinsert them manually. As a first step,
make a note of the time at which the table was deleted. For instance, let's say
it occurred on 2023-05-18 11:57:11 UTC. The objective is to roll back to a point
before that time. Let's roll back to 2023-05-18 at 11:57:00 UTC.</p>
<h3>Let's make a mistake</h3>
<p>We are going to drop a table.</p>
<pre><code class="language-sql">postgres=#
DROP TABLE customers;
</code></pre>
<p>Note the time the table got deleted. Here it is 2023-05-18 11:57:11 UTC. Now
let's discuss how we can restore the deleted table.</p>
<h3>Creating a new data directory</h3>
<p>Let's create a new data directory where we can recover the data.</p>
<pre><code class="language-bash">initdb /usr/local/var/postgresql-child
</code></pre>
<h3>Fetch the base backup</h3>
<p>The base backup serves as the starting point, while the remaining data will be
regenerated by PostgreSQL using the WAL files. To fetch the base backup, you can
use the following code snippet.</p>
<pre><code class="language-bash">envdir ~/wal-e.env wal-e backup-fetch /usr/local/var/postgresql-child LATEST
</code></pre>
<p>The &quot;LATEST&quot; tag will pull the latest base backup if multiple base backups are
in the bucket. On running the above command you will receive an output similar
to the following.</p>
<pre><code>wal_e.main   INFO     MSG: starting WAL-E
DETAIL: The subcommand is &quot;backup-fetch&quot;.
STRUCTURED: time=2023-05-18T06:29:22.826910-00 pid=41789
wal_e.worker.s3.s3_worker INFO     MSG: beginning partition download
DETAIL: The partition being downloaded is part_00000000.tar.lzo.
HINT: The absolute S3 key is local/basebackups_005/
base_000000010000000000000005_00000040/tar_partitions/part_00000000.tar.lzo.
STRUCTURED: time=2023-05-18T06:29:24.674572-00 pid=41789
</code></pre>
<h3>Configuring recovery</h3>
<p>Now, we need to regenerate the remaining data from the WAL files. To do that,
make the following changes in the PostgreSQL configuration file.</p>
<pre><code class="language-bash">#postgresql.conf

# Command to fetch each wal files from the bucket.
restore_command = 'envdir ~/wal-e.env wal-e wal-fetch %f %p'

# Time at which we want to stop recovery.
recovery_target_time  = '2023-05-18 11:57:00'
</code></pre>
<p>We can stop the parent server since it is no longer needed.</p>
<pre><code class="language-bash">pg_ctl -D /usr/local/var/postgresql-parent stop
</code></pre>
<p>To initiate the server in recovery mode and to allow PostgreSQL to regenerate
the data using the WAL files, create a file named &quot;recovery.signal&quot; in the new
data directory.</p>
<pre><code class="language-bash">touch /usr/local/var/postgresql-child/recovery.signal
</code></pre>
<p>Start the child server pointing to the new data directory by running the
following command.</p>
<pre><code class="language-bash"> data_directory=&quot;/usr/local/var/postgresql-child&quot;
 pg_ctl -D $data_directory start -l $data_directory/postgresql.log
</code></pre>
<p>If you examine the PostgreSQL logs, you will notice that the recovery process is
paused at the specified time.</p>
<pre><code>2023-05-18 12:07:41.688 IST [43159] LOG:  restored log file &quot;000000010000000000006&quot; from archive
2023-05-18 12:07:41.692 IST [43159] LOG:  recovery stopping before commit of transaction 743, time 2023-05-18 11:57:11.135927+05:30
2023-05-18 12:07:41.692 IST [43159] LOG:  pausing at the end of recovery
2023-05-18 12:07:41.692 IST [43159] HINT:  Execute pg_wal_replay_resume() to promote.
</code></pre>
<p>It's important to note that you won't be able to connect to the server using
psql at this point because it is not ready to accept connections. By default,
PostgreSQL pauses the recovery process after reaching the recovery target time.
To change this behavior and to allow the server to accept connections after
reaching the target time, add the following configuration to your PostgreSQL
configuration file.</p>
<pre><code class="language-bash">recovery_target_action  = 'promote'
</code></pre>
<p>After making the above change, restart the server once again by running the
following command.</p>
<pre><code class="language-bash">data_directory=&quot;/usr/local/var/postgresql-child&quot;
pg_ctl -D $data_directory restart -l $data_directory/postgresql.log
</code></pre>
<p>Now, you will observe that the server is ready to accept connections after
completing the recovery process. Once the recovery is successfully completed,
PostgreSQL automatically deletes the &quot;recovery.signal&quot; file. You can verify the
successful deletion of the recovery file from your data directory.</p>
<p>Once the server is up and ready, connect to the server and check if the deleted
table is present. You will find that the deleted table is now restored and
available in the database.</p>
<pre><code class="language-sql">postgres=#
select * from customers;

 user_id | username |        email         | registration_date
---------+----------+----------------------+-------------------
       1 | johndoe  | johndoe@example.com  | 2021-01-01
       2 | janedoe  | janedoe@example.com  | 2021-02-15
       3 | bobsmith | bobsmith@example.com | 2021-03-10
       4 | sarahlee | sarahlee@example.com | 2021-04-05
       5 | maxwell  | maxwell@example.com  | 2021-05-20
(5 rows)
</code></pre>
<p>To learn more about PostgreSQL continuous backup, you can refer to the
<a href="https://www.PostgreSQL.org/docs/current/continuous-archiving.html">official PostgreSQL documentation</a>.</p>
<h2>Challenges faced</h2>
<h3>Restoration of PostgreSQL roles</h3>
<p>When we restored the PostgreSQL database, the roles and passwords were also
restored in the database. However, we create a new database with the desired
data in the continuous rollback feature. Therefore, we should use a new role and
password to ensure security. We resolved this issue by changing the restored
role and password to a new one.</p>
<h3>Early recovery completion</h3>
<p>Another issue we encountered was the early recovery of the database before
reaching the specified target time. Suppose no activity occurs in the database,
and we attempt to roll back to the current time. PostgreSQL initiates the
recovery process and recovers all the available WAL files. However, it fails to
locate the target time since no corresponding WAL file is available for the
given timestamp. PostgreSQL raises the following error in this scenario and
shuts down the server.</p>
<pre><code>2023-05-18 02:12:15.846 UTC [76] LOG:  last completed transaction
was at log time 2023-05-18 02:04:02.755919+00
2023-05-18 02:12:15.846 UTC [76] FATAL:  recovery ended before configured
recovery target was reached
2023-05-18 02:12:15.850 UTC [75] LOG:  startup process (PID 76) exited with
exit code 1
2023-05-18 02:12:15.850 UTC [75] LOG:  terminating any other active server
processes
2023-05-18 02:12:15.853 UTC [75] LOG:  shutting down due to startup
process failure
2023-05-18 02:12:15.859 UTC [75] LOG:  database system is shut down
</code></pre>
<p>In this case, we can remove the specified target time and restart the server. If
we do not provide any target time, PostgreSQL will recover until the last
available WAL file, which will contain the latest transaction of our database.</p>
<h3>Recovery is an asynchronous process</h3>
<p>As mentioned above, we must update the restored role and password to new ones.</p>
<pre><code class="language-bash">update-role-and-password(){
# Create a new temporary user as we cannot update the current session user.
psql -d &lt;DB_NAME&gt; \
-c &quot;CREATE USER tempuser WITH SUPERUSER LOGIN PASSWORD 'tempuser-pwd';&quot;

# Login as a temporary user and update the parent role and password.
PGPASSWORD=tempuser  PGUSER=tempuser-password  psql -d &lt;DB_NAME&gt; \
-c &quot;ALTER ROLE &lt;parent-role&gt; RENAME TO &lt;NEW_ROLE&gt;;
ALTER ROLE &lt;NEW_ROLE&gt; WITH PASSWORD &lt;NEW_PASSWORD&gt;;&quot;

# Login as the new user and remove the temporary user.
PGPASSWORD=&lt;NEW_ROLE&gt; PGUSER=&lt;NEW_PASSWORD&gt; psql -d &lt;DB_NAME&gt; \
-c &quot;DROP ROLE tempuser;&quot;
}


# Start the server in recovery mode.
pg_ctl -D /usr/local/var/postgresql-child start

# Call the method to update role and password.
update-role-and-password

</code></pre>
<p>If you try the above code, you will encounter the following error.</p>
<pre><code>ERROR:  cannot execute CREATE ROLE in a read-only transaction
</code></pre>
<p>Since the recovery process is asynchronous, the system may attempt to update the
role before completing the recovery. It is important to note that the server
will be in read-only mode during the recovery, which can lead to the error
mentioned.</p>
<p>To solve this issue, it is necessary to determine when the recovery process was
completed. This can be achieved by checking for the existence of the &quot;recovery.
signal&quot; file in a loop.</p>
<pre><code class="language-bash">wait_until_recovery_is_completed()
{
  recovery_signal_path=&quot;/usr/local/var/postgresql-child/recovery.signal&quot;
  while [ -f &quot;$file_path&quot; ]; do
    sleep 1  # Wait for 1 second before checking again.
  done
}

</code></pre>
<pre><code>pg_ctl -D /usr/local/var/postgresql-child start
wait_until_recovery_is_completed
update-role-and-password
</code></pre>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[NeetoDeploy: Zero to One]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/neeto-deploy-zero-to-one"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/neetoDeploy_an_alternative_to_heroku.jpg"/>
      <id>https://www.bigbinary.com/blog/neeto-deploy-zero-to-one</id>
      <published>2023-06-08T00:00:00.000Z</published>
      <updated>2023-06-08T00:00:00.000Z</updated>
      <author>
        <name>Unnikrishnan KP</name>
        <uri>https://www.bigbinary.com/blog/authors/unni</uri>
      </author>
      <category term="NeetoDeploy"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/neetoDeploy_an_alternative_to_heroku.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[How we built the first version of NeetoDeploy from scratch]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/neeto-deploy-zero-to-one"><![CDATA[<p>This blog chronicles the exciting journey of how we built
<a href="https://neeto.com/neetodeploy">NeetoDeploy</a>. It's a Heroku alternative. We
started from absolute zero and built a fully functional PaaS product with almost
all the features that Heroku offers on their review apps, with a team of 4
developers in 2 months.</p>
<h2>How it all started</h2>
<p>At <a href="https://neeto.com">Neeto</a>, we are building
<a href="https://blog.neeto.com/p/neeto-products-and-people">20+ products</a>
simultaneously. All of these products had their production and staging
environments hosted on Heroku. In addition, pull requests from these products
had review apps deployed on Heroku. With an average of 5 open PRs at any time
per product, we are talking about 100+ live review apps, 20+ staging apps, and
15+ production apps. Each one of these apps needed PostgreSQL, Redis, and
ElasticSearch instances, besides other requirements.</p>
<p>In August 2022, Heroku made this
<a href="https://blog.heroku.com/next-chapter">announcement</a>.</p>
<blockquote>
<p>&quot;Starting November 28, 2022, we plan to stop offering free product plans and
plan to start shutting down free dynos and data services.&quot;</p>
</blockquote>
<p>It meant that in 2 months, our monthly Heroku bill would skyrocket. At first, we
talked about switching to one of the Heroku alternatives.</p>
<blockquote>
<p>&quot;Every problem is an opportunity in disguise.&quot; - John Adams.</p>
</blockquote>
<p>And we thought - &quot;Why not build our own Heroku replacement?&quot;.</p>
<p><a href="https://bigbinary.com">BigBinary</a> has over 11 years of Ruby on Rails and React
consulting expertise. However, building a Heroku replacement, a complex The
DevOps-heavy project was way out of our comfort zone. With faith in our
engineering team and an exuberant spirit of youthful adventure, we embarked on a
journey in early September 2022 to build
<a href="https://neeto.com/neetodeploy">NeetoDeploy</a>.</p>
<h2>The Journey</h2>
<p>We put together a team of 4 developers. We discussed technologies ranging from
Capistrano, Ansible, and AWS to Kubernetes. The more we talked, the more it
became clear that no single technology could solve this problem. We needed a
complex system with multiple independent components that would interact together
to handle the following core responsibilities:</p>
<ol>
<li>GitHub integration.</li>
<li>A build system that would identify the application's run-time dependencies,
install them in the correct order, and build runnable machine images.</li>
<li>A scalable containerized environment that can run the pre-built machine
images.</li>
<li>A place to store the built machine images.</li>
<li>If the application needed a connection to external services (PostgreSQL,
Redis, ElasticSearch, etc.), the ability to provision those on run-time.</li>
<li>A dashboard to view and manage the deployments.</li>
<li>Live logs.</li>
<li>Load balancing/routing.</li>
</ol>
<h2>The Architecture</h2>
<p>Once we understood the core functionality, we devised an architecture for the
system. We then drew an architecture diagram depicting the different components
and how they would interact with each other.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2023/neeto-deploy-zero-to-one/neeto-deploy-arch.webp" alt="NeetoDeploy - Architecture"></p>
<p>This diagram helped facilitate the rest of the discussions and our questions
regarding the project's feasibility. We looked at the diagram and saw for the
first time that we could break up this complex beast into manageable pieces that
we could build, test and deploy independently.</p>
<p>As per the plan, NeetoDeploy would comprise the following independent
components:</p>
<ol>
<li>Slug Compiler</li>
<li>Dyno Manager</li>
<li>Add-on Manager</li>
<li>The Compute Cluster - with the router and load balancer</li>
<li>Web Dashboard</li>
</ol>
<h2>The Slug Compiler</h2>
<p>This component would bundle the application code, its run-time dependencies
(Ruby, Node, Ruby gems, NPM packages, third-party tools like ffmpeg, etc.), and
the operating system into a single image. We could then run this image on a
container.</p>
<p>Using Docker to build the image was the first approach that we tried. After
analyzing the problem, we understood that we needed to generate a Dockerfile on
the fly. While working on this problem, we stumbled upon
<a href="https://buildpacks.io/">Cloud Native Buildpacks</a>.</p>
<p>Their website said, &quot;transform your application source code into images that can
run on any cloud&quot;. This is precisely what we needed.</p>
<p>CNB(Cloud Native Buildpacks) system has three components:</p>
<ol>
<li>Stack</li>
<li>Builder</li>
<li>Buildpacks</li>
</ol>
<p>CNB provides <a href="https://github.com/buildpacks/pack">pack utility</a> that would
accept stack, builder, and buildpacks as parameters and build an OCI-compliant
machine image that works with existing Docker tooling and any broader container
ecosystem like Kubernetes. In addition, Heroku had open-sourced their older
stacks and builders.</p>
<p>Now we had everything we needed to build runnable images. But we needed the
ability to build multiple images in parallel since NeetoDeploy would have
various projects, and each project could have numerous deployments (app
corresponding to the main branch for staging/production and review apps for each
commit in a pull request).</p>
<p>We built the initial version of Slug Compiler as a Ruby on Rails application,
exposing API endpoints to start and stop a build. It would need a GitHub
repository URL to fetch the source code, a list of buildpacks, and a callback
URL as inputs. Once the image is successfully built, it will make a POST request
to the callback URL.</p>
<p>The slug compiler would spin up an EC2 machine for each build request. We made a
custom AMI from an Ubuntu image with <code>pack</code> and other packages required for the
CNB build system to run. Once the <code>pack</code> command builds the image, it will push
it to our Dockerhub account (Docker registry) and return the image URL via a
callback. It would then kill the EC2 instance.</p>
<p>We found uploading the image to <a href="https://hub.docker.com">Dockerhub</a> very slow.
So we set up a private Docker registry on
<a href="https://aws.amazon.com/ecs/">AWS ECS</a>.</p>
<h2>The Add-on Manager</h2>
<p>Applications typically need access to a database, search service, cache service,
etc. The Neeto products use PostgreSQL, Redis, and ElasticSearch. We decided to
build the first version of the add-on manager to support these add-ons.</p>
<p>We built the add-on infrastructure using three big
<a href="https://aws.amazon.com/ec2/">AWS EC2</a> boxes to keep things simple. Each machine
ran a PG, Redis, and ElasticSearch server, respectively. We made the add-on
manager as a Ruby on Rails API server, which would accept the add-on type as
input and return a connection URI with login credentials included. We would
support only a fixed version of the add-ons in the initial version.</p>
<p>Upon receiving the request for a PG add-on, we will create a new database on the
PG server with a unique username/password and return the connection string. For
Redis and ElasticSearch, we simulated separate connections using namespaces.</p>
<p>This add-on manager had some severe drawbacks since multiple applications shared
the same add-on servers running on the same physical machine. Two of the biggest
drawbacks had to do with Security and Resource choking.</p>
<ol>
<li>Security: With some effort, it was possible to tamper with the data of other
applications.</li>
<li>Resource choking: If one application uses more CPU and Memory, it blocks all
other applications.</li>
</ol>
<p>Nevertheless, this throw-away version of the add-on manager was a good start.</p>
<h2>The Dyno manager and the compute cluster</h2>
<p>We needed a secure, scalable, containerized environment to run our pre-built
images. <a href="https://kubernetes.io">Kubernetes</a> was the obvious answer. Kubernetes,
also known as K8s, is an open-source system for automating deployment, scaling,
and managing containerized applications. We created our cluster on
<a href="https://aws.amazon.com/eks/">AWS EKS</a>.</p>
<p>Dyno manager was once again a Ruby on Rails API server app, which takes a
pre-built OCI image URL and a callback URL as inputs. It would then interface
with the Kubernetes cluster using the
<a href="https://kubernetes.io/docs/reference/kubectl/">kubectl CLI</a> to deploy the image
on the cluster.</p>
<p>Our first cluster was of fixed size. It had four nodes (EC2 machines).
Kubernetes would deploy images to these machines and manage them. But the
fixed-size cluster soon proved inadequate as we had more parallel deployments
than could be accommodated. So we set up cluster autoscaling.</p>
<h2>Load balancing and routing</h2>
<p>All applications hosted on NeetoDeploy are made publicly available on a
_.neetoreviewapp.com subdomain. A public IP address is needed to set up a
<a href="https://www.cloudflare.com/en-gb/learning/dns/dns-records/dns-cname-record/">DNS CNAME record</a>
for _.neetoreviewapp.com. We provisioned an
<a href="https://aws.amazon.com/elasticloadbalancing/">Elastic Load Balancer</a>, an AWS
component with a public IP address. ELB is the component of our system that acts
as the interface to the outside world.</p>
<p>We now needed to route the incoming web requests based on the subdomain to one
of the deployed applications, which required a programmable router. An
<a href="https://docs.nginx.com/nginx-ingress-controller/">Nginx ingress controller</a>
would meet this requirement. The Nginx ingress controller is essentially an
Nginx server set up as a reverse proxy with the redirect rules necessary.</p>
<h2>The Web Dashboard</h2>
<p>NeetoDeploy needed an admin user-facing web application that would perform the
following functions:</p>
<ol>
<li>Admin user login.</li>
<li>Initiate Github account integration.</li>
<li>Select a repo and create a project.</li>
<li>View and manage the deployments for a project.</li>
<li>Interact with other components (Slug compiler, dyno manager, and add-on
manager) to coordinate and orchestrate the functioning of the NeetoDeploy
system.</li>
<li>Maintain state like store project-specific environment variables, add-on
connection URLs, pre-built image URLs, etc.</li>
</ol>
<p>We built the Dashboard app using Ruby on Rails, React.js,
<a href="https://blog.neeto.com/p/neetoui-is-the-ui-library-of-neeto">neetoUI</a>, and
other integrations typical of any Neeto product.</p>
<h2>Live logging</h2>
<p>We needed to fetch and display two types of logs at run-time:</p>
<ul>
<li>Build and release logs.</li>
<li>Application logs.</li>
</ul>
<p>Fetching live logs from a remote machine and displaying them in the browser is a
complicated problem. We went with
<a href="https://api.rubyonrails.org/classes/ActionController/Live/SSE.html">Server Side Events</a>
(SSE) for the first version and streamed the logs directly to the browser.</p>
<ol>
<li>The dyno manager would tail <code>kubectl logs</code>.</li>
<li>STDOUT was continuously read and transmitted as server-side events.</li>
<li>The dyno manager sent the <code>app-logs-url</code> to the dashboard app via a callback.</li>
<li>Dashboard app had a log-display React component that streamed the SSE events
using the <code>app-logs-url</code> and displayed the live logs.</li>
</ol>
<h2>How it all came together</h2>
<ol>
<li>The Admin user signed up for a new account.</li>
<li>The admin logged in to the Dashboard app.</li>
<li>The GitHub account was connected by the admin.</li>
<li>The admin created a new project after selecting a GitHub repository.</li>
<li>The admin made a new Pull Request in the selected GitHub repository.</li>
<li>The dashboard app received the GitHub event for the new pull request
creation.</li>
<li>The dashboard app requested the slug compiler to build an image for the
repository using code corresponding to the pull request's latest commit. It
also sent the list of buildpacks to use.</li>
<li>The dashboard app also requested the add-on manager to create the necessary
add-ons.</li>
<li>The dashboard app received the add-on URLs and saved them.</li>
<li>Slug compiler built the image, stored it on ECS and made a callback to the
dashboard app with the image URL, and the dashboard app saved the image URL.</li>
<li>The dashboard app requested the dyno manager to deploy and start the
necessary web and worker processes after passing the image URL and add-on
URLs as environment variables to set on the containers.</li>
<li>The Dyno manager talked to Kubernetes, completed the specified cluster
deployments and set up the necessary ingress rules.</li>
<li>The application is available for public access at
https://xyz.neetoreviewapp.com.</li>
</ol>
<h2>Roadmap</h2>
<p>We improved each component to make them scalable, secure and robust. We added
features like CLI, performance metrics, continuous database backup, enabled
caching, reduced build time, horizontal scaling to support the increased load,
platform extensibility with custom build packs, stabilized live logging with
<a href="https://fluentbit.io/">Fluentbit</a> and more.</p>
<p>We migrated the review apps and staging environment of all
<a href="https://neeto.com">neeto</a> products to NeetoDeploy. We also migrated production
instances of most of our static websites. We are now gearing up to migrate the
production instances of all the Neeto products. Exciting features like custom
plans for dynos, support for more add-on types, autoscaling to support
unexpected surges in traffic and more, are in the pipeline.</p>
<p>In the coming weeks and months, we will be writing more about the challenges we
faced and how we are building NeetoDeploy. Stay tuned for more.</p>
<p>If your application runs on Heroku, you can deploy it on NeetoDeploy without any
change. If you want to give NeetoDeploy a try, then please send us an email at
<a href="mailto:invite@neeto.com">invite@neeto.com</a>.</p>
<p>If you have questions about NeetoDeploy or want to see the journey, follow
NeetoDeploy on <a href="https://twitter.com/neetodeploy">Twitter</a>. You can also join our
<a href="https://launchpass.com/neetohq">community Slack</a> to chat with us about any
Neeto product.</p>
]]></content>
    </entry>
</feed>