<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom" xmlns:media="http://search.yahoo.com/mrss/" xml:lang="en-US">
  <title>BigBinary Blog: Puma</title>
  <subtitle>Deep technical writing on Ruby on Rails, performance, scaling, monitoring and engineering.</subtitle>
  <link rel="self" type="application/atom+xml" href="https://www.bigbinary.com/blog/categories/puma/feed.xml"/>
  <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/categories/puma"/>
  <id>https://www.bigbinary.com/blog/categories/puma</id>
  <updated>2025-05-13T00:00:00.000Z</updated>
  <author>
    <name>BigBinary</name>
    <uri>https://www.bigbinary.com/</uri>
  </author>
  <icon>https://www.bigbinary.com/favicon.ico</icon>
  <logo>https://www.bigbinary.com/images/bigbinary_square_big_logo.png</logo>
  <rights>Copyright 2025 Big Binary LLC</rights>
  <generator uri="https://nextjs.org">Next.js</generator>
  <entry>
      <title type="text"><![CDATA[Understanding Active Record Connection Pooling]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/understanding-active-record-connection-pooling"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/understanding_active_record_connection_pooling.jpg"/>
      <id>https://www.bigbinary.com/blog/understanding-active-record-connection-pooling</id>
      <published>2025-05-13T00:00:00.000Z</published>
      <updated>2025-05-13T00:00:00.000Z</updated>
      <author>
        <name>Vishnu M</name>
        <uri>https://www.bigbinary.com/blog/authors/vishnu-m</uri>
      </author>
      <category term="Rails"/>
      <category term="Puma"/>
      <category term="Ruby"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/understanding_active_record_connection_pooling.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[This is Part 5 of our blog series on scaling Rails applications. Database Connection Pooling When a Rails application needs to interact with a database, it establishes a connection, which is a...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/understanding-active-record-connection-pooling"><![CDATA[<p><em>This is Part 5 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>.</em></p>
<h2>Database Connection Pooling</h2>
<p>When a Rails application needs to interact with a database, it establishes a
connection, which is a dedicated communication channel between the application
and the database server. When a new request comes to Rails, the operation can be
handled like this.</p>
<ol>
<li>Create a connection</li>
<li>Do database operation</li>
<li>Close the connection</li>
</ol>
<p>When the next request comes, then repeat the above process.</p>
<p>Creating new database connections is an expensive operation - it takes time to
establish the connection, authenticate, and set up the communication channel. It
means that every single time a request comes, we are spending time in setting up
the connection.</p>
<p>Wouldn't it be better to store the established connection to somewhere and when
a new request comes, then get the pre-established connection from this pool.
This expedites the process since we don't need to create a connection and close
a connection in every single request.</p>
<p>The new process might look like this.</p>
<ol>
<li>Create a connection</li>
<li>Do database operation</li>
<li>Put the connection in a pool</li>
</ol>
<p>Now, when a new request comes, the operation will look like this.</p>
<ol>
<li>Get the connection from the pool</li>
<li>Do database operation</li>
<li>Return the connection to the pool</li>
</ol>
<p>Database connection pooling is a performance optimization technique that
maintains a set of reusable database connections.</p>
<h2>Active Record Connection Pool Implementation</h2>
<p>Active Record manages a pool of database connections for each web and background
process. Each process will have a connection pool of its own, which means a
Rails application running with multiple processes (like Puma processes, Sidekiq
processes) will have multiple independent connection pools. The pool is a set of
database connections that are shared among threads in the <strong>same process</strong>.</p>
<p>Note that the pooling happens at the process level. A thread from process A
can't get a connection from process B.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/understanding-active-record-connection-pooling/without-pg-bouncer.png" alt="Connection pooling"></p>
<p>When a connection is needed, the thread checks out a connection from the pool,
perform operations, and then returns the connection to the pool. This is done at
a query level now. For each individual query, a connection is leased, used, and
then returned back to the pool.</p>
<p>Pre Rails 7.2, the connection used to be leased and held till the end of the
request if it is a web request and till the job is done if it is a background
job. This was a problem for applications that spent a lot of time doing I/O. The
thread will hog the connection for the entire duration of the I/O operation
limiting the number of queries that can be executed concurrently. To facilitate
this change and make query caching work, the query cache has been
<a href="https://github.com/rails/rails/pull/50938/">updated</a> to be owned by the pool.</p>
<p>This means that the query cache is now shared across all connections in the
pool. Previously, each connection had its own query cache. As the whole request
used the same connection, this was fine. But now, as the connection is leased
for each query, the query cache needs to be shared across all connections in the
pool.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/understanding-active-record-connection-pooling/connection-leasing-comparison.png" alt="Connection-leasing-comparison"></p>
<h2>Connection Pool Configuration Options</h2>
<p>Active Record's connection pool behavior can be customized through several
configuration options in the database.yml file:</p>
<ul>
<li><a href="https://api.rubyonrails.org/classes/ActiveRecord/DatabaseConfigurations/HashConfig.html#method-i-pool">pool</a>:
Sets the maximum number of connections the pool will maintain. The default is
tied to <code>RAILS_MAX_THREADS</code>, but you can set it to any value. There is a small
problem when you set it to <code>RAILS_MAX_THREADS</code> which we'll discuss later.</li>
<li><a href="https://api.rubyonrails.org/classes/ActiveRecord/DatabaseConfigurations/HashConfig.html#method-i-checkout_timeout">checkout timeout</a>:
Determines how long a thread will wait to get a connection before timing out.
The default is 5 seconds. If all connections are in use and a thread waits
longer than this value, an <code>ActiveRecord::ConnectionTimeoutError</code> exception
will be raised.</li>
<li><a href="https://api.rubyonrails.org/classes/ActiveRecord/DatabaseConfigurations/HashConfig.html#method-i-idle_timeout">idle timeout</a>:
Specifies how long a connection can remain idle before it's removed from the
pool. The default is 300 seconds. This helps reclaim resources from
connections that aren't being used.</li>
<li><a href="https://api.rubyonrails.org/classes/ActiveRecord/DatabaseConfigurations/HashConfig.html#method-i-reaping_frequency">reaping frequency</a>:
Controls how often the Reaper(which we'll discuss shortly) process runs to
remove dead or idle connections. The default is 60 seconds.</li>
</ul>
<h2>Active Record Connection Pool Reaper</h2>
<p>Database connections can sometimes become &quot;dead&quot; due to issues like database
restarts, network problems etc. Active Record provides Reaper to handle this.</p>
<p>The Reaper periodically checks connections in the pool and removes dead
connections as well as idle connections that have been checked out for a long
time.</p>
<p>It acts somewhat like a garbage collector for database connections. The Reaper
uses the <code>idle_timeout</code> setting to determine how long a connection can remain
idle before being removed, tracking idle time based on when connections were
last used.</p>
<p>There is another configuration option called <code>reaping_frequency</code> that controls
how often the Reaper runs to remove dead or idle connections from the pool. By
default, this is set to 60 seconds. It means the Reaper will wake up once every
minute to perform its maintenance tasks.</p>
<p>If your application is spiky and receives a lot of traffic in surges, then set
the reaping frequency and idle timeout to a lower value. This will ensure that
the reaper runs more frequently and removes idle connections more quickly,
helping to keep the connection pool healthy and responsive.</p>
<h2>Why are idle connections bad?</h2>
<p>Idle database connections can significantly impact database performance for
several interconnected reasons:</p>
<p><strong>Memory Consumption</strong>: Each database connection, even when idle, maintains its
own memory allocation. The database must reserve memory for session state,
buffers, user context, and transaction workspace. This memory remains allocated
even when the connection isn't doing any work. For example, if each connection
uses 10 MB of memory, 100 idle connections would unnecessarily consume 1 GB of
your database's memory that could otherwise be used for active queries, caching,
or other productive work.</p>
<p><strong>CPU overhead</strong>: While &quot;idle&quot; suggests no activity, the database still performs
regular maintenance work for each connection. It must monitor connection health
via keepalive checks, manage process tables etc.</p>
<p>The crucial issue is that the overhead of having idle connections scales
non-linearly. As we add more idle connections, the database spends an increasing
proportion of its CPU time just managing these connections rather than
processing actual queries. Thankfully, the reaper handles this for us.</p>
<h2>How many database connections will the web and background processes utilize at maximum?</h2>
<p>As we learned, the connection pool is managed at the process level. Each Rails
process maintains its own pool.</p>
<ol>
<li><strong>In web processes (Puma)</strong>:</li>
</ol>
<p>Each Puma process is a separate process with its own connection pool. In a
process, each thread can check out one connection. Therefore, maximum
connections needed per process equals <code>max_threads</code> setting in Puma.</p>
<ol start="2">
<li><strong>In background processes (Sidekiq)</strong>:</li>
</ol>
<p>Sidekiq runs as a separate process with its own connection pool. The Sidekiq
<code>concurrency</code> setting determines the number of threads and therefore the maximum
connections needed equals the <code>concurrency</code> value.</p>
<p><em>Note: If you're using Sidekiq swarm and running multiple Sidekiq processes,
then take that it into account.</em></p>
<p>We can calculate the total potential connections for a typical application as
shown below.</p>
<pre><code>Web connections = Number of web dynos * Number of Puma processes
                  * `max_threads` value

Background connections = Number of worker dynos * Number of Sidekiq processes
                         * Threads per process

Total number of connections = Web connections + Background connections
</code></pre>
<p>The key thing to note here is that the database needs to support at least these
many simultaneous connections.</p>
<p><em>Note that if preboot is enabled, then the maximum number of connections will be
<strong>double</strong> the above value. This is because during the release phase, there is a
small window in which both the old dynos and new dynos are running.</em></p>
<p>In Rails 7,
<a href="https://edgeapi.rubyonrails.org/classes/ActiveRecord/Relation.html#method-i-load_async"><code>load_async</code></a>
was introduced which allows us to run database queries asynchronously in a
background thread. When <code>load_async</code> is in used, the calculation for maximum
number of connections needed changes a bit. First, let's understand how
<code>load_async</code> works.</p>
<h2>How <code>load_async</code> works</h2>
<p><code>load_async</code> allows Rails to execute database queries asynchronously in
background threads. Unlike regular ActiveRecord queries which are lazily loaded,
<code>load_async</code> queries are always executed immediately in background threads and
joined to the main thread when results are needed.</p>
<p>The async executor is configured through the
<code>config.active_record.async_query_executor</code> setting. There are three possible
configurations:</p>
<ol>
<li><code>nil</code> (default): Async queries are disabled, and <code>load_async</code> will execute
queries synchronously.</li>
<li><code>:global_thread_pool</code>: Uses a single thread pool for all database
connections.</li>
<li><code>:multi_thread_pool</code>: Uses separate thread pools for each database
connection.</li>
</ol>
<p>Rails provides a configuration option named
<a href="https://guides.rubyonrails.org/configuring.html#config-active-record-global-executor-concurrency">global_executor_concurrency</a>
(default: 4) that controls how many concurrent async queries can run per
process. So, the maximum number of connections per process when <code>load_async</code> is
used.</p>
<pre><code class="language-ruby">Maximum connections per process = Process level concurrency
                                  + global_executor_concurrency + 1
</code></pre>
<p>Here Process level concurrency means <code>max_threads</code> for the Puma process and
<code>sidekiq_conurrency</code> for the Sidekiq process.</p>
<p>The &quot;+1&quot; accounts for the main control thread, which may occasionally need a
connection (e.g., during model introspection at class load time).</p>
<p>There is a nice
<a href="https://judoscale.com/tools/heroku-postgresql-connection-calculator">calculator</a>
created by the folks at <a href="https://judoscale.com/">Judoscale</a> which can be used to
calculate the maximum number of connections needed for your application.</p>
<h2>Setting Database Pool Size Configuration</h2>
<p>Our <code>database.yml</code> file has the following line.</p>
<pre><code class="language-yaml">pool: &lt;%%= ENV.fetch(&quot;RAILS_MAX_THREADS&quot;) { 5 } %&gt;
</code></pre>
<p>We know that a thread doesn't take more than one DB connection. So the maximum
number of connections needed per pool is equal to the total number of threads.
So the above configuration looks fine.</p>
<p>However this doesn't take into account whether we use <code>load_async</code> or not. If we
use <code>load_async</code>, then the number of connections needed per process will be
<code>RAILS_MAX_THREADS + global_executor_concurrency + 1</code>.</p>
<p>Do we really need to go into this much detail to determine the pool size? Turns
out there is a much easier answer.</p>
<p>Almost all database hosting providers mention the maximum number of connections
allowed in their plan. We can just set the pool config to the maximum number of
connections supported by our database plan. Let us say we have a Standard-0
database on Heroku. It supports up to 120 connections. So we can set the pool
config to 120.</p>
<pre><code class="language-yaml">pool: 120
</code></pre>
<p>We can do this because the database connections are lazily initialized in the
pool. The application doesn't create more database connections than it needs. So
we needn't be conservative here.</p>
<p>The only thing we need to ensure is that the maximum connection utilization
doesn't exceed the database plan limit. If that happens, then we have another
solution - PgBouncer.</p>
<h2>PgBouncer</h2>
<p>PgBouncer is a lightweight connection pooler for PostgreSQL. It sits between our
application(s) and our PostgreSQL database and manages a pool of database
connections.</p>
<p>While both PgBouncer and Active Record provide connection pooling, they operate
at different levels and serve different purposes.</p>
<p>Active Record connection pool operates within a single Ruby process and manages
connections for threads within the process, whereas PgBouncer is an external
connection pooler that sits between the application and the database and manages
connections across all the application processes.
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/understanding-active-record-connection-pooling/with-pg-bouncer.png" alt="With PgBouncer"></p>
<h2>The dreaded ActiveRecord::ConnectionTimeoutError</h2>
<p>This error comes up when a thread waits more than <code>checkout_timeout</code> seconds to
acquire a connection. This usually happens when the <code>pool</code> size is set to a
value less than the concurrency.</p>
<p>For example, lets say we have set the Sidekiq concurrency to 10 and pool size
to 5. If we have more than 5 threads wanting a connection at any point of time,
the threads will have to wait.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/understanding-active-record-connection-pooling/threads-waiting-for-connection.png" alt="Connection pooling"></p>
<p>What's the solution? As we discussed earlier setting the <code>pool</code> to a really high
value should fix the error in most cases.</p>
<p>Even after setting the config correctly, <code>ActiveRecord::ConnectionTimeoutError</code>
can still happen and it could be puzzling. Let is discuss a few scenarios where
this can happen.</p>
<h2>Custom code spinning up new threads and taking up connections</h2>
<pre><code class="language-ruby">class SomeService
  def process
    threads = []

    5.times do |index|
      threads &lt;&lt; Thread.new do
        ActiveRecord::Base.connection.execute(&quot;select pg_sleep(5);&quot;)
      end
    end

    threads.each(&amp;:join)
  end
end
</code></pre>
<p>Here 5 threads are spun up. Note that these threads also take up connections
from the same pool allotted to the process.</p>
<h3>Active Storage proxy mode</h3>
<p>Even if our application code is not spinning up new threads, Rails itself can
sometimes spin up additional threads. For example Active Storage configured in
<a href="https://edgeguides.rubyonrails.org/active_storage_overview.html#proxy-mode">proxy mode</a>.</p>
<p>Active Storage’s proxy controllers
<a href="https://github.com/rails/rails/blob/b97a7625970c74f2273211ccb17046049f409110/activestorage/app/controllers/active_storage/blobs/proxy_controller.rb">1</a>,
<a href="https://github.com/rails/rails/blob/b97a7625970c74f2273211ccb17046049f409110/activestorage/app/controllers/active_storage/representations/proxy_controller.rb">2</a>
generate responses as streams, which require dedicated threads for processing.</p>
<p>This means that when serving an Active Storage file through one of these proxy
controllers, Rails actually utilizes two separate threads - one for the main
request and another for the streaming process. Each of these threads requires
its own separate database connection from the ActiveRecord connection pool.</p>
<h3>Rack timeouts</h3>
<p><a href="https://github.com/zombocom/rack-timeout">rack-timeout</a> is commonly used across
Rails applications to automatically terminate long-running requests. While it
helps prevent server resources from being tied up by slow requests, it can also
cause a few issues.</p>
<p>Rack timeout uses Ruby's
<a href="https://rubyapi.org/3.4/o/thread#method-i-raise">Thread#raise</a> API to terminate
requests that exceed the configured timeout. When a timeout occurs, rack-timeout
raises a <code>Rack::Timeout::RequestTimeoutException</code> from another thread. If this
exception is raised while a thread is in the middle of database operations, it
can prevent proper cleanup of database connections.</p>
<h2>Tracking down ActiveRecord::ConnectionTimeoutErrors</h2>
<p>If we still frequently see <code>ActiveRecord::ConnectionTimeoutError</code> exceptions in
our application, we can get additional context by logging the connection pool
info to our error monitoring service. This can help identify which all threads
were holding onto the connections when the error occurred.</p>
<pre><code class="language-ruby">config.before_notify do |notice|
  if notice.error_class == &quot;ActiveRecord::ConnectionTimeoutError&quot;
    notice.context = { connection_pool_info: detailed_connection_pool_info }
  end
end

def detailed_connection_pool_info
  connection_info = {}

  ActiveRecord::Base.connection_pool.connections.each_with_index do |conn, index|
    connection_info[&quot;connection_#{index + 1}&quot;] = conn.owner ? conn.owner.inspect : &quot;[UNUSED]&quot;
  end

  connection_info[&quot;current_thread&quot;] = Thread.current.inspect
  connection_info
end
</code></pre>
<p><code>&lt;thread_obj&gt;.inspect</code> gives us the name, id and status of the thread. For
example, if one entry in the hash looks like
<code>#&lt;Thread:0x00006a42eca73ba0@puma srv tp 002 /app/.../gems/puma-6.2.2/lib/puma/thread_pool.rb:106 sleep_forever&gt;</code>
then it means that the connection is taken up by a Puma thread.</p>
<h2>Monitoring Active Record Connection Pool Stats</h2>
<p>If we want to monitor Active Record Connection Pool stats, then periodically we
need to send the stats to a service provider which can display the data
graphically. For periodically checking the stat, we are using
<a href="https://github.com/jmettraux/rufus-scheduler">rufus-scheduler</a> gem. For
collecting the data and showing the data we are using NewRelic but you can use
any APM of your choice. We have configured to send the pool stat every 15
seconds.</p>
<p><a href="https://gist.github.com/vishnu-m/8cfae21cac385aa07819c8805e491872">Here</a> is the
gist which collects and sends data.</p>
<p><em>This was Part 5 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>. If any part of the
blog is not clear to you then please write to us at
<a href="https://www.linkedin.com/company/bigbinary">LinkedIn</a>,
<a href="https://twitter.com/bigbinary">Twitter</a> or
<a href="https://bigbinary.com/contact">BigBinary website</a>.</em></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Finding the ideal threads per process with GVL tooling]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/tuning-puma-max-threads-configuration-with-gvl-instrumentation"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/tuning_puma_max_threads_configuration_with_gvl_instrumentation.jpg"/>
      <id>https://www.bigbinary.com/blog/tuning-puma-max-threads-configuration-with-gvl-instrumentation</id>
      <published>2025-05-06T00:00:00.000Z</published>
      <updated>2025-05-06T00:00:00.000Z</updated>
      <author>
        <name>Vishnu M</name>
        <uri>https://www.bigbinary.com/blog/authors/vishnu-m</uri>
      </author>
      <category term="Rails"/>
      <category term="Puma"/>
      <category term="Ruby"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/tuning_puma_max_threads_configuration_with_gvl_instrumentation.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[This is Part 4 of our blog series on scaling Rails applications. In part 1 we saw how to find ideal number of processes for our Rails application. In part 3, we learned about Amdahl's law, which...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/tuning-puma-max-threads-configuration-with-gvl-instrumentation"><![CDATA[<p><em>This is Part 4 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>.</em></p>
<p>In
<a href="https://bigbinary.com/blog/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance">part 1</a>
we saw how to find ideal number of processes for our Rails application.</p>
<p>In
<a href="https://bigbinary.com/blog/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency">part 3</a>,
we learned about Amdahl's law, which helps us find the ideal number of threads
theoretically.</p>
<p>In this blog, we'll run a bunch of tests on our real production application to
see what the actual number of threads should be for each process.</p>
<p>In
<a href="https://bigbinary.com/blog/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance">part 1</a>
we discussed the presence of GVL and the concept of thread switching. Based on
the GVL's interaction, a thread can be in one of these three states.</p>
<ol>
<li><strong>Running</strong>: The thread has the GVL and is executing Ruby code.</li>
<li><strong>Idle</strong>: The thread doesn't want the GVL because it is performing I/O
operations.</li>
<li><strong>Stalled</strong>: The thread wants the GVL and is waiting for it in the GVL wait
queue.</li>
</ol>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/tuning-puma-max-threads-configuration-with-gvl-instrumentation/thread-states.png" alt="Thread states"></p>
<p>Based on the above diagram, we can approximately equate <code>idle time</code> to
<code>I/O time</code>.</p>
<h2>GVL instrumentation using perfm</h2>
<p>Thanks to Jean Boussier's work on the
<a href="https://bugs.ruby-lang.org/issues/18339">GVL instrumentation API</a> and John
Hawthorn's work on <a href="https://github.com/jhawthorn/gvl_timing">gvl_timing</a>, we can
now measure the time a thread spends in each of these states for apps running on
Ruby 3.2 or higher.</p>
<p>Using the great work done by these folks, we have created
<a href="https://github.com/bigbinary/perfm">perfm</a>, to help us figure out the ideal
number of Puma threads based on the application's workload.</p>
<p>Perfm inserts a Rack middleware to our Rails application. This middleware
instruments the GVL, collects the required metrics and stores them in a table.
It also has a <code>Perfm::GvlMetricsAnalyzer</code> class which can be used to generate a
report on the data collected.</p>
<h3>Using perfm to measure the application's I/O percentage</h3>
<p>To use perfm, we need to add the following line to our Gemfile.</p>
<pre><code class="language-ruby">gem 'perfm'
</code></pre>
<p>We'll run <code>bin/rails generate perfm:install</code>. This will generate the migration
to create <code>perfm_gvl_metrics</code> which will be used to store request-level metrics.</p>
<p>Now we'll create an initializer <code>config/initializers/perfm.rb</code>.</p>
<pre><code class="language-ruby">Perfm.configure do |config|
  config.enabled = true
  config.monitor_gvl = true
  config.storage = :local
end

Perfm.setup!
</code></pre>
<p>After deploying the code to production, we need to collect around 20K requests
as that will give us a fair number of data points to analyze. The GVL monitoring
can be disabled after that by setting <code>config.monitor_gvl</code> to <code>false</code> so that
the table doesn't keep growing.</p>
<p>After collecting the request data, now it's time to analyze it.</p>
<p>Run the following code in the Rails console.</p>
<pre><code class="language-ruby">irb(main):001* gvl_metrics_analyzer = Perfm::GvlMetricsAnalyzer.new(
irb(main):002*   start_time: 2.days.ago, # configure this
irb(main):003*   end_time: Time.current
irb(main):004&gt; )
irb(main):005&gt;
irb(main):006&gt; results = gvl_metrics_analyzer.analyze
irb(main):007&gt; io_percentage = results[:summary][:total_io_percentage]
=&gt; 45.09
</code></pre>
<p>This will give us the percentage of time spent doing I/O. We ran it in our
<a href="https://neeto.com/cal">NeetoCal</a> production application and we got a value of
45%.</p>
<p>As we discussed in
<a href="https://www.bigbinary.com/blog/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency">part 3</a>,
Amdahl's law gives us a theoretical maximum speedup based on the parallelizable
portion of our workload. The formula is given below.
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/tuning-puma-max-threads-configuration-with-gvl-instrumentation/amdahls-law.png" alt="Amdahl's law formula"></p>
<p>Where:</p>
<ul>
<li><code>p</code> is the portion that can be parallelized (in our case, it's 0.45)</li>
<li><code>N</code> is the number of threads</li>
<li><code>(1 - p)</code> is the portion that must run sequentially (in our case, it's 0.55)</li>
</ul>
<p>Let's calculate the theoretical speedup for different numbers of threads with p
= 0.45:</p>
<table>
<thead>
<tr>
<th>Thread Count (N)</th>
<th>Speedup</th>
<th>% Improvement from previous run</th>
</tr>
</thead>
<tbody>
<tr>
<td>1</td>
<td>1.00</td>
<td>-</td>
</tr>
<tr>
<td>2</td>
<td>1.29</td>
<td>29%</td>
</tr>
<tr>
<td>3</td>
<td>1.43</td>
<td>11%</td>
</tr>
<tr>
<td>4</td>
<td>1.52</td>
<td>6%</td>
</tr>
<tr>
<td>5</td>
<td>1.57</td>
<td>3%</td>
</tr>
<tr>
<td>6</td>
<td>1.60</td>
<td>2%</td>
</tr>
<tr>
<td>8</td>
<td>1.64</td>
<td>&lt;2%</td>
</tr>
<tr>
<td>16</td>
<td>1.69</td>
<td>&lt;1%</td>
</tr>
<tr>
<td>∞</td>
<td>1.82</td>
<td>-</td>
</tr>
</tbody>
</table>
<p>We can see that after 4 threads, the percentage improvement drops below 5%. This
means that 4 is a reasonable value for <code>max_threads</code>. We can set the value of
<code>RAILS_MAX_THREADS</code> to 4.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/tuning-puma-max-threads-configuration-with-gvl-instrumentation/speedup-vs-thread-count.png" alt="Speedup V/S Number of threads"></p>
<p>Looking at the table, adding a 5th thread would only give us a 3% performance
improvement, which may not justify the additional memory usage and potential GVL
contention.</p>
<p>We have also created a small application to help visualize and find the ideal
number of threads when the I/O percentage is provided as input.
<a href="https://v0-single-page-application-lake.vercel.app/">Here</a> is the link to the
app.</p>
<h2>Validate thread count using stall time</h2>
<p>This value of <code>4</code> we got theoretically by using Amdahl's law. Now it's time to
put this law to test. Let's see in the real world if the value of <code>4</code> is the
correct value or not.</p>
<p>What we need to do is start with <code>RAILS_MAX_THREADS</code> env variable (Puma
<code>max_threads</code>) set to <code>4</code> and then check if this value provides minimal GVL
contention. By GVL contention, we mean the amount of time a thread spends
waiting for the GVL i.e the stall time.</p>
<p>If the stall time is high, that means the set thread count is high. We don't
want our request threads to spend their time doing nothing causing latency
spikes.<code>75ms</code> is an acceptable value for stall time. The lesser the better of
course.</p>
<p>The average stall time can be found in the perfm analyzer results. As we
mentioned earlier, we had collected data for <a href="https://neeto.com/cal">NeetoCal</a>.
Now let's find the average stall time.</p>
<pre><code class="language-ruby">irb(main):001* gvl_metrics_analyzer = Perfm::GvlMetricsAnalyzer.new(
irb(main):002*   start_time: 2.days.ago,
irb(main):003*   end_time: Time.current,
irb(main):004*   puma_max_threads: 4
irb(main):005&gt; )
irb(main):006&gt; results = gvl_metrics_analyzer.analyze
irb(main):007&gt; avg_stall_ms = results[:summary][:average_stall_ms]
=&gt; 110.24
</code></pre>
<p>The stall time seems a bit high. Let us decrease the <code>RAILS_MAX_THREADS</code> value
by 1 and collect a few data points(i.e around 20K requests). Now the value of
<code>RAILS_MAX_THREADS</code> will be <code>3</code>. This process has to be repeated until we find
the value for which the average stall time is less than <code>75ms</code>.</p>
<pre><code class="language-ruby">irb(main):001* gvl_metrics_analyzer = Perfm::GvlMetricsAnalyzer.new(
irb(main):002*   start_time: 2.days.ago,
irb(main):003*   end_time: Time.current,
irb(main):004*   puma_max_threads: 3
irb(main):005&gt; )
irb(main):006&gt; results = gvl_metrics_analyzer.analyze
irb(main):007&gt; avg_stall_ms = results[:summary][:average_stall_ms]
=&gt; 79.38
</code></pre>
<p>Now the output is closer to <code>75 ms</code>.</p>
<p>Hence we can finalize on the value 3 as the value for <code>RAILS_MAX_THREADS</code>. If we
decrease the value again by one i.e set it to 2, the stall time will decrease
but we're limiting the concurrency of our application. It is a trade-off.</p>
<p>Remember that our goal is to maximize concurrency while minimizing GVL
contention. But if our app spends a lot of time doing I/O - for instance, if we
have a proxy application that makes a lot of external API calls directly from
the controller, then we can switch the app server to
<a href="https://github.com/socketry/falcon">Falcon</a>. Falcon is tailor-made for such use
cases.</p>
<p>Broadly speaking, one should take care of the following items to ensure that the
time spent by the request doing I/O is minimal.</p>
<ul>
<li>Remove N+1 queries</li>
<li>Remove long-running queries</li>
<li>Move inline third party API calls to background job processor</li>
<li>Move heavy computational stuff to background job processor</li>
</ul>
<p>For a finely optimized Rails application, the <code>max_threads</code> value will be
around 3. That's why the default value of <code>max_threads</code> for Rails applications
is <code>3</code> now. This has been decided after a lot of discussion
<a href="https://github.com/rails/rails/issues/50450">here</a>. We recommend you read the
whole discussion. It is very interesting.</p>
<p><em>This was Part 4 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>. If any part of the
blog is not clear to you then please write to us at
<a href="https://www.linkedin.com/company/bigbinary">LinkedIn</a>,
<a href="https://twitter.com/bigbinary">Twitter</a> or
<a href="https://bigbinary.com/contact">BigBinary website</a>.</em></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Amdahl's Law: the relationship of speedup and concurrency]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/amdahls_law_the_theoretical_relationship_between_speedup_and_concurrency.jpg"/>
      <id>https://www.bigbinary.com/blog/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency</id>
      <published>2025-04-29T00:00:00.000Z</published>
      <updated>2025-04-29T00:00:00.000Z</updated>
      <author>
        <name>Vishnu M</name>
        <uri>https://www.bigbinary.com/blog/authors/vishnu-m</uri>
      </author>
      <category term="Rails"/>
      <category term="Puma"/>
      <category term="Ruby"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/amdahls_law_the_theoretical_relationship_between_speedup_and_concurrency.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[This is Part 3 of our blog series on scaling Rails applications. We have only two parameters to work with if we want to fine-tune our Puma configuration. 1. The number of processes. 2. The number of...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency"><![CDATA[<p><em>This is Part 3 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>.</em></p>
<p>We have only two parameters to work with if we want to fine-tune our Puma
configuration.</p>
<ol>
<li>The number of processes.</li>
<li>The number of threads each process can have.</li>
</ol>
<p>In
<a href="https://bigbinary.com/blog/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance">part 1</a>
of <a href="https://www.bigbinary.com/blog/scaling-rails-series">Scaling Rails series</a>,
we saw what the number of processes should be. Now let's look at what the number
of threads in each process should be.</p>
<h2>Amdahl's law</h2>
<p>Each application has a few things which must be performed in &quot;serial order&quot; and
a few things which can be &quot;parallelized&quot;. If we draw a diagram, then this is
what it will look like.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency/amdahls-gantt-chart1.png" alt="Amdahl's law Gantt chart"></p>
<p>Let's say that <code>T1'</code> and <code>T2'</code> are the enhanced times. These are the times the
application would take after the enhancement has been applied. In this case the
enhancement will come in the form of increasing the threads in a process.</p>
<p><code>T1'</code> will be same as <code>T1</code> since it's the serial part. <code>T2'</code> will be lower than
<code>T2</code> since we will parallelize some of the code. After the parallelization is
done, the enhanced version would look something like this.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency/amdahls-gantt-chart.png" alt="Amdahl's law Gantt chart"></p>
<p>It's clear that the serial part (T1) will limit how much speedup we can get no
matter how much we parallelize <code>T2</code>.</p>
<p>Computer scientist <a href="https://en.wikipedia.org/wiki/Gene_Amdahl">Gene Amdahl</a> came
up with <a href="https://en.wikipedia.org/wiki/Amdahl%27s_law">Amdahl's law</a> which gives
the mathematical value for the overall speedup that can be achieved.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency/amdahls-law.png" alt="Amdahl's law picture"></p>
<p>I made a video explaining how this formula came about.</p>
<p><a href="https://www.youtube.com/watch?v=2hYs2X6Fb1M"><img src="https://img.youtube.com/vi/2hYs2X6Fb1M/hqdefault.jpg" alt="Watch on YouTube" width="480" height="360"></a><br><a href="https://www.youtube.com/watch?v=2hYs2X6Fb1M">Watch on YouTube</a></p>
<p><em>Amdahl's law states that the theoretical speedup gained from parallelization is
directly determined by the fraction of sequential code in the program.</em></p>
<p>Now, let's see how we can use Amdahl's law to determine the ideal number of
threads.</p>
<p>The parallelizable portion in this case is the portion of the application that
spends time doing I/O. The non-parallelizable portion is the time spent by the
application executing Ruby code. Remember that because of GVL, within a process,
only one thread has access to CPU at any point of time.</p>
<p>Now we need to know what percentage of time our app spends doing I/O. This will
be the value <code>p</code> as per the video.</p>
<p>Later in this series, we'll show you how to calculate what percentage of the
time the Rails application is spending doing I/O. For this blog let's assume
that our application spends 37% of the time doing I/O i.e the value of <code>p</code> is
<strong>0.37</strong>.</p>
<p>Let's calculate how much speedup we will get if we use one thread(n is 1). Now
let's change n to 2 and get the speedup value. Similarly, we bump up n all the
way to 15 and we record the speedup.</p>
<p>Now let's draw a graph between the overall speedup and the number of threads.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency/speedup-vs-thread-count.png" alt="Speedup V/S Number of threads"></p>
<p>From the graph, it can be seen that the speedup increases as the number of
threads increases, but the rate of increase diminishes as more threads are
added. This is because the serial portion remains constant and is unaffected by
the increase in threads.</p>
<table>
<thead>
<tr>
<th>Threads(N)</th>
<th>Speedup(S)</th>
<th>% Improvement from previous run</th>
</tr>
</thead>
<tbody>
<tr>
<td>1</td>
<td>1.000</td>
<td>-</td>
</tr>
<tr>
<td>2</td>
<td>1.227</td>
<td>22.7%</td>
</tr>
<tr>
<td>3</td>
<td>1.366</td>
<td>11.3%</td>
</tr>
<tr>
<td>4</td>
<td>1.456</td>
<td>6.6%</td>
</tr>
<tr>
<td>5</td>
<td>1.518</td>
<td>4.2%</td>
</tr>
<tr>
<td>6</td>
<td>1.562</td>
<td>2.9%</td>
</tr>
<tr>
<td>7</td>
<td>1.594</td>
<td>2.0%</td>
</tr>
<tr>
<td>8</td>
<td>1.619</td>
<td>1.6%</td>
</tr>
</tbody>
</table>
<p>By examining the graph we can observe that the speedup gain from increasing
threads seem significant up to 4 threads, after which the incremental gain in
speedup starts to plateau.</p>
<p>Remember that these are theoretical maximums based on Amdahl's law. In practice,
we need to use fewer threads as adding more threads can cause an increase in
memory usage and GVL contention, thereby causing latency spikes.</p>
<p>It's obvious that if we add more threads then more requests can be handled by
Puma concurrently. What it means is that requests will be waiting for lesser
time at the load balancer layer as there are more Puma threads waiting to pick
up the request for processing. But in part 1, we saw that just because we have
more threads, it doesn't mean things will move faster. More threads might cause
other threads to wait for the GVL.</p>
<p>There is no point in accepting requests if our web server can't respond to it
promptly. Whereas, if the <code>max_threads</code> value is set to a lower value, requests
will queue up at the Load Balancer layer which is better than overwhelming the
application server.</p>
<p>If more and more requests are waiting at the load balancer level, then the
request queue time will shoot up. The right way to solve this problem is to add
more Puma processes. It is advised to increase the capacity of the Puma server
by adding more processes rather than increasing the number of threads.</p>
<p><a href="https://gist.github.com/neerajsingh0101/35e5307fb197b08ac6a62aa725cafec6">Here</a>
is a middleware that can be used to track the request queue time. This code is
taken from
<a href="https://github.com/judoscale/judoscale-ruby/blob/15a4e9bd59734defb76656b59cba067b60aed473/judoscale-ruby/lib/judoscale/request_metrics.rb">judoscale</a>.</p>
<p>Note that <strong>Request Queue Time</strong> is the time spent waiting before the request is
picked up for processing.</p>
<p>This middleware will only work if the load balancer is adding the
<code>HTTP_REQUEST_START</code> header. Heroku automatically adds this header.</p>
<p>Now we need to use this middleware and for that open <code>config/application.rb</code>
file and we need to add the following line.</p>
<pre><code class="language-ruby">config.middleware.use RequestQueueTimeMiddleware
</code></pre>
<p><em>This was Part 3 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>. If any part of the
blog is not clear to you then please write to us at
<a href="https://www.linkedin.com/company/bigbinary">LinkedIn</a>,
<a href="https://twitter.com/bigbinary">Twitter</a> or
<a href="https://bigbinary.com/contact">BigBinary website</a>.</em></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[The GVL in Ruby and its impact on scaling Rails]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/gvl-in-ruby-and-its-impact-in-scaling-rails-applications"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/gvl_in_ruby_and_its_impact_in_scaling_rails_applications.jpg"/>
      <id>https://www.bigbinary.com/blog/gvl-in-ruby-and-its-impact-in-scaling-rails-applications</id>
      <published>2025-04-24T00:00:00.000Z</published>
      <updated>2025-04-24T00:00:00.000Z</updated>
      <author>
        <name>Vishnu M</name>
        <uri>https://www.bigbinary.com/blog/authors/vishnu-m</uri>
      </author>
      <category term="Rails"/>
      <category term="Puma"/>
      <category term="Ruby"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/gvl_in_ruby_and_its_impact_in_scaling_rails_applications.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[This is Part 2 of our blog series on scaling Rails applications. Let's start from the basics. Let's see how a standard web application mostly behaves. Web applications and CPU usage Code in a web...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/gvl-in-ruby-and-its-impact-in-scaling-rails-applications"><![CDATA[<p><em>This is Part 2 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>.</em></p>
<p>Let's start from the basics. Let's see how a standard web application mostly
behaves.</p>
<h2>Web applications and CPU usage</h2>
<p>Code in a web application typically works like this.</p>
<ul>
<li>Do some data manipulation.</li>
<li>Make a few database calls.</li>
<li>Do more calculations.</li>
<li>Make some network calls.</li>
<li>Do more calculations.</li>
</ul>
<p>Visually, it'll look something like this.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/work-done-in-processing-web-request.png" alt="Three threads 1 process &amp; 2 cores"></p>
<p>CPU work includes operations like view rendering, string manipulation, any kind
of business logic processing etc. In short, anything that involves Ruby code
execution can be considered CPU work. For the rest of the work, like database
calls, network call etc. CPU is idle. Another way of looking at when the CPU is
working and when it's idle is this picture.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/cpu-working-idle.png" alt="CPU sometimes working &amp; sometimes idle"></p>
<p>When a program is using CPU, then that portion of the code is called <strong>CPU
bound</strong> and when program is not using CPU, then that portion of the code is
called <strong>IO bound</strong>.</p>
<h3>CPU bound or IO bound</h3>
<p>Let us understand what <strong>CPU bound</strong> truly means. Consider the following piece
of code.</p>
<pre><code class="language-ruby">10.times do
  Net::HTTP.get(URI.parse(&quot;https://bigbinary.com&quot;))
end
</code></pre>
<p>In the above code, we are hitting the BigBinary website 10 times sequentially.
Running the above code takes time because making a network connection is a
time-consuming process.</p>
<p>Let's assume the code above takes 10 seconds to finish. We want the code to run
faster. So we bought a better CPU for the server. Do you think now the code will
run faster?</p>
<p>It will not. That's because the above code is <strong>not</strong> CPU bound. CPU is not the
limiting factor in this case. This code is I/O bound.</p>
<p>A program is <strong>CPU bound</strong> if the program will run faster if the CPU were
faster.</p>
<p>A program is <strong>I/O bound</strong> if the program will run faster if the I/O operations
were faster.</p>
<p>Some of the examples of I/O bound operations are:</p>
<ul>
<li><strong>making database calls</strong>: reading data from tables, creating new tables etc.</li>
<li><strong>making network calls</strong>: reading data from a website, sending emails etc.</li>
<li><strong>dealing with file systems</strong>: reading files from the file system.</li>
</ul>
<p>Previously, we saw that our CPU was idle sometimes. Now we know that the
technical term for that idleness is <strong>IO bound</strong> let's update the picture.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/cpu-bound-io-bound.png" alt="CPU bound and IO bound"></p>
<p>When a program is I/O bound, the CPU is not doing anything. We don't want
precious CPU cycles to be wasted. So what can we do so that the CPU is fully
utilized?</p>
<p>So far we have been dealing with only one thread. We can increase the number of
threads in the process. In this way, whenever the CPU is done executing CPU
bound code of one thread and that thread is doing an I/O bound operation, then
the CPU can switch and handle the work from another thread. This will ensure
that the CPU is efficiently utilized. We will look at how the switching between
threads works a bit later in the article.</p>
<h2>Concurrency vs Parallelism</h2>
<p>Concurrency and parallelism sound similar, and in your daily life, you can
substitute one for another, and you will be fine. However, from the computer
engineering point of view, there is a difference between work happening
concurrently and work happening in parallel.</p>
<p>Imagine a person who has to respond to 100 emails and 100 Twitter messages. The
person can reply to an email and then reply to a Twitter message, then do the
same all over again: reply to an email and reply to a Twitter message.</p>
<p>The boss will see the count of pending emails and Twitter messages go down from
100 to 99 to 98. The boss might think that the work is happening in &quot;parallel.&quot;
But that's not true.</p>
<p>Technically, the work is happening concurrently. For a system to be parallel, it
should have two or more actions executed simultaneously. In this case, at any
given moment, the person was either responding to email or responding to
Twitter.</p>
<p>Another way to look at it is that <strong>Concurrency is about dealing</strong> with lots of
things at the same time. <strong>Parallelism is about doing</strong> lots of things at the
same time.</p>
<p>If you find it hard to remember which one is which then remember that
<strong>concurrency</strong> starts with the word <strong>con</strong>. Concurrency is the <em>conman</em>. It's
pretending to be doing things &quot;in parallel,&quot; but it's only doing things
concurrently.</p>
<h2>Understanding GVL in Ruby</h2>
<p>GVL (Global VM Lock) in Ruby is a mechanism that prevents multiple threads from
executing Ruby code simultaneously. The GVL acts like a traffic light in a
one-lane bridge. Even if multiple cars (threads) want to cross the bridge at the
same time, the traffic light (GVL) allows only one car to pass at a time. Only
when one car has made it safely to the other end, the second car is allowed by
the traffic light(GVL) to start.</p>
<p>Ruby's memory management(like garbage collection) and some other parts of Ruby
are not thread-safe. Hence, GVL ensures that only one thread runs Ruby code at a
time to avoid any data corruption.</p>
<p>When a thread &quot;holds the GVL&quot;, it has exclusive access to modify the VM
structures.</p>
<p>It's important to note that GVL is there to protect how Ruby works and manages
Ruby's internal VM state. GVL is not there to protect our application code. It's
worth repeating. The presence of GVL doesn't mean that we can write our code in
a thread unsafe manner and expect Ruby to take care of all threading issues in
our code.</p>
<p>Ruby offers tools like <a href="https://ruby-doc.com/3.3.6/Thread/Mutex.html">Mutex</a> and
<a href="https://github.com/ruby-concurrency/concurrent-ruby">concurrent-ruby</a> gem to
manage concurrent code. For example, the following
code(<a href="https://www.youtube.com/watch?v=rI4XlFvMNEw&amp;t=575s">source</a>) is not thread
safe and the GVL will not protect our code from race conditions.</p>
<pre><code class="language-ruby">from = 100_000_000
to = 0

50.times.map do
  Thread.new do
    while from &gt; 0
      from -= 1
      to += 1
    end
  end
end.map(&amp;:join)

puts &quot;to = #{to}&quot;
</code></pre>
<p>When we run this code, we might expect the result to always equal 100,000,000
since we're just moving numbers from <code>from</code> to <code>to</code>. However, if we run it
multiple times, we'll get different results.</p>
<p>This happens because multiple threads are trying to modify the same variables
(from and to) simultaneously without any synchronization. This is called race
condition and it happens because the operation <code>to += 1</code> and <code>from -= 1</code> are
non-atomic at the CPU-level. In simpler terms operation <code>to += 1</code> can be written
as three CPU-level operations.</p>
<ol>
<li>Read current value of <code>to</code>.</li>
<li>Add 1 to it.</li>
<li>Store the result back to <code>to</code>.</li>
</ol>
<p>To fix this race condition the above code can be re-written using a
<a href="https://docs.ruby-lang.org/en/master/Thread/Mutex.html">Mutex</a>.</p>
<pre><code class="language-rb">from = 100_000_000
to = 0
lock = Mutex.new

50.times.map do
  Thread.new do
    while from &gt; 0
      lock.synchronize do
        if from &gt; 0
          from -= 1
          to += 1
        end
      end
    end
  end
end.map(&amp;:join)

puts &quot;to = #{to}&quot;
</code></pre>
<p>It's worth nothing that Ruby implementations like JRuby and TruffleRuby don't
have a GVL.</p>
<h2>GVL dictates how many processes we will need</h2>
<p>Let's say that we deploy the production app to AWS's EC2's <code>t2.medium</code> machine.
This machine has 2 vCPU as we can see from this chart.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/t2-medium.png" alt="T2 medium"></p>
<p>Without going into CPU vs vCPU discussion, let's keep things simple and assume
that the AWS machine has two cores. So we have deployed our code on a machine
with two cores but we have only one process running in production. No worries.
We have three threads. So three threads can share two cores. You would think
that something like this should be possible.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/puma-one-process-2-cores.png" alt="Three threads 1 process &amp; 2 cores"></p>
<p>But it's not possible. Ruby doesn't allow it.</p>
<p>Currently, it's not possible because Thread 1 and Thread 2 belong to the same
process. This is because of the <strong>Global VM Lock (GVL)</strong>.</p>
<p>The GVL ensures that only one thread can execute CPU bound code at a time within
a single Ruby process. The important thing to note here is that this lock is
<strong>only for the CPU bound code</strong> and <strong>only for the same process</strong>.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/gvl-lock.png" alt="Single Process Multi Core"></p>
<p>In the above case, all three threads can do DB operations in parallel. But two
threads of the same process can't be doing CPU operations in parallel.</p>
<p>We can see that &quot;Thread 1&quot; is using Core 1. Core 2 is available but &quot;Thread 2&quot;
can't use Core 2. GVL won't allow it.</p>
<p>Again, let's revisit what GVL does. For the CPU bound code GVL will ensure that
only one thread from a process can access CPU.</p>
<p>So now the question is how do we utilize Core 2. Well, the GVL is applied at a
process level. Threads of the same process are not allowed to do CPU operations
in parallel. Hence, the solution is to have more processes.</p>
<p>To have two Puma processes we need to set the value of env variable
<code>WEB_CONCURRENCY</code> to 2 and reboot Puma.</p>
<pre><code class="language-ruby">WEB_CONCURRENCY=2 bundle exec rails s
</code></pre>
<p>Now we have two processes. Now both Core 1 and Core 2 are being utilized.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/gvl-two-process.png" alt="Multi Process Multi Core"></p>
<p>What if the machine has 5 cores. Do we need 5 processes?</p>
<p>Yes. In that case, we will need to have 5 processes to utilize all the cores.</p>
<p>Therefore for achieving maximum utilization, the rule of thumb is that the
number of processes i.e <code>WEB_CONCURRENCY</code> should be set to the number of cores
available in the machine.</p>
<h2>Thread switching</h2>
<p>Now let's see how switching between threads happens in a multi-threaded
environment. Note that the number of threads is 2 in this case.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/thread1-thread2.png" alt="CPU bound and IO bound"></p>
<p>As we can see, the CPU switches between Thread 1 and Thread 2 whenever it's
idle. This is great. We don't waste CPU cycles now, as we saw in the
single-threaded case. But the switching logic is much more nuanced than what is
shown in the picture.</p>
<p>Ruby manages multiple threads at two levels: the operating system level and the
Ruby level. When we create threads in Ruby, they are &quot;native threads&quot; - meaning
they are real threads that the operating system (OS) can see and manage.</p>
<p>All operating systems have a component called the scheduler. In Linux, it's
called the
<a href="https://en.wikipedia.org/wiki/Completely_Fair_Scheduler">Completely Fair Scheduler</a>
or CFS. This scheduler decides which thread gets to use the CPU and for how
long. However, Ruby adds its own layer of control through the Global VM Lock
(GVL).</p>
<p>In Ruby a thread can execute CPU bound code only if it holds the GVL. The Ruby
VM makes sure that a thread can hold the GVL for up to 100 milliseconds. After
that the thread will be forced to release GVL to another thread if there is
another thread waiting to execute CPU bound code. This ensures that the waiting
Ruby threads are not
<a href="https://en.wikipedia.org/wiki/Starvation_(computer_science)">starved</a>.</p>
<p>When a thread is executing CPU-bound code, it will continue until either:</p>
<ol>
<li>It completes its CPU-bound work.</li>
<li>It hits an I/O operation (which automatically releases the GVL).</li>
<li>It reaches the limit of 100ms.</li>
</ol>
<p>When a thread starts running, the Ruby VM uses a background timer thread at the
VM level that checks every 10ms how long the current Ruby thread has been
running. If the thread has been running longer than the thread quantum (100ms by
default), the Ruby VM takes back the GVL from the active thread and gives it to
the next thread waiting in the queue. When a thread gives up the GVL (either
voluntarily or is forced to give up), the thread goes to the back of the queue.</p>
<p>The default thread quantum is 100ms and starting from Ruby 3.3, it can be
configured using the <code>RUBY_THREAD_TIMESLICE</code> environment variable.
<a href="https://bugs.ruby-lang.org/issues/20861">Here</a> is the link to the discussion.
This environment variable allows fine-tuning of thread scheduling behavior - a
smaller quantum means more frequent thread switches, while a larger quantum
means fewer switches.</p>
<p>Let's see what happens when we have two threads.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/multi-threaded.png" alt="CPU bound and IO bound"></p>
<ol>
<li>T1 completes quantum limit of 100ms and gives up the GVL to T2.</li>
<li>T2 completes 50ms of CPU work and voluntarily gives up the GVL to do I/O.</li>
<li>T1 completes 75 ms of CPU work and voluntarily gives the GVL to do I/O.</li>
<li>Both T1 and T2 are doing I/O and doesn't want the GVL.</li>
</ol>
<p>It means that Thread 2 would be a lot faster if it had more access to CPU. To
make CPU instantly available, we can have lesser number of threads CPU has to
handle. But we need to play a balancing game. If the CPU is idle then we are
paying for the processing cost for no reason. If the CPU is extremely busy then
that means requests will take longer to process.</p>
<h2>Thread switching can lead to misleading data</h2>
<p>Let's take a look at a simple code given below. This code is taken from
<a href="https://byroot.github.io/ruby/performance/2025/01/23/the-mythical-io-bound-rails-app.html">a blog</a>
by <a href="https://x.com/_byroot">Jean Boussier</a>.</p>
<pre><code>start = Time.now
database_connection.execute(&quot;SELECT ...&quot;)
query_duration = (Time.now - start) * 1000.0
puts &quot;Query took: #{query_duration.round(2)}ms&quot;
</code></pre>
<p>The code looks simple. If the result is say <code>Query took: 80ms</code> then you would
think that the query actually took <code>80ms</code>. But now we know two things</p>
<ul>
<li>Executing database query is an IO operation (IO bound)</li>
<li>Once the IO bound operation is done then the thread might not immediately get
hold of the GVL to execute CPU bound code.</li>
</ul>
<p>Think about it. What if the query took only <code>10ms</code> and the rest of the <code>70ms</code>
The thread was waiting for the CPU because of the GVL. The only way to know
which portion took how much time is by instrumenting the GVL.</p>
<h2>Visualizing the effect of the GVL</h2>
<p>To better understand the effect of multiple threads when it comes to Ruby's
performance, let's do a quick test. We'll start with a <strong>cpu_intensive</strong> method
that performs pure arithmetic operations in nested loops, creating a workload
that is heavily CPU dependent.</p>
<p><a href="https://gist.github.com/neerajsingh0101/de84bf200fae4e2003205ed81fcd9d7f">Here</a>
is the code.</p>
<p>Running this script produced the following output:</p>
<pre><code class="language-ruby">Running demonstrations with GVL tracing...

Starting demo with 1 threads doing CPU-bound work
Time elapsed: 7.4921 seconds

Starting demo with 3 threads doing CPU-bound work
Time elapsed: 7.8146 seconds
</code></pre>
<p>From the output, we can see that for CPU-bound work, a single thread performed
better. Why? Let's visualize the result with the help of the traces generated in
the above script using the <a href="https://github.com/ivoanjo/gvl-tracing">gvl-tracing</a>
gem. The trace files can be visualized using
<a href="https://ui.perfetto.dev/">Perfetto</a>, which provides a timeline view showing how
threads interact with the GVL.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/cpu-single-multi.webp" alt="Single and multi threads CPU bound"></p>
<p>We can see above that in the case of CPU-bound work if we have a single thread
then it's not waiting for GVL. However, if we have three threads then each
thread is waiting for GVL multiple times.</p>
<h3>Understanding the advantage of multiple threads in mixed workloads</h3>
<p>Now let's look at mixed workloads in single-threaded and multi-threaded
environment. We'll use a separate script with a <strong>mixed_workload</strong> method that
combines CPU-bound work with I/O operations. We use <code>IO.select</code> with blocking
behavior to simulate I/O operations. This creates actual I/O blocking that
releases the GVL and shows as &quot;waiting&quot; in the GVL trace, accurately
representing real-world I/O operations like database queries.</p>
<p><a href="https://gist.github.com/neerajsingh0101/af1eb90a79c7da429d4287528d7bb788">Here</a>
is the code for the mixed workload test.</p>
<p>Running this script with 1 thread and 3 threads produced the following output:</p>
<pre><code class="language-ruby">Running demonstrations with GVL tracing...

Starting demo with 1 thread doing Mixed I/O and CPU work
Time elapsed: 9.32 seconds

Starting demo with 3 threads doing Mixed I/O and CPU work
Time elapsed: 6.1344 seconds
</code></pre>
<p>The key advantage of multiple threads in mixed workloads lies in how the GVL is
managed during I/O operations. When a thread encounters an I/O operation (like a
database query, network call, or file read), it voluntarily releases the GVL.
This is fundamentally different from CPU-bound work, where threads compete for
the GVL and one thread must wait for another to finish or reach the 100ms
quantum limit.</p>
<p>During I/O operations, the thread is essentially blocked waiting for an external
resource (database, network, disk). While waiting, the thread doesn't need the
GVL because it's not executing Ruby code. This creates an opportunity for other
threads to acquire the GVL and do useful CPU work. The result is that CPU cycles
that would otherwise be wasted during I/O waits are now being utilized
productively by other threads.</p>
<p>Let's visualize this with the single-threaded case first:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/mixed-single.png" alt="Single thread mixed workload"></p>
<p>In the single-threaded case, the threads wait for I/O operations to complete.
During these I/O waits, the CPU sits idle. The thread performs some CPU work,
then waits for I/O, then does more CPU work, then waits for I/O again. During
all the I/O wait periods, no productive work is happening. The CPU is available
but there's no other thread to utilize it.</p>
<p>Now let's look at the multi-threaded case with three threads:</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/mixed-multi.png" alt="Multi threaded mixed workload"></p>
<p>When there are three threads, the situation changes a bit. Threads now
occasionally spend time waiting for the GVL, but the overall throughput is
significantly better.</p>
<p>When Thread 1 releases the GVL to perform I/O, Thread 2 can immediately acquire
it and start executing CPU-bound work. While Thread 2 is working, Thread 1 might
still be waiting for its I/O operation to complete. Then when Thread 2 releases
the GVL for its own I/O operation, Thread 3 can acquire it. This creates a
pipeline effect where threads are constantly handing off the GVL to each other
ensuring that the CPU is almost always doing useful work.</p>
<p>The small amount of GVL contention we see in the multi-threaded case (threads
waiting for GVL) is more than compensated for by the elimination of idle CPU
time. Instead of the CPU sitting idle during I/O operations, other threads keep
it busy.</p>
<p>This is why Rails applications with typical workloads (lots of database queries,
API calls, and other I/O operations) benefit significantly from having multiple
threads.</p>
<h2>Why can't we increase the thread count to a really high value?</h2>
<p>In the previous section, we saw that increasing the number of threads can help
in utilizing the CPU better. So why can't we increase the number of threads to a
really high value? Let us visualize it.</p>
<p>In the hope of increasing performance, let us bump up the number of threads in
the previous code snippet to <code>20</code> and see the gvl-tracing result.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/gvl-in-ruby-and-its-impact-in-scaling-rails-applications/20-threads.png" alt="20 threads"></p>
<p>As we can see in the above picture, the amount of GVL contention is massive
here. Threads are waiting to get a hold of the GVL. Same will happen inside a
Puma process if we increase the number of threads to a very high value. As we
know, each request is handled by a thread. GVL contention therefore, means that
the requests keep waiting, thereby increasing latency.</p>
<h2>What's next</h2>
<p>In the coming blogs, we'll see how we can figure out the ideal value for
<code>max_threads</code>, both theoretically and empirically, based on our application's
workload.</p>
<p><em>This was Part 2 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>. If any part of the
blog is not clear to you then please write to us at
<a href="https://www.linkedin.com/company/bigbinary">LinkedIn</a>,
<a href="https://twitter.com/bigbinary">Twitter</a> or
<a href="https://bigbinary.com/contact">BigBinary website</a>.</em></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Understanding how Puma handles requests]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/understanding_puma_concurrency_effect_of_gvl.jpg"/>
      <id>https://www.bigbinary.com/blog/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance</id>
      <published>2025-04-23T00:00:00.000Z</published>
      <updated>2025-04-23T00:00:00.000Z</updated>
      <author>
        <name>Vishnu M</name>
        <uri>https://www.bigbinary.com/blog/authors/vishnu-m</uri>
      </author>
      <category term="Rails"/>
      <category term="Puma"/>
      <category term="Ruby"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/understanding_puma_concurrency_effect_of_gvl.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[This is Part 1 of our blog series on scaling Rails applications. If we do rails new to create a new Rails application, Puma will be the default web server. Let's start by explaining how Puma handles...]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance"><![CDATA[<p><em>This is Part 1 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>.</em></p>
<p>If we do <code>rails new</code> to create a new Rails
application, <a href="https://puma.io">Puma</a> will be the default web server. Let's start
by explaining how Puma handles requests.</p>
<h2>How does Puma handle requests?</h2>
<p>Puma listens to incoming requests on a TCP socket. When a request comes in, then
that request is queued up in the socket. The request is then picked up by a Puma
process. In Puma, a process is a separate OS process that runs an instance of
the Rails application.</p>
<p><em>Note that Puma official documentation calls a Puma process a Puma worker. Since
the term &quot;worker&quot; might confuse people with background workers like Sidekiq or
SolidQueue, in this article, we have used the word Puma process at a few places
to remove any ambiguity</em>.</p>
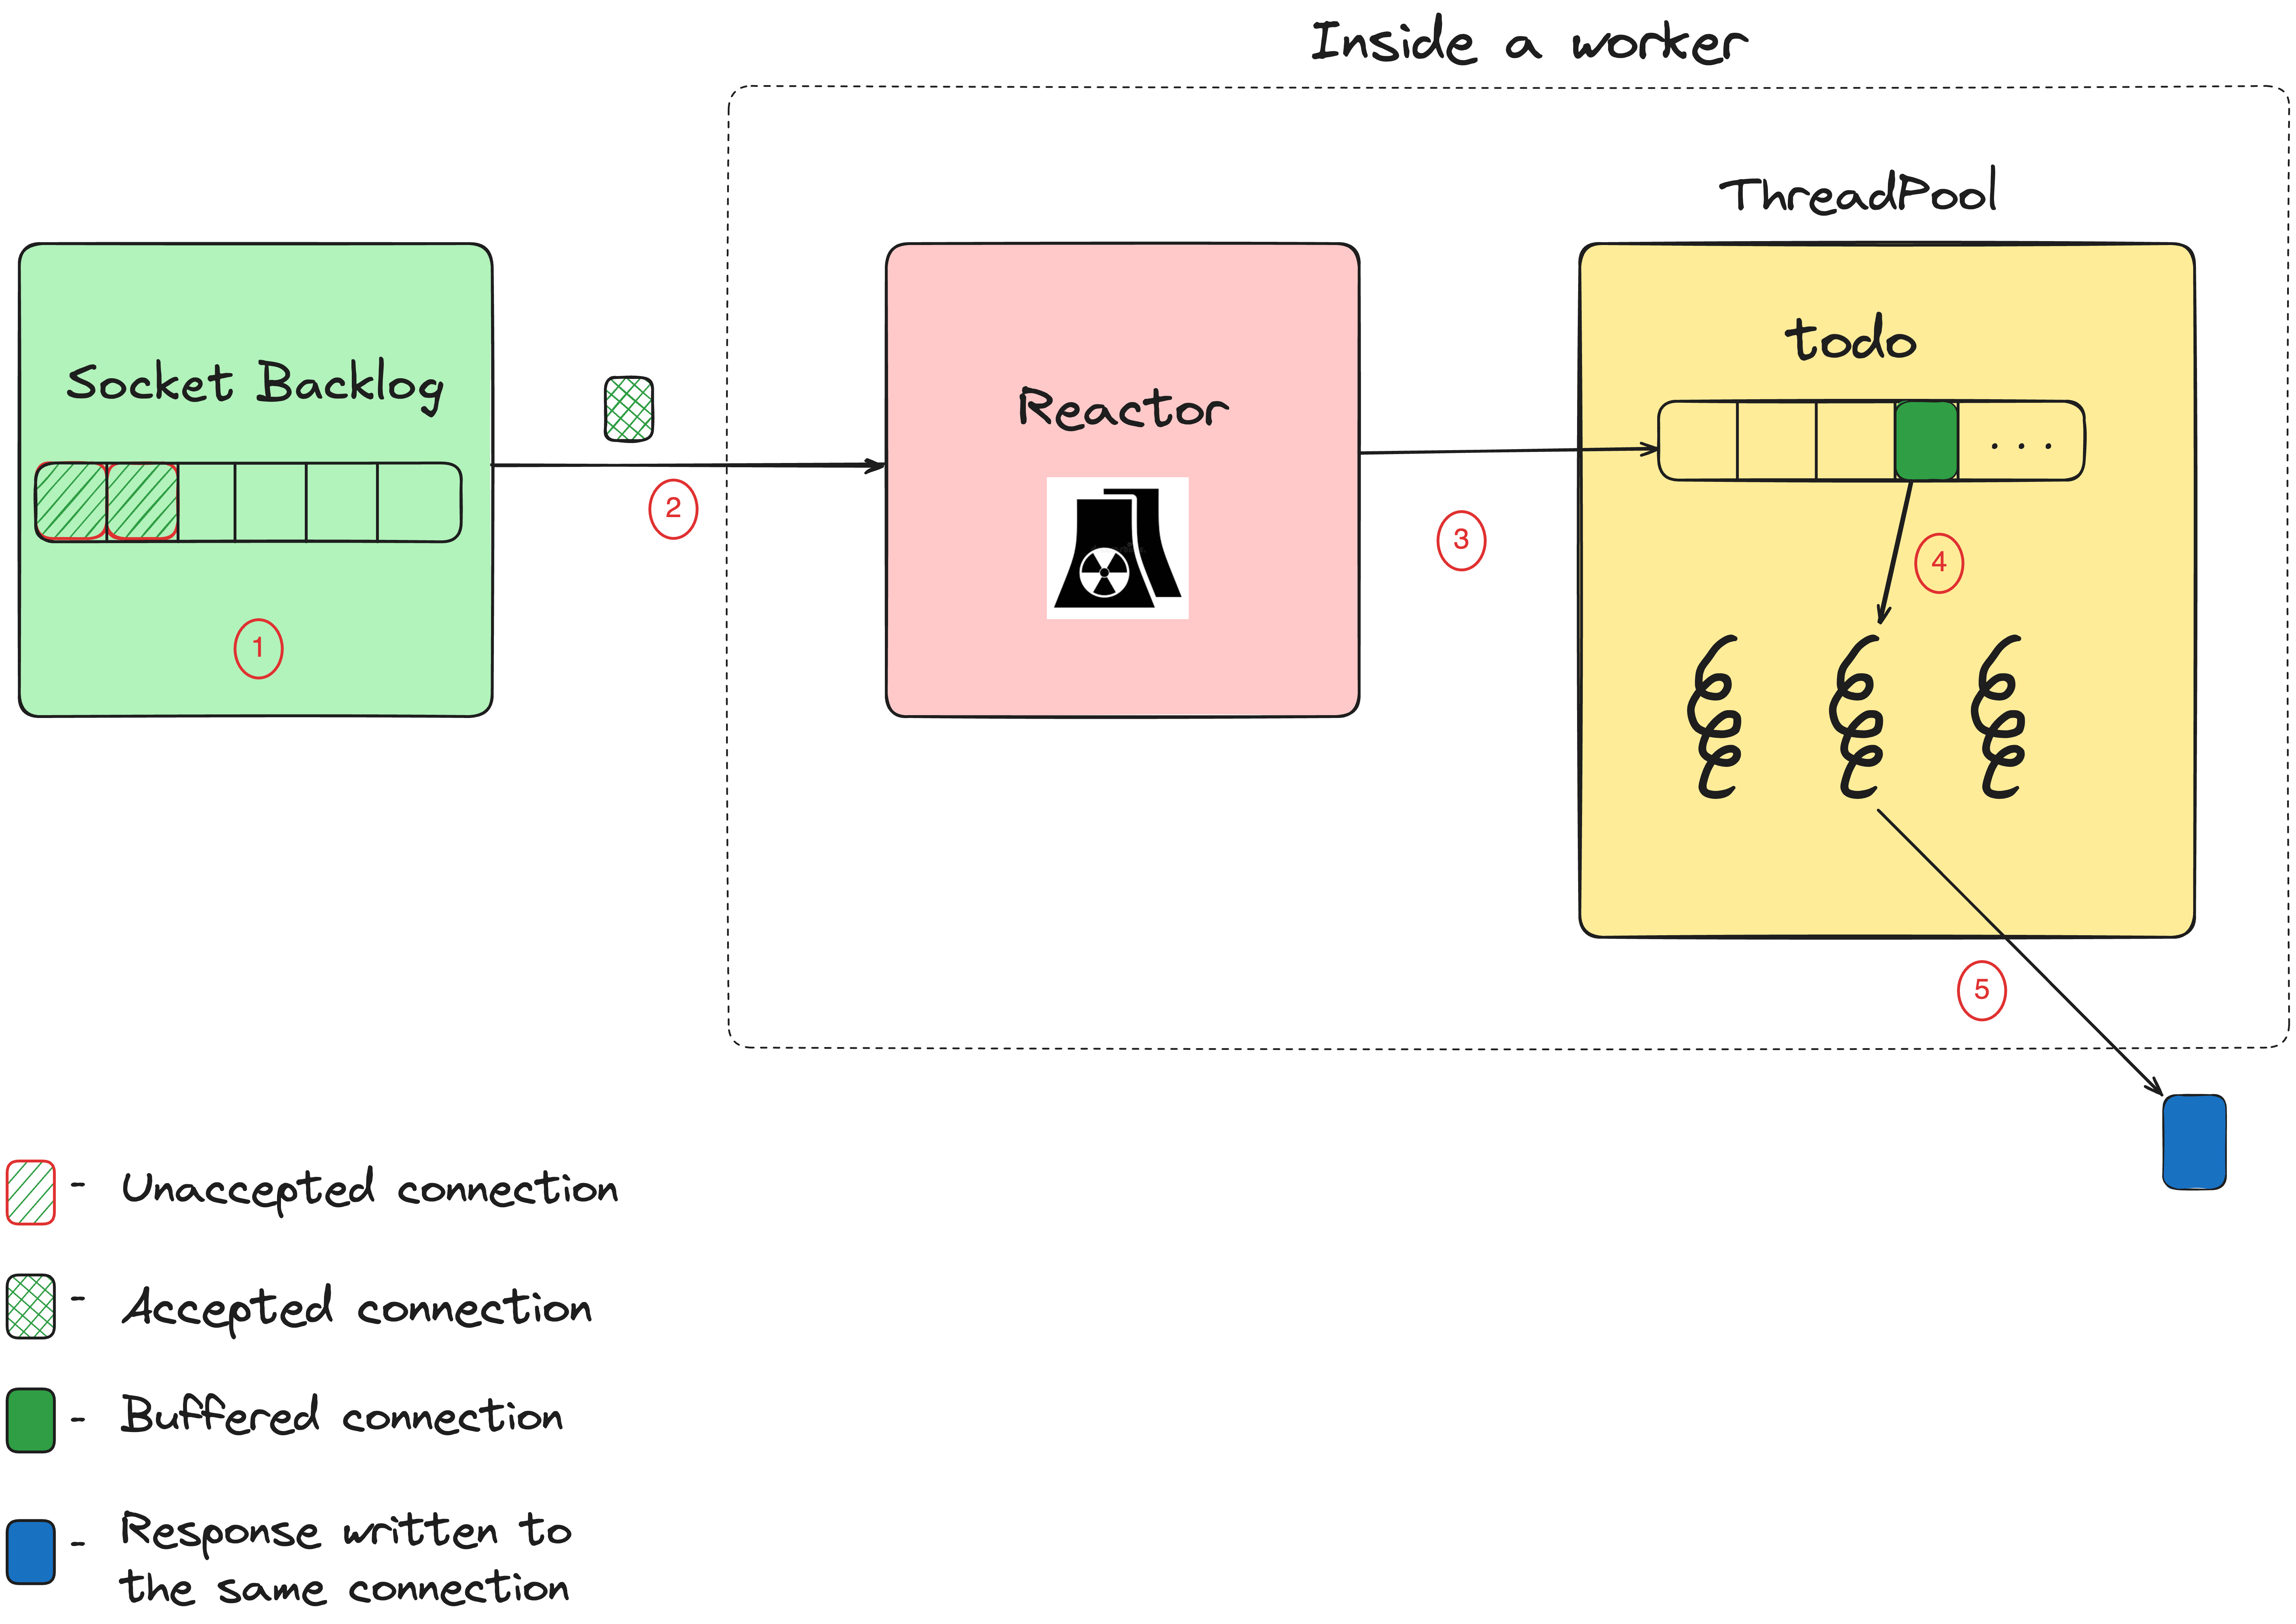
<p>Now, let's look at how a request is processed by Puma step-by-step.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance/puma-internals.png" alt="Puma internals"></p>
<ol>
<li>
<p>All the incoming connections are added to the socket backlog, which is an OS
level queue that holds pending connections.</p>
</li>
<li>
<p>A separate thread (created by the
<a href="https://msp-greg.github.io/puma/Puma/Reactor.html">Reactor</a> class) reads the
connection from the socket backlog. As the name suggests, this Reactor class
implements the
<a href="https://en.wikipedia.org/wiki/Reactor_pattern">reactor pattern</a>. The reactor
can manage multiple connections at a time thanks to non-blocking I/O and an
event-driven architecture.</p>
</li>
<li>
<p>Once the incoming request is fully buffered in memory, the request is passed
to the thread pool where the request resides in the <code>@todo</code> array.</p>
</li>
<li>
<p>A thread in the thread pool pulls a request from the <code>@todo</code> array and
processes it. The thread calls the Rack application, which, in our case is a
Rails application, and generates a response.</p>
</li>
<li>
<p>The response is then sent back to the client via the same connection. Once
this is complete, the thread is released back to the thread pool to handle
the next item from the <code>@todo</code> array.</p>
</li>
</ol>
<h2>Modes in Puma</h2>
<ol>
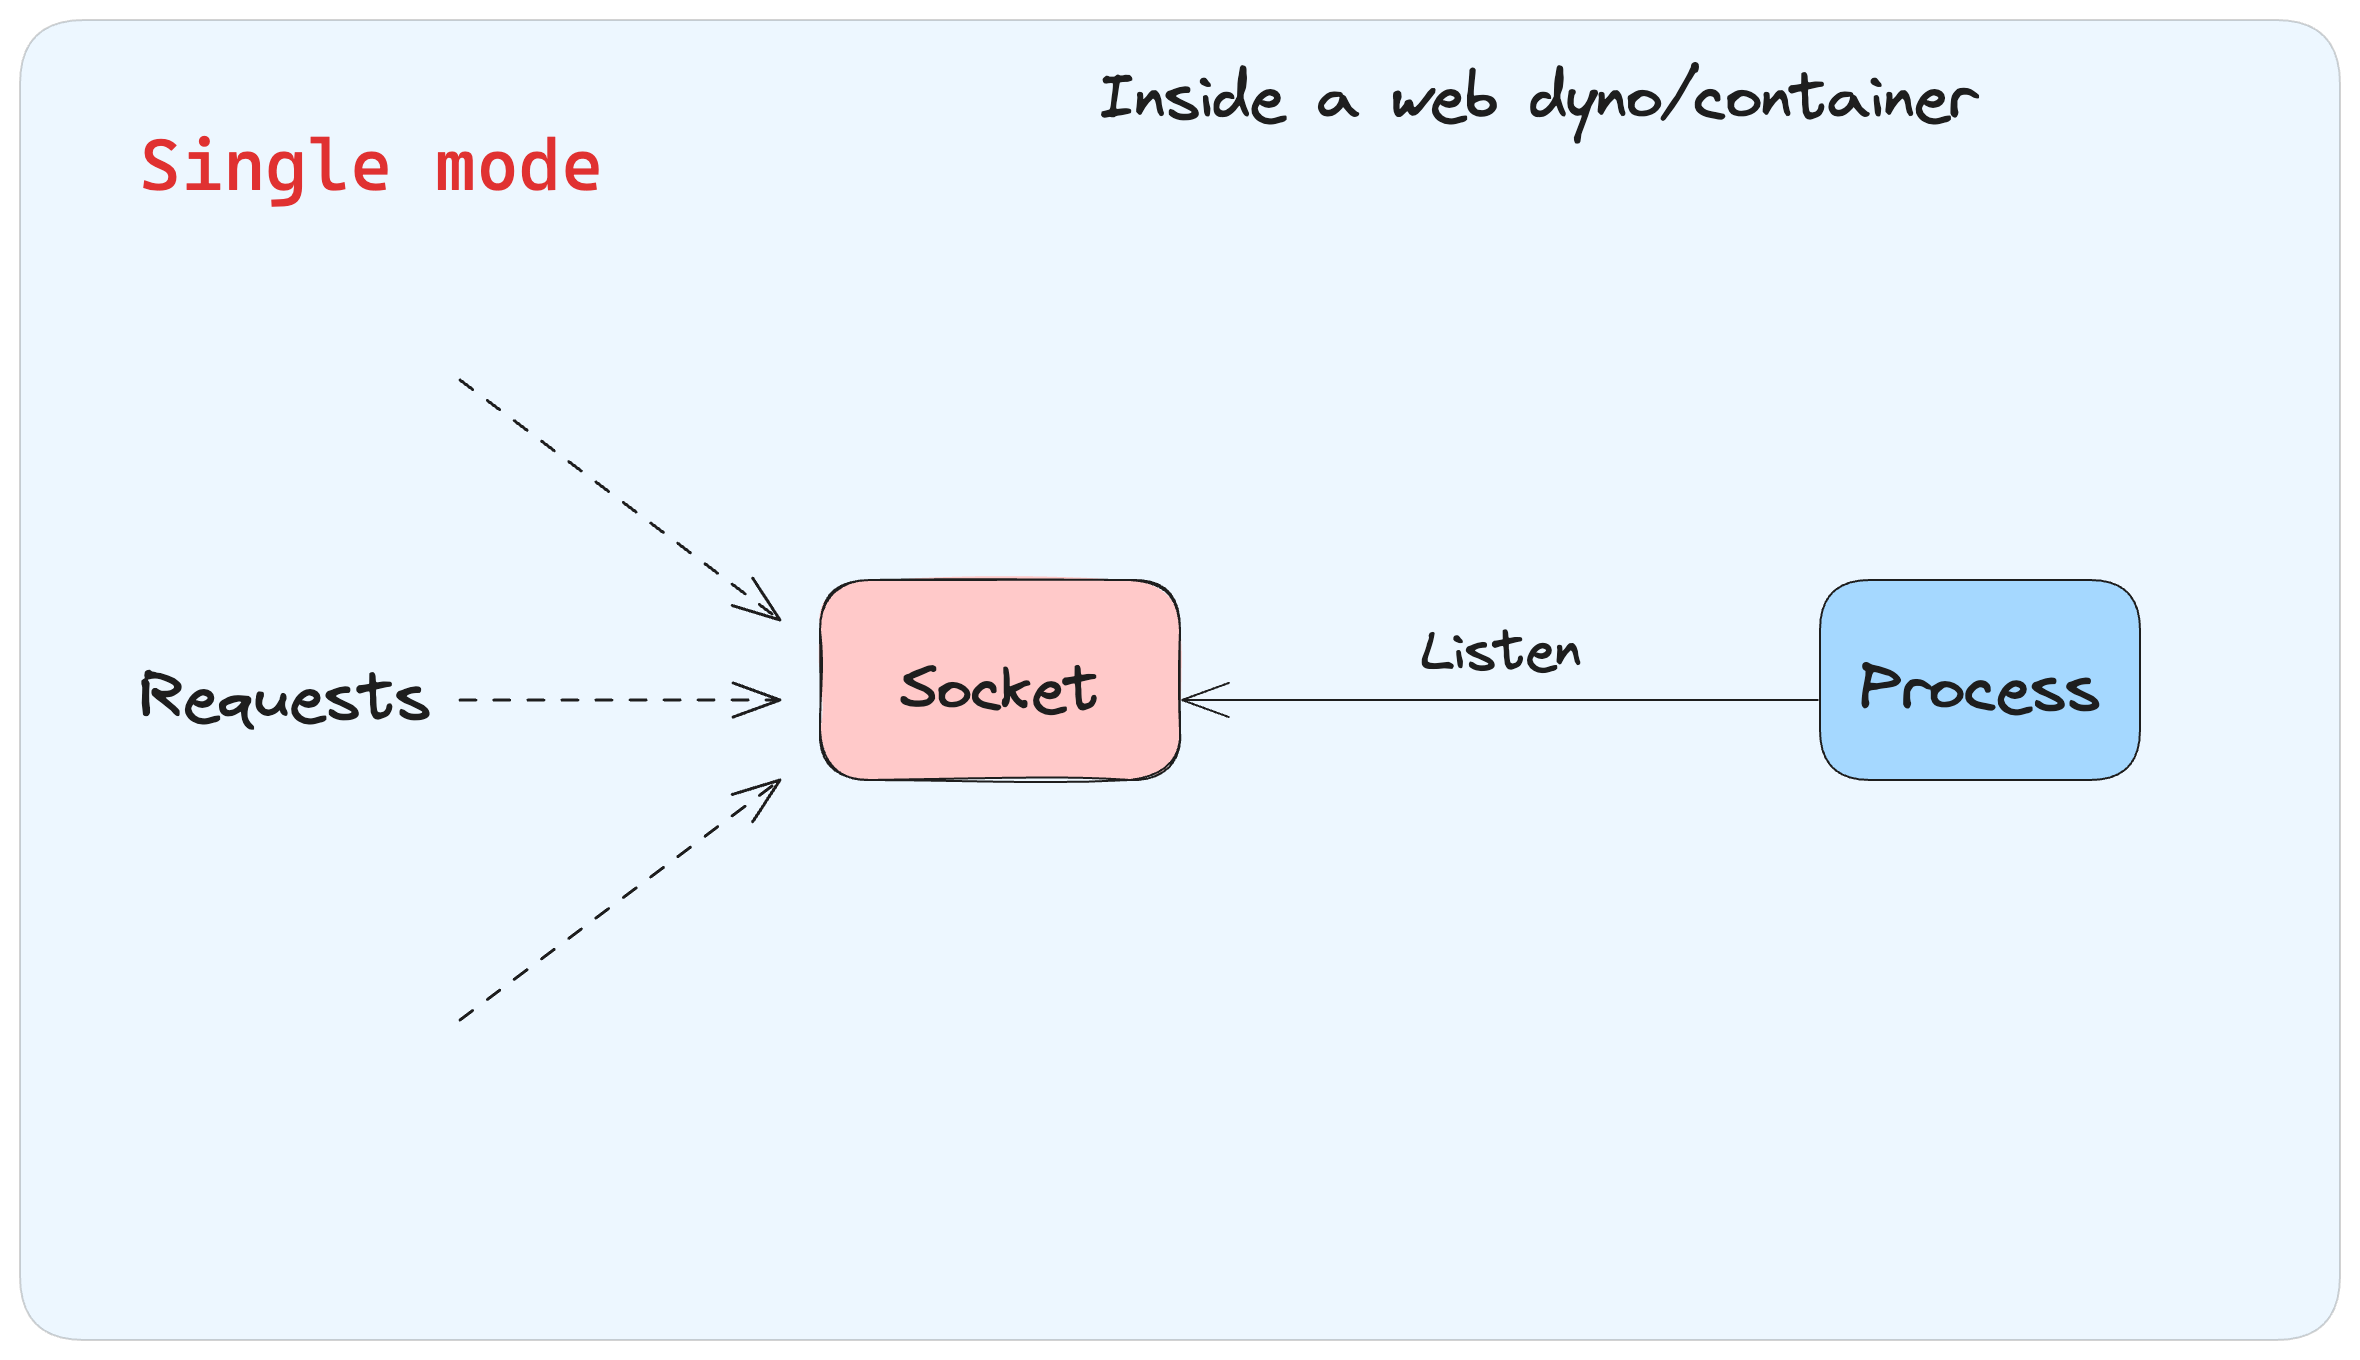
<li>
<p><strong>Single Mode</strong>: In single mode, only a single Puma process boots and does
not have any additional child processes. It is suitable only for applications
with low traffic.</p>
<p><img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance/single-mode.png" alt="Single mode"></p>
</li>
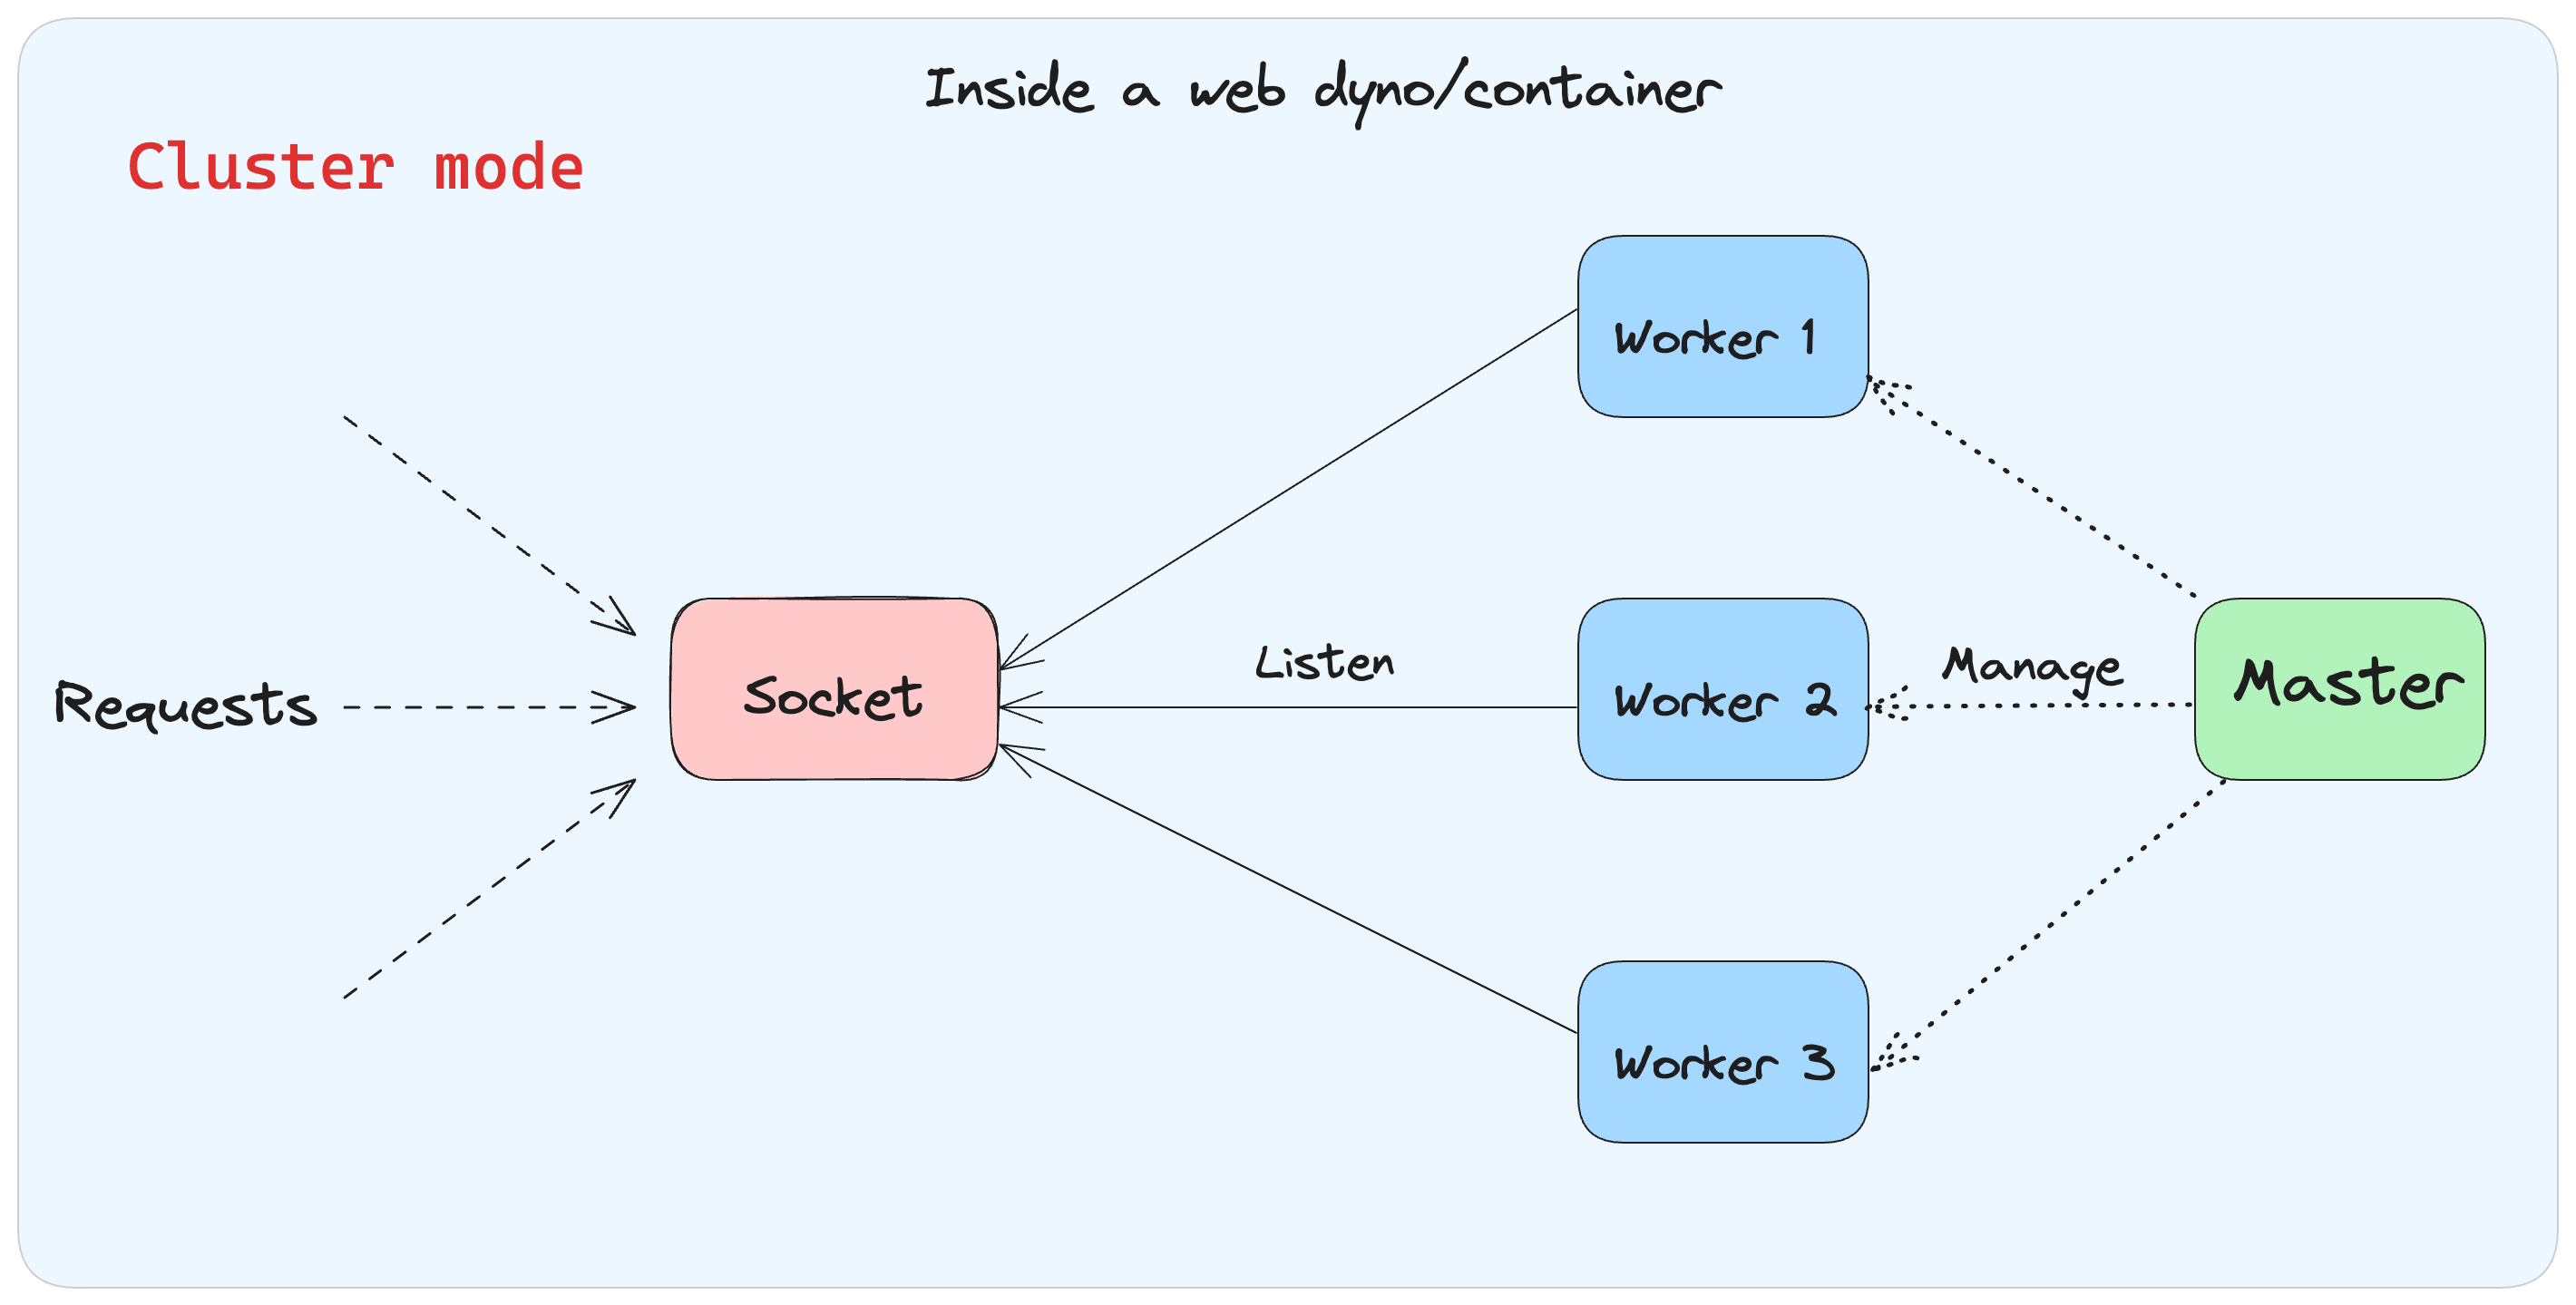
<li>
<p><strong>Cluster Mode</strong>: In cluster mode, Puma boots up a master process, which
prepares the application and then invokes the
<a href="https://en.wikipedia.org/wiki/Fork_(system_call)">fork()</a> system call to
create one or more child processes. These processes are the ones that are
responsible for handling requests. The master process monitors and manages
these child processes.
<img src="https://www.bigbinary.com/blog/images/images_used_in_blog/2025/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance/cluster-mode.png" alt="Cluster mode"></p>
</li>
</ol>
<h2>Default Puma configuration in a new Rails application</h2>
<p>When we create a new Rails 8 or higher application, the default Puma
<code>config/puma.rb</code> will have the following code.</p>
<p><em>Please note that we are mentioning Rails 8 here because the Puma configuration
is different in prior versions of Rails.</em></p>
<pre><code class="language-ruby">threads_count = ENV.fetch(&quot;RAILS_MAX_THREADS&quot;, 3)
threads threads_count, threads_count

rails_env = ENV.fetch(&quot;RAILS_ENV&quot;, &quot;development&quot;)
environment rails_env

case rails_env
when &quot;production&quot;
  workers_count = Integer(ENV.fetch(&quot;WEB_CONCURRENCY&quot;, 1))
  workers workers_count if workers_count &gt; 1

  preload_app!
when &quot;development&quot;
  worker_timeout 3600
end
</code></pre>
<p>For a brand new Rails application, the env variables <code>RAILS_MAX_THREADS</code> and
<code>WEB_CONCURRENCY</code> won't be set. This means <code>threads_count</code> will be set to 3 and
<code>workers_count</code> will be 1.</p>
<p>Now let's look at the second line from the above mentioned code.</p>
<pre><code class="language-ruby">threads threads_count, threads_count
</code></pre>
<p>In the above code, <code>threads</code> is a method to which we are passing two arguments.
The default value of <code>threads_count</code> is 3. So effectively, we are calling method
<code>threads</code> like this.</p>
<pre><code>threads(3, 3)
</code></pre>
<p>The threads method in Puma takes two arguments: <code>min</code> and <code>max</code>. These arguments
specify the minimum and maximum number of threads that each Puma process will
use to handle requests. In this case Puma will initialize 3 threads in the
thread pool.</p>
<p>Now let's look at the following line from the above mentioned code.</p>
<pre><code class="language-ruby">workers workers_count if workers_count &gt; 1
</code></pre>
<p>The value of <code>workers_count</code> in this case is <code>1</code>, so Puma will run in <strong>single</strong>
mode. As mentioned earlier in Puma a worker is basically a process. It's not
background job worker.</p>
<p>What we have seen is that if we don't specify <code>RAILS_MAX_THREADS</code> or
<code>WEB_CONCURRENCY</code> then, by default, Puma will boot a single process and that
process will have three threads. In other words Rails will boot with the ability
to handle 3 requests concurrently.</p>
<p>This is the default value for Puma for Rails booting in development or in
production mode - a single process with three threads.</p>
<h2>Configuring Puma's concurrency and parallelism</h2>
<p>When it comes to concurrency and parallelism in Puma, there are two primary
parameters we can configure: the number of threads each process will have and
the number of processes we need.</p>
<p>To figure out the right value for each of these parameters, we need to know how
Ruby works. Specifically, we need to know how GVL in Ruby works and how it
impacts the performance of Rails applications.</p>
<p>We also need to know what kind of Rails application it is. Is it a CPU intensive
application, IO intensive or somewhere in between.</p>
<p>Don't worry in the next blog, we will start from the basics and will discuss all
this and much more.</p>
<p><em>This was Part 1 of our blog series on
<a href="https://www.bigbinary.com/blog/scaling-rails-series">scaling Rails applications</a>. If any part of the
blog is not clear to you then please write to us at
<a href="https://www.linkedin.com/company/bigbinary">LinkedIn</a>,
<a href="https://twitter.com/bigbinary">Twitter</a> or
<a href="https://bigbinary.com/contact">BigBinary website</a>.</em></p>
]]></content>
    </entry>
  <entry>
      <title type="text"><![CDATA[Scaling Rails Series]]></title>
      <link rel="alternate" type="text/html" href="https://www.bigbinary.com/blog/scaling-rails-series"/>
      <link rel="enclosure" type="image/jpeg" href="https://www.bigbinary.com/blog/images/social_preview_images/scaling_rails_series.jpg"/>
      <id>https://www.bigbinary.com/blog/scaling-rails-series</id>
      <published>2025-04-22T00:00:00.000Z</published>
      <updated>2025-04-22T00:00:00.000Z</updated>
      <author>
        <name>Vishnu M</name>
        <uri>https://www.bigbinary.com/blog/authors/vishnu-m</uri>
      </author>
      <category term="Rails"/>
      <category term="Puma"/>
      <media:thumbnail url="https://www.bigbinary.com/blog/images/social_preview_images/scaling_rails_series.jpg" width="1200" height="627"/>
      <summary type="text"><![CDATA[Scaling Rails]]></summary>
      <content type="html" xml:base="https://www.bigbinary.com/blog/scaling-rails-series"><![CDATA[<p>Rails makes it pretty easy to get started with development. You don't even have
to set up your database. It comes with SQLite. Install Rails, and you start the
development.</p>
<p>Same with deploying to production. You need to change your database. Other than
that it comes with sane defaults. You don't really need to know what's
<code>RAILS_MAX_THREADS</code> and what's <code>WEB_CONCURRENCY</code>. However, as your application
starts getting more traffic, you want to scale your application.</p>
<p>Over the last decade and a half of consultancy, we have seen all types of
applications.</p>
<p>We have seen Rails applications which are IO heavy like scraping websites. There
are applications which are heavy on background jobs. Then there are flash sale
sites where there is no traffic one minute and the next minute there are tons of
traffic. Then there are ticketing sites.</p>
<p>Each application has its own challenges.</p>
<p>If an application is not properly tuned, then we can run into all kinds of
issues. You can run out of memory or database connections. In some cases,
because of the wrong configuration, Sidekiq jobs were failing and these jobs
continued to get enqueued which made the situation worse.</p>
<p>To solve all these types of issues, we need to know what's actually happening.
And that's what we will do. We will look at under the hood to see how Rails
works, how Puma works, how connection pooling works, how to tune Sidekiq and how
to measure what we need to know to make decisions.</p>
<p>It's a journey to understand from the ground up how to scale Rails applications.
This page will have links to all the future blogs. You can follow the Scaling
Rails series by joining the newsletter or following us on
<a href="https://twitter.com/bigbinary">twitter</a> or
<a href="https://www.linkedin.com/company/bigbinary/">LinkedIn</a>. We even have an
<a href="https://bigbinary.com/blog/feed.xml">RSS feed</a>.</p>
<h3><a href="https://www.bigbinary.com/blog/understanding-puma-concurrency-and-the-effect-of-the-gvl-on-performance">Part 1 - Understanding how Puma handles requests</a></h3>
<ul>
<li>How Puma handles requests</li>
<li>Default Puma configuration in a new Rails application</li>
</ul>
<h3><a href="https://www.bigbinary.com/blog/gvl-in-ruby-and-its-impact-in-scaling-rails-applications">Part 2 - GVL in Ruby and the impact of GVL in scaling Rails applications</a></h3>
<ul>
<li>Web applications and CPU usage</li>
<li>CPU bound or IO bound</li>
<li>Concurrency vs Parallelism</li>
<li>Understanding the GVL</li>
<li>GVL dictates how many processes you will need</li>
<li>Thread switching</li>
<li>Visualizing the effect of the GVL</li>
</ul>
<h3><a href="https://www.bigbinary.com/blog/amdahls-law-the-theoretical-relationship-between-speedup-and-concurrency">Part 3 - Amdahl's Law: The Theoretical Relationship Between Speedup and Concurrency</a></h3>
<ul>
<li>Amdahl's law</li>
<li>Relationship between speedup gained and the number of threads</li>
<li>Ideal number of threads in a process</li>
<li>Request queue time</li>
</ul>
<h3><a href="https://www.bigbinary.com/blog/tuning-puma-max-threads-configuration-with-gvl-instrumentation">Part 4 - Finding ideal number of threads per process using GVL Instrumentation</a></h3>
<ul>
<li>GVL instrumentation using perfm</li>
<li>Determining the I/O workload of an application using the GVL data</li>
<li>Empirically determining the ideal number of Puma threads for an application</li>
</ul>
<h3><a href="https://www.bigbinary.com/blog/understanding-active-record-connection-pooling">Part 5 - Understanding Active Record Connection Pooling</a></h3>
<ul>
<li>Database connection pooling</li>
<li>Active Record connection pool implementation</li>
<li>Connection pool configuration options</li>
<li>Active Record connection pool reaper</li>
<li>How many database connections will the web and background processes utilize at
maximum?</li>
<li>How does using <code>load_async</code> affect the connection usage?</li>
<li>Setting database pool size configuration</li>
<li>PgBouncer</li>
<li>Tracking down <code>ActiveRecord::ConnectionTimeoutError</code></li>
<li>Monitoring Active Record connection pool stats</li>
</ul>
<h3><a href="https://www.bigbinary.com/blog/understanding-queueing-theory">Part 6 - Understanding Queueing Theory</a></h3>
<ul>
<li>Queueing systems</li>
<li>Basic terminology in queueing theory</li>
<li>Little's law</li>
<li>The knee curve</li>
<li>Theoretical parallelism</li>
<li>Concurrency and effective parallelism</li>
</ul>
]]></content>
    </entry>
</feed>